News Posts matching #Grace CPU

Return to Keyword Browsing

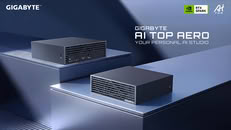
Gigabyte Launches the AI TOP AERO Powered by NVIDIA RTX Spark

Gigabyte today announced the launch of AI TOP AERO, a new AI desktop powered by the NVIDIA RTX Spark platform. Positioned as a Personal AI Studio, AI TOP AERO combines an NVIDIA Blackwell architecture GPU, up to 128 GB of unified system memory, and Gigabyte's cooling and compact chassis design. The new desktop expands Gigabyte's AI PC lineup, bringing local AI development, content creation and gaming to personal workspaces.

NVIDIA RTX Spark unites NVIDIA AI, RTX graphics, and unified memory in one slim, powerful Windows PC. Designed to run larger AI models locally--without cloud dependency--and move between creative work, development, and immersive gaming without missing a beat. Connect apps, tools, and workflows into one seamless experience. Private by default. RTX Spark brings NVIDIA's full-stack AI platform, ready for the AI workloads of today and whatever comes next. Delivered on the familiar, trusted Windows platform.
Server CPU Shipments Projected to Grow Over 40% YoY in 2027, with Arm-Based Products Continuing to Gain Market Share

TrendForce's latest AI server industry research indicates that demand for server CPUs has grown steadily since the second half of 2025 as AI server providers actively introduce AI agent applications. Server CPU shipments are projected to increase 31% YoY in 2026.

In 2027, continued growth in AI inference demand and rising adoption of agentic AI services are expected to drive server CPU shipments up by more than 40% YoY, potentially reshaping a market landscape traditionally dominated by x86 processors.

NVIDIA RTX Spark PCs Available Today—A New Beginning for Windows PCs

NVIDIA today announced the availability of NVIDIA RTX Spark laptops, bringing together RTX graphics and NVIDIA's full-stack AI platform in slim, premium Windows PCs for accelerated creation, immersive gaming and powerful local AI—rolling out from ASUS, Dell, HP, Lenovo, Microsoft and MSI.

Combining decades of NVIDIA innovation into a single superchip, RTX Spark delivers up to 128 GB of unified memory and 1 petaflop of FP4 AI performance to run large language models and AI agents locally. On a single device, creators, developers and gamers can move seamlessly between their everyday workflows and emerging AI agents on the familiar Windows platform.

NVIDIA RTX Spark Game Ready for Dozens of AAA Titles at Launch, Including DLSS 5 and Anti-Cheat Support

NVIDIA today announced that its new RTX Spark superchip that will power the next-generation of AI-native PCs, will be Game Ready for dozens of AAA games at launch on Windows 11, providing an uncompromising gaming experience that's maxed out for 1440p. The RTX Spark superchip features a 20-core Grace CPU and a GeForce RTX Blackwell iGPU featuring 6,144 CUDA cores. NVIDIA is closely collaborating with Microsoft and the various game developers to ensure not just Spark-native ports of popular titles, but also seamless translation of games to the RTX Spark platform for both the system- and graphics APIs.

A key announcement here is that NVIDIA is working with developers of competitive online games to ensure that their anti-cheat solutions work seamlessly with RTX Spark. Modern anti-cheat solutions rely heavily on kernel-mode interactions with hardware to ensure trust, something that has the potential to break in scenarios where games originally developed for Windows x64 machines are made to run on Windows Arm64 machine through translation layers. NVIDIA's developer collaboration ensures that the hardware-end of the anti-cheat trust-chain remains intact, and you should be able to play your favorite online games such as Counter-Strike 2, Dota 2, Fortnite, Marvel Rivals, NARAKA: BLADEPOINT, Rocket League, RUST, THE FINALS, War Thunder, World of Tanks, and more.

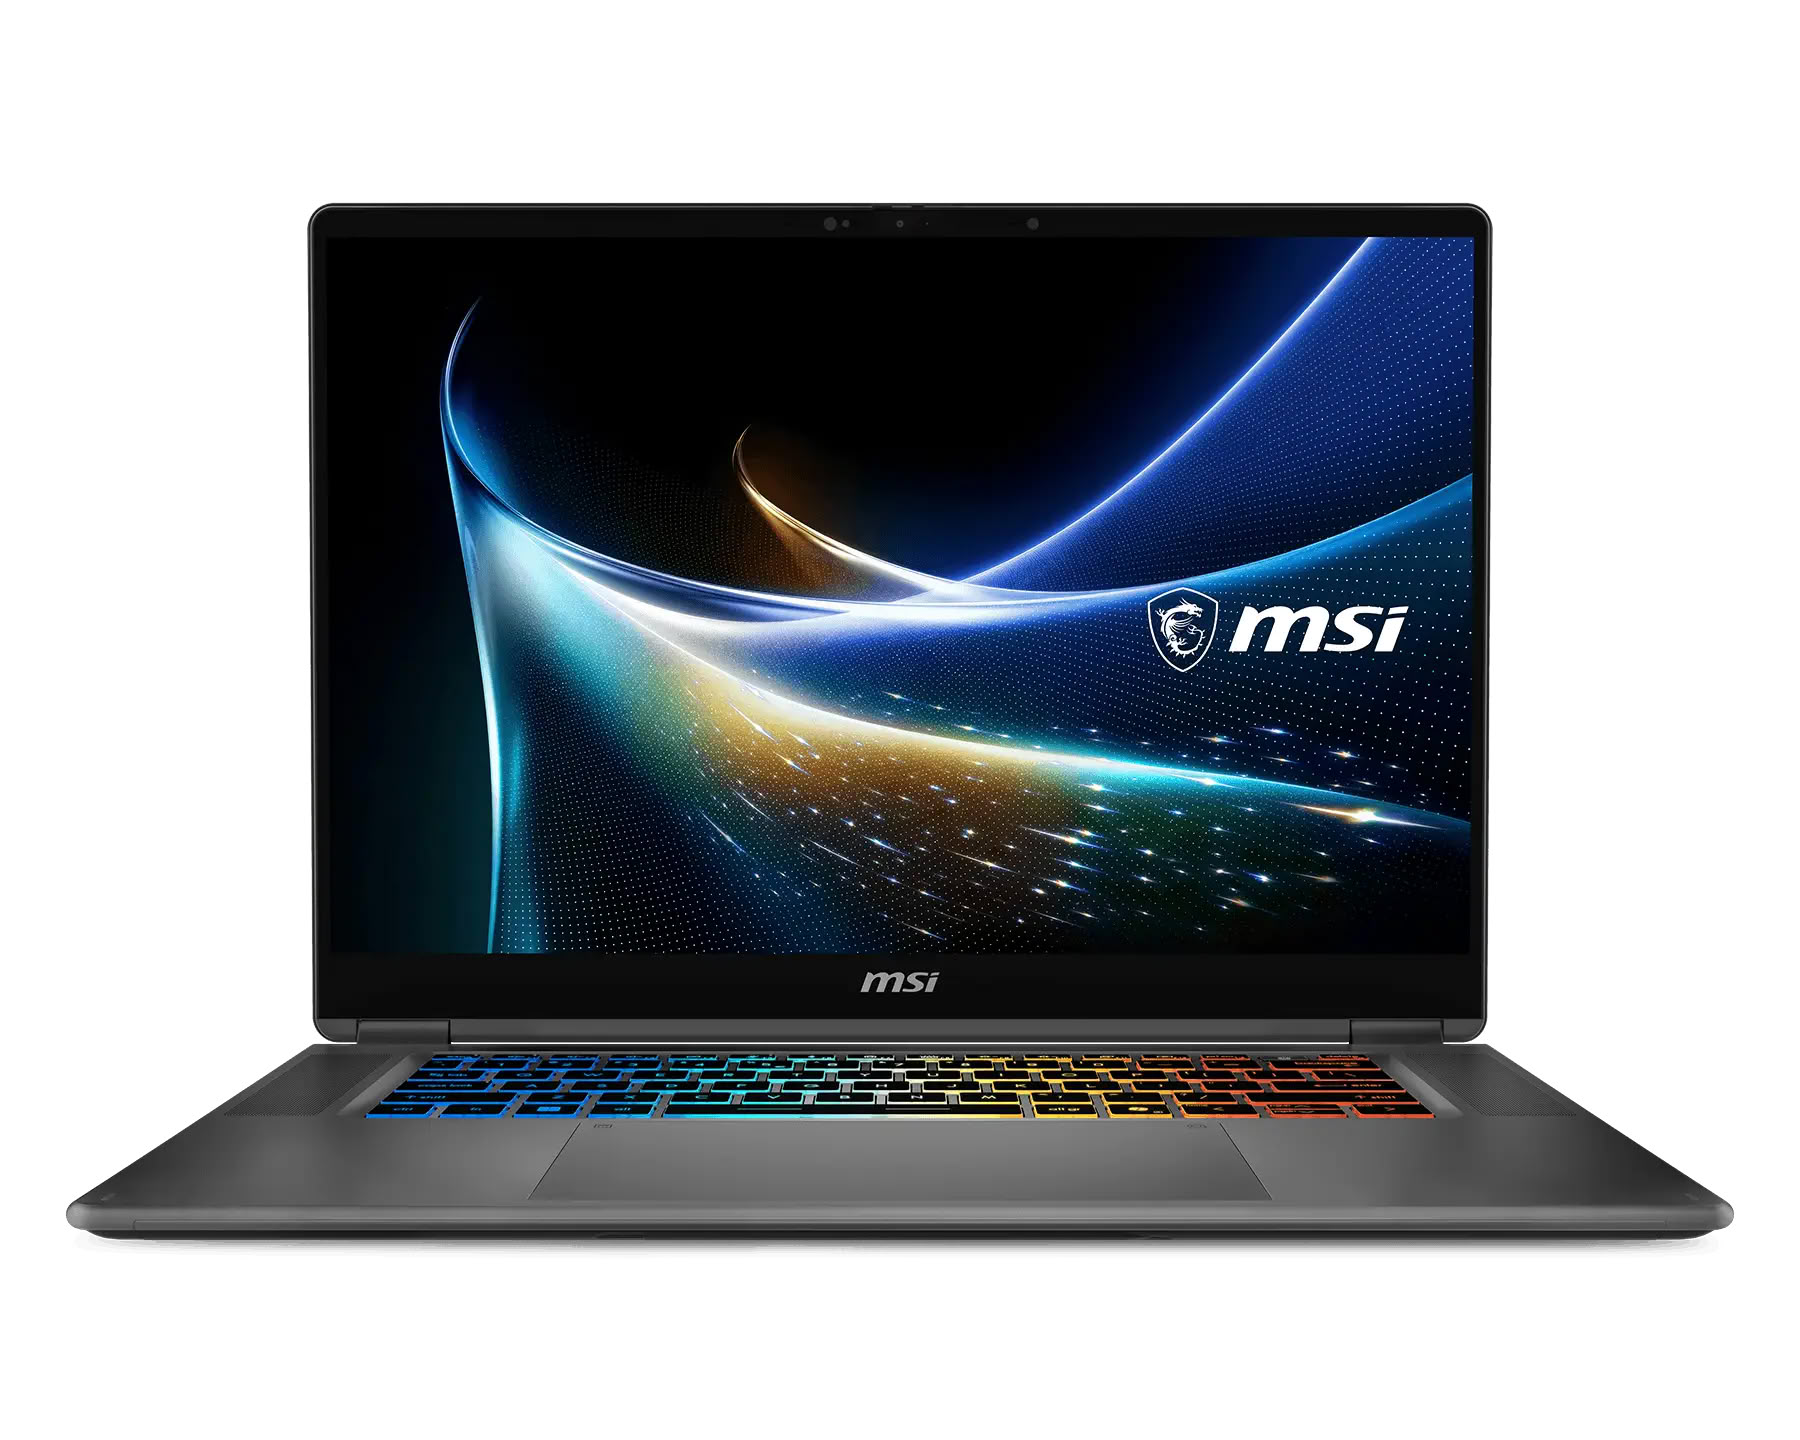
MSI Unveils Prestige N16 Flip AI+: An NVIDIA RTX Spark-Powered 2-in-1 Built for the Agentic AI Era

MSI, a global leader in high-performance and AI computing, today announced that the Prestige N16 Flip AI+ is now available for pre-order through MSI-certified partners in select markets.

Prestige N16 Flip AI+ is powered by NVIDIA RTX Spark, uniting NVIDIA AI, RTX graphics, and unified memory in one powerful and efficient thin-and-light Windows PC. Designed to run larger AI models locally—without cloud dependency—and move between creative work, development, and immersive gaming without missing a beat. Connect apps, tools, and workflows into one seamless experience. Private by default. RTX Spark brings NVIDIA's full-stack AI platform, ready for the AI workloads of today and whatever comes next. Delivered on the familiar, trusted, and secure Windows platform.

Dell Technologies Drives the Agentic AI Era with New Windows PCs and Workstations

Dell Technologies announces an expanded portfolio of Windows PCs and workstations built for the age of agentic AI. Together with NVIDIA and Microsoft, Dell delivers agentic AI across every stage of the creative and development journey, spanning a premium creator laptop, compact creator desktop and an AI workstation within the Windows environment.

NVIDIA RTX Spark comes to the XPS and Dell lineup for the first time, powering the new XPS 16 Creator Edition laptop and Dell Creator Edition Desktop. Paired with Windows, RTX Spark brings advanced AI, creative and gaming workloads together on a platform optimized for its performance. Dell Pro Precision with GB300 will be available on Windows, bringing always-on AI compute into the environment enterprise teams already depend on.

Acer Presents Their NVIDIA RTX Spark Design at IFA 2026

Acer showcased the Acer SFF RTX Spark design for a compact desktop powered by the NVIDIA RTX Spark superchip at Acer's next@Acer global press conference on September 2 during IFA 2026. NVIDIA RTX Spark redefines personal computing, combining personal agents, advanced content creation and high-performance gaming in a new platform engineered from the ground up for the next wave of Windows PC experiences. Designed for creators, AI developers and gamers, NVIDIA RTX Spark brings NVIDIA's full-stack AI platform and full suite of RTX technologies to compact desktops.

Powered by NVIDIA RTX Spark at its core, the Acer SFF RTX Spark offers major compute power in a space-saving footprint for tapping into agentic AI running locally. The design is built to deliver up to 1 petaflop of AI performance and up to 128 GB of high-speed unified memory, delivering a combination of compute and data privacy. It features up to a 6,144-core Blackwell RTX GPU, up to a 20-core NVIDIA Grace CPU, up to 1 petaflop of AI compute, and up to 128 GB of unified memory, paired with NVIDIA's full-stack AI platform and full suite of RTX technologies to accelerate AI innovation at the edge.

ASUS Unveils Revolutionary ProArt PCs Powered by NVIDIA RTX Spark at Computex 2026

At Computex2026, ASUS today announced a new generation of AI creator PCs under its ProArt lineup, powered by NVIDIA's RTX Spark. The new lineup—including the ProArt P16 (H7607) and P14 (H7407) laptops, alongside the ProArt Mini PC—is designed for AI creators, workflow builders, developers who demand powerful local AI capabilities and advanced content creation workflows.

ProArt AI PC powered by NVIDIA RTX Spark
ProArt P16 & P14 are NVIDIA RTX Spark-powered slim Windows laptops with all-day battery life and ASUS Lumina Pro OLED premium displays. Designed for creators and AI developers, The RTX Spark superchip features an NVIDIA Blackwell RTX GPU with 6,144 CUDA cores and fifth-generation Tensor Cores with FP4 precision, connected via the NVIDIA NVLink-C2C chip-to-chip interconnect to a high-performance, 20-core NVIDIA Grace CPU.

NVIDIA Launches Vera CPU, Purpose-Built for Agentic AI

NVIDIA today launched the NVIDIA Vera CPU, the world's first processor purpose-built for the age of agentic AI and reinforcement learning—delivering results with twice the efficiency and 50% faster than traditional rack-scale CPUs. As reasoning and agentic AI advances, scale, performance and cost are increasingly driven by the infrastructure supporting the models that plan tasks, run tools, interact with data, run code and validate results.

The NVIDIA Vera CPU builds on the success of the NVIDIA Grace CPU, enabling organizations of all sizes and across industries to build AI factories that unlock agentic AI at scale. With the highest single-thread performance and bandwidth per core, Vera is a new class of CPU that delivers higher AI throughput, responsiveness and efficiency for large-scale AI services such as coding assistants, as well as consumer and enterprise agents.

EuroHPC JU Signs Contract to Deploy AI Supercomputer HammerHAI

The European High Performance Computing Joint Undertaking (EuroHPC JU) has signed a contract with HPE to deploy HammerHAI - the first new, standalone supercomputer under its AI Factories initiative. Once installed at the High-Performance Computing Center Stuttgart (HLRS) in Germany, the AI-optimized system will provide powerful new capabilities for artificial intelligence, machine learning, and data science, strengthening European science, industry, small and medium-sized enterprises, and startups.

The new HammerHAI supercomputer will be manufactured and installed by HPE, based on the liquid-cooled NVIDIA GB200 NVL4 architecture. Combining NVIDIA Grace CPUs with NVIDIA Blackwell GPUs and scaled with NVIDIA Quantum-X800 InfiniBand networking, the NVIDIA GB200 NVL4 by HPE will offer more than 15 Exaflops of peak AI inference performance. It will integrate the VAST Data DASE storage architecture, which provides a unified data platform for AI and HPC workloads, as well as a partition based on AI-optimized inference engines and hardware accelerators from Netherlands-based Axelera AI. The HPE Morpheus Enterprise software will be used as a unified AI control plane, enabling automated provisioning, governance, and workload lifecycle management.

GIGABYTE Powers Telecom AI Transformation with End-to-End Infrastructure at MWC 2026

GIGABYTE Technology, a global leader known for its engineering excellence in high-performance computing and AI servers, extends its comprehensive end-to-end AI infrastructure portfolio designed specifically for the telecommunications industry at MWC 2026. GIGABYTE's end-to-end product solutions enable operators to convert massive volumes of network data into intelligence, automation, and new revenue streams, as telecommunications networks evolve from data carriers into AI-powered digital platforms.

At the core of the telco-to-AI transformation is the AI Factory, where network and subscriber data are converted into operational intelligence and commercialized AI services. GIGABYTE addresses this need with GB300 NVL72, a liquid-cooled rack-scale platform integrating 72 NVIDIA Blackwell Ultra GPUs and 36 NVIDIA Grace CPUs in a single system. Connected via NVIDIA Quantum-X800 InfiniBand or NVIDIA Spectrum-X Ethernet and NVIDIA ConnectX -8 SuperNIC s, GB300 NVL72 is optimized for large-scale AI training and inference workloads, enabling operators to automate operations, optimize network planning, and deploy AI-driven services at telecom scale.

Meta Partners with NVIDIA to Deploy Millions of Blackwell and Rubin GPUs

NVIDIA today announced a multiyear, multigenerational strategic partnership with Meta spanning on-premises, cloud and AI infrastructure. Meta will build hyperscale data centers optimized for both training and inference in support of the company's long-term AI infrastructure roadmap. This partnership will enable the large-scale deployment of NVIDIA CPUs and millions of NVIDIA Blackwell and Rubin GPUs, as well as the integration of NVIDIA Spectrum-X Ethernet switches for Meta's Facebook Open Switching System platform.

"No one deploys AI at Meta's scale—integrating frontier research with industrial-scale infrastructure to power the world's largest personalization and recommendation systems for billions of users," said Jensen Huang, founder and CEO of NVIDIA. "Through deep codesign across CPUs, GPUs, networking and software, we are bringing the full NVIDIA platform to Meta's researchers and engineers as they build the foundation for the next AI frontier."

Giga Computing Announces New Server Built on NVIDIA GB200 NVL4 Platform at SCA/HPC Asia 2026

Giga Computing, a subsidiary of GIGABYTE and a leader in high-performance computing and data center solutions, today announced the launch of its next-generation AI and HPC server, GIGABYTE XN24-VC0-LA61, powered by the NVIDIA GB200 NVL4 platform. Purpose-built for its heterogeneous architecture of CPU and GPU, the system will make its debut at SCA/HPC Asia 2026 in Osaka, Japan, showcasing Giga Computing's latest innovation in accelerated computing with liquid cooling technologies.

The XN24 server has been selected for the RIKEN Center for Computational Science (R-CCS) next-generation HPC-Quantum hybrid platform. The new platform integrates GIGABYTE servers into the development of FugakuNEXT, the eventual successor to Japan's flagship supercomputer, Fugaku. This integration will use the NVIDIA CUDA-Q platform to support the development of hybrid quantum-GPU supercomputing systems and research into advanced scientific applications that bridge quantum and traditional high-performance computing.

ASUS Showcases ExpertCenter Pro ET900N G3 at CES 2026

ASUS today announced the showcase of ExpertCenter Pro ET900N G3 at CES 2026, underscoring its commitment to delivering enterprise-grade AI infrastructure in accessible, deskside form factors. The all-new ET900N G3—accelerated by the NVIDIA GB300 Grace Blackwell Ultra Desktop Platform—sets a new standard for deskside AI supercomputers, combining extreme performance, unified memory architecture, and data-center-class connectivity.

Solving the last-mile challenge of modern AI development
AI development has reached extraordinary heights through massive cloud and data-center infrastructure, yet many researchers, developers, and data scientists still face a 'last-mile' challenge. While cloud services offer immense scale, countless workflows require local, private, and immediate compute power—especially for training, fine-tuning, or running large AI models that exceed the limits of traditional workstations. What these professionals need is a system that delivers data-center-class performance in a familiar, easily deployable deskside form factor.

Supermicro Showcases the Future of HPC Clusters and AI Infrastructure at SC25

Super Micro Computer, Inc. (SMCI), a Total IT Solution Provider for AI/ML, HPC, Cloud, Storage, and 5G/Edge, will showcase its latest AI Factory, HPC, and liquid-cooled data center innovations at Supercomputing 2025 (SC25) in St. Louis, Missouri. This broad portfolio, ranging from desktop workstations to rack-scale solutions, demonstrates Supermicro's commitment to powering the next generation of high-performance computing, scientific research, and enterprise AI deployments.

"Supermicro continues to lead the industry in delivering complete, next-generation infrastructure solutions in close collaboration with our technology partners," said Charles Liang, president and CEO of Supermicro. "At SC25, we are demonstrating our high-performance DCBBS architecture, direct liquid cooling, and rack-scale innovations, which empower customers to deploy AI and HPC workloads faster, more efficiently, and more sustainably."

MSI to Showcase NVIDIA MGX Servers and EdgeXpert Desktop AI Supercomputer at OCP 2025

MSI, a global leader in high-performance computing, will showcase its latest AI infrastructure solutions at the OCP Global Summit 2025, held from October 13-16, 2025 at the San Jose Convention Center, California (Booth #A55). The company will debut its NVIDIA MGX-based high-density AI servers and the new EdgeXpert Desktop AI Supercomputer, highlighting a strategy that spans large-scale data centers and edge computing environments to meet the surging demand for generative AI and accelerated computing.

MSI's GPU servers are built on the NVIDIA MGX modular architecture, accelerating AI workloads across training, inference, and simulation with support for the latest NVIDIA Hopper GPUs and NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs. The CG481-S6053 (4U) integrates dual AMD EPYC 9005 CPUs, 8 FHFL PCIe 6.0 GPU slots, 24 DDR5 DIMM slots, and 8x 400G Ethernet networking via NVIDIA ConnectX-8 SuperNICs, ideal for large-scale AI training clusters requiring maximum GPU density and bandwidth.

ASUS Announces Availability of ASUS Ascent GX10 Personal AI Supercomputer

ASUS today announced that the new Ascent GX10 will be available on October 15, 2025. This compact and powerful desktop AI supercomputer is designed to make advanced AI development more accessible to developers, AI researchers and data scientists. Powered by the NVIDIA GB10 Grace Blackwell Superchip and the NVIDIA AI software stack, the Ascent GX10 delivers full-stack AI performance in a minimal footprint.

"ASUS offers a comprehensive suite of personal AI supercomputers, from workstations to NVIDIA MGX servers accelerated by NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs, and large-scale infrastructure featuring the NVIDIA HGX B300 and NVIDIA GB300 NVL72 platforms," said Jackie Hsu, ASUS Senior Vice President and Co-Head of Open Platform Business Group & AIoT Business Group. " As we nurture accounts, we will support customers on their AI journey to expand their footprint across the NVIDIA ecosystem."

NVIDIA Ports CUDA to RISC-V, Betting Big on Open-Source ISA

During the RISC-V Summit in China, NVIDIA's Frans Sijstermans, vice president of hardware engineering, officially announced that NVIDIA has ported its massive CUDA software library to RISC-V ISA, signaling that the company sees RISC-V adoption accelerating in every aspect of the hardware stack, and that it could be a perfect match for NVIDIA GPUs. Historically, NVIDIA ported its CUDA platform to every major instruction set, including x86, Arm, PowerPC, and even Sun's SPARC. This is done to ensure that if any platform takes off in the enterprise or any segment, NVIDIA is there from the start to support it and allow its GPUs to run at full speed. Now, the $4 trillion company is making a bet that RISC-V will be the next desirable ISA to bring full support for.

NVIDIA envisions systems where its GPUs are the center of any acceleration, and supplementary RISC-V CPUs oversee CUDA drivers, application logic, and the operating system, orchestrating parallel workloads entirely within the CUDA ecosystem. The diagram shown at the summit highlights a DPU handling networking tasks, creating a cohesive trio of compute, control, and data-movement elements. If you recall, NVIDIA already uses NV-RISC-V CPU inside its GPUs for handling control logic on the GPU itself. That demonstrates NVIDIA's strategy to build heterogeneous platforms that combine RISC-V controllers with its GPUs, DPUs, and networking silicon. Now that CUDA is fully supported on RISC-V, NVIDIA could look into alternatives for its Grace CPU to be built on the RISC-V ISA. As the open-source ISA slowly breaks into the server space with the RVA23 specification, which NVIDIA mandates for CUDA support, we could see some interesting heterogeneous designs.

Pegatron Unveils AI-Optimized Server Innovations at GTC Paris 2025

PEGATRON, a globally recognized Design, Manufacturing, and Service (DMS) provider, is showcasing its latest AI server solutions at GTC Paris 2025. Built on NVIDIA Blackwell architecture, PEGATRON's cutting-edge systems are tailored for AI training, reasoning, and enterprise-scale deployment.

NVIDIA GB300 NVL72
At the forefront is the RA4802-72N2, built on the NVIDIA GB300 NVL72 rack system, featuring 72 NVIDIA Blackwell Ultra GPUs and 36 NVIDIA Grace CPUs. Designed for AI factories, it boosts output by up to 50X. PEGATRON's in-house developed Coolant Distribution Unit (CDU) delivers 310 kW of cooling capacity with redundant hot-swappable pumps, ensuring performance and reliability for mission-critical workloads.

NVIDIA Blackwell Delivers Breakthrough Performance in Latest MLPerf Training Results

NVIDIA is working with companies worldwide to build out AI factories—speeding the training and deployment of next-generation AI applications that use the latest advancements in training and inference. The NVIDIA Blackwell architecture is built to meet the heightened performance requirements of these new applications. In the latest round of MLPerf Training—the 12th since the benchmark's introduction in 2018—the NVIDIA AI platform delivered the highest performance at scale on every benchmark and powered every result submitted on the benchmark's toughest large language model (LLM)-focused test: Llama 3.1 405B pretraining.

The NVIDIA platform was the only one that submitted results on every MLPerf Training v5.0 benchmark—underscoring its exceptional performance and versatility across a wide array of AI workloads, spanning LLMs, recommendation systems, multimodal LLMs, object detection and graph neural networks. The at-scale submissions used two AI supercomputers powered by the NVIDIA Blackwell platform: Tyche, built using NVIDIA GB200 NVL72 rack-scale systems, and Nyx, based on NVIDIA DGX B200 systems. In addition, NVIDIA collaborated with CoreWeave and IBM to submit GB200 NVL72 results using a total of 2,496 Blackwell GPUs and 1,248 NVIDIA Grace CPUs.

NVIDIA Wins Multiple COMPUTEX Best Choice Awards

NVIDIA today received multiple accolades at COMPUTEX's Best Choice Awards, in recognition of innovation across the company. The NVIDIA GeForce RTX 5090 GPU won the Gaming and Entertainment category award; the NVIDIA Quantum-X Photonics InfiniBand switch system won the Networking and Communication category award; NVIDIA DGX Spark won the Computer and System category award; and the NVIDIA GB200 NVL72 system and NVIDIA Cosmos world foundation model development platform won Golden Awards. The awards recognize the outstanding functionality, innovation and market promise of technologies in each category. Jensen Huang, founder and CEO of NVIDIA, will deliver a keynote at COMPUTEX on Monday, May 19, at 11 a.m. Taiwan time.

GB200 NVL72 and NVIDIA Cosmos Go Gold
NVIDIA GB200 NVL72 and NVIDIA Cosmos each won Golden Awards. The NVIDIA GB200 NVL72 system connects 36 NVIDIA Grace CPUs and 72 NVIDIA Blackwell GPUs in a rack-scale design. It delivers 1.4 exaflops of AI performance and 30 terabytes of fast memory, as well as 30x faster real-time trillion-parameter large language model inference with 25x energy efficiency compared with the NVIDIA H100 GPU. By design, the GB200 NVL72 accelerates the most compute-intensive AI and high-performance computing workloads, including AI training and data processing for engineering design and simulation. NVIDIA Cosmos accelerates physical AI development by enabling developers to build and deploy world foundation models with unprecedented speed and scale.

NVIDIA & MediaTek Reportedly Readying "N1" Arm-based SoC for Introduction at Computex

Around late April, MediaTek confirmed that their CEO—Dr. Rick Tsai—will be delivering a big keynote speech—on May 20—at this month's Computex 2025 trade show. The company's preamble focuses on their "driving of AI innovation—from edge to cloud," but industry moles propose a surprise new product introduction during proceedings. MediaTek and NVIDIA have collaborated on a number of projects; the most visible being automative solutions. Late last year, intriguing Arm-based rumors emerged online—with Team Green allegedly working on a first time attempt at breaking into the high-end CPU consumer market segment; perhaps with the leveraging of "Blackwell" GPU architecture. MediaTek was reportedly placed in the equation, due to expertise accumulated from their devising of modern Dimensity "big core" mobile processor designs. At the start of 2025, data miners presented evidence of Lenovo seeking new engineering talent. Their job description mentioned a mysterious NVIDIA "N1x" SoC.

Further conjecture painted a fanciful picture of forthcoming "high-end N1x and mid-tier N1 (non-X)" models—with potential flagship devices launching later on this year. According to ComputerBase.de, an unannounced "GB10" PC chip could be the result of NVIDIA and MediaTek's rumored "AI PC" joint venture. Yesterday's news article divulged: "currently (this) product (can be) found in NVIDIA DGX Spark (platforms), and similarly equipped partner solutions. The systems, available starting at $3000, are aimed at AI developers who can test LLMs locally before moving them to the data center. The chip combines a 'Blackwell' GPU with a 'Grace' Arm CPU (in order) to create an SoC with 128 GB LPDDR5X, and a 1 TB or 4 TB SSD. The 'GB10' offers a GPU with one petaflop of FP4 performance (with sparsity)." ComputerBase reckons that the integrated graphics solution makes use of familiar properties—namely "5th-generation Tensor Cores and 4th-generation RT Cores"—from GeForce RTX 50-series graphics cards. When discussing the design's "Grace CPU" setup, the publication's report outlined a total provision of: "20 Arm cores, including 10 Cortex-X925 and 10 Cortex-A725. The whole thing sits on a board measuring around 150 × 150 mm—for comparison: the classic NUC board format is 104 × 101 mm."

GIGABYTE to Present End-to-End AI Portfolio at COMPUTEX 2025

GIGABYTE Technology, a global leader in computing innovation, will return to COMPUTEX 2025 from May 20 to 23 under the theme "Omnipresence of Computing: AI Forward." Demonstrating how GIGABYTE's complete spectrum of solutions spanning the AI lifecycle, from data center training to edge deployment and end-user applications reshapes the infrastructure to meet the next-gen AI demands.

As generative AI continues to evolve, so do the demands for handling massive token volumes, real-time data streaming, and high-throughput compute environments. GIGABYTE's end-to-end portfolio - ranging from rack-scale infrastructure to servers, cooling systems, embedded platforms, and personal computing—forms the foundation to accelerate AI breakthroughs across industries.

Oracle Cloud Infrastructure Bolstered by Thousands of NVIDIA Blackwell GPUs

Oracle has stood up and optimized its first wave of liquid-cooled NVIDIA GB200 NVL72 racks in its data centers. Thousands of NVIDIA Blackwell GPUs are now being deployed and ready for customer use on NVIDIA DGX Cloud and Oracle Cloud Infrastructure (OCI) to develop and run next-generation reasoning models and AI agents. Oracle's state-of-the-art GB200 deployment includes high-speed NVIDIA Quantum-2 InfiniBand and NVIDIA Spectrum-X Ethernet networking to enable scalable, low-latency performance, as well as a full stack of software and database integrations from NVIDIA and OCI.

OCI, one of the world's largest and fastest-growing cloud service providers, is among the first to deploy NVIDIA GB200 NVL72 systems. The company has ambitious plans to build one of the world's largest Blackwell clusters. OCI Superclusters will scale beyond 100,000 NVIDIA Blackwell GPUs to meet the world's skyrocketing need for inference tokens and accelerated computing. The torrid pace of AI innovation continues as several companies including OpenAI have released new reasoning models in the past few weeks.

Huawei CloudMatrix 384 System Outperforms NVIDIA GB200 NVL72

Huawei announced its CloudMatrix 384 system super node, which the company touts as its own domestic alternative to NVIDIA's GB200 NVL72 system, with more overall system performance but worse per-chip performance and higher power consumption. While NVIDIA's GB200 NVL72 uses 36 Grace CPUs paired with 72 "Blackwell" GB200 GPUs, the Huawei CloudMatrix 384 system employs 384 Huawei Ascend 910C accelerators to beat NVIDIA's GB200 NVL72 system. It takes roughly five times more Ascend 910C accelerators to deliver nearly twice the GB200 NVL system performance, which is not good on per-accelerator bias, but excellent on per-system level of deployment. SemiAnalysis argues that Huawei is a generation behind in chip performance but ahead of NVIDIA in scale-up system design and deployment.

When you look at individual chips, NVIDIA's GB200 NVL72 clearly outshines Huawei's Ascend 910C, delivering over three times the BF16 performance (2,500 TeraFLOPS vs. 780 TeraFLOPS), more on-chip memory (192 GB vs. 128 GB), and faster bandwidth (8 TB/s vs. 3.2 TB/s). In other words, NVIDIA has the raw power and efficiency advantage at the chip level. But flip the switch to the system level, and Huawei's CloudMatrix CM384 takes the lead. It cranks out 1.7× the overall PetaFLOPS, packs in 3.6× more total HBM capacity, and supports over five times the number of GPUs and the associated bandwidth of NVIDIA's NVL72 cluster. However, that scalability does come with a trade-off, as Huawei's setup draws nearly four times more total power. A single GB200 NVL72 draws 145 kW of power, while a single Huawei CloudMatrix 384 draws ~560 kW. So, NVIDIA is your go-to if you need peak efficiency in a single GPU. If you're building a massive AI supercluster where total throughput and interconnect speed matter most, Huawei's solution actually makes a lot of sense. Thanks to its all-to-all topology, Huawei has delivered an AI training and inference system worth purchasing. When SMIC, the maker of Huawei's chips, gets to a more advanced manufacturing node, the efficiency of these systems will also increase.
Return to Keyword Browsing
Nov 11th, 2026 03:59 CST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts