 36
ASUS Radeon RX 9070 XT TUF OC Review
(36 Comments) »Introduction

ASUS TUF Gaming Radeon RX 9070 XT OC is the company's top custom-design graphics card based on AMD's latest performance-segment GPU leading the RX 9000 series. The RX 9070 XT TUF Gaming uses the company's latest generation Vented Exoskeleton board design for TUF Gaming, which it debuted with its GeForce RTX 50-series. There are a couple of visual cues telling you which card this is, such as the prominent Radeon logo on top, and three 8-pin PCIe power connectors—an interesting choice, given that some of the other AMD board partners have implemented the modern 12V-2x6 with their premium RX 9070 XT cards. The Radeon RX 9070 XT is recommended by AMD for both 4K Ultra HD and 1440p gaming use-cases. With the RX 9000 series, AMD made a tactical retreat from the enthusiast segment, which means its flagship for this generation is a performance-segment part that it can concentrate its engineering efforts on.

The Radeon RX 9070 XT introduces a new naming scheme. Logically, the RX 9070 XT is the spiritual successor to the RX 7800 XT, but AMD has changed the naming scheme to help buyers better compare the SKU with a GeForce rival. The RX 9070 XT, hence, goes up against the RTX 5070 series from NVIDIA, including the RTX 5070 itself, and crosses swords with RTX 5070 Ti in some cases, at a lower price point.
The RX 9070 XT debuts the company's latest RDNA 4 graphics architecture, which comes with a design focus on maximizing performance per square mm of die-area. For starters, the new Navi 48 chip the RX 9070 XT is based on is a traditional monolithic silicon built on the 4 nm TSMC N4P foundry node, an upgrade from the previous generation, which used the latest foundry node of the time only for a centralized silicon with the number crunching machinery of the GPU, while relegating the memory controllers and Infinity Cache to chiplets built on an older node. The Navi 48 hence has a massive transistor density increase over its predecessor.
The new RDNA 4 graphics architecture comes with a design focus on uplifting the ray tracing performance of the GPU, with the company claiming a nearly 100% increase in RT performance over the previous generation, lowering the performance cost of having it enabled in your game, given that ray tracing is no longer a novelty, and is a must-have feature for today's AAA game titles. The company also worked to significantly increase the AI acceleration performance of the silicon, paving the way for the new FSR 4 performance enhancement suite. Lastly, the shader performance per CU sees a significant uplift, allowing AMD to arrive at a reasonable CU count of 64 to achieve performance in league of much larger enthusiast-segment GPUs from the previous generation. The memory size is 16 GB, across a 256-bit wide memory interface, and in a surprising move, AMD decided to stick with the older generation GDDR6 memory standard, instead focusing on significant updates to its memory management system.
The RX 9070 XT maxes out the 4 nm Navi 48 silicon it's based on, enabling all 64 compute units, which works out to 4,096 stream processors, 128 AI accelerators, 64 RT accelerators, 256 TMUs, and 128 ROPs. The GPU is able to run its engine clock at or above 3.00 GHz in overclocked scenarios, while the memory ticks at 20 Gbps, for 640 GB/s of memory bandwidth. AMD also updated its display and media engines. The media engine comes with image quality improvements for H.264 and H.265 hardware-accelerated encoding; besides support for AV1 B-frames.
The ASUS TUF Gaming RX 9070 XT OC, as we said, implements the latest generation of its TUF Gaming Vented Exoskeleton cooling solution, with striking industrial looks, and a design that exposes more of the heatsink underneath for the highest exhaust flow. ASUS offers factory overclocked speeds of 2520 MHz Game clock, compared to 2400 MHz reference Game clock. ASUS is pricing the card at an eye-watering $800, a 33% premium over the $600 AMD baseline.
| Price | Cores | ROPs | Core Clock | Boost Clock | Memory Clock | GPU | Transistors | Memory | |
|---|---|---|---|---|---|---|---|---|---|
| RTX 4070 | $400 | 5888 | 64 | 1920 MHz | 2475 MHz | 1313 MHz | AD104 | 35800M | 12 GB, GDDR6X, 192-bit |
| RX 7800 XT | $540 | 3840 | 96 | 2124 MHz | 2430 MHz | 2425 MHz | Navi 32 | 28100M | 16 GB, GDDR6, 256-bit |
| RTX 4070 Super | $600 | 7168 | 80 | 1980 MHz | 2475 MHz | 1313 MHz | AD104 | 35800M | 12 GB, GDDR6X, 192-bit |
| RX 7900 GRE | $650 | 5120 | 160 | 1880 MHz | 2245 MHz | 2250 MHz | Navi 31 | 57700M | 16 GB, GDDR6, 256-bit |
| RTX 4070 Ti | $700 | 7680 | 80 | 2310 MHz | 2610 MHz | 1313 MHz | AD104 | 35800M | 12 GB, GDDR6X, 192-bit |
| RTX 5070 | $600 | 6144 | 80 | 2325 MHz | 2512 MHz | 1750 MHz | GB205 | 31100M | 12 GB, GDDR7, 192-bit |
| RTX 4070 Ti Super | $860 | 8448 | 96 | 2340 MHz | 2610 MHz | 1313 MHz | AD103 | 45900M | 16 GB, GDDR6X, 256-bit |
| RX 7900 XT | $720 | 5376 | 192 | 2000 MHz | 2400 MHz | 2500 MHz | Navi 31 | 57700M | 20 GB, GDDR6, 320-bit |
| RX 9070 | $625 | 3584 | 128 | 2070 MHz | 2520 MHz | 2518 MHz | Navi 48 | 53900M | 16 GB, GDDR6, 256-bit |
| RX 9070 XT | $710 | 4096 | 128 | 2400 MHz | 2970 MHz | 2518 MHz | Navi 48 | 53900M | 16 GB, GDDR6, 256-bit |
| ASUS RX 9070 XT TUF OC | $800 | 4096 | 128 | 2520 MHz | 3060 MHz | 2518 MHz | Navi 48 | 53900M | 16 GB, GDDR6, 256-bit |
| RTX 5070 Ti | $840 | 8960 | 96 | 2295 MHz | 2452 MHz | 1750 MHz | GB203 | 45600M | 16 GB, GDDR7, 256-bit |
| RX 7900 XTX | $750 | 6144 | 192 | 2300 MHz | 2500 MHz | 2500 MHz | Navi 31 | 57700M | 24 GB, GDDR6, 384-bit |
| RTX 4080 | $1250 | 9728 | 112 | 2205 MHz | 2505 MHz | 1400 MHz | AD103 | 45900M | 16 GB, GDDR6X, 256-bit |
| RTX 4080 Super | $1300 | 10240 | 112 | 2295 MHz | 2550 MHz | 1438 MHz | AD103 | 45900M | 16 GB, GDDR6X, 256-bit |
| RTX 5080 | $1120 | 10752 | 112 | 2295 MHz | 2617 MHz | 1875 MHz | GB203 | 45600M | 16 GB, GDDR7, 256-bit |
| RTX 4090 | $1800 | 16384 | 176 | 2235 MHz | 2520 MHz | 1313 MHz | AD102 | 76300M | 24 GB, GDDR6X, 384-bit |
| RTX 5090 | $2700 | 21760 | 176 | 2017 MHz | 2407 MHz | 1750 MHz | GB202 | 92200M | 32 GB, GDDR7, 512-bit |
AMD RDNA 4 Architecture


The new Radeon RX 9070 XT and RX 9070 are powered by the 4 nm Navi 48 silicon. Unlike the Navi 31 and Navi 32 before it, this is a traditional monolithic die built entirely on the TSMC N4P (4 nm EUV) process node. It has an area of 356.5 mm², but with an impressive transistor count of 53.9 billion. To put this number into context, the previous "big Navi" GPU, the Navi 31 powering the RX 7900 XTX, has 57.8 billion transistors (just 8% more), despite having 96 CU, a larger Infinity Cache, and a wider 384-bit memory bus. Navi 31 has a die area of 529 mm² (304 mm² for the 5 nm GCD, with the rest being 6 nm MCDs), so you can see the kind of strides AMD made with die-area. At the top-level, the Navi 48 features a PCI-Express 5.0 x16 host interface and a 256-bit wide GDDR6 memory bus. With 20 Gbps GDDR6 memory chips, the RX 9070 XT gets 640 GB/s of memory bandwidth. This is made up for with a faster 64 MB Infinity Cache, and a critical improvement AMD made to its memory management system, called Out-of-Order Memory Queuing.
The Navi 48 silicon physically has 64 CU spread across 4 shader engines. With each CU containing 64 stream processors, the chip has a total of 4,096 stream processors. All 64 CU are enabled on the RX 9070 XT, while the RX 9070 has 56 out of 64 of them enabled. The maxed-out Navi 48 contains 4,096 stream processors, 128 AI accelerators, 64 RT accelerators, 256 TMUs, and 128 ROPs. The chip also features 64 MB of 3rd Gen Infinity Cache, and a 256-bit wide GDDR6 memory interface, driving 16 GB of 20 Gbps memory on both the RX 9070 XT and RX 9070. With 56 CU enabled on the RX 9070, it has 3,584 stream processors, 112 AI accelerators, 56 RT accelerators, 224 TMUs, and an untouched ROP count of 128, besides the exact same memory configuration as the RX 9070 XT.

At the heart of the RDNA 4 graphics architecture is the new dual compute unit, with a vastly improved memory sub-system, improvements made to the scalar units, a new technology called dynamic register allocation, and improvements to CU efficiency and engine clocks. Each CU has two scheduler blocks, driving a 192 KB general purpose register (GPR), an 8 KB scalar GPR, 32 FMA ALUs, and 32 FMA+INT ALUs. There are also 8 transcendental logic units. RDNA 4 introduces the concept of dual SIMD32 vector units, for even more parallelism. The Scalar Unit comes with support for newer Float32 ops. Schedulers are updated with accelerated spill/fill operations. Instruction prefetching is improved. The new generation AI Accelerator comes with two 16-bit and four 8-bit/4-bit dense matrix compute rates, support for 4:2 structured sparsity for doubling throughput, and matrix loads with transpose. AMD has incorporated many technologies from its CDNA 3 Radeon Instinct AI ML accelerators on the AI Accelerators of RDNA 4, including enhanced and power-optimized WMMA, improvements to the ops per CU, support for FP8, E4M3 and E5M2 formats, and 4:2 structured sparsity.
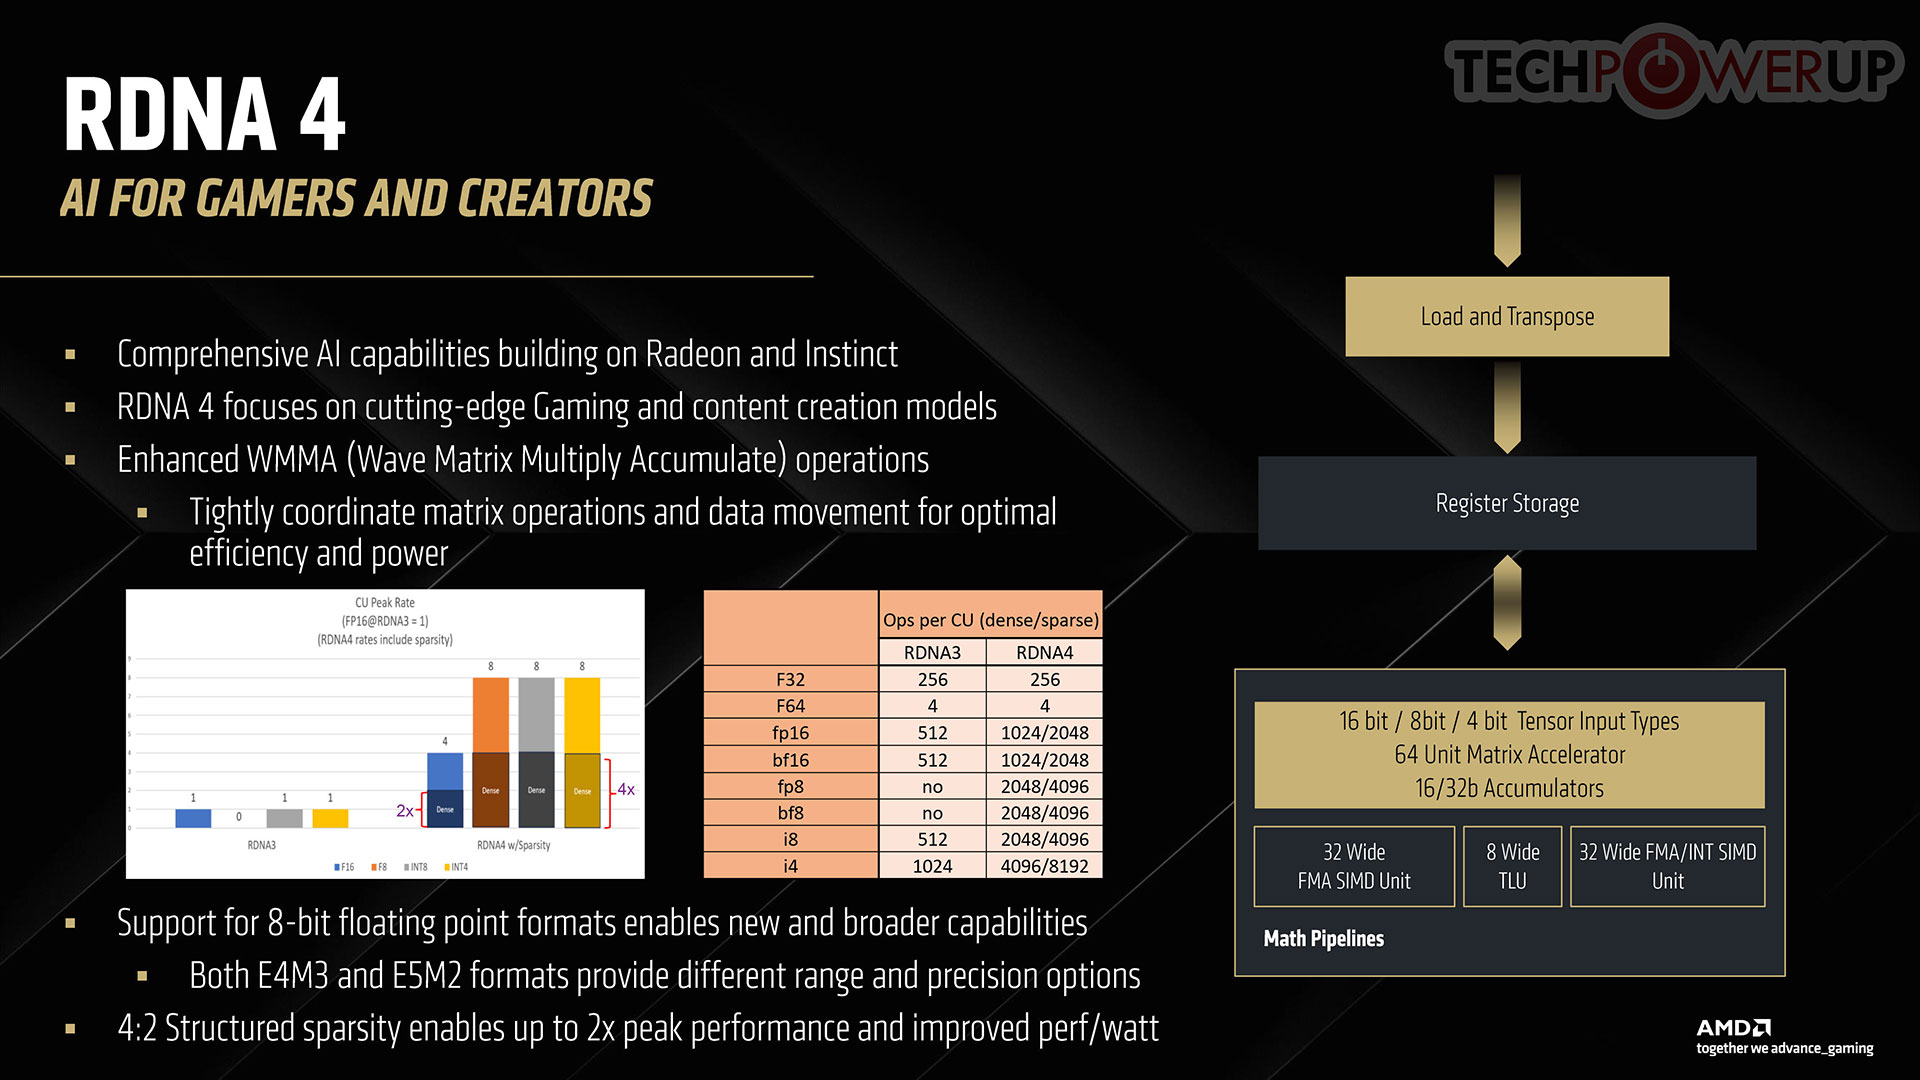
The new generation AI Accelerator comes with two 16-bit and four 8-bit/4-bit dense matrix compute rates, support for 4:2 structured sparsity for doubling throughput, and matrix loads with transpose. AMD has incorporated many technologies from its CDNA 3 Radeon Instinct AI ML accelerators on the AI Accelerators of RDNA 4, including enhanced and power-optimized WMMA, improvements to the ops per CU, support for FP8, E4M3 and E5M2 formats, and 4:2 structured sparsity.
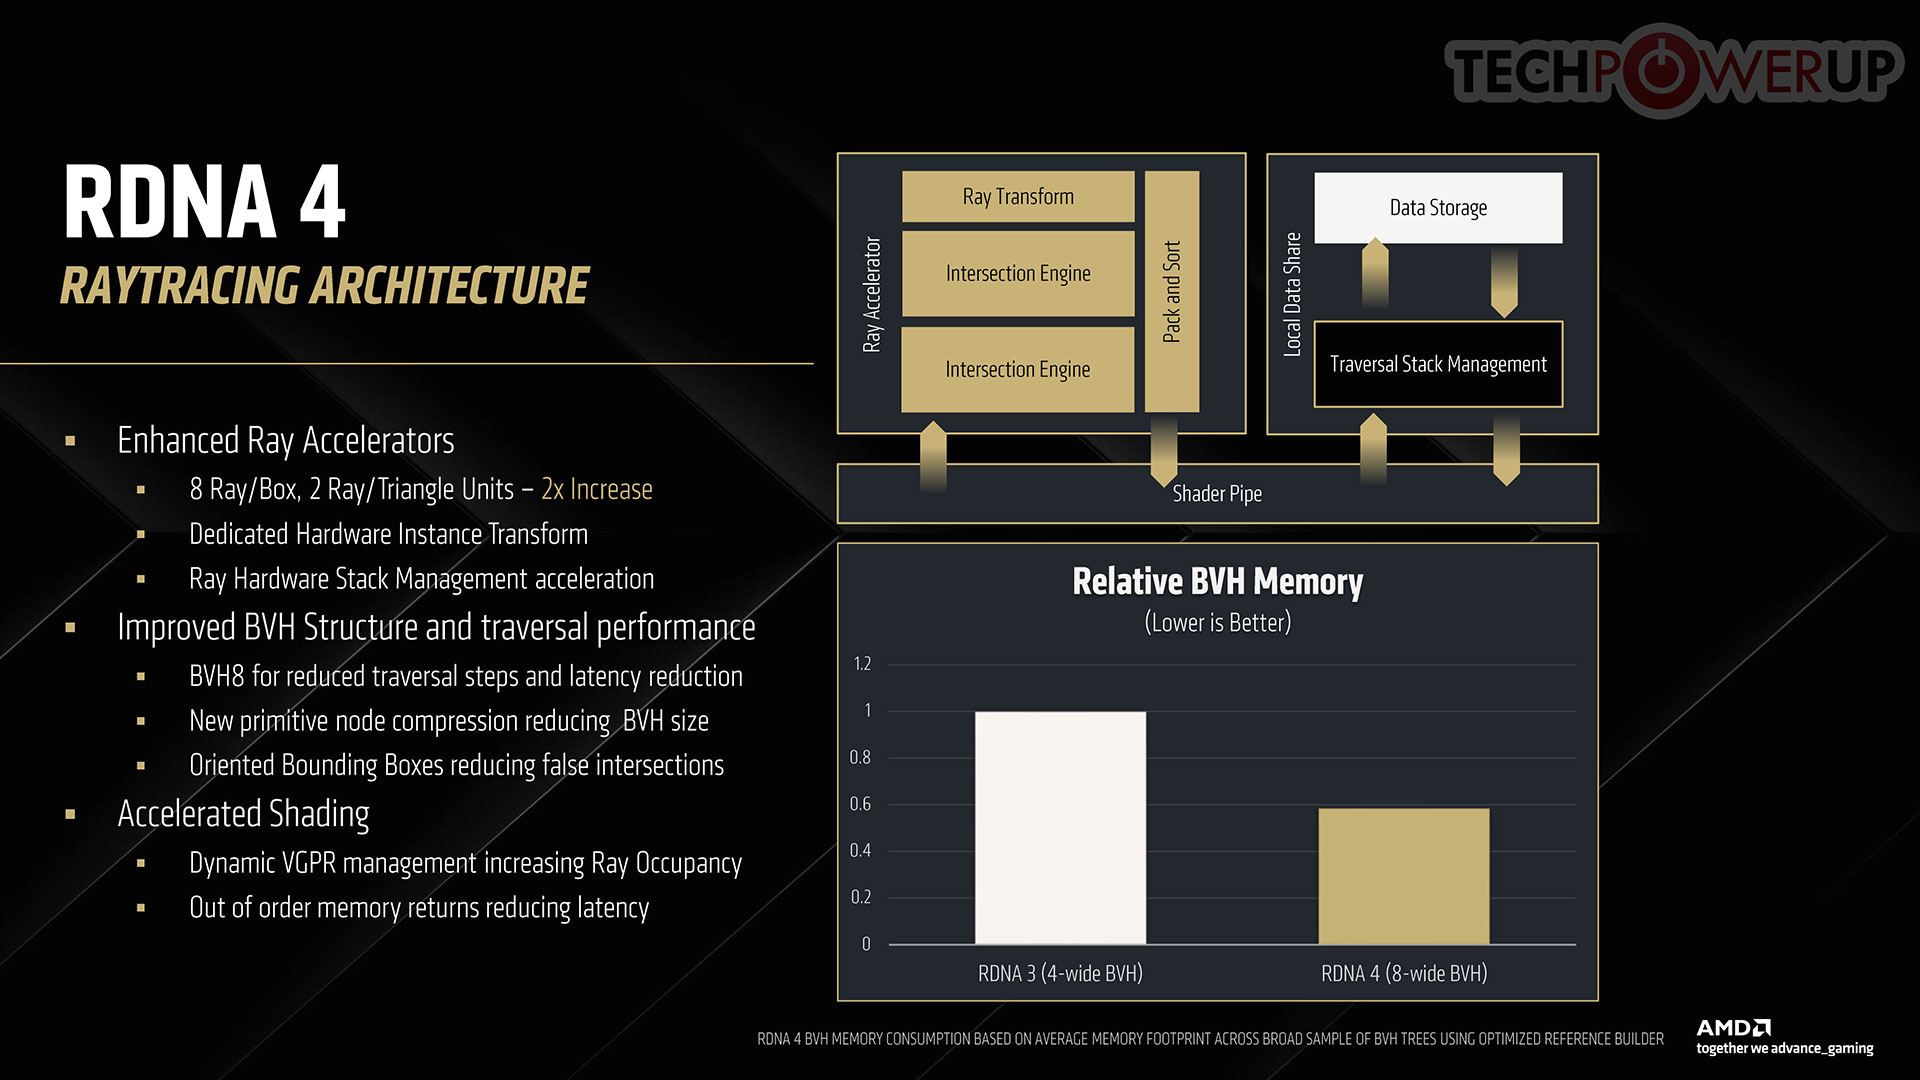
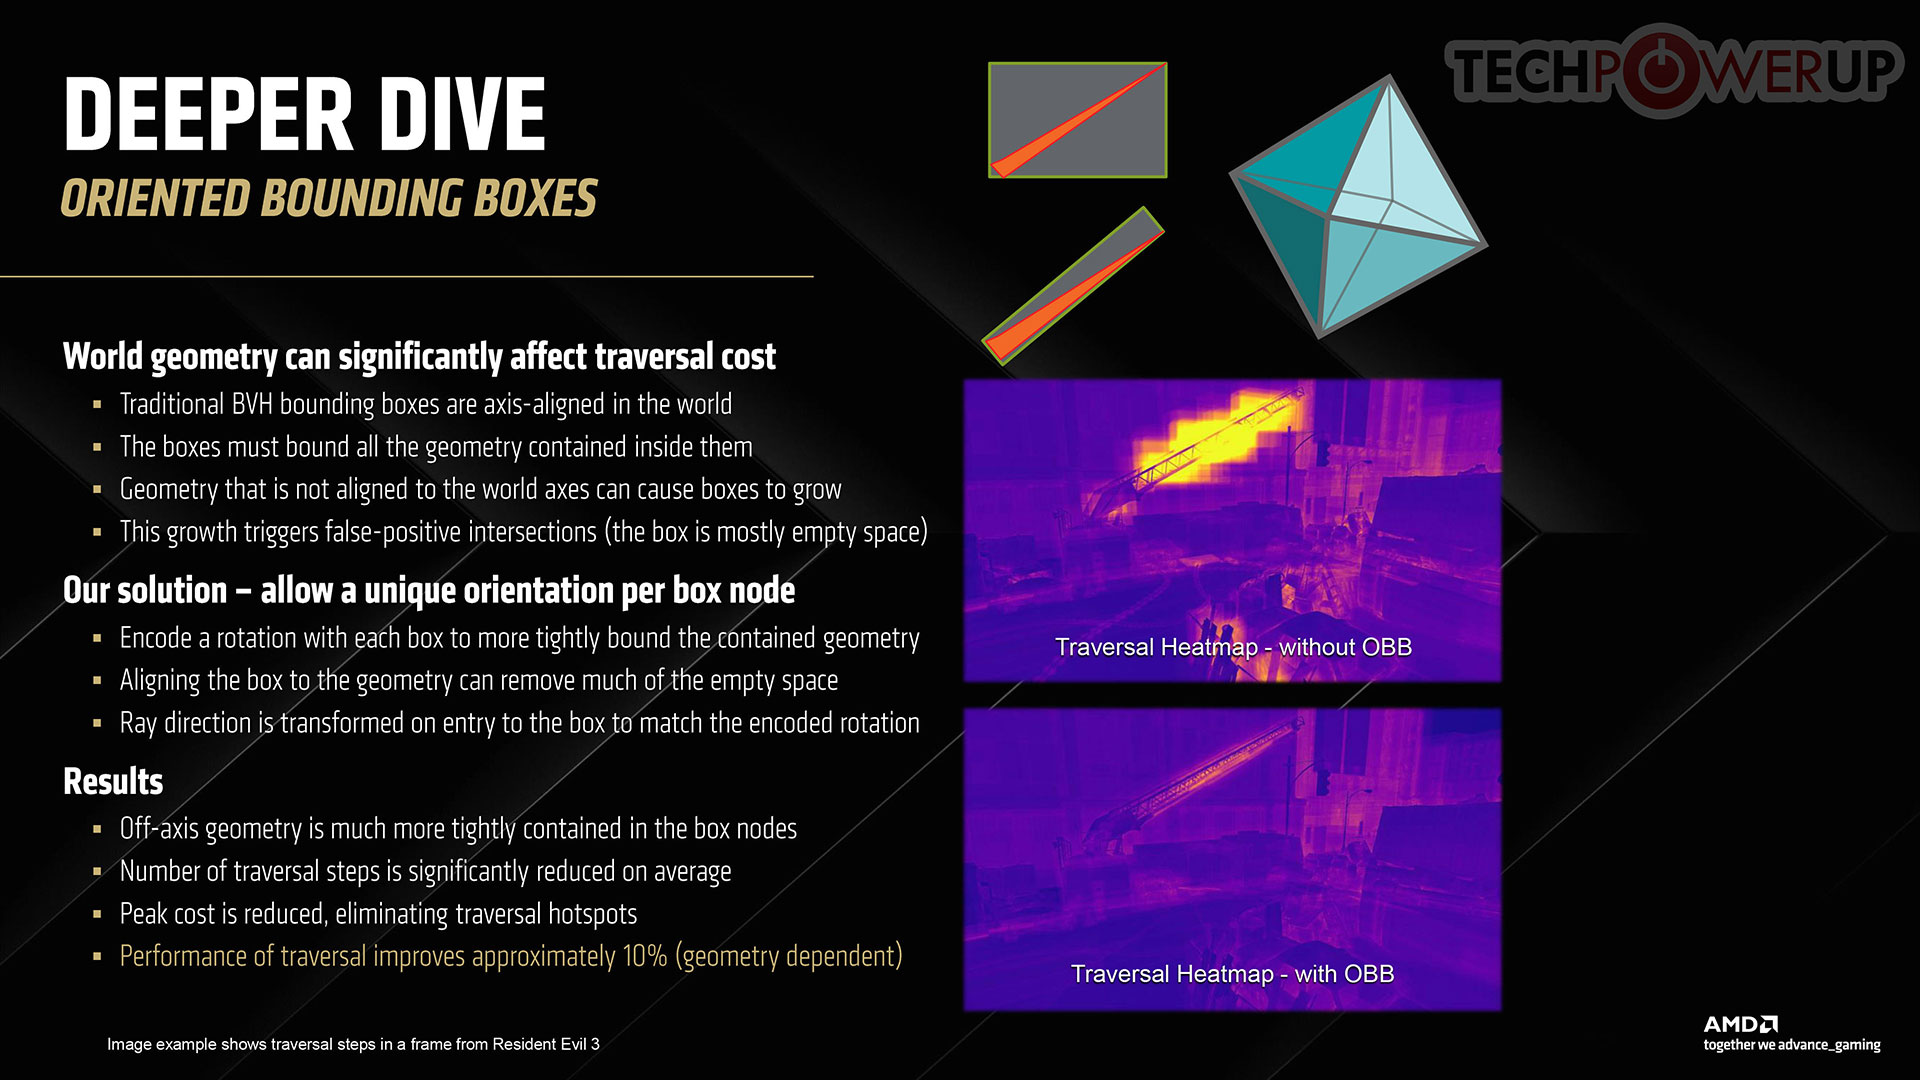
The new generation Ray Accelerator comes with double the box and triangle intersection resources as RDNA 3 RT accelerator, support for hardware instance transforms, improvements to the RT stack management, BVH8 node compression, and a revolutionary feature called oriented bounding boxes. To contain the number of rays really needed to be tested against an object, modern ray tracing technologies use something called a bounding box, which defines a region in which a geometry has to be tested against rays. Most of the time, the geometry is of a vastly different shape and smaller than the shape of a bounding box, which introduces false intersections, and wastes ray testing resources. AMD innovated a way to turn this bounding box into a 3D shape by giving it a Z-axis component, so the bounding box is oriented closer to the shape of the object to be tested, reducing the number of rays needed to be tested against it.
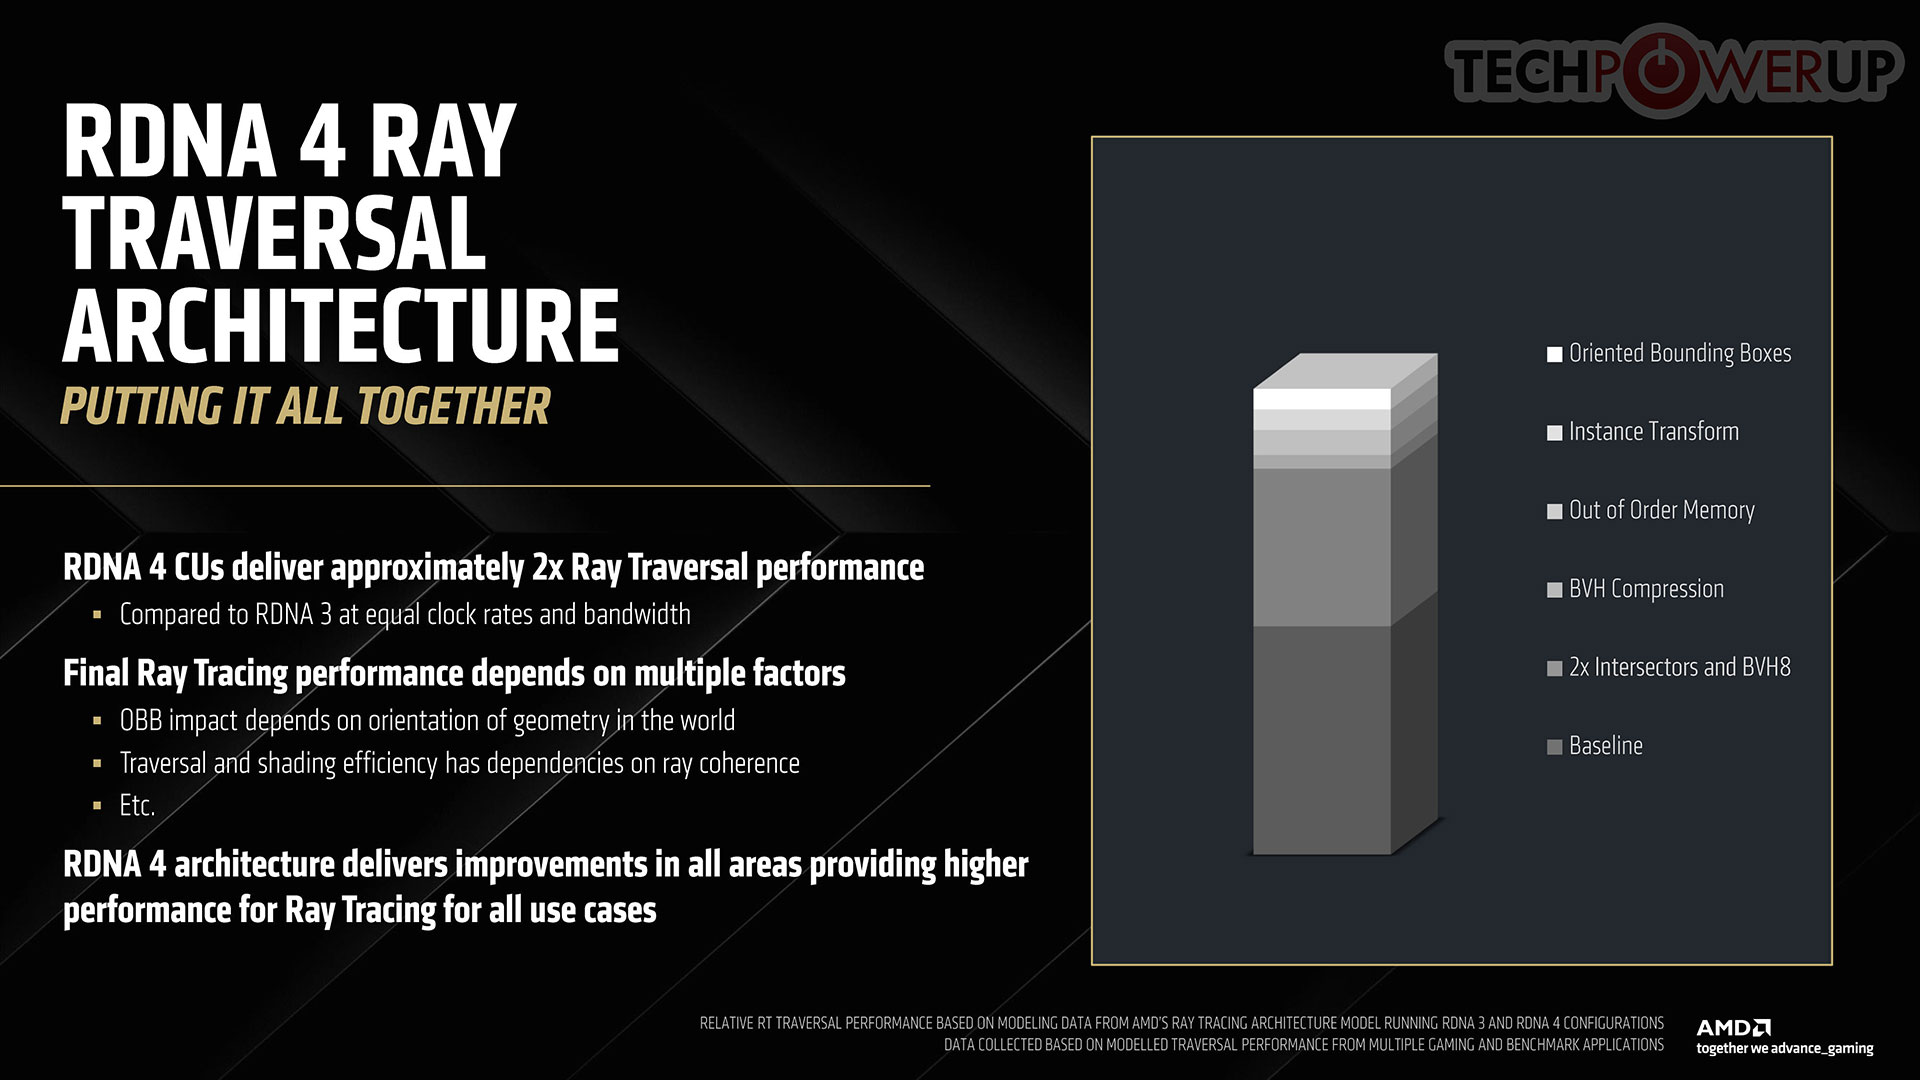
This graph highlights the contribution of various components toward the 100% generational ray traversal performance gain, allowing AMD to make do with a CU count of 64, with RDNA 3 being the baseline.
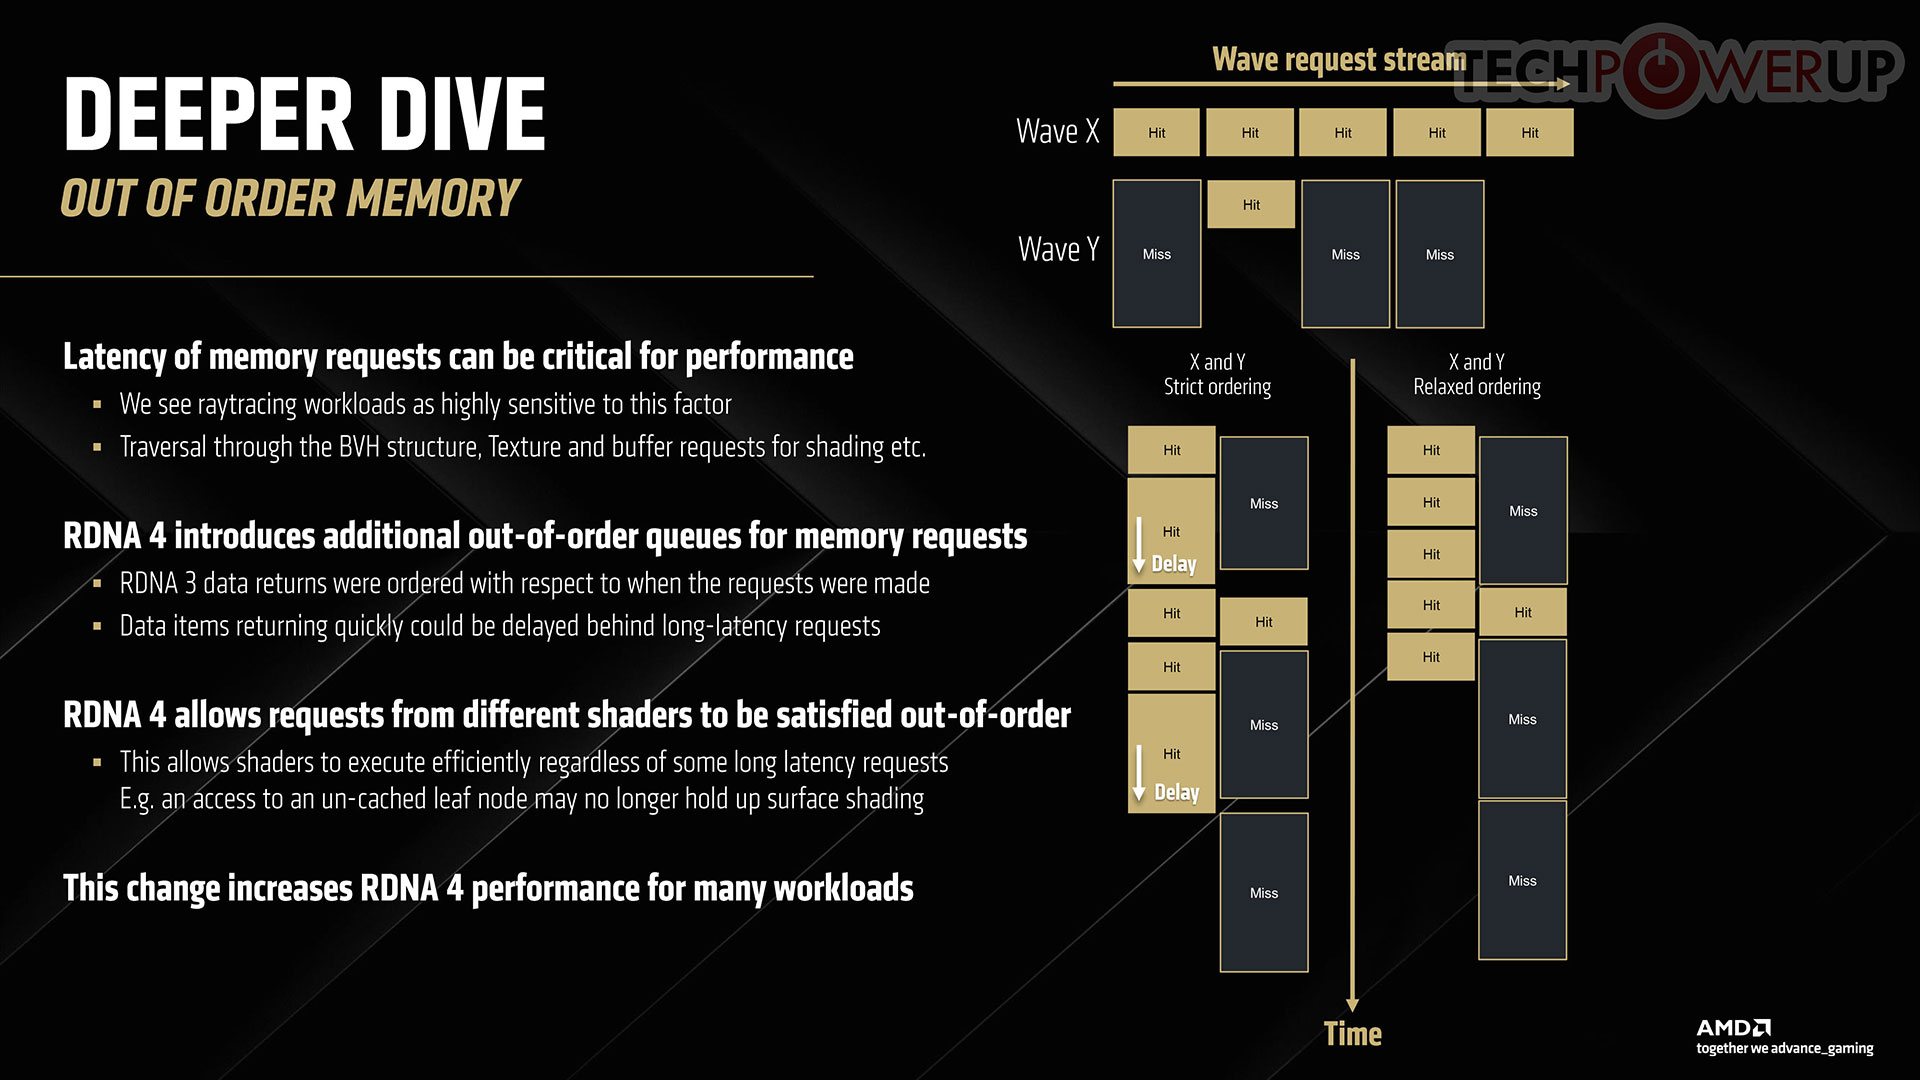
Both ray tracing and ML acceleration are memory sensitive applications, so AMD innovated a revolutionary change to its memory management system with the introduction of new out-of-order memory. All math is executed in waves on an RDNA GPU, and mutual dependencies between waves can cause memory request stream misses, as one wave's memory request queue waits for the other wave to complete its task. This is solved with a new out-of-order (relaxed ordering) memory management. This graph highlights the contribution of various components toward the 100% generational ray traversal performance gain, allowing AMD to make do with a CU count of 64, with RDNA 3 being the baseline.
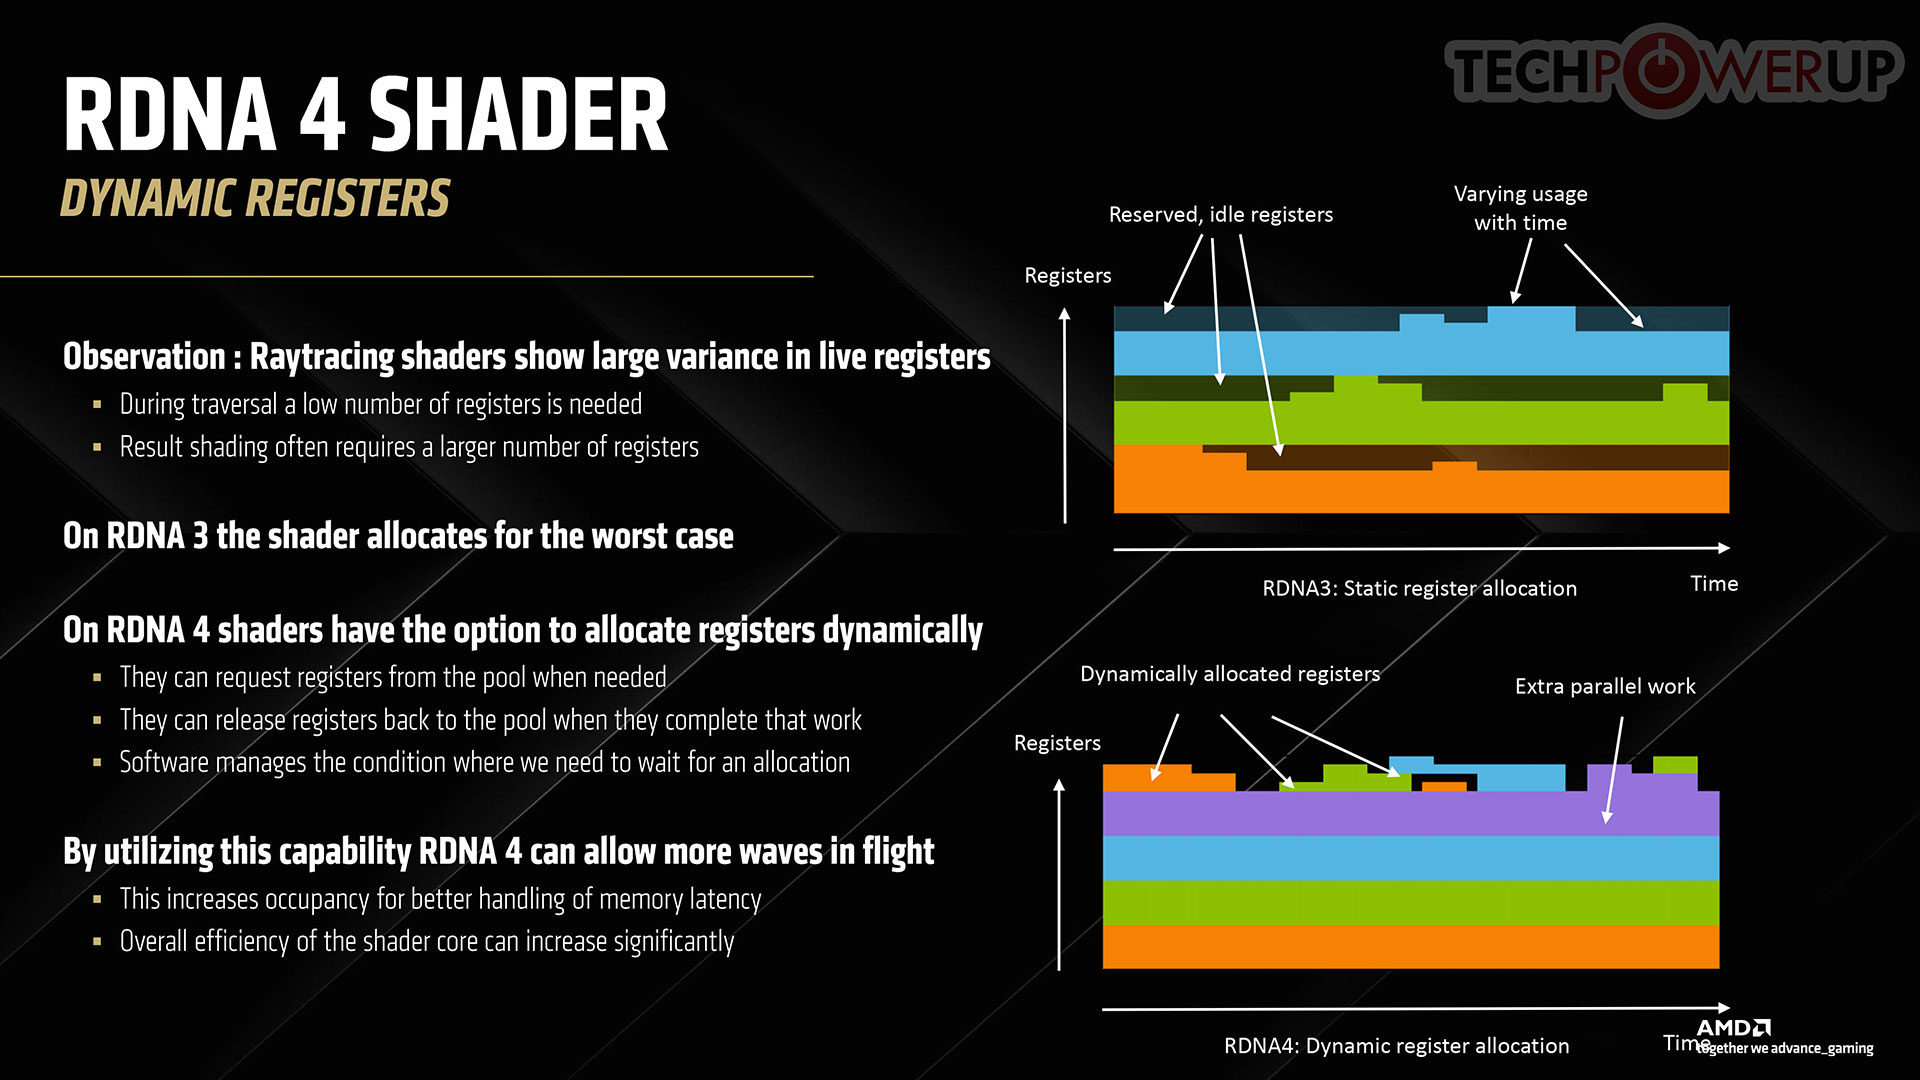
On AMD, a fairly big chunk of the ray tracing stack continues to be executed on shaders, but the company has made advances to ensure the cost of ray tracing on the shader resources of the GPU is minimal, with the introduction of Dynamic Registers to improve parallelism.
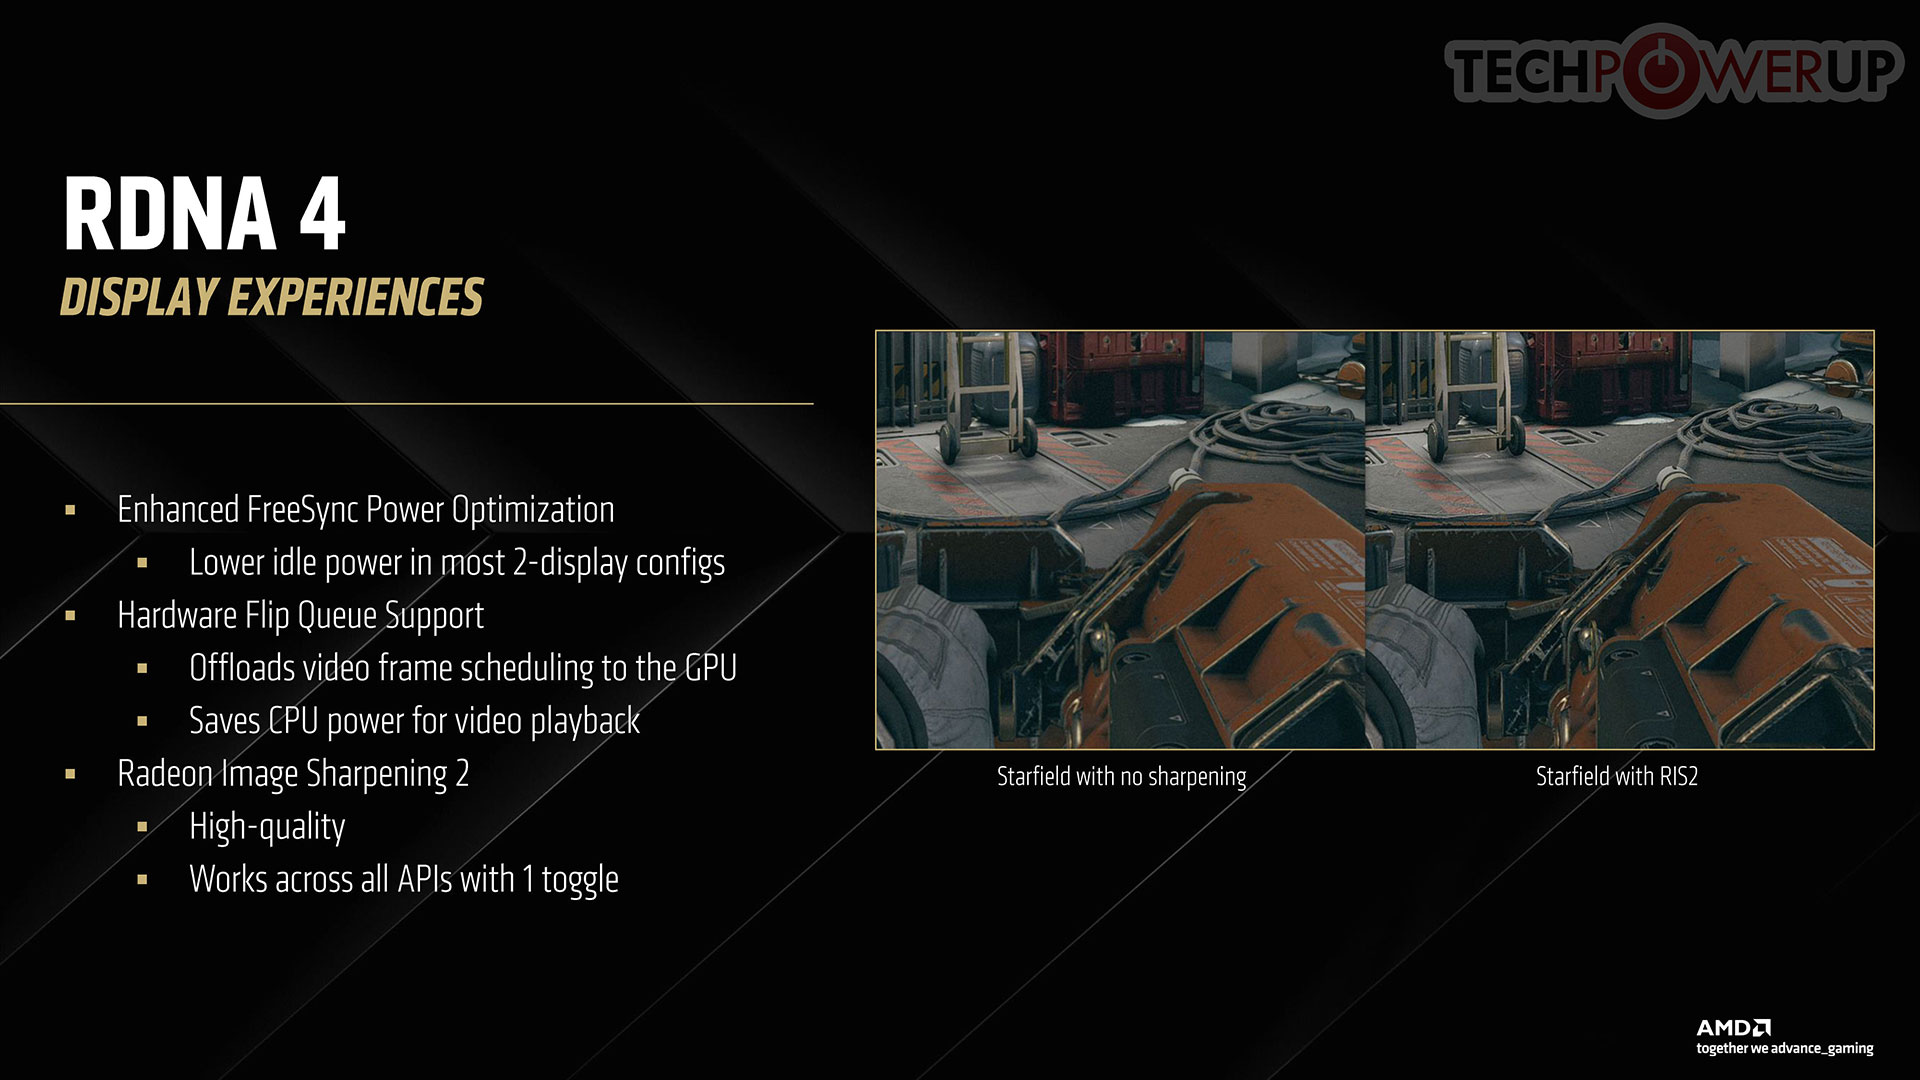
The new Radiance 2 Display Engine comes with major hardware updates that reduce GPU idle power draw in multi-monitor setups. The engine also comes with hardware flip-metering support (something NVIDIA also introduced with Blackwell, and which enables Multi-Frame Gen on the RTX 50-series). Flip-metering improves video frame pacing to the GPU and reduces CPU overhead for video playback. There is also a display engine level hardware image sharpening component that drives Radeon Image Sharpening. As for I/O, you get contemporary DisplayPort 2.1a and HDMI 2.1b, the maximum bitrate is UHBR 13.5.
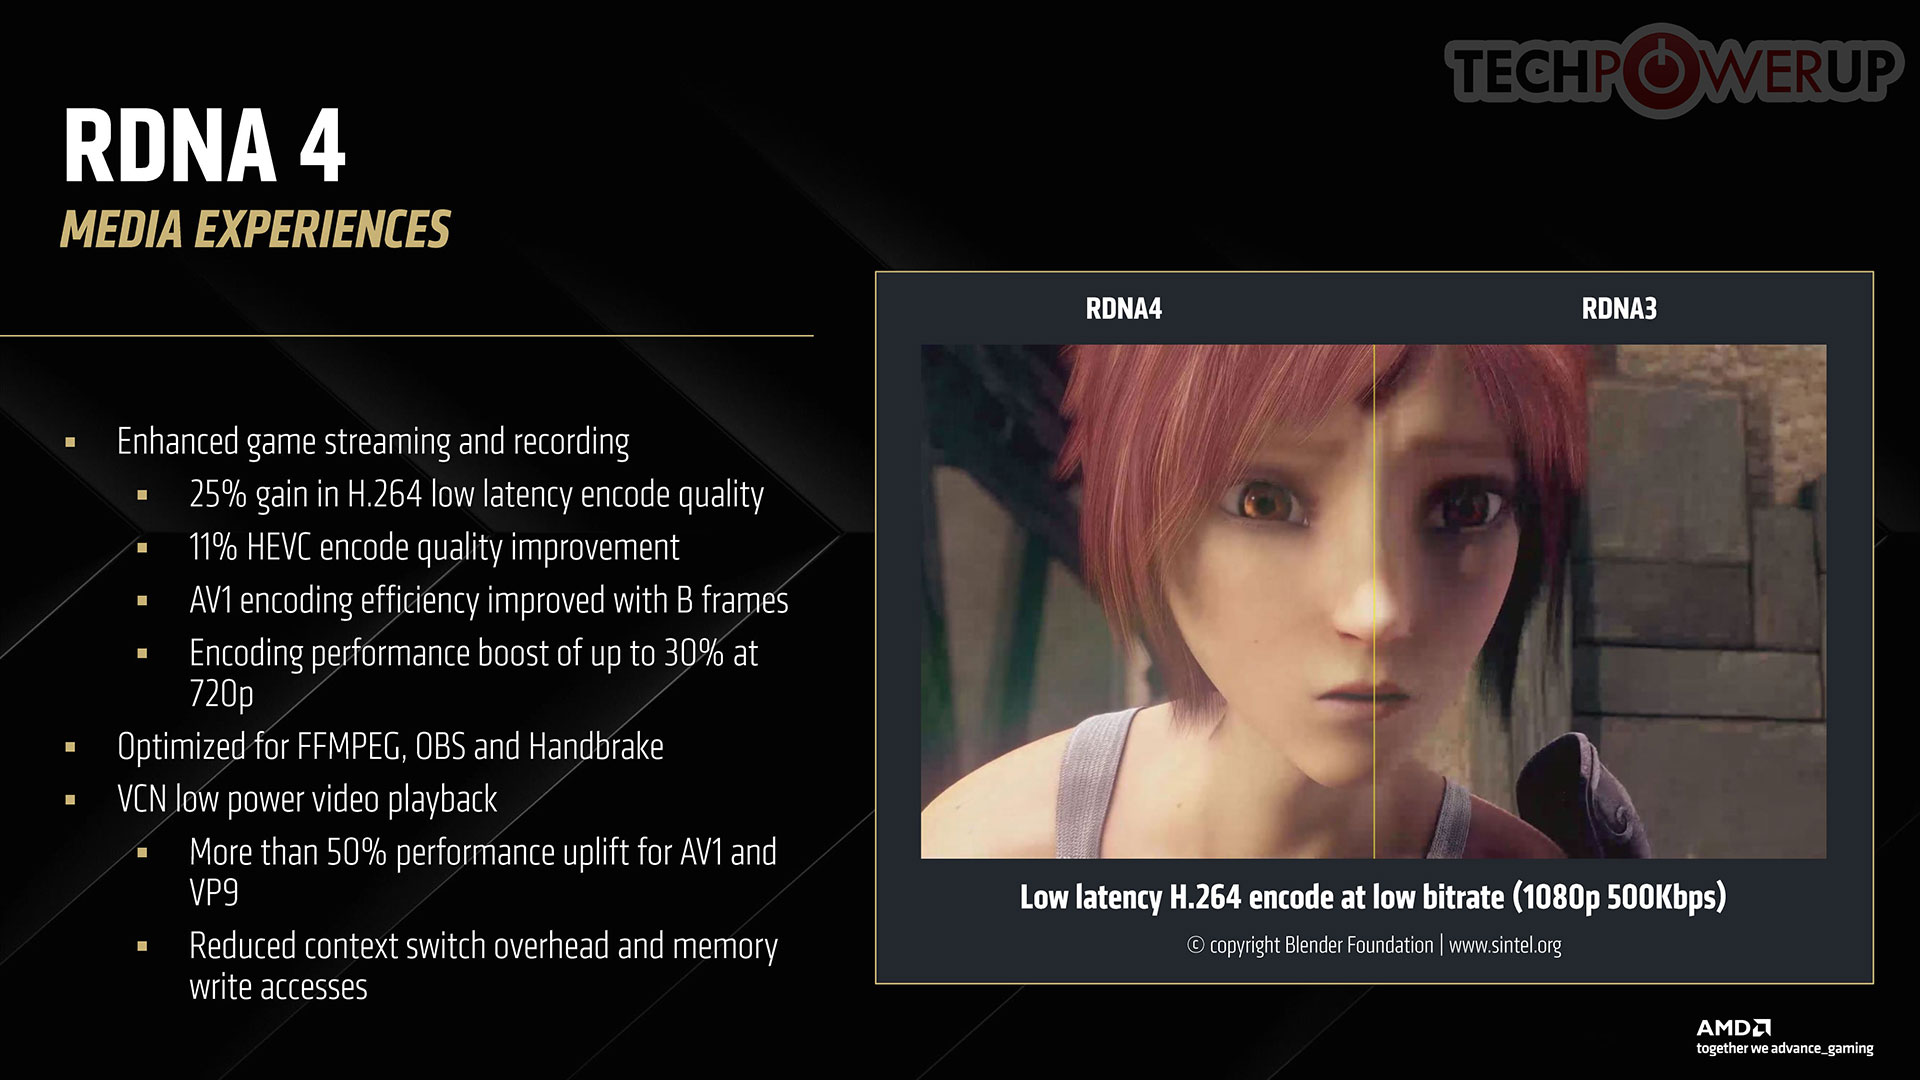
Navi 48 comes with a dual media engine, each of the two can perform concurrent encoding and decoding, and so the implementation resembles an NVIDIA GPU having two each of NVENC and NVDEC units. The new generation media engine offers a 25% increase in H.264 low-latency encode quality, and an 11% improvement in HEVC encode quality. AV1 encode and decode get B-frames support, vastly improving bitrates. The media engine posts a 50% generational performance uplift (measured in encoder/decoder frame rates), with reductions in memory overhead.
AMD FSR 4 and New AMD Software Features
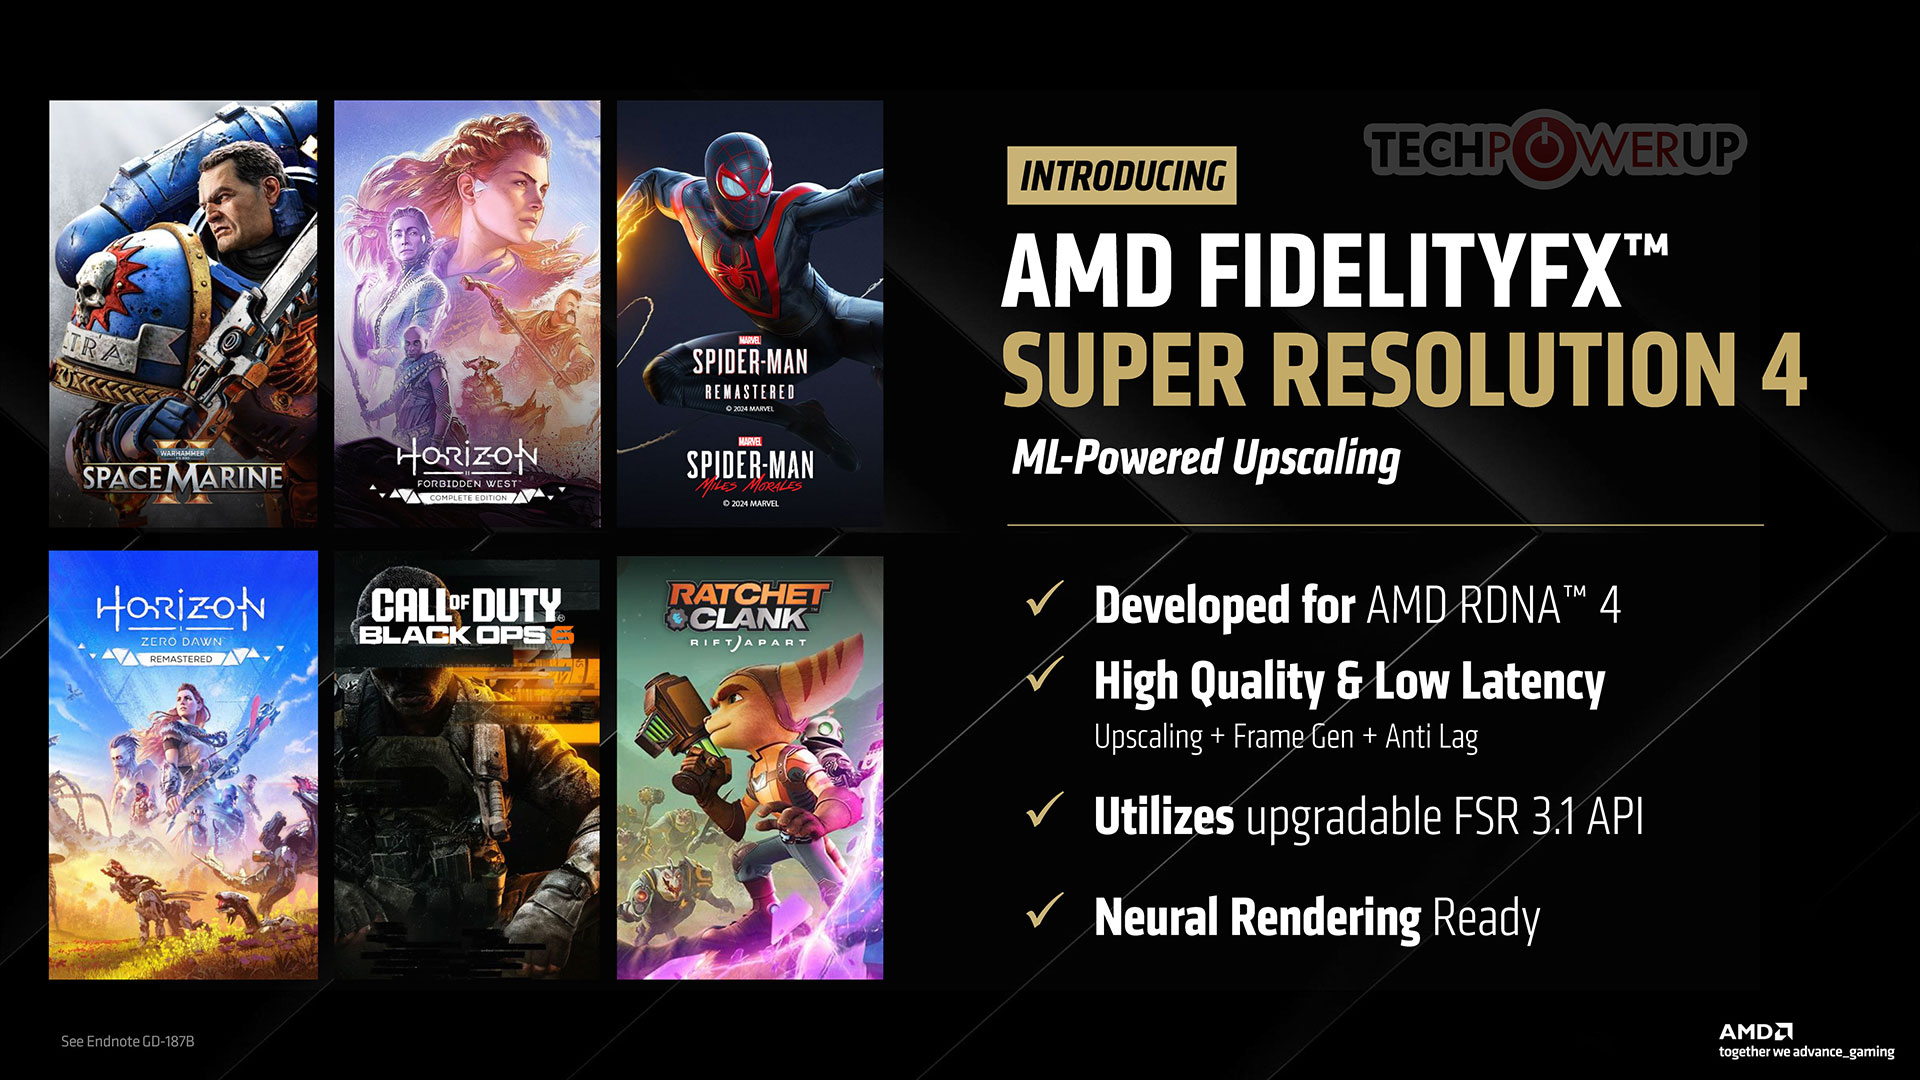
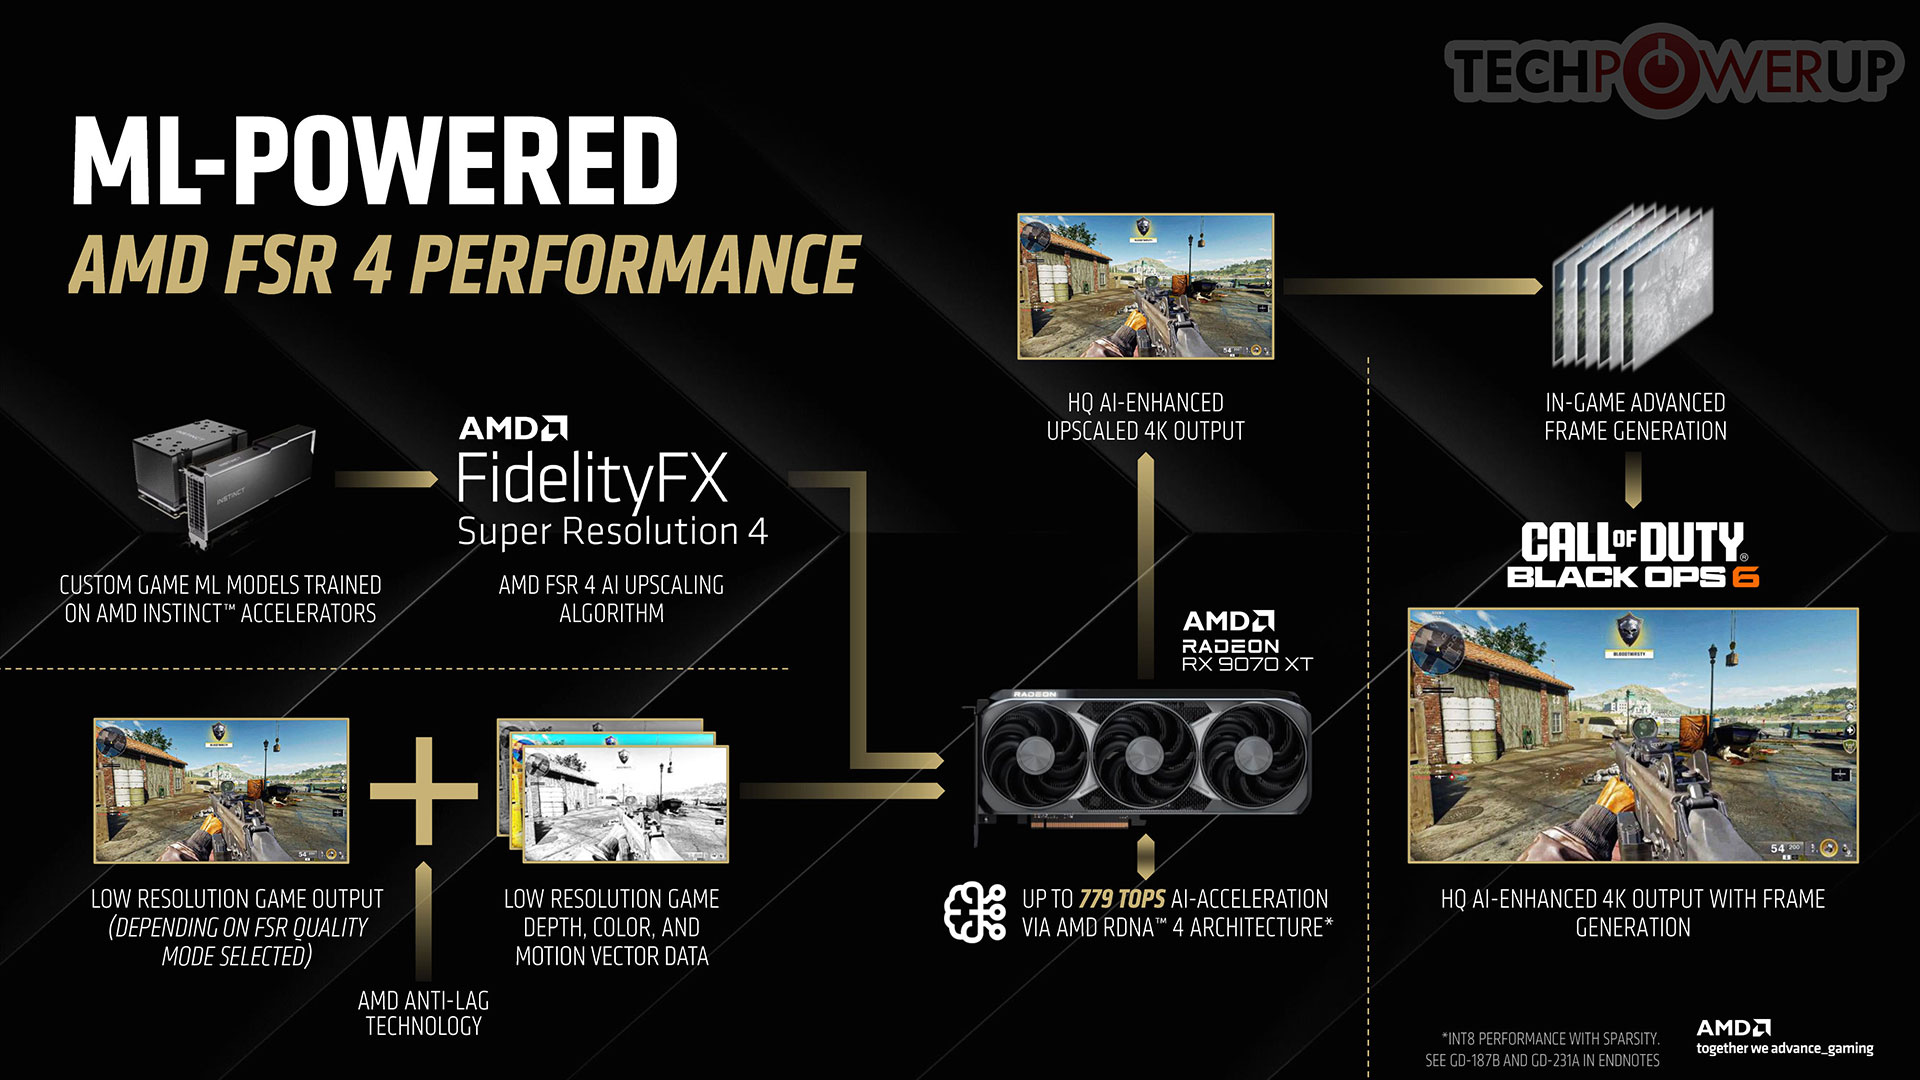
With the Radeon RX 9000 series, AMD is debuting FSR 4, the latest version of its performance enhancement suite. FSR 4 introduces the biggest tech update since FSR 2, which also makes it exclusive to the RX 9000 series. With the RDNA 4 generation of GPUs offering significantly higher ML compute throughput, AMD designed a new ML-based upscaler to reconstruct details of the upscaled frame. In that sense, FSR 4 is technologically close to DLSS. RDNA 4 GPUs also leverage AI DNNs to de-noise ray tracing and path tracing, unburdening the shaders.
An AI ML based upscaler requires ground truth data, and just as NVIDIA goes through the painstaking task of training game-specific ML models that can later be shipped to end-users through game developers and as driver updates; AMD has set up a large FSR 4 data-center of its own, powered by Radeon Instinct MI300-series AI GPUs for the task. On the client side, the ML-based upscaler needs the dedicated AI acceleration hardware from the RDNA 4 family. The frame generation technology appears to be carried over from FSR 3 Frame Generation, and is essentially a smart frame interpolation technology.
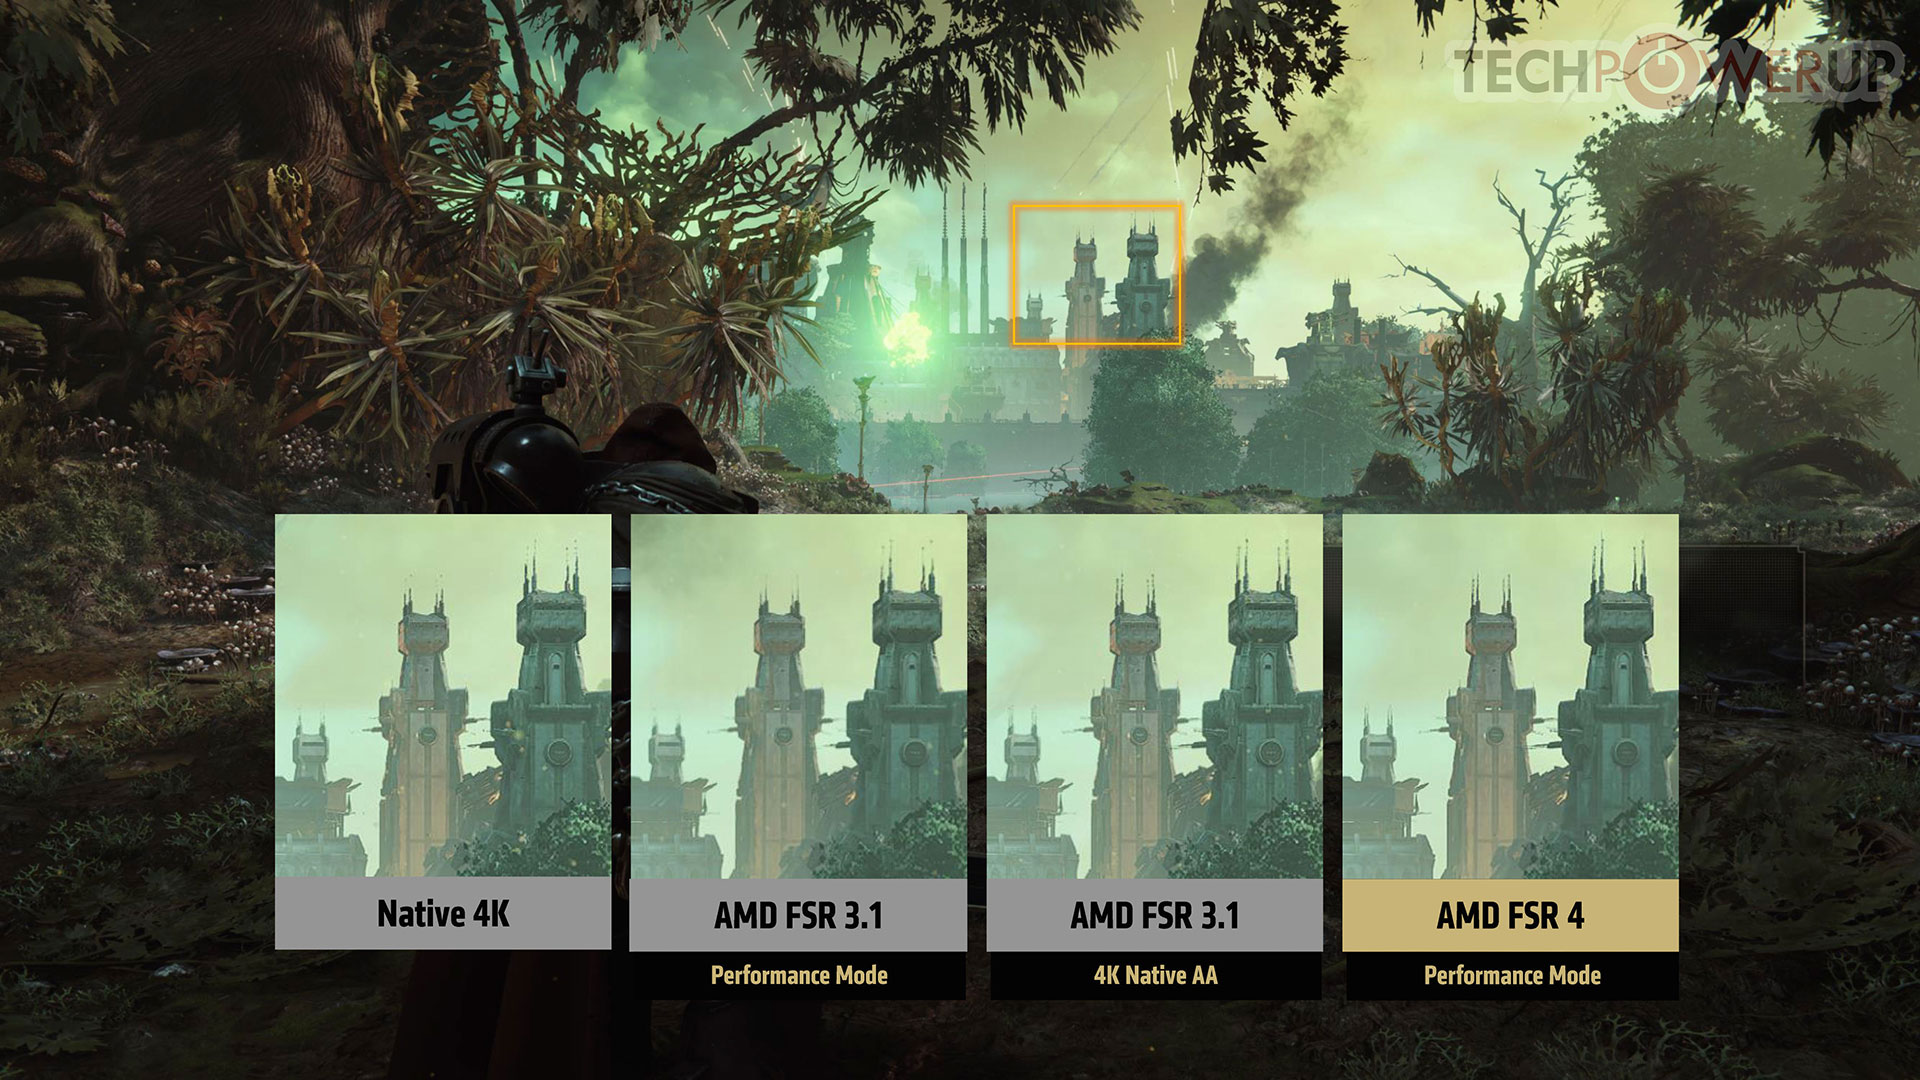
AMD in its presentation provided examples of image quality for FSR 4, claiming that in some cases, FSR 4 presents geometry more accurately than even native resolution. While AMD didn't detail it, FSR 4 comes with preparation for neural rendering. Given that Microsoft has now standardized neural shaders, and the ability for applications to directly address AI acceleration hardware on the GPU via the DirectX API, AMD could in the near future implement neural rendering, however, the company hasn't detailed a timeline. FSR 4 is ready for neural rendered objects.
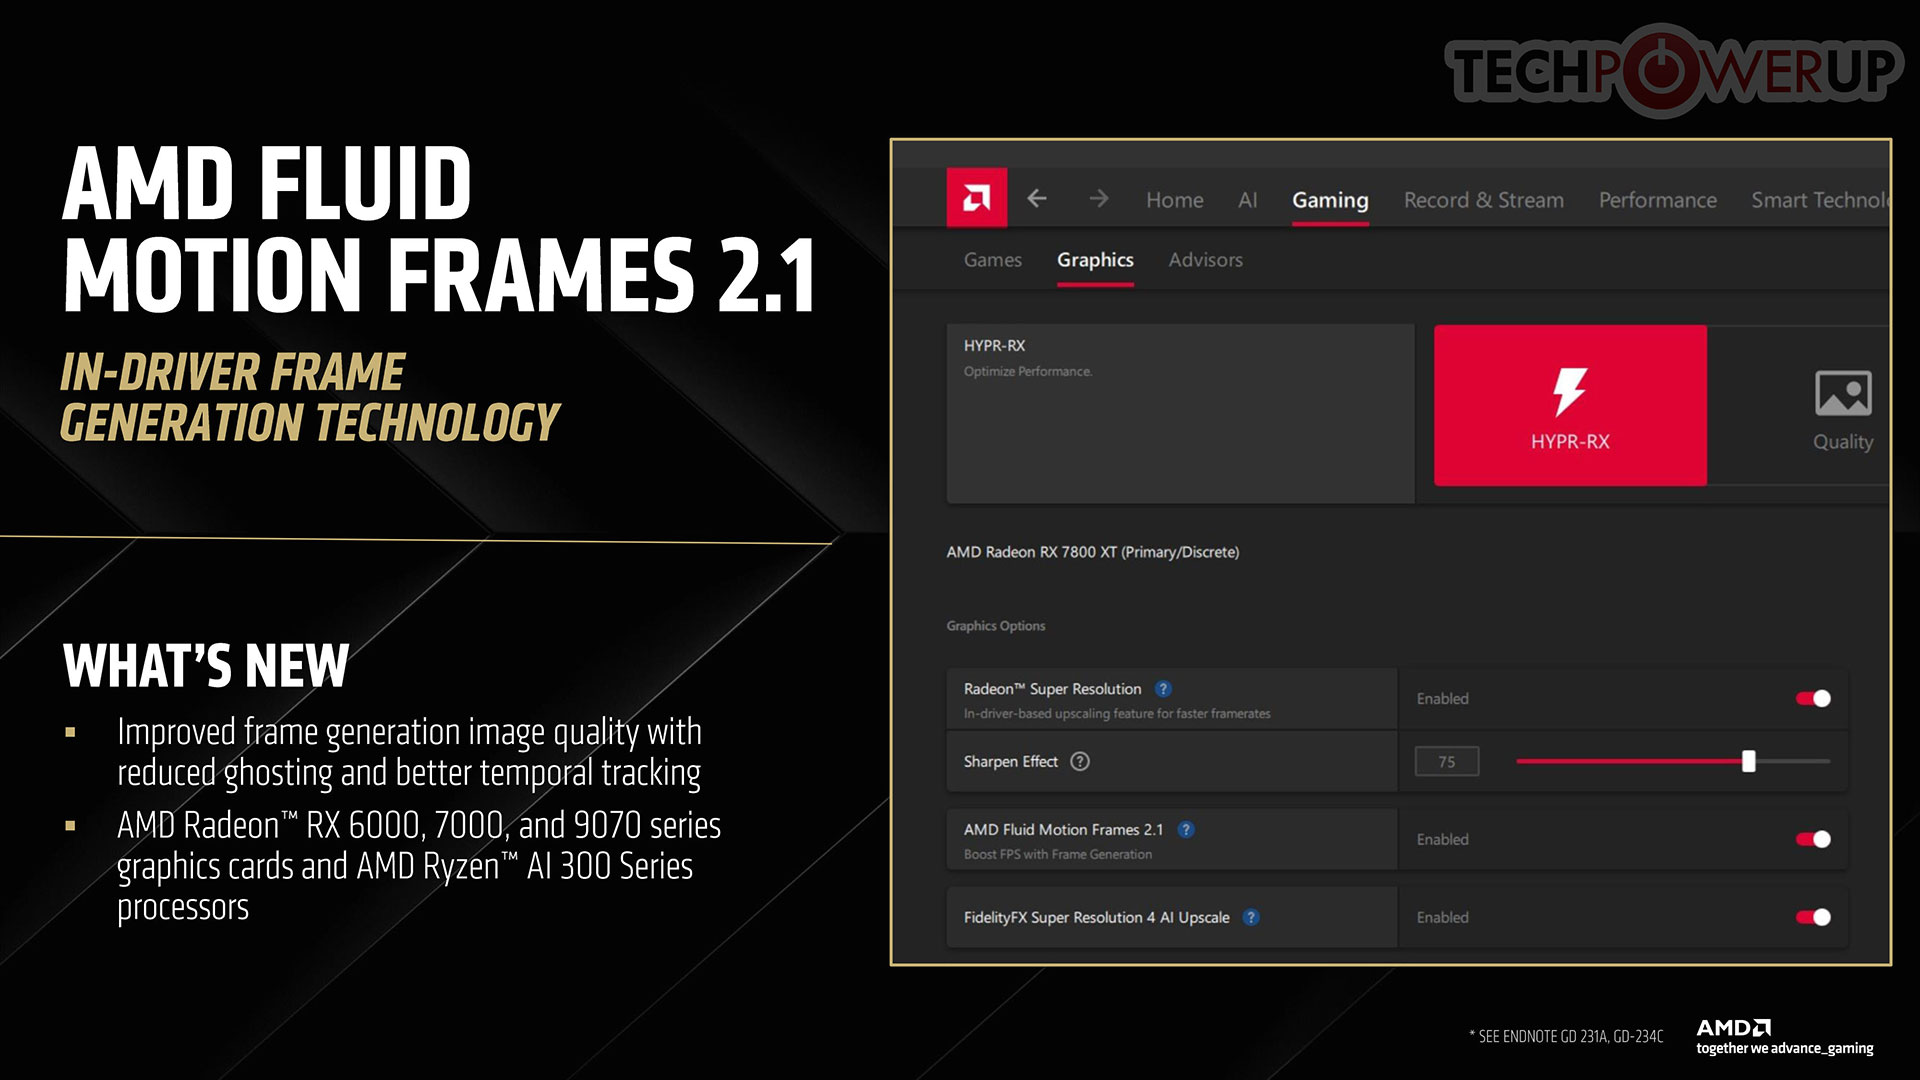
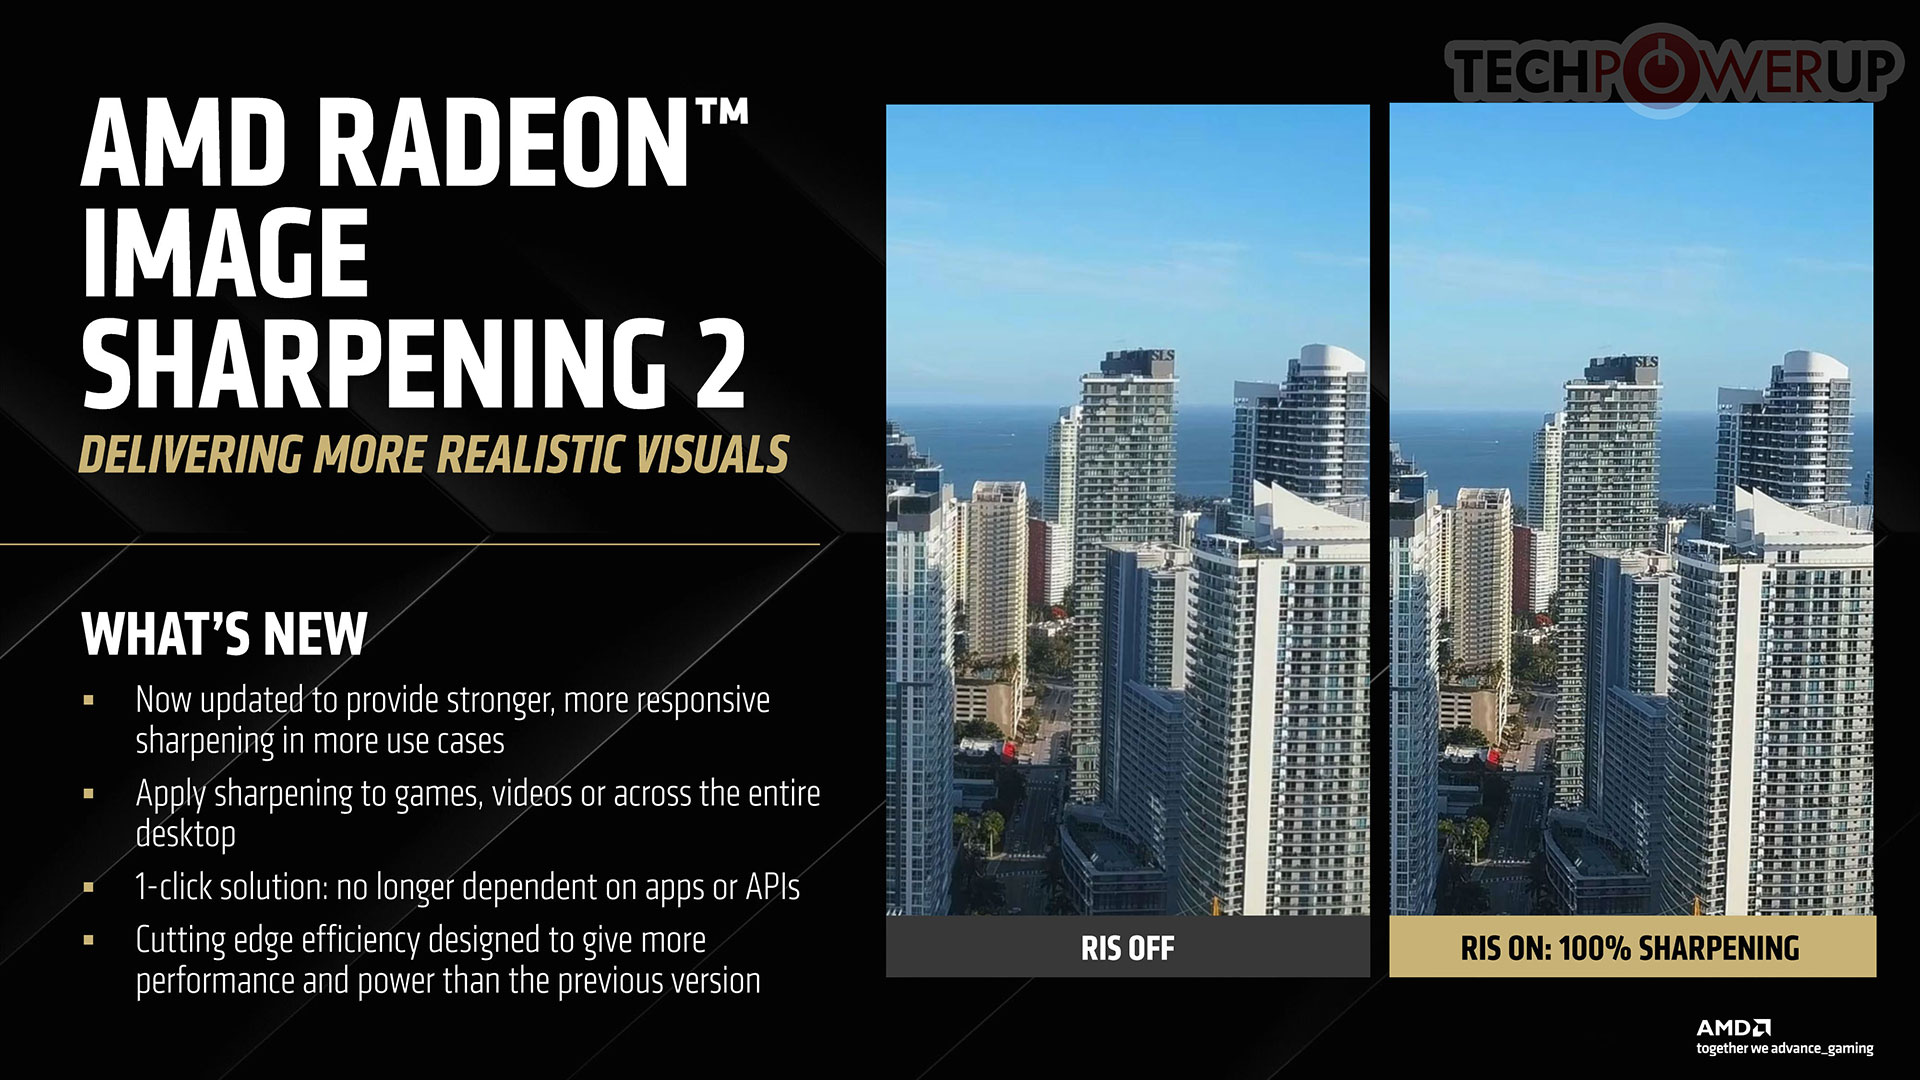
Fluid Motion Frames gets an update with FMF 2.1, with improved image quality, reduced ghosting, and improved temporal tracking. The company also updated its API-agnostic image sharpening tool, with the introduction of Radeon Image Sharpening 2 (RIS 2).
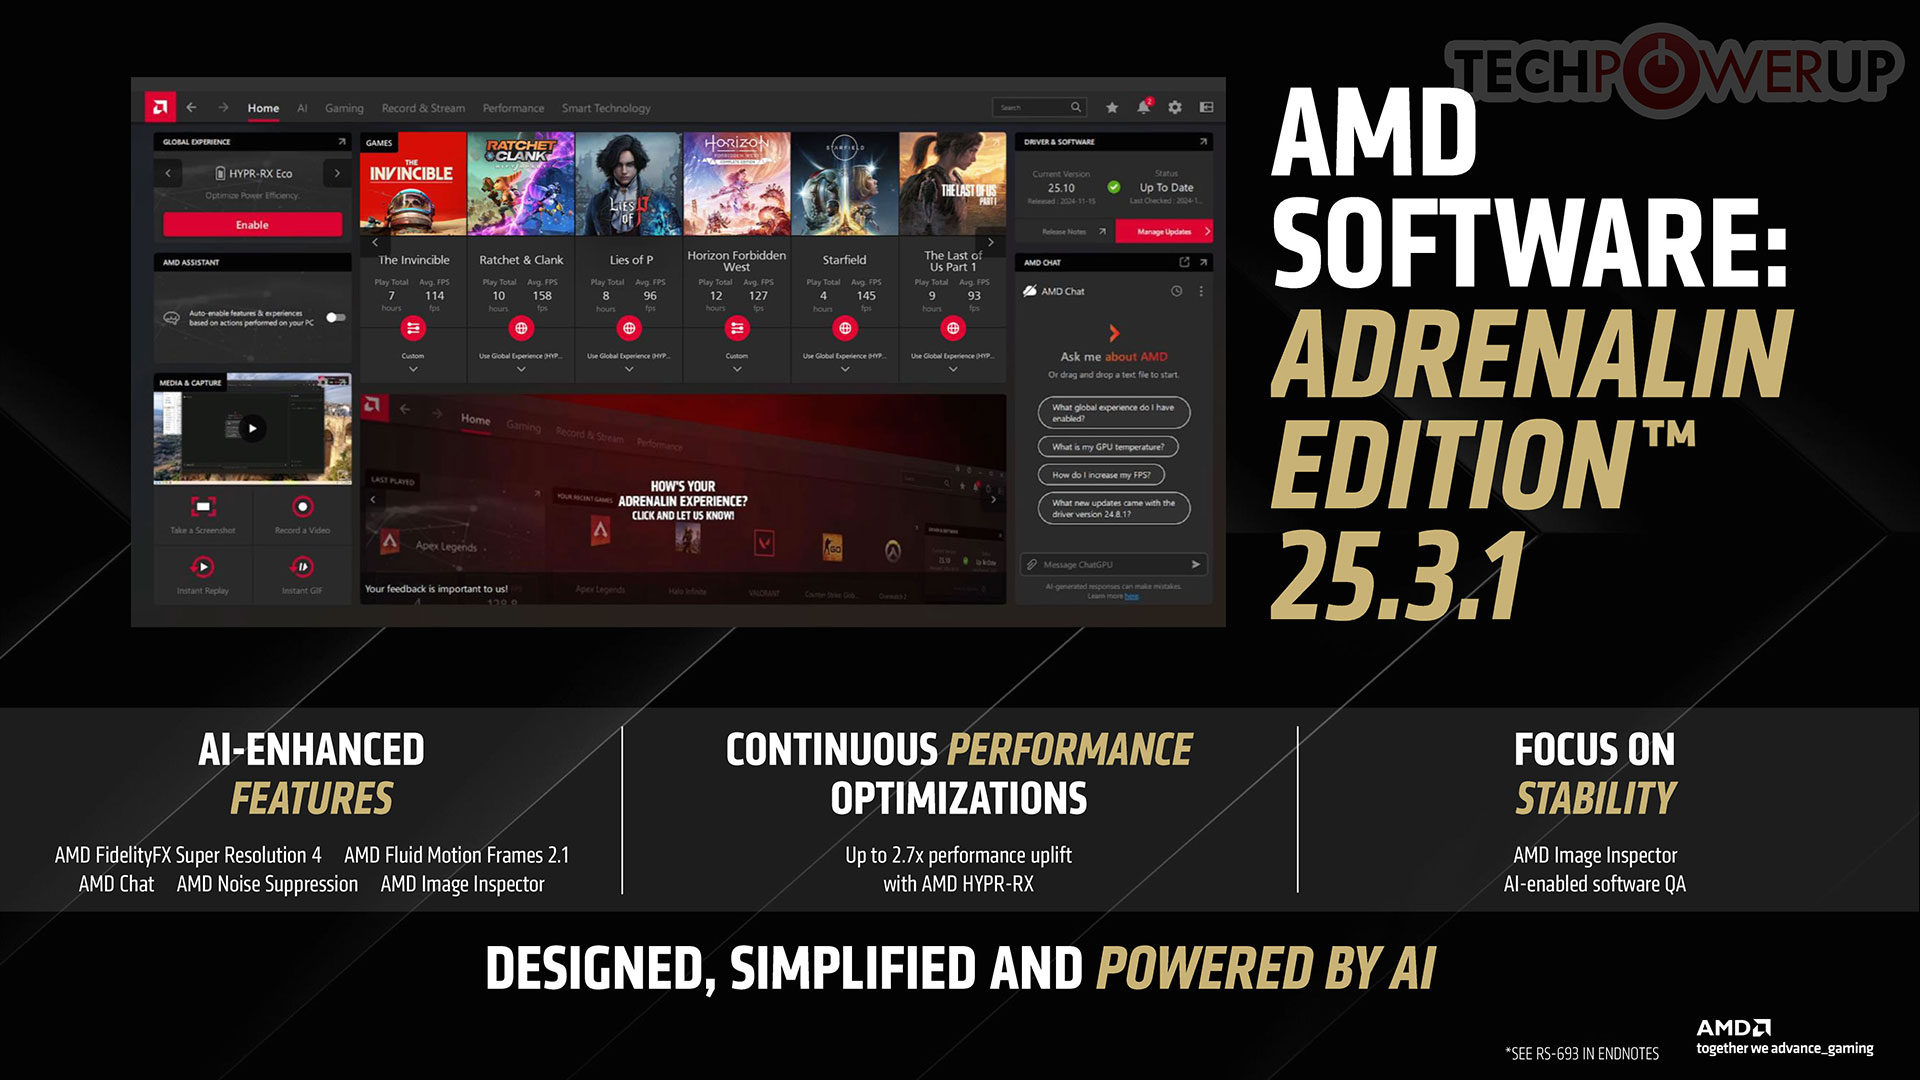
AMD provides a slick driver frontend application called simply "AMD Software." AMD improved the way in which users can report bugs, artifacts, or corruption in games, through a voluntary (opt-in) feature called AMD Image Inspector.
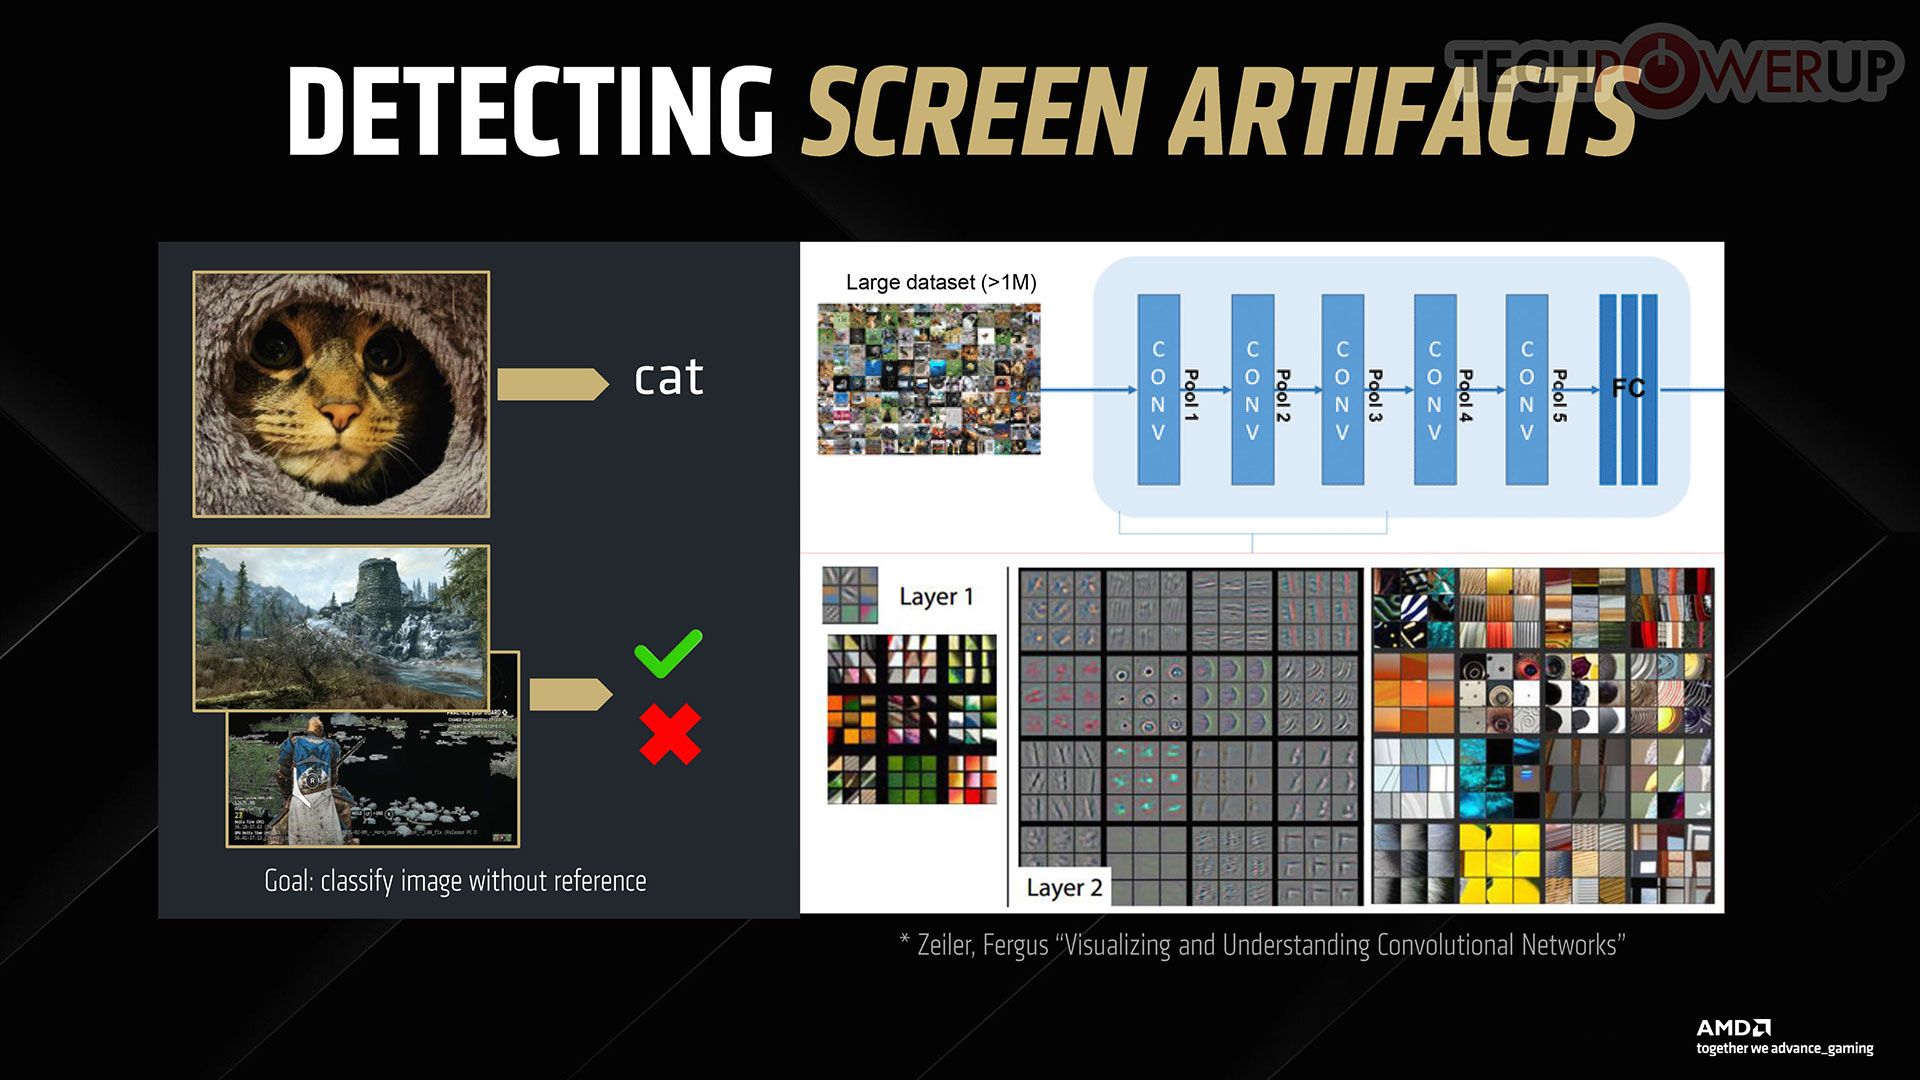
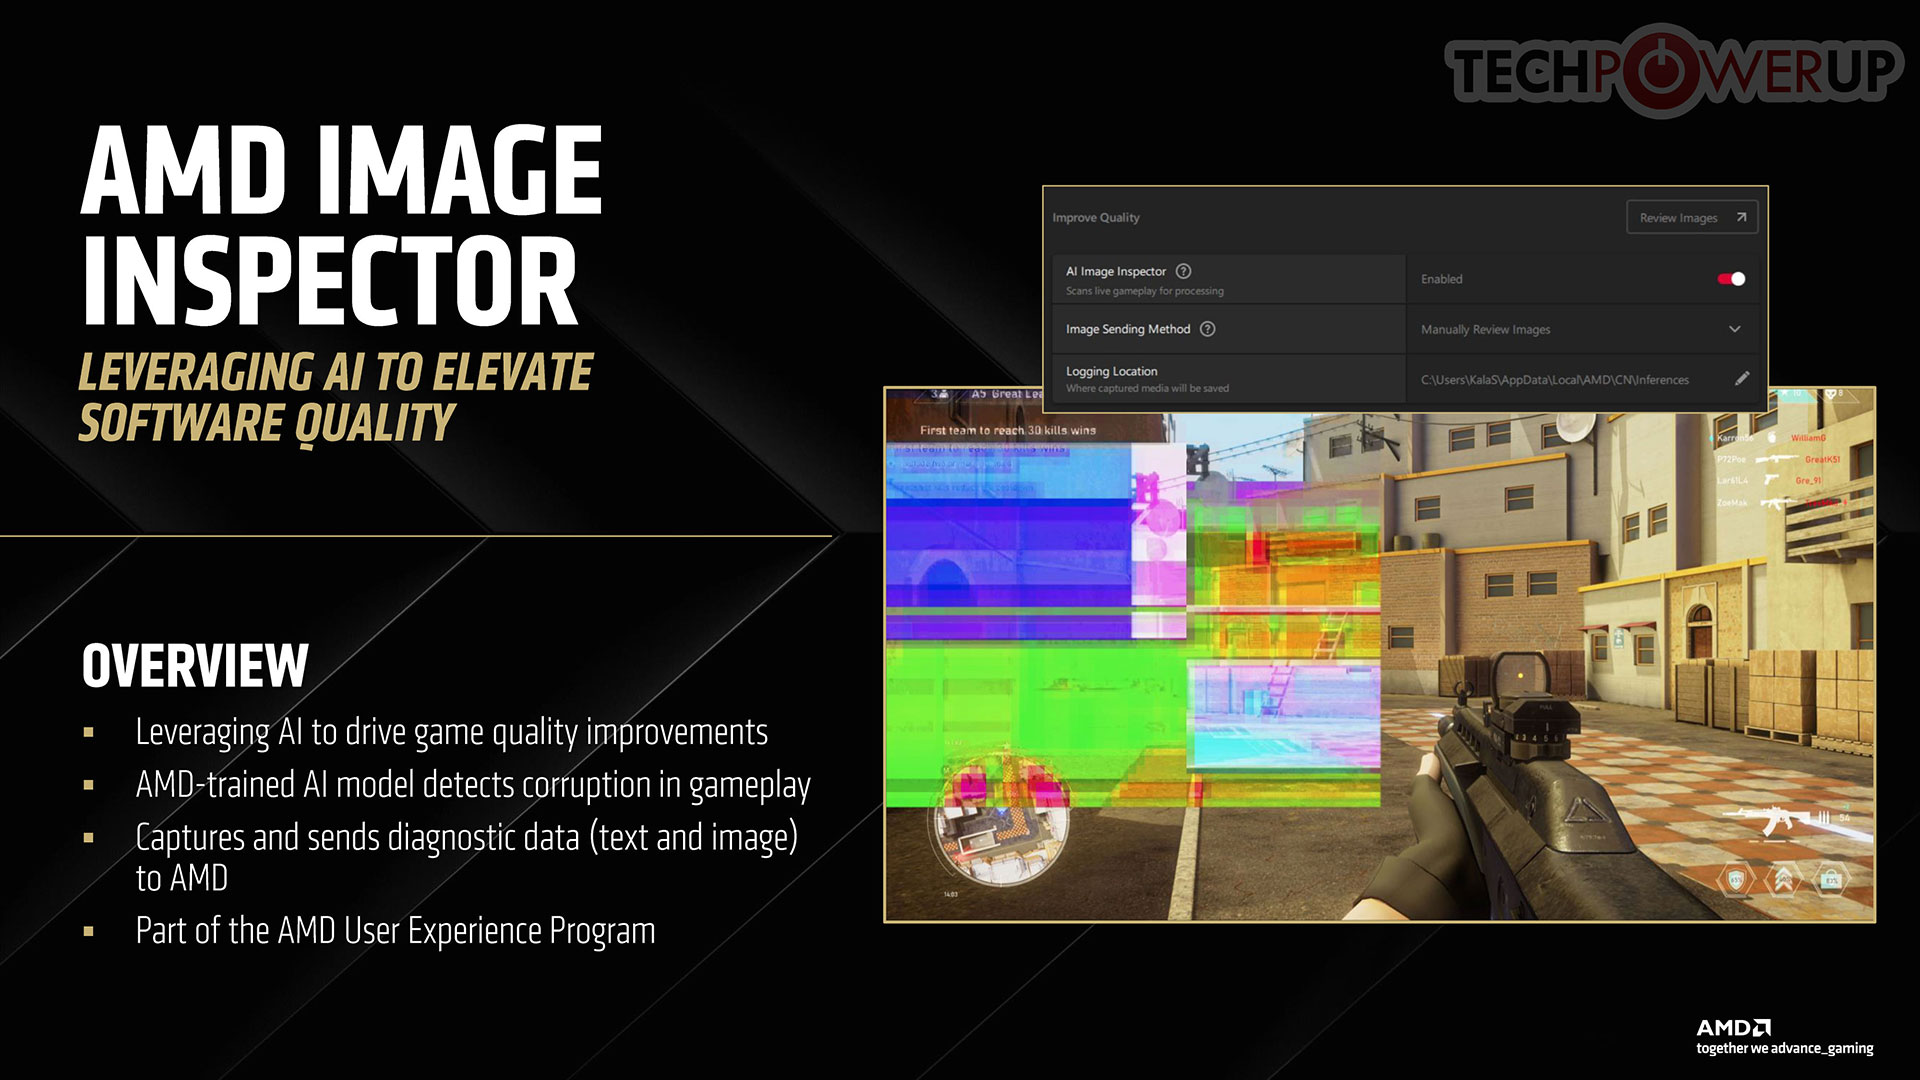
As you submit a screenshot or video sequence to AMD, the company uses an AI model to identify rendering bugs, or corruption in the display. The entire driver-level game optimization, testing, and bug fixing process has been revamped with AI doing the heavy lifting.
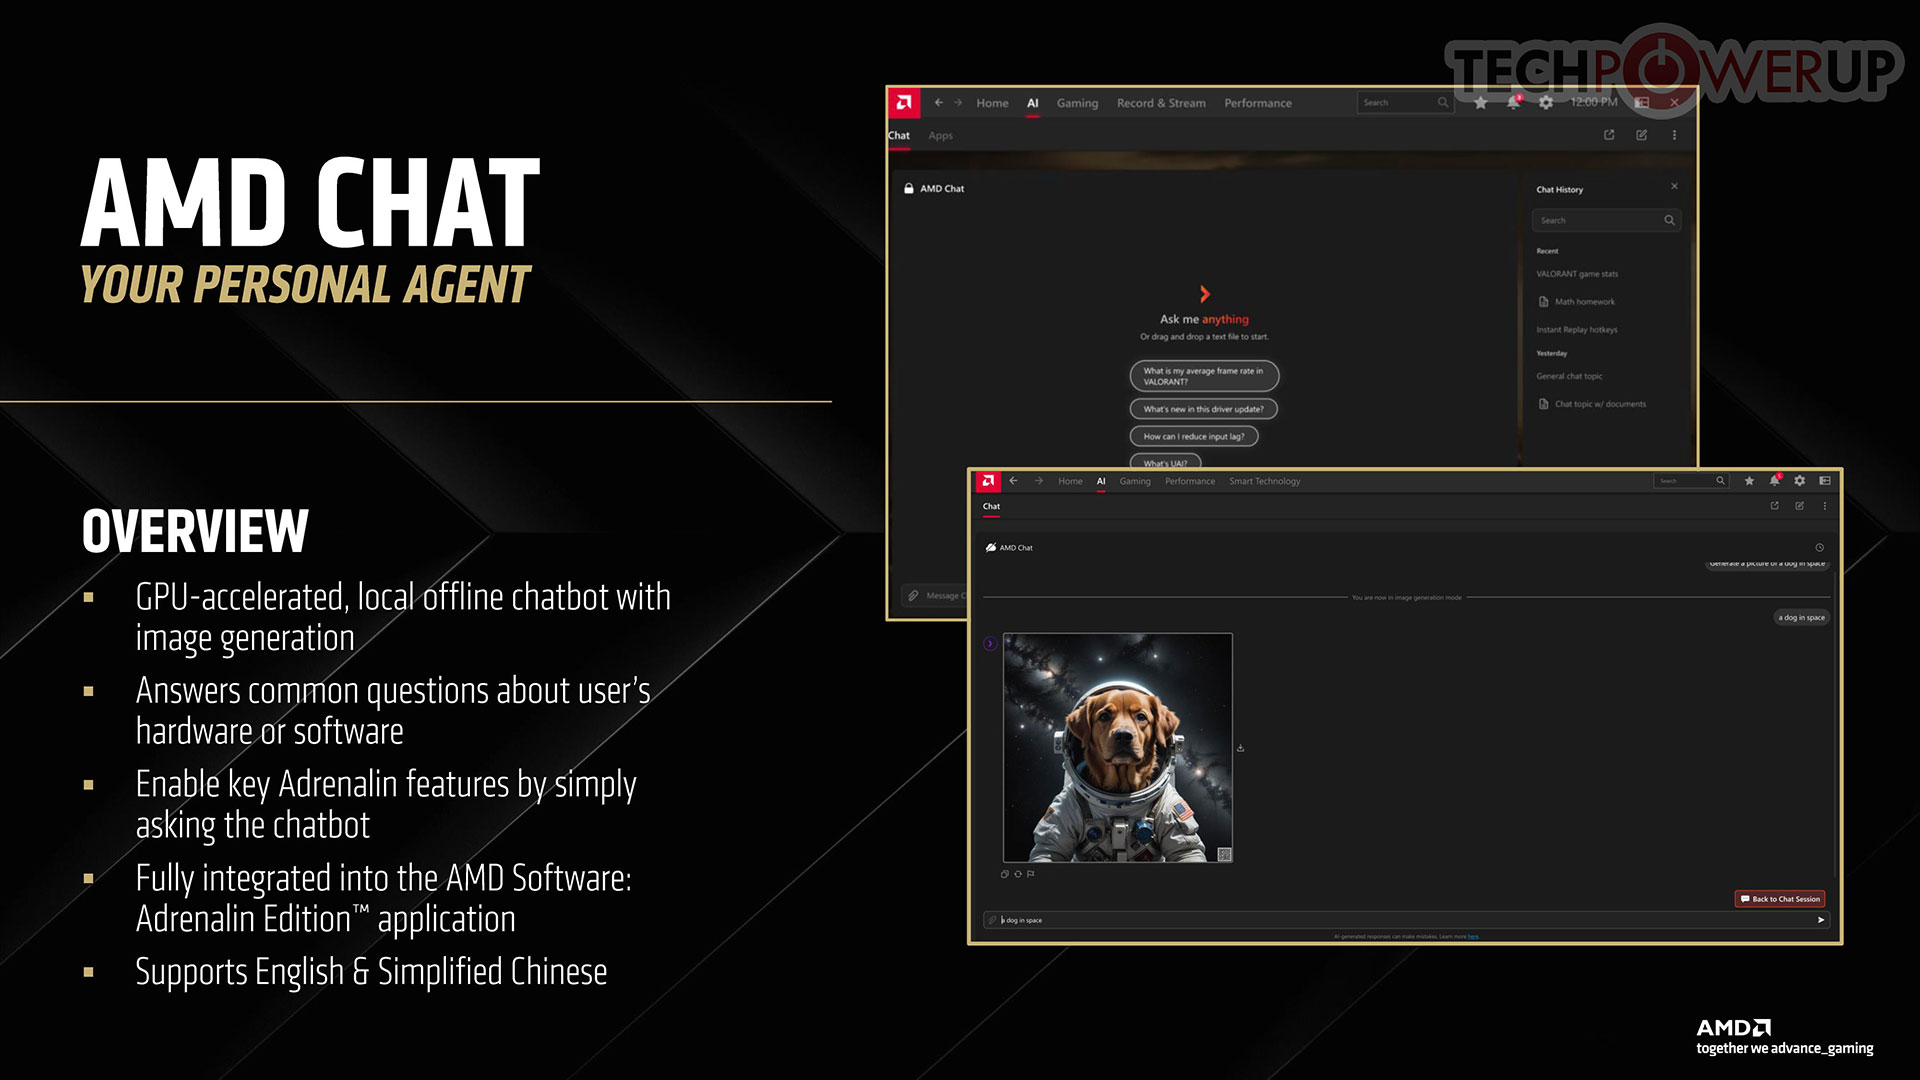
The company also introduced AMD Chat, which is an AI chatbot that runs locally, and is accelerated by the GPU. You can make plain language queries on configuring AMD Software features and settings; and also chat with it on AMD technologies. This is essentially AMD's answer to NVIDIA's ChatRTX, but we don't know if the utility can be trained with custom datasets.
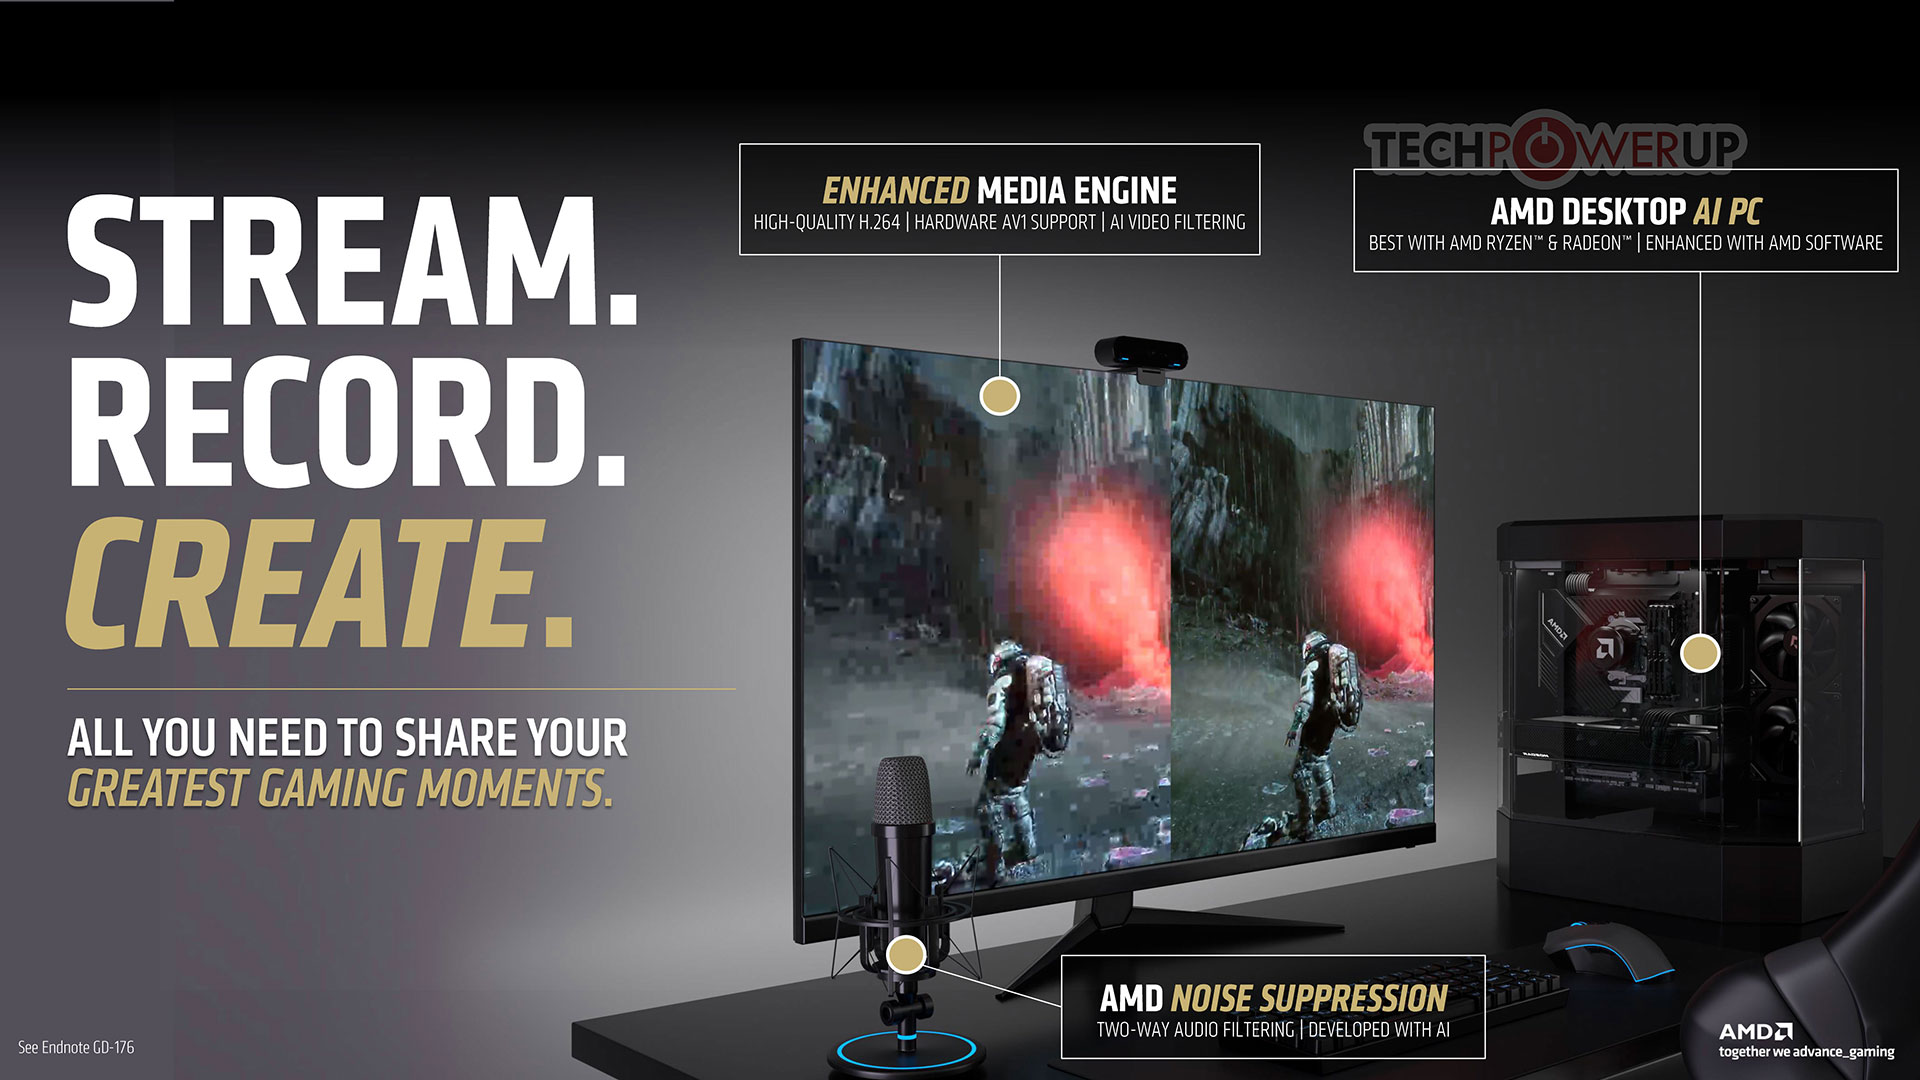

For streamers, AMD Software simplifies connecting their gameplay with their social media and streaming accounts. You can then take advantage of the new dual media engine of RDNA 4 that improves H.264 and HEVC image quality, and use other utilities such as AMD Noise Suppression, which is a 2-way AI-based audio filter.
AMD AI Apps Manager consolidates all your AI applications into a simple launcher-like interface resembling a game launcher.
Packaging


The Card


Visually, the ASUS RTX 9070 XT TUF OC follows the design theme of the company's previous TUF cards, and it also matches the GeForce 50 TUF visuals exactly. On the back you get a high quality metal backplate with a cutout for air to flow through.

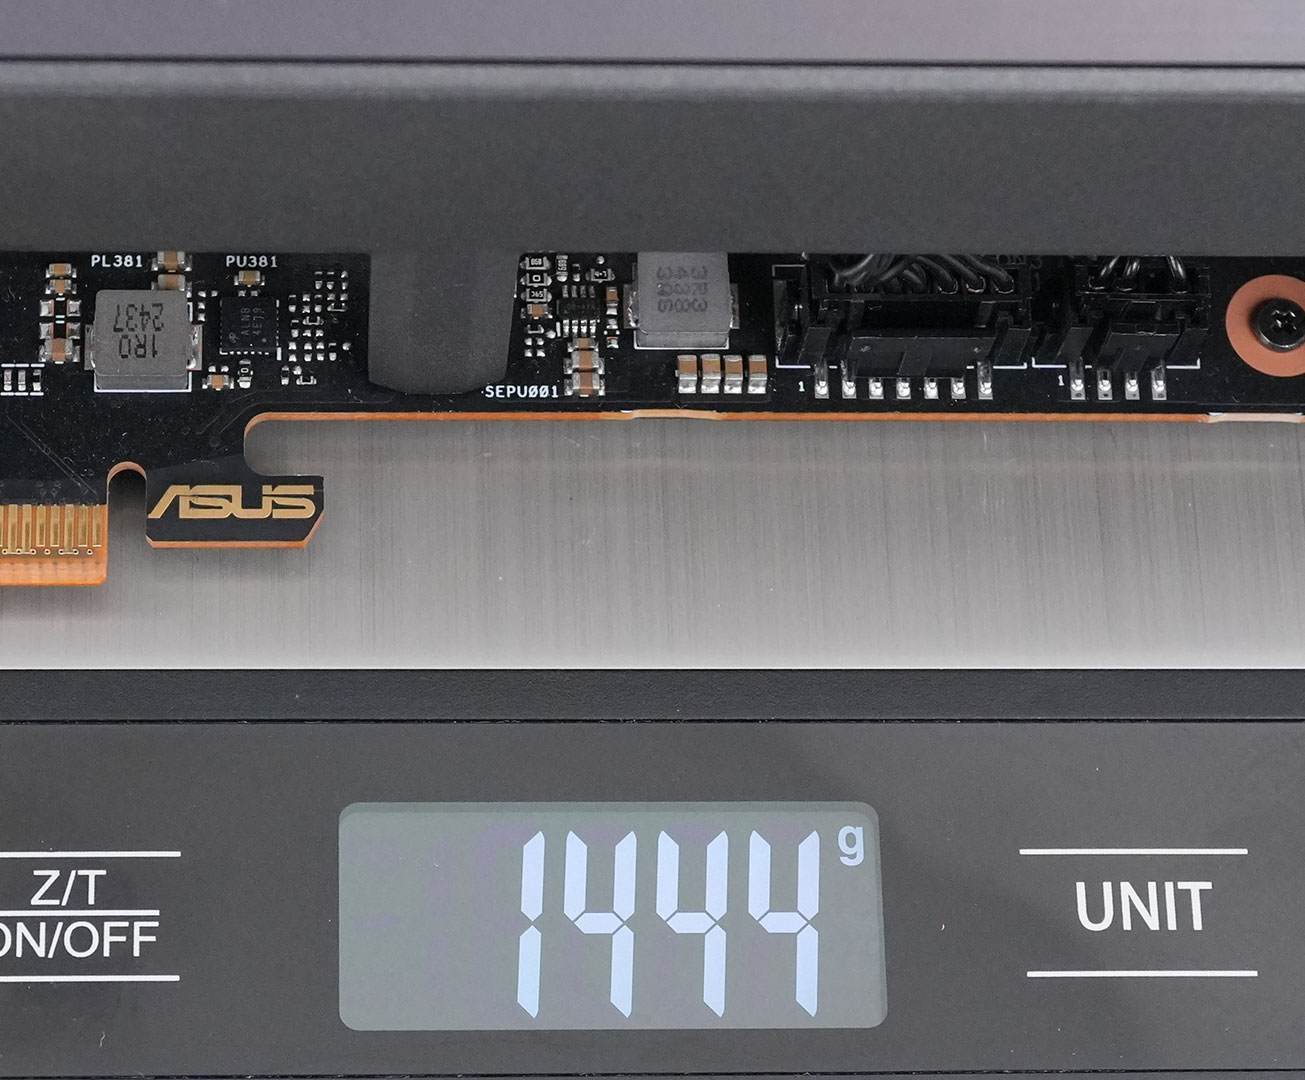
Dimensions of the card are 33.0 x 14.0 cm, and it weighs 1444 g.
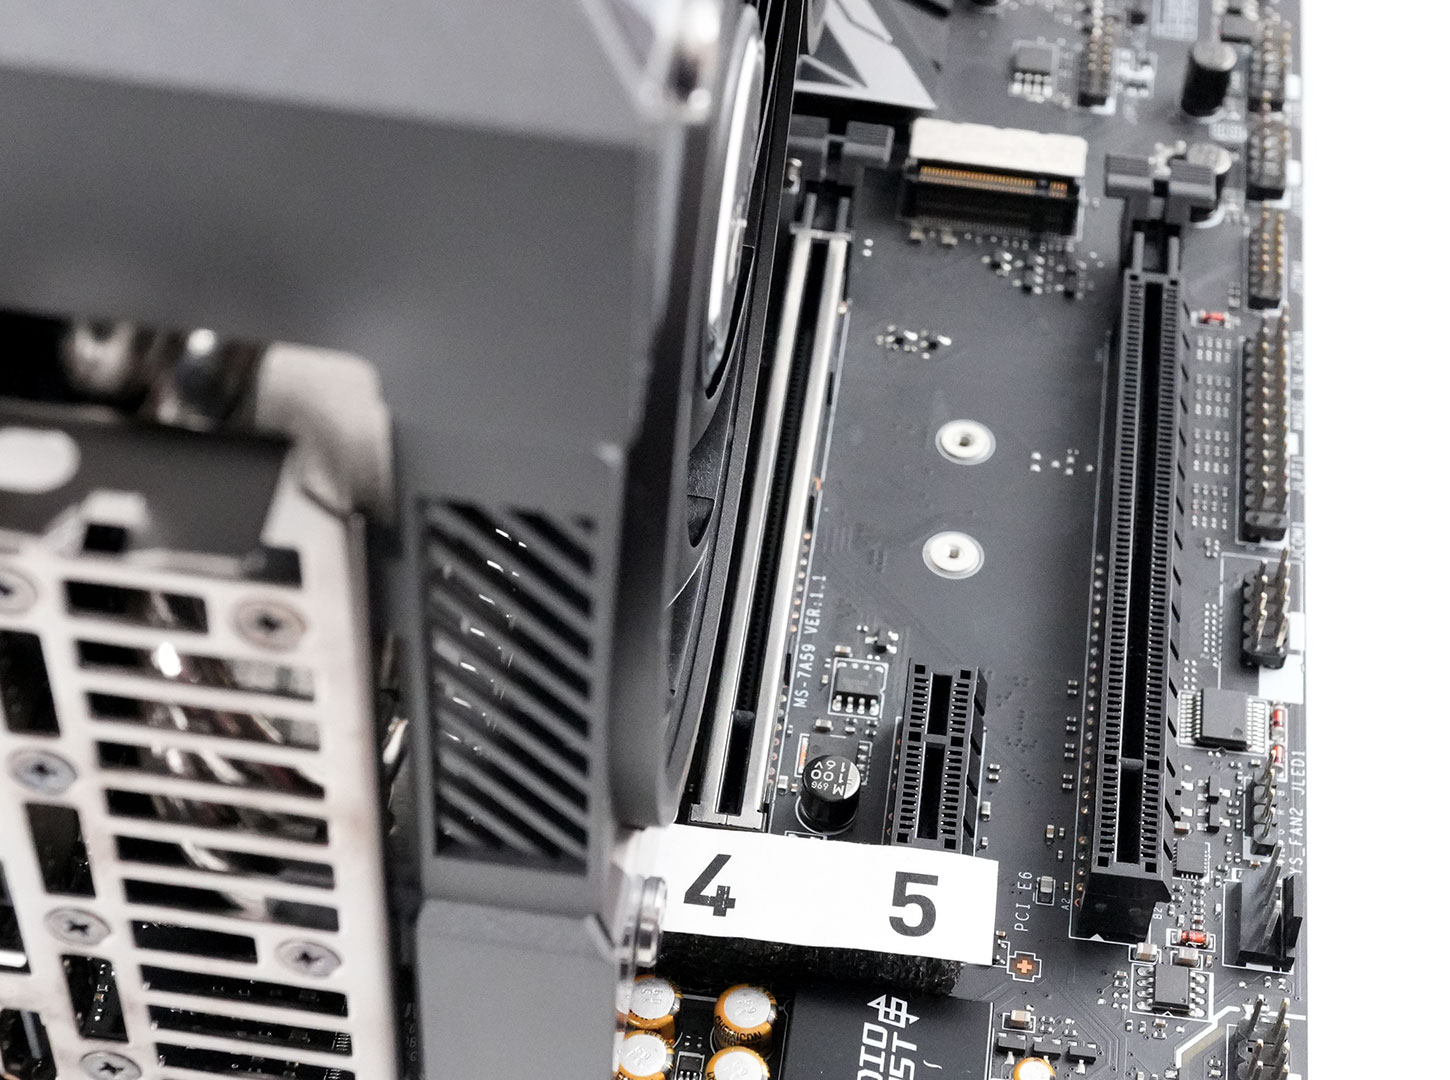
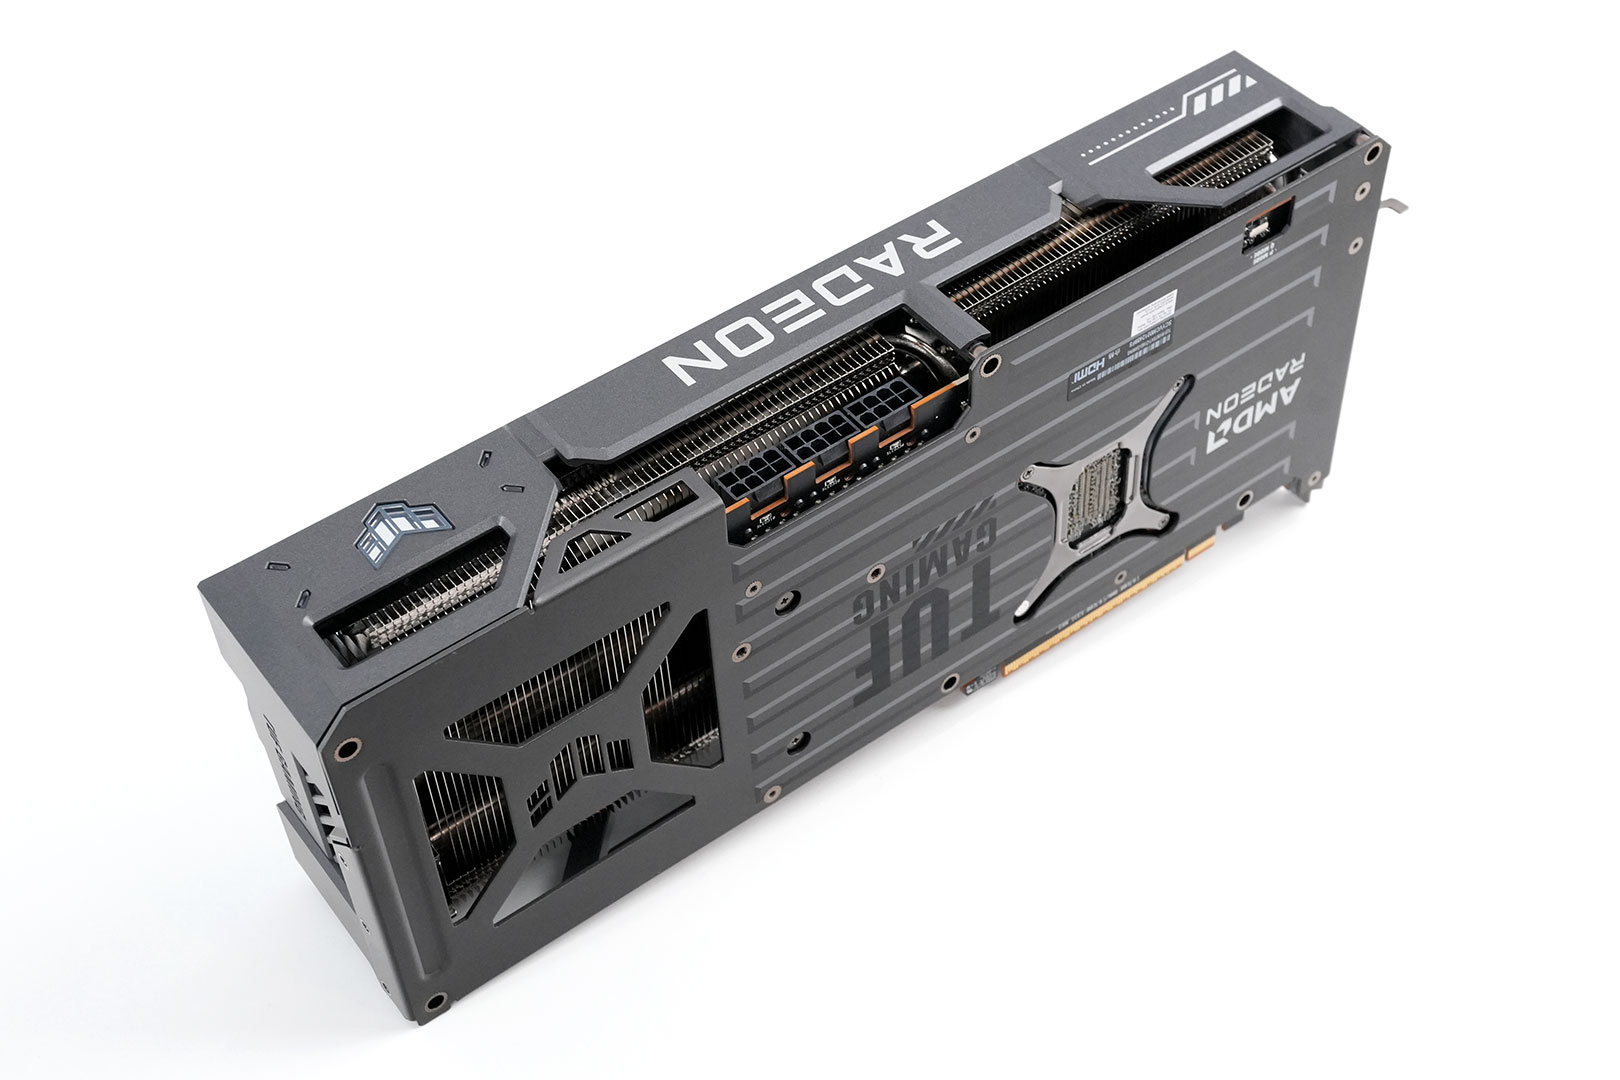
Installation requires three slots in your system. We measured the card's width to be 60 mm.
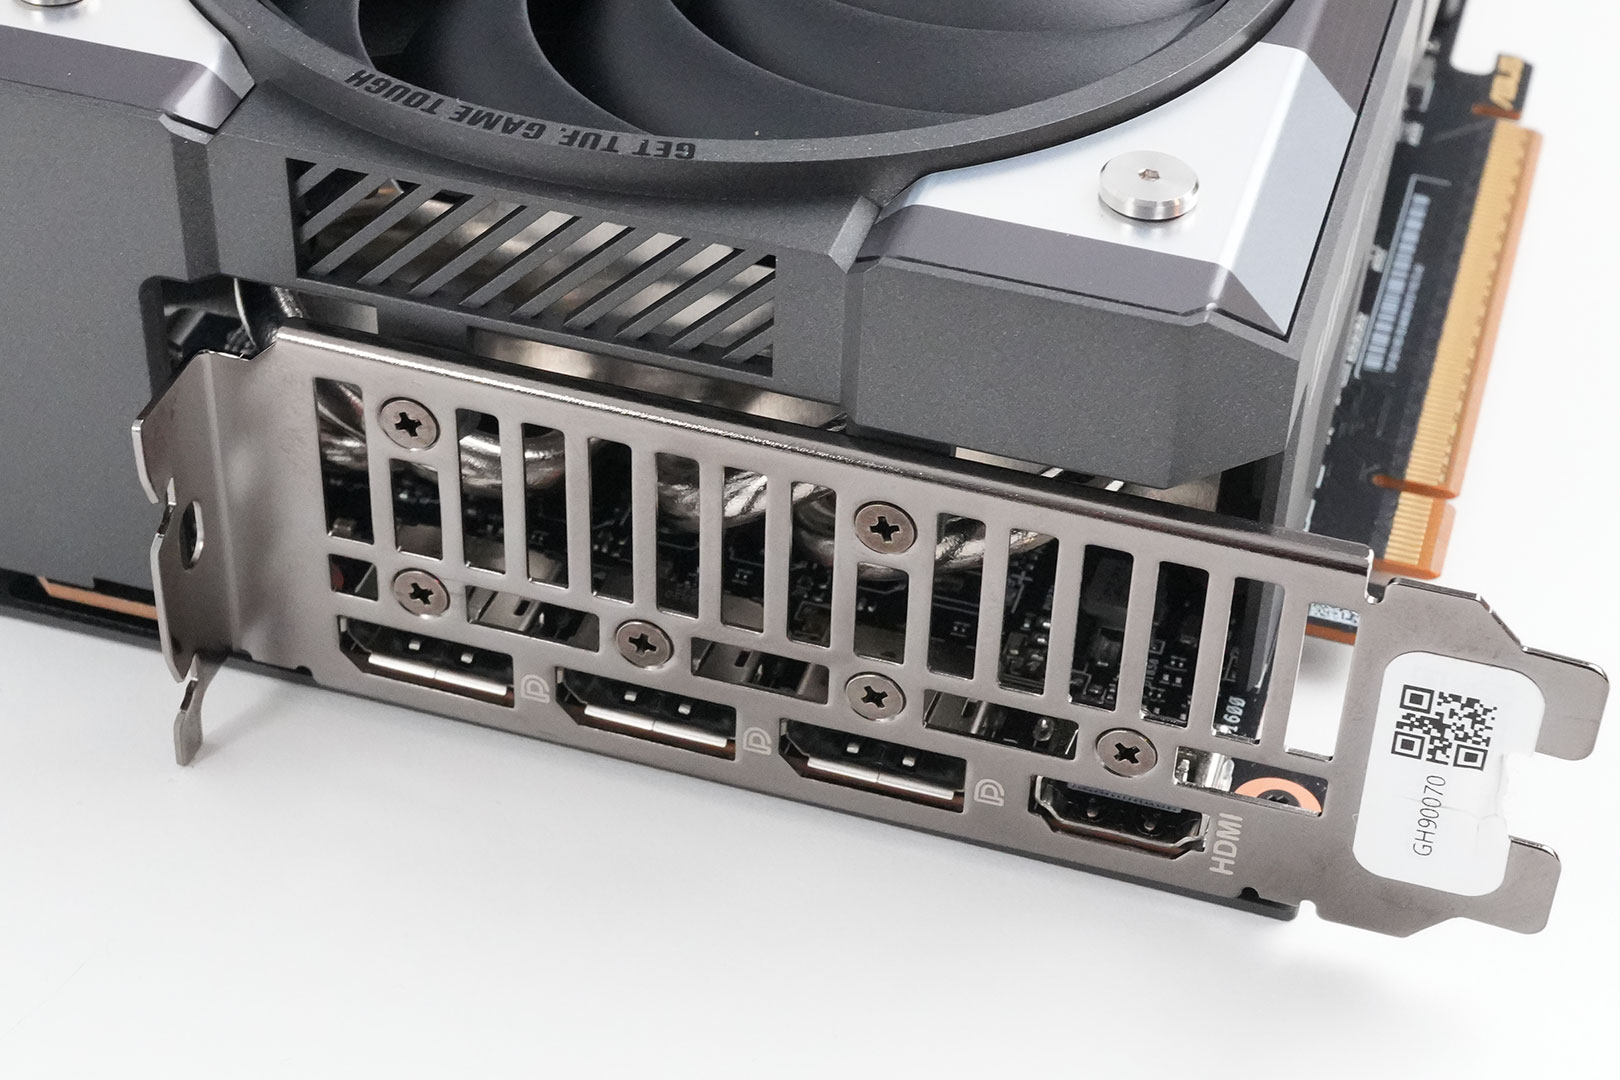
Display connectivity includes three standard DisplayPort 2.1a and a HDMI 2.1b.
With RDNA 4, AMD put effort to improve its standing with game streamers and creative professionals. It's done this by giving Navi 48 a dual VCN solution, so the GPU has two concurrent hardware accelerators for encoding and decoding. Perhaps the biggest change at the silicon level is that AMD improved the encoding quality of its hardware H.264 and HEVC codecs. This was a niche complaint streamers had with AMD GPUs, and would avoid the brand altogether. The company also updated its AV1 hardware acceleration with support for B-frames, which are frames that lack image information, but math data that let the decoder reconstruct image data by comparing with the image data from adjacent I-frames containing it. This technique vastly improves streaming bitrates since half the frames lack image data.
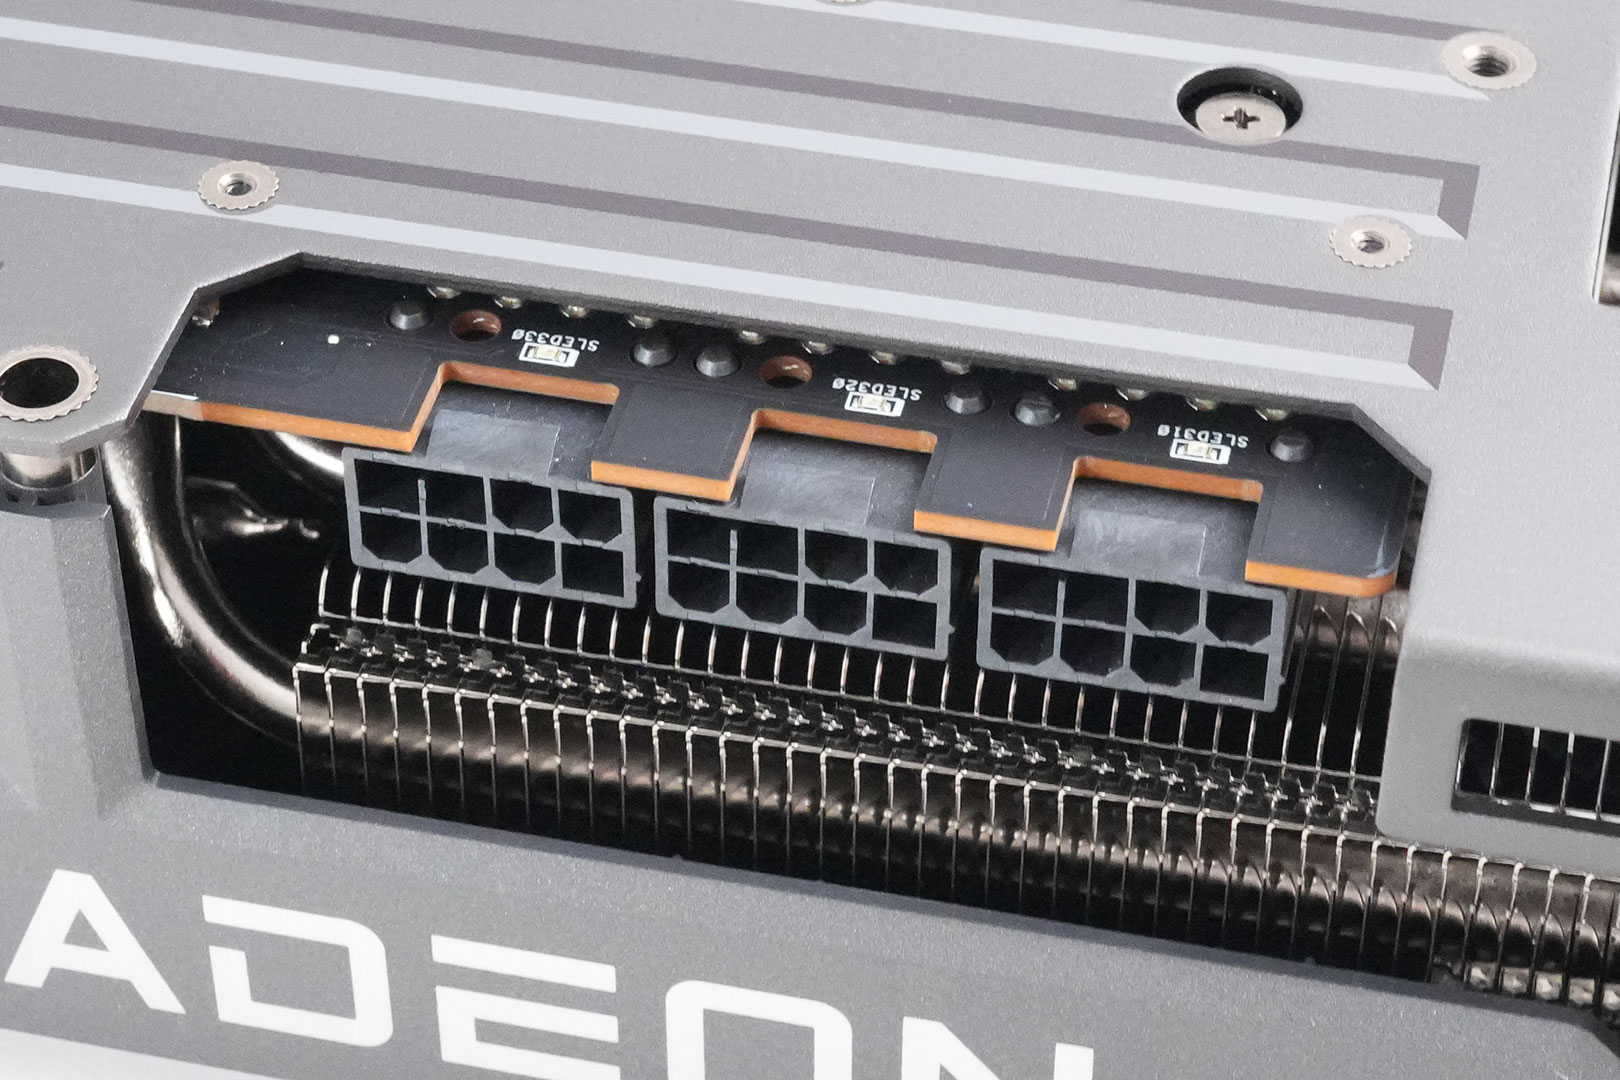
The card uses three 8-pin power connectors, which allow a theoretical total power consumption of 450 W, plus 75 W from the PCIe slot.
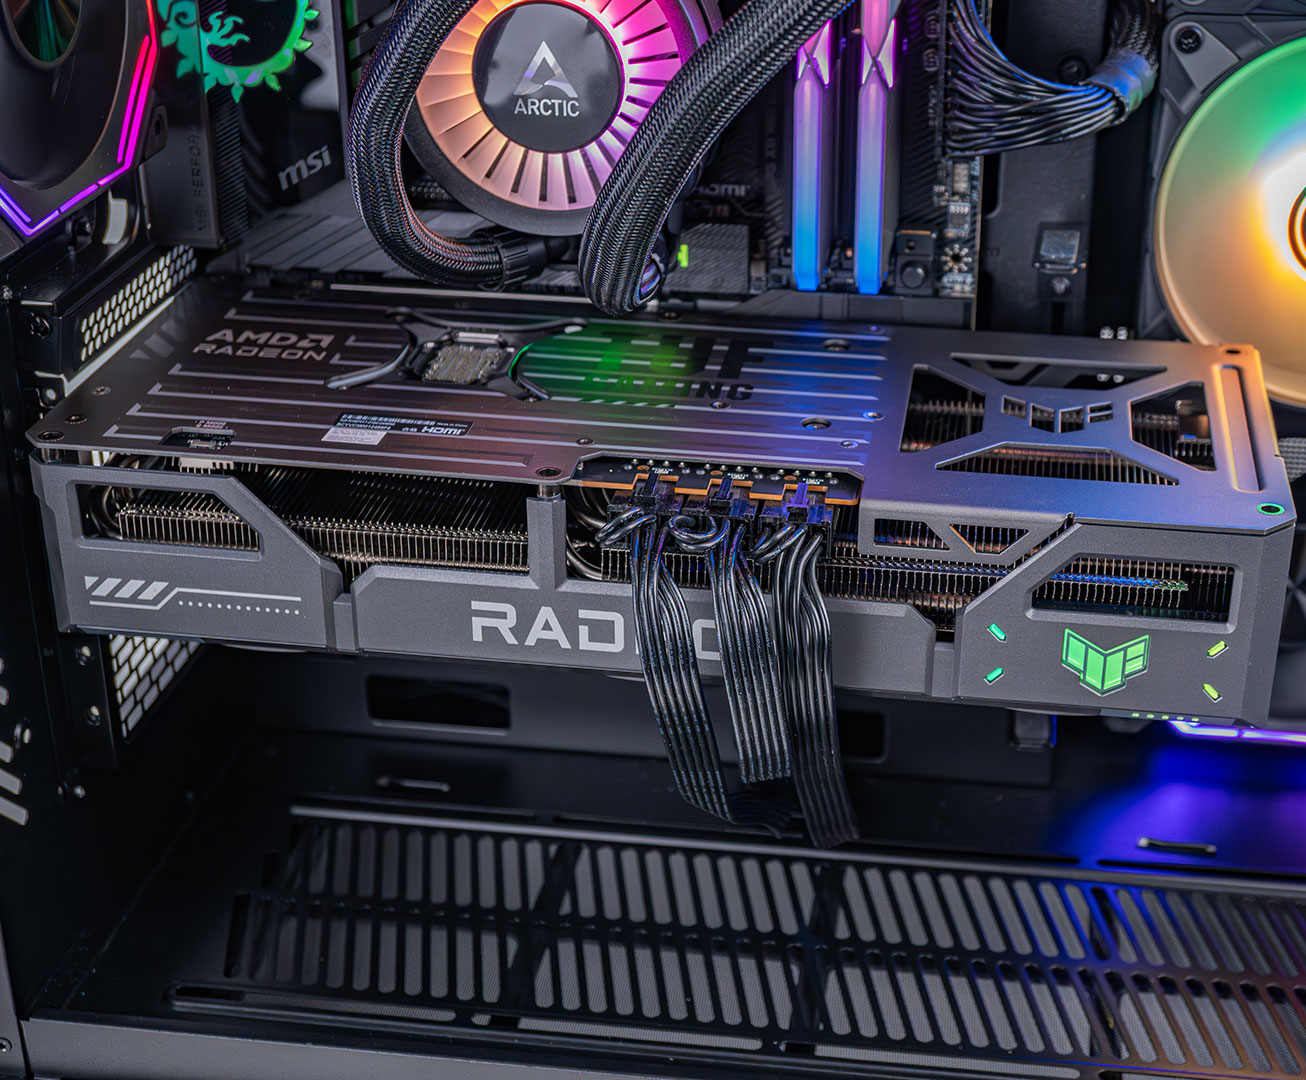
ASUS has installed an RGB lighting zone near the corner of the card.

This BIOS switch lets you toggle between the default performance BIOS and an optional "quiet" BIOS.
Teardown
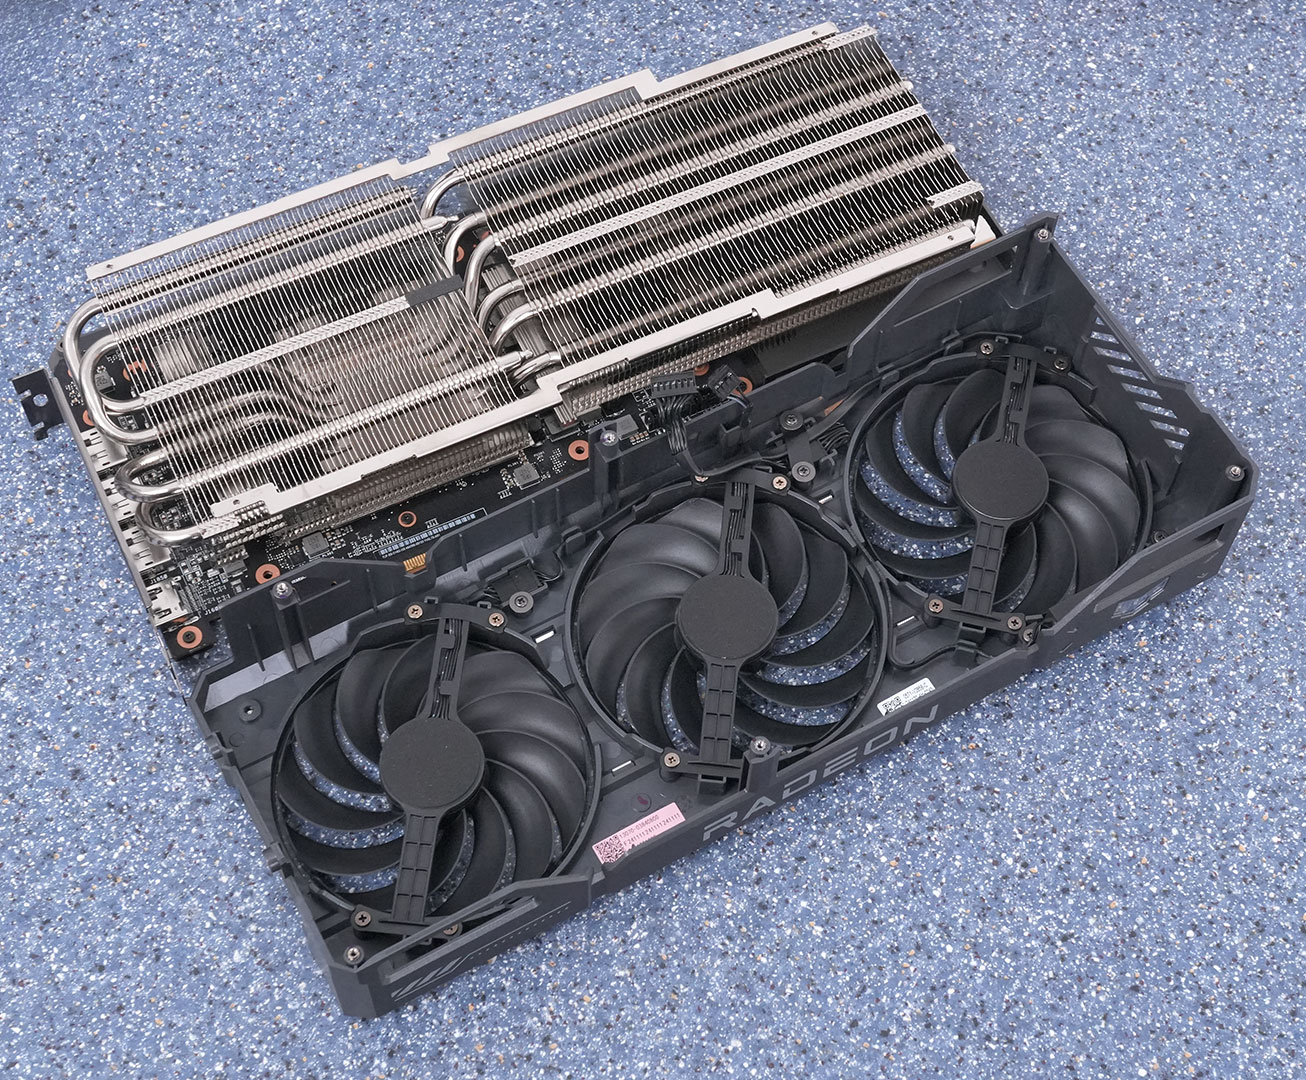
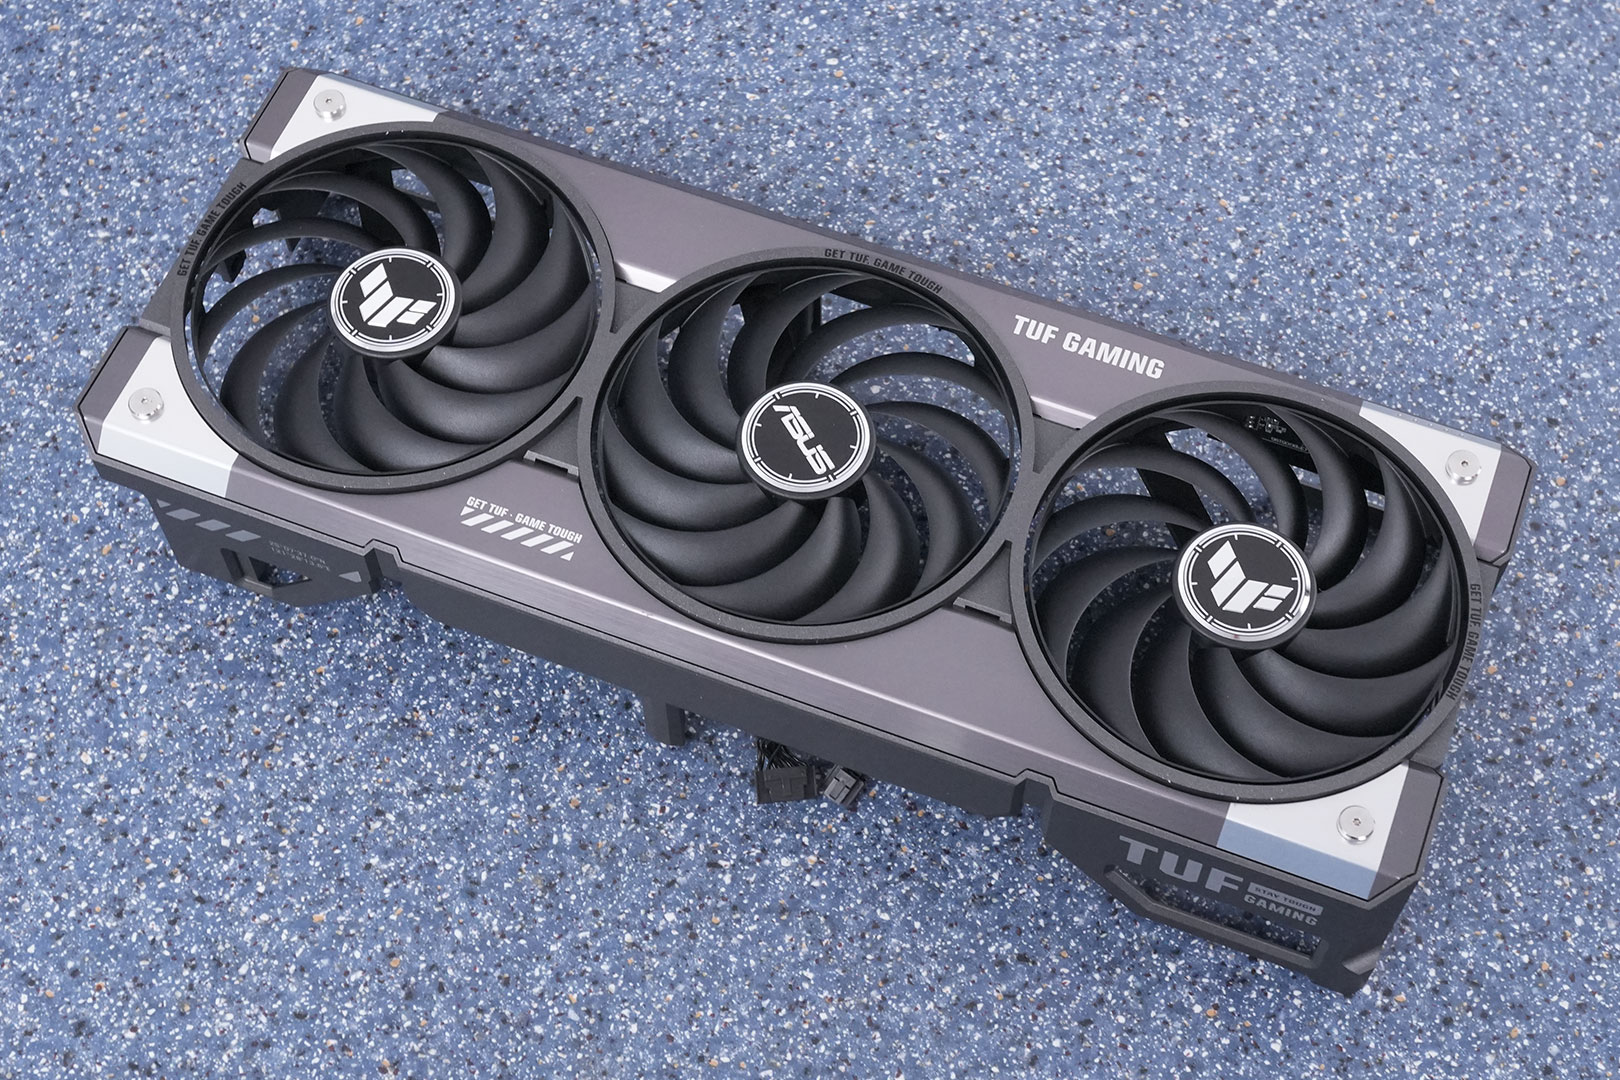
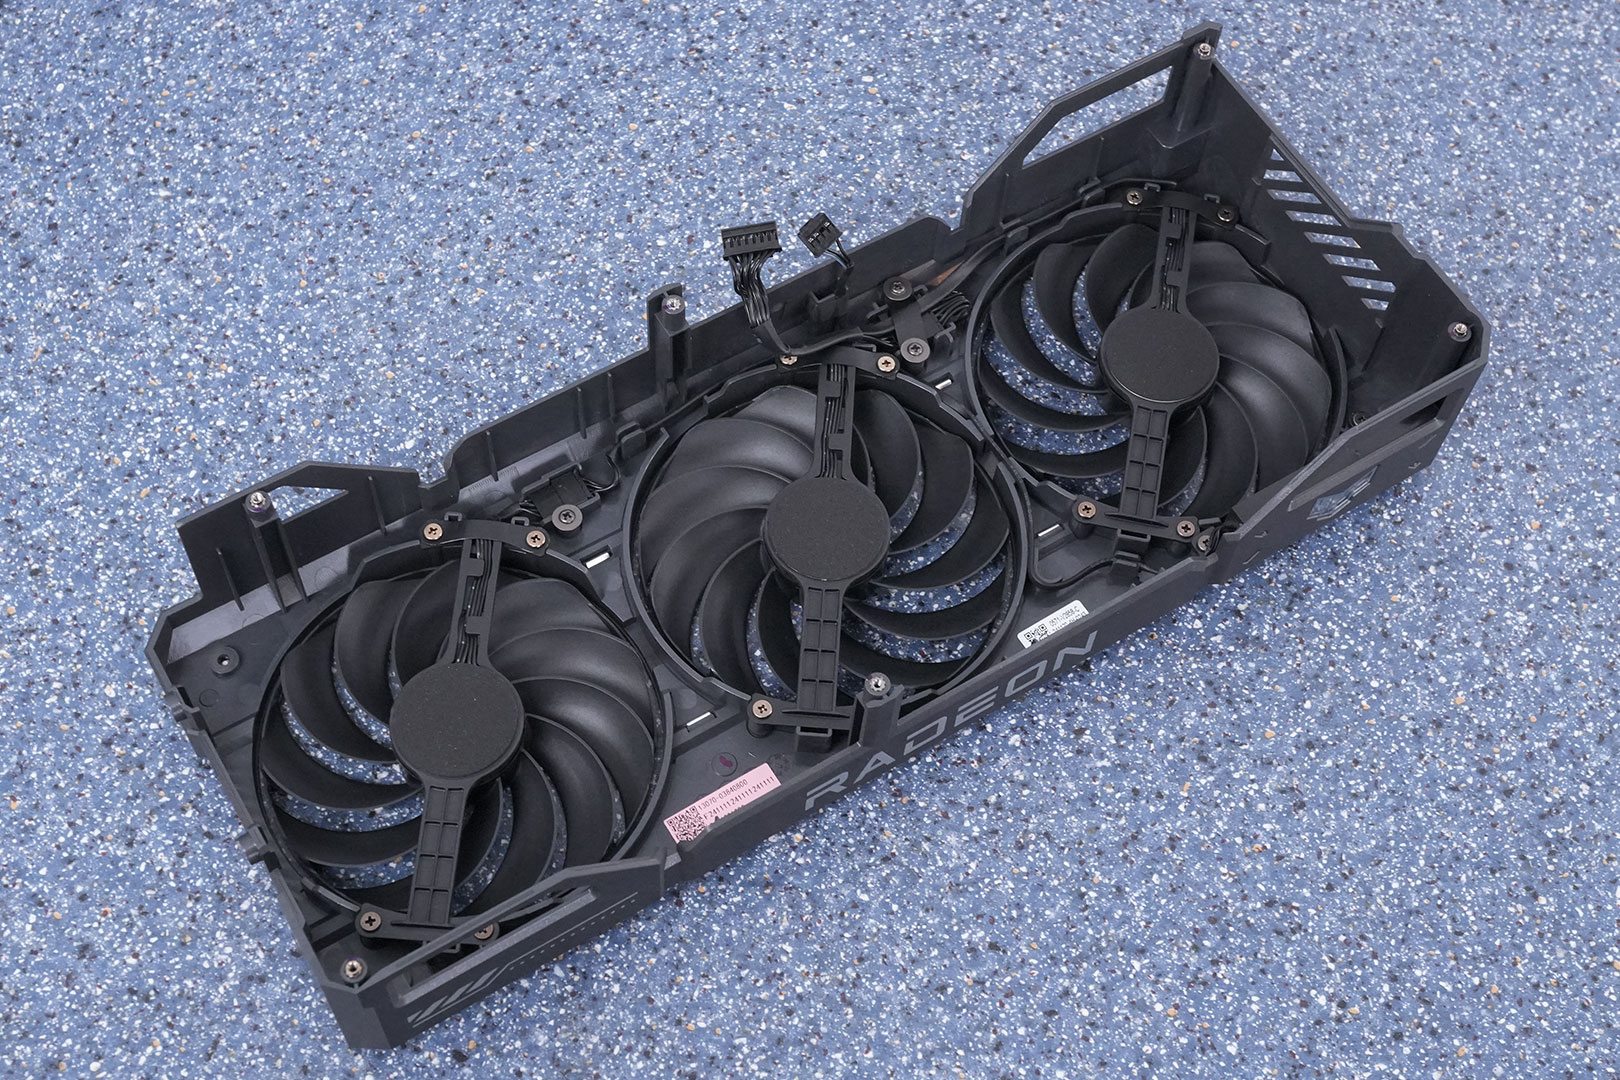
ASUS made the fan assembly removable, so it's easy to replace a fan if one breaks in a few years.
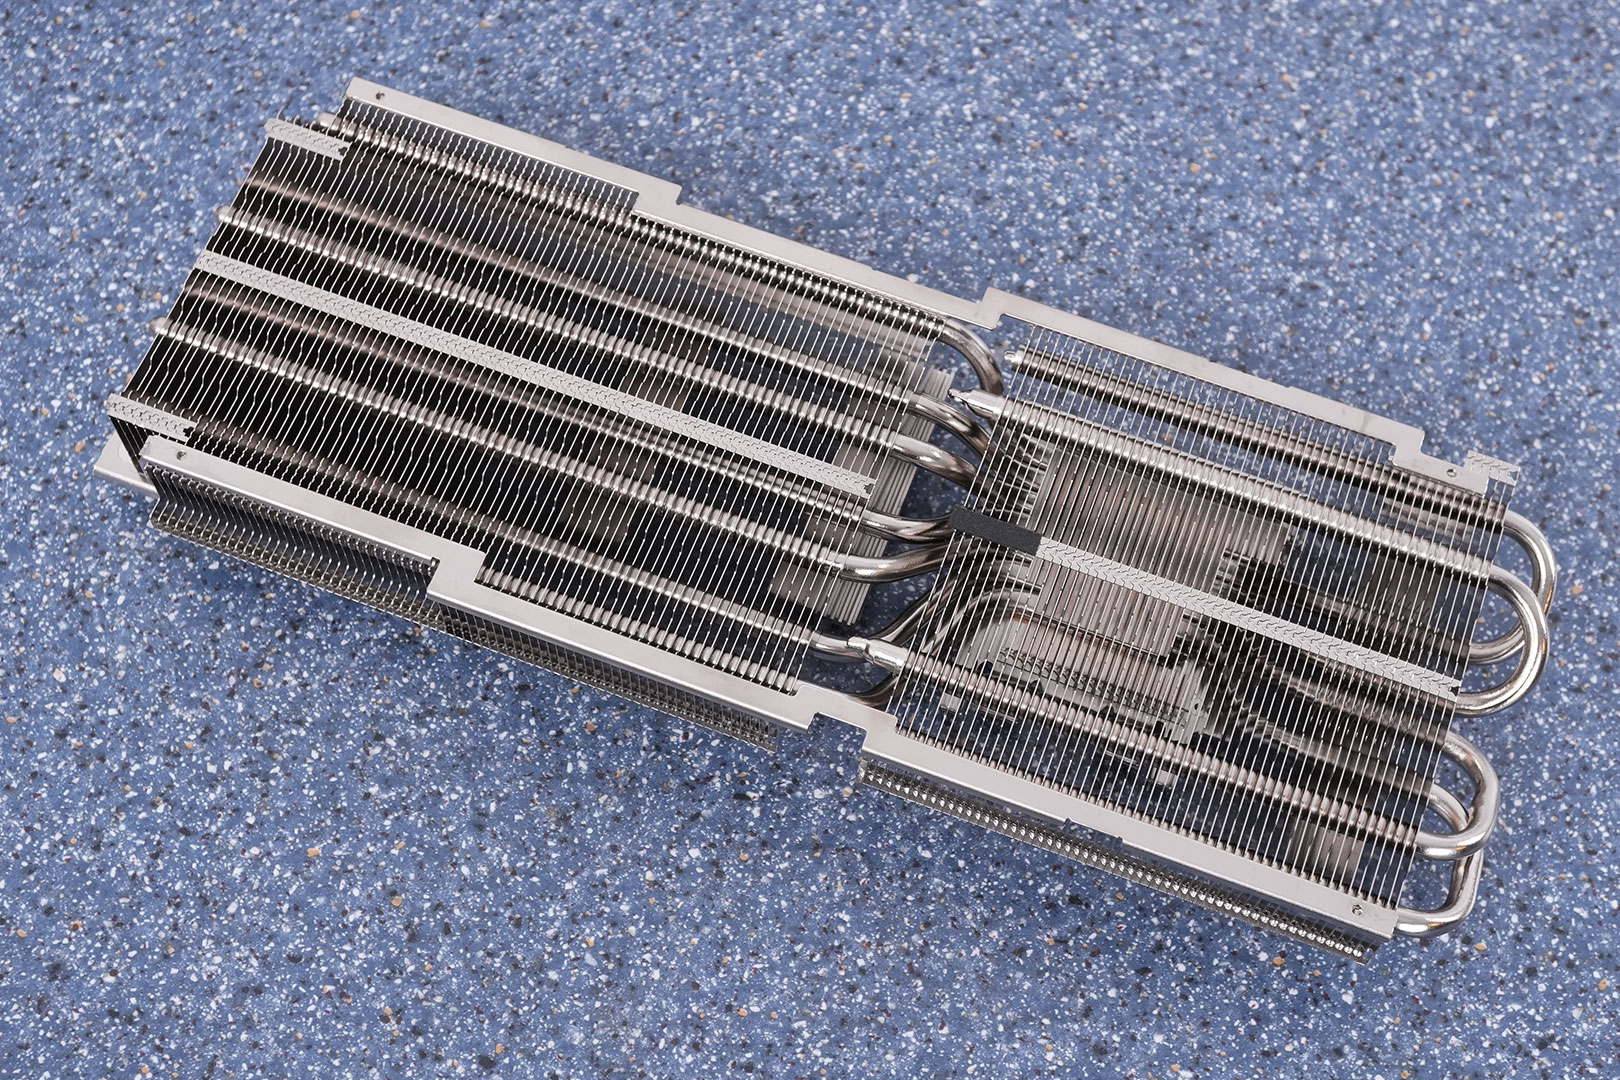
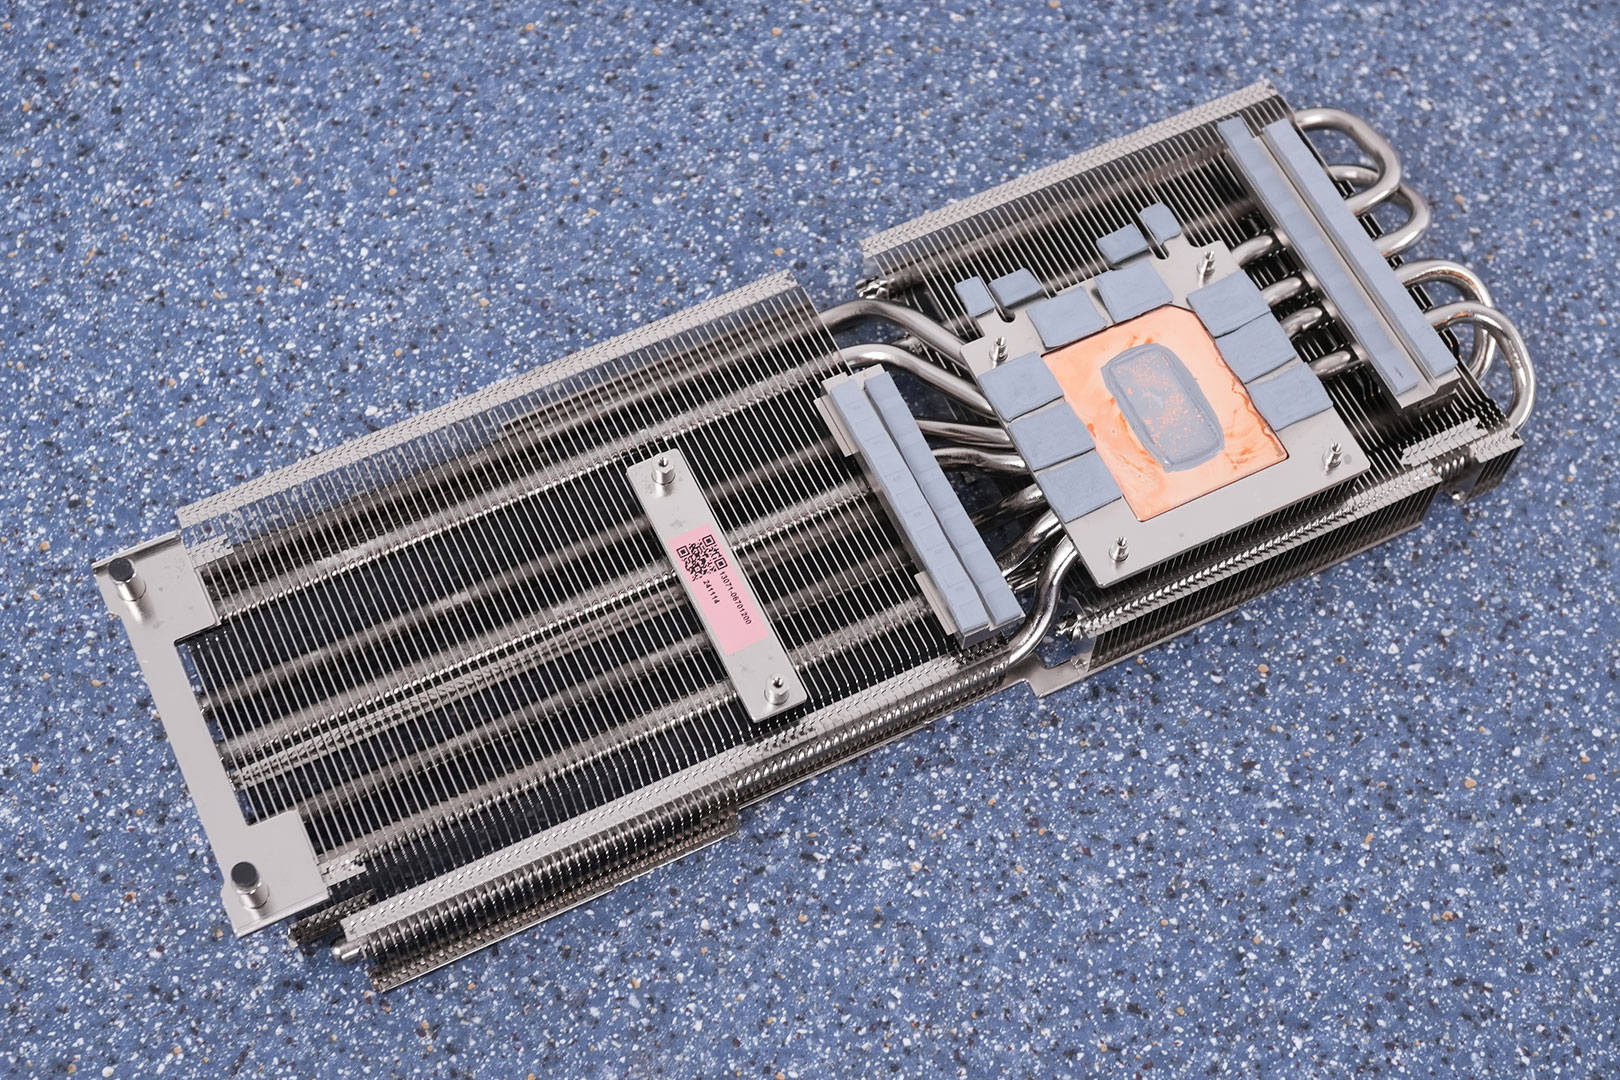

The heatsink uses seven heatpipes and provides cooling not only for the GPU, but also for the memory chips and VRM circuitry.
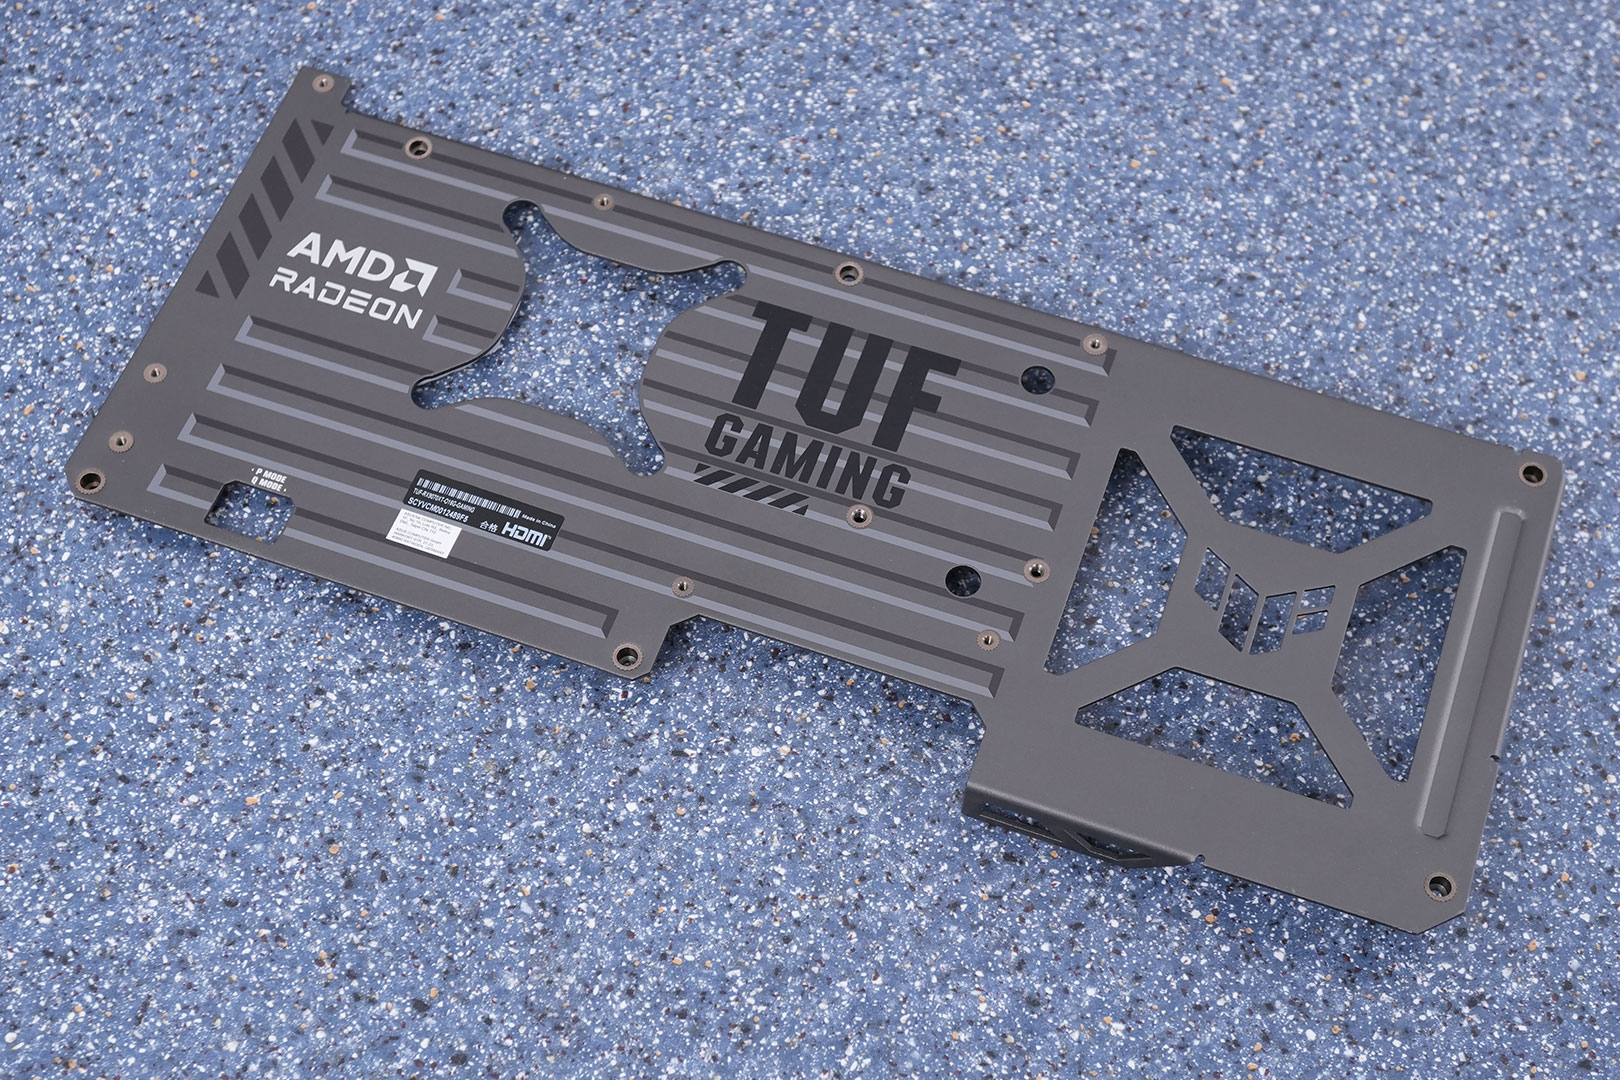
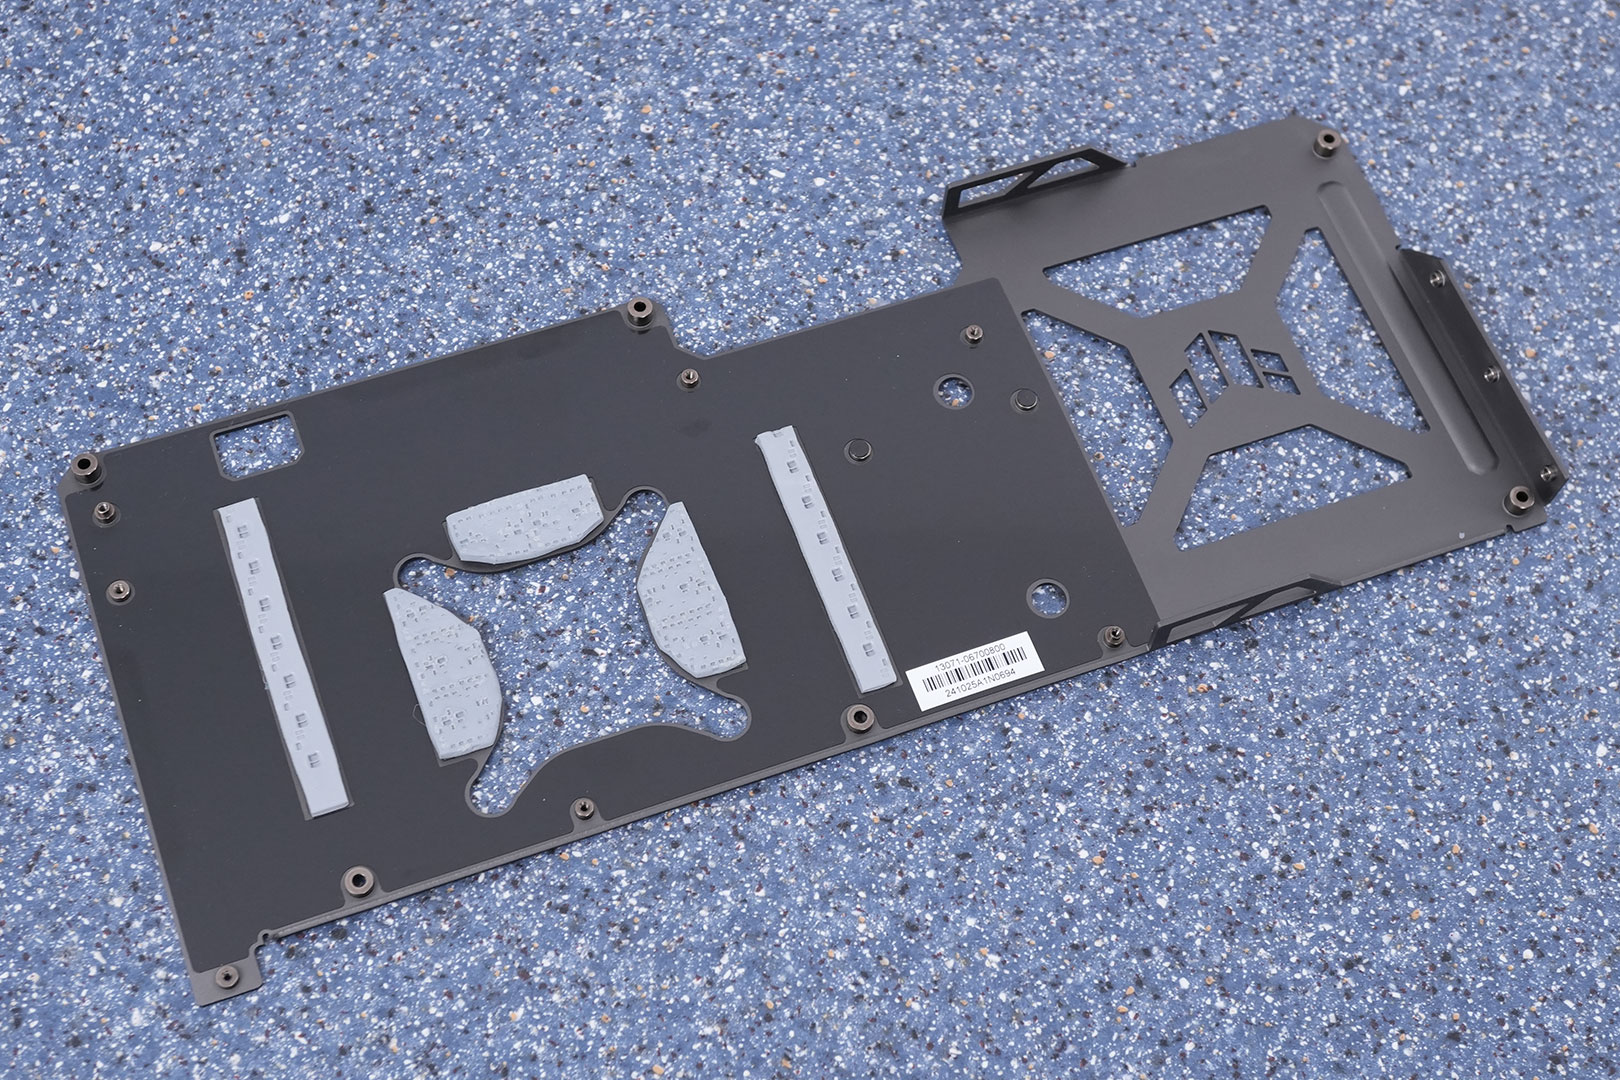
The backplate protects against damage during installation and handling.
High-resolution PCB Pictures
These pictures are for the convenience of volt modders and people who would like to see all the finer details on the PCB. Feel free to link back to us and use these in your articles, videos or forum posts.

High-resolution versions are also available (front, back).
Our Patreon Silver Supporters can read articles in single-page format.
Nov 17th, 2026 21:36 CST
change timezone
Latest GPU Drivers
New Forum Posts
- Without Jensen, PC gaming will be (36)
- Will zen 6 mobos have anything extra vs current ones? (52)
- Hi, just to say thanks and who I am (3)
- 9070 GRE 3.9ghz validation reached. (19)
- [testers wanted] Qsurfer My own QNAP Nas explorer/Search tool (8)
- Lenovo Legion Pro 5 Audio Nightmare: Fan Noise, Harsh Voice & Massive DPC Latency (Help!) (2)
- Help with fixing Overclock (8)
- WarpCoreBench scores! (56)
- Slow SSD read speeds - help! (15)
- Ryzen 7 8700G OC (9)
Popular Reviews
- Acemagic Retro X3 Review
- Upcoming Hardware Launches 2027 (Updated Nov 2026)
- AMD Zen 6 Technical Deep Dive
- ASUS ROG Strix B850-I Gaming Wi-Fi7 W Review
- Corsair HX1000i Shift Crystal Review
- Chieftec Iceberg PRO 360 DARK Review
- AMD Ryzen 7 9800X3D Review - The Best Gaming Processor
- Phantom Blade Zero Performance Benchmark Review - 35 GPUs Tested
- Montech King 95 3D PRO Review
- Biwin Black Opal NV7400 2 TB Review
TPU on YouTube
Controversial News Posts
- NVIDIA Co-Founder and CEO Jensen Huang Officially Resigns (464)
- Open Letter Asking NVIDIA to Reinstate Jensen Huang Passes 115,000 Signatures (184)
- OpenAI CEO Argues Home PCs Waste the World's Limited DRAM Supply (152)
- Report: Jensen Huang Eyes NVIDIA Comeback (137)
- NVIDIA Launches Investigation Into Jensen Huang's Relationship With Suspected Chinese Spy (136)
- Intel "Raptor Lake Next" 16-Core and 20-Core CPUs Surface (130)
- Legendary Game Studio BioWare Shuts Down Following EA Layoffs (104)
- Dell CEO Says the Memory Shortage Will Get Worse in 2027 (95)