News Posts matching #800G

Return to Keyword Browsing

Cisco Unveils Silicon One G300 102.4 Tbps Switching ASIC

Cisco (NASDAQ: CSCO) continues to transform the network into an AI innovation platform, today unveiling the Silicon One G300, a 102.4 Tbps switching silicon designed for massive AI cluster buildouts. The Cisco Silicon One G300 will power new Cisco N9000 and Cisco 8000 systems that push the frontier of AI networking in the data center. The systems feature innovative liquid cooling and support high-density optics to achieve new efficiency benchmarks and ensure customers get the most out of their GPU investments. In addition, the company enhanced Nexus One to make it easier for enterprises to operate their AI networks—on-premises or in the cloud—removing the complexity that can hold organizations back from scaling AI data centers.

"We are spearheading performance, manageability, and security in AI networking by innovating across the full stack - from silicon to systems and software," said Jeetu Patel, President and Chief Product Officer, Cisco. "We're building the foundation for the future of infrastructure, supporting every type of customer—from hyperscalers to enterprises—as they shift to AI-powered workloads."

Tenstorrent Cuts 20 Cores From Already-Shipping "Blackhole" P150 Cards

Tenstorrent, a startup focused on designing high-performance AI accelerators and led by the renowned computer architect Jim Keller as CEO, has announced significant hardware updates to its existing Blackhole P150 accelerators, which include the P150a and P150b models. In the latest documentation change, the company notes that its Blackhole P150 accelerators will now work with about 14.3% fewer cores than originally advertised. In the official documents, the P150 accelerators are now shipping with 120 working "Tensix" cores instead of the previously advertised 140 cores. The reason for this change is unknown, as the company provided a vague explanation: "To present a unified interface to metal and other system software, firmware v19.5.0 and later will change the core count on all existing cards to 120. Typical workloads show a non-material (~1-2%) performance difference."

The Blackhole P150 accelerators featured 140 "Tensix" cores and 32 GB of GDDR6 memory, operating at up to 300 W in an actively cooled form factor designed for desktop workstations, and the P150a model includes four passive QSFP-DD 800G ports. However, as the number of cores is reduced by approximately 14%, TeraFLOPS take a nosedive as well. In the older documents for the 140-core SKUs, the BLOCKFP8 8-bit floating point performance was listed at 774 TeraFLOPS, while the new 120-core version reduces that number to 664 TeraFLOPS at the same precision level. Why this sudden change is happening is still a mystery. However, the HPC community with a lot of knowledge in the industry suggests a few reasons.

NVIDIA Moves to In-House Server Production, Leaving OEMs with a Secondary Role

NVIDIA plans to reshape the industry's approach to building high-performance AI servers with its "Vera Rubin" product stack, which will enter volume production as the VR200 line in late 2026. Rather than supplying CPUs and GPUs to OEMs, NVIDIA plans to ship fully finished L10 compute trays that come pre-populated with "Vera" CPUs, "Rubin" accelerators, memory, 800G NICs, 110kW power delivery, and liquid-cooling infrastructure, all of which are validated before they leave the factory. This, however, will leave many system vendors and OEMs shifting away from designing core server electronics and toward tasks such as rack-level assembly, power configuration, installation of rack cooling sidecars, and final certification.

Rubin silicon is rumored to have a TDP of up to 2.3 kW for highest-end models, leading to rack-level power consumption exceeding 250 kW and making custom cooling designs economically unviable. NVIDIA's strategy reportedly involves standardizing cooling and power across two performance tiers while increasing network I/O density. These choices decrease the feasibility and cost-effectiveness of third-party replication. By centralizing production with select partners, development cycles can be shortened and manufacturing yields improved. However, this approach also limits the options OEMs and hyperscalers have traditionally used to differentiate their hardware.

Broadcom Intros Thor Ultra Industry's First 800G AI Ethernet NIC

Broadcom Inc. (NASDAQ:AVGO), a global leader in semiconductor and infrastructure software solutions, today announced Thor Ultra, the industry's first 800G AI Ethernet Network Interface Card (NIC), capable of interconnecting hundreds of thousands of XPUs to drive trillion-parameter AI workloads. By adopting the open Ultra Ethernet Consortium (UEC) specification, Thor Ultra gives customers the ability to scale AI workloads with unparalleled performance, and efficiency in an open ecosystem.

"Thor Ultra delivers on the vision of Ultra Ethernet Consortium for modernizing RDMA for large AI clusters," said Ram Velaga, senior vice president and general manager of the Core Switching Group at Broadcom. "Designed from the ground up, Thor Ultra is the industry's first 800G Ethernet NIC and is fully feature compliant with UEC specification. We are grateful to our customers for their partnership and to our exceptional engineering team for the product innovation."

AMD Instinct MI500 UAL256 Mega Pod to Scale up to 256 GPUs, 64 "Verano" CPUs

While AMD hasn't launched its upcoming Instinct MI400 series of accelerators yet, the company has started preparing its supply chain for what comes after. Thanks to SemiAnalysis, we have a clearer picture of what AMD's Instinct MI500 UAL256 rack will look like. At the base of each compute node, there will be a single "Verano" CPU paired with four Instinct MI500 accelerators. With up to 64 nodes, split across two 32-node racks, AMD plans to enable 256 logical GPUs and 64 CPUs per mega pod, working in tandem for advanced AI and HPC workloads. Instinct MI500s UAL256 will be AMD's second-generation rack-scale system, following the upcoming Instinct MI450X IF128 aka "Helios", scheduled for the second half of 2026. The Instinct MI500 UAL256 scale-up mega pod is scheduled to arrive in 2027, just in time for Verano and Instinct MI500 accelerator.

The Instinct MI500 UAL256 scale-up mega pod splits the compute into two 32-rack cabinets, with a single central rack connecting them and hosting 18 switching trays for networking. Each of these networking trays contains four 102.4T "Vulcano" switch ASICs, designed for 800G external throughput, and manufactured on TSMC's 3 nm node. For the central processor, AMD showed few details at its Advancing AI event, which claimed that Verano introduces the "Zen 7" microarchitecture for even higher IPC and support for even newer instruction sets. For now, it's not clear if AMD will increase CPU core counts beyond the up to 256 cores per package of "Venice." Still, we're hearing that Verano will retain the Socket SP7 infrastructure, which means it will likely retain the memory and PCIe interfaces introduced in 2026, such as PCIe Gen 6, UALink, and Ultra Ethernet.

xMEMS Extends µCooling Fan-on-a-Chip Technology to AI Data Centers

xMEMS Labs, Inc., the pioneer of monolithic MEMS-based solutions, today announced the expansion of its revolutionary µCooling fan-on-a-chip platform into AI data centers, bringing the industry's first in-module active thermal management solution to high-performance optical transceivers.

Originally developed for compact mobile devices, xMEMS µCooling now provides targeted, hyper-localized active cooling for dense, thermally-challenged environments inside 400G, 800G, and 1.6T optical transceivers—a critical yet underserved category in next-gen AI infrastructure.

PCI-SIG Ratifies PCI Express 7.0 Specification to Reach 128 GT/s

The AI data center buildout requires massive bandwidth from accelerator to accelerator and from accelerator to CPU. At the core of that bandwidth bridge is PCIe technology, which constantly needs to evolve to satisfy massive bandwidth requirements. Today, PCI-SIG, the working group behind the PCI and PCIe connector, is releasing details about the almost ready 0.9 version of the PCIe 7.0 connector and its final specifications. The latest PCIe 7.0 will bring 128 GT/s speeds, with a bi-directional bandwidth of 512 GB/s in the x16 lane configuration. Targeting applications like 800G Ethernet, AI/ML, cloud, quantum computing, hyperscalers, military/aerospace, and cloud providers all need massive bandwidth for their respective applications and use cases to work flawlessly.

Interestingly, as PCIe doubles bandwidth over the traditional three-year cadence, high bandwidth for things like storage is becoming available on fewer and fewer lanes. For example, PCIe 3.0 with x16 lanes delivers 32 GB/s of bi-directional bandwidth. And now, PCIe 7.0 delivers that same bandwidth on only a single x1 lane. Some other goals of the new PCIe 7.0 include significant improvements in channel parameters and signal integrity while enhancing power efficiency and maintaining the protocol's low-latency characteristics. All while ensuring complete backward compatibility with previous generations of the standard. Notably, the PCIe 7.0 standard uses PAM4 signaling, which was first presented for PCIe 6.0. Here is a nice PAM4 signaling primer if you want to learn more about PAM4 signaling. Below are the specifications of PCIe generations and their respective characteristics. We expect to see final version v1.0 by end of the year, and some PCIe 7.0 accelerators next year.
PCIe 7.0 PCIe 7.0 PCIe 7.0

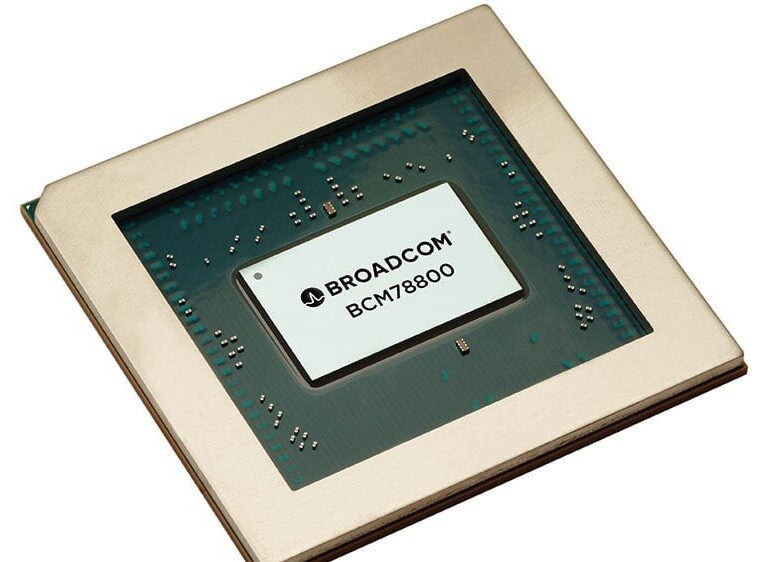
Ethernet Switch Chips are Now Infected with AI: Broadcom Announces Trident 5-X12

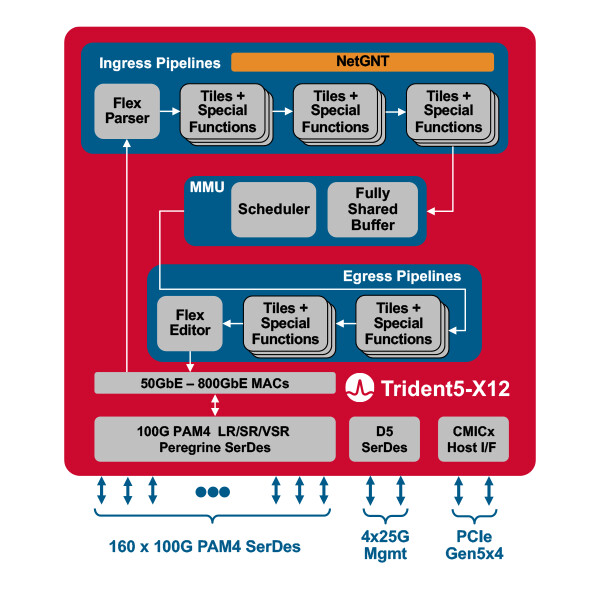
Artificial intelligence has been a hot topic this year, and everything is now an AI processor, from CPUs to GPUs, NPUs, and many others. However, it was only a matter of time before we saw an integration of AI processing elements into the networking chips. Today, Broadcom announced its new Ethernet switching silicon called Trident 5-X12. The Trident 5-X12 delivers 16 Tb/s of bandwidth, double that of the previous Trident generation while adding support for fast 800G ports for connection to Tomahawk 5 spine switch chips. The 5-X12 is software-upgradable and optimized for dense 1RU top-of-rack designs, enabling configurations with up to 48x200G downstream server ports and 8x800G upstream fabric ports. The 800G support is added using 100G-PAM4 SerDes, which enables up to 4 m DAC and linear optics.

However, this is not only a switch chip on its own. Broadcom has added AI processing elements in an inference engine called NetGNT (Networking General-purpose Neural-network Traffic-analyzer). It can detect common traffic patterns and optimize data movement across the chip. Specifically, the company has listed an example of the system doing AI/ML workloads. In that case, NetGNT performs intelligent traffic analysis to avoid network congestion in these workloads. For example, it can detect the so-called "incast" patterns in real-time, where many flows converge simultaneously on the same port. By recognizing the start of incast early, NetGNT can invoke hardware-based congestion control techniques to prevent performance degradation without added latency.
Return to Keyword Browsing
Nov 20th, 2026 02:07 PST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts