News Posts matching #HBM

Return to Keyword Browsing

Huawei Prepares 160,000 Ascend 950DT Accelerators for DeepSeek Data Center

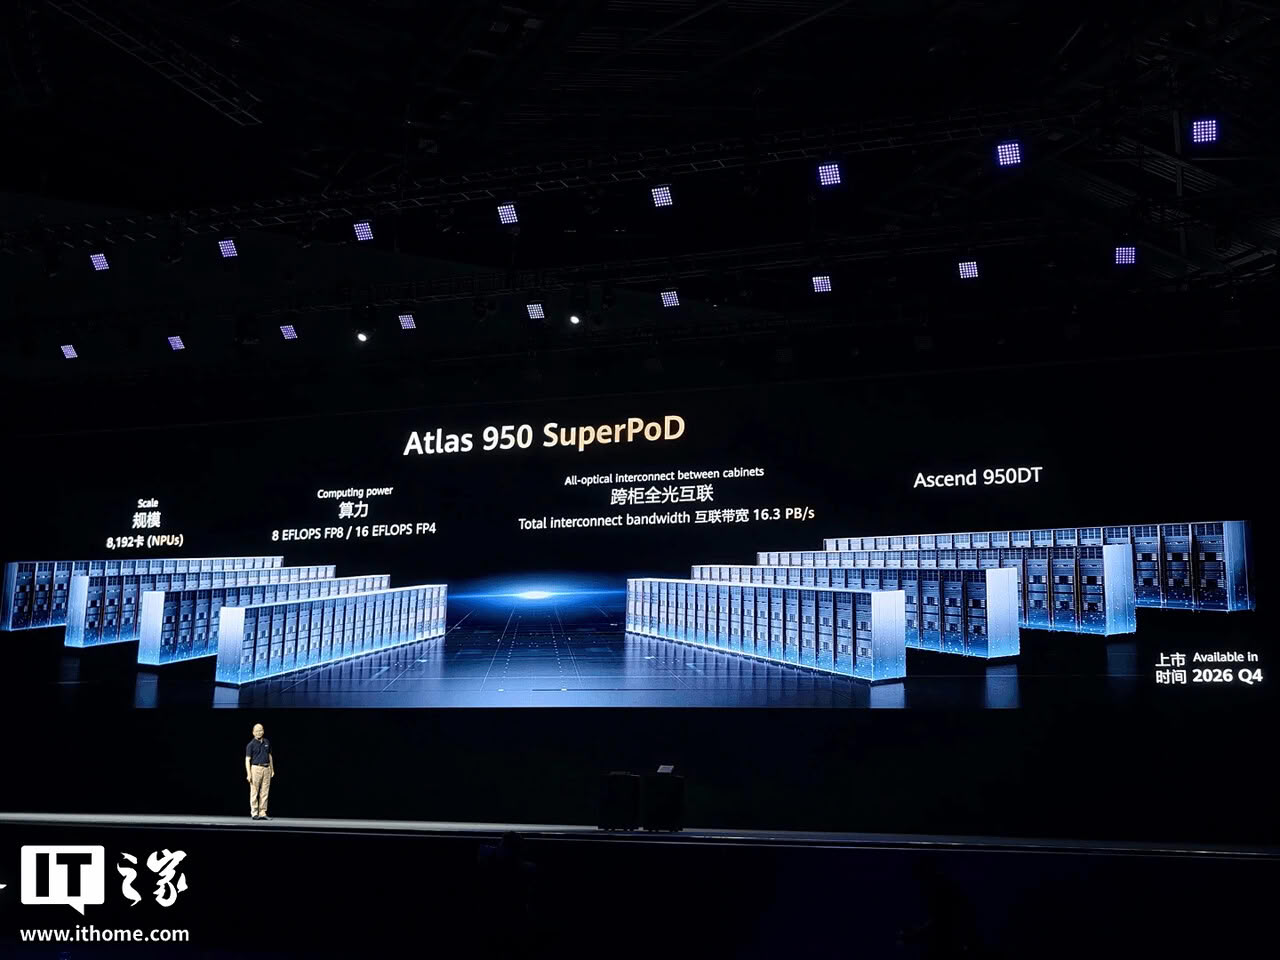
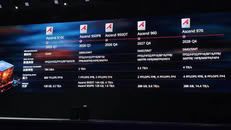
Chinese AI labs are increasingly ordering domestic AI accelerators, and one of the leading AI labs, DeepSeek, has reportedly placed an order for 160,000 Huawei Ascend 950DT chips. Late last year, Huawei revealed that the company is preparing a series of chips and rack-scale solutions to meet domestic AI demand, and now we are seeing large orders starting to materialize. For reference, the Huawei Ascend 950DT AI accelerator has a memory capacity of 144 GB, built on Huawei's own HBM memory design. This in-house solution delivers a bandwidth of nearly 4 TB/s, aligning perfectly with Huawei's vision. The chip can achieve about one PetaFLOP of FP8 peak compute, or about two PetaFLOPS of FP4.

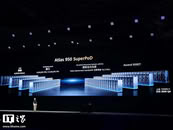
DeepSeek, one of the leading Chinese AI labs, will use Huawei's Ascend 950DT chips for large-scale inference operations and will deploy them in a single data center located in Inner Mongolia. The overall system will deliver a peak of 160 ExaFLOPS at FP8 or about 320 ExaFLOPS at FP4 precision. The system will also have about 23 PB of total HBM memory, meaning that the large-scale inferencing operations will be able to serve thousands of customers concurrently without any issues.
CXMT Captures 10% of the Global DRAM Market Revenue Share

According to Counterpoint Research trackers, Chinese memory giant CXMT captured 10% of the global DRAM market share by revenue in Q2 2026, which is 150% more than the company had a year ago. On a quarterly basis, the company also experienced significant growth of 25%, as it increased its market share from 8% in Q1 to 10% in Q2. This is impressive considering the company managed to grow its revenue market share despite constrained access to advanced tooling, while established giants like Samsung, SK hynix, and Micron have undisputed access to all semiconductor manufacturing tools.

Among other DRAM makers, Samsung retains the number one spot with a 38% share, SK hynix holds 25%, and Micron is just behind at 24%. Interestingly, over the last few quarters, Samsung managed to maintain and grow its number one position, while SK hynix's share dropped from 39% a year ago to the current 25%. Micron fluctuated between 22% and the current 24%, while Nanya doubled its share from 1% to 2%.

Samsung New Memory Roadmap: HBM5 Aims for 2x Performance, zHBM for 8x

Samsung presented its updated memory roadmap at SEMICON Taiwan 2026, with HBM5 and the upcoming zHBM architecture being the main focus points while setting ambitious goals and expectations. According to Samsung, HBM5 is targeting twice the performance and 20% higher performance per watt compared to HBM4E, alongside a 20% reduction in thermal resistance. As changes, the base die moves from the 4 nm process used in HBM4 and HBM4E to Samsung's in-house 2 nm node, and the stack options expand to 12, 16, and 20 layers. Mass production is expected around 2028. Recently, Samsung confirmed at the Hot Chips 2026 conference's Advance Program that the company is preparing to ship HBM4E memory with speeds of 16 Gbps per pin. Samsung is currently shipping HBM4 that works at 11.7 Gbps per pin.

zHBM uses a more radical approach, rather than placing memory beside the accelerator as conventional HBM does, zHBM stacks memory directly on top of the processor, shortening the data path and delivering higher bandwidth and efficiency. With zHBM, Samsung is targeting eight times the raw performance and three times the performance per watt of HBM4E, with thermal resistance reduced by 75-90%. At FMS 2026, Samsung unveiled the industry's first concept models of zHBM and is expected to launch this completely different architecture after 2029. Rethinking the HBM architecture appears to be the direction the industry is heading. NVIDIA recently announced its own NVHBM custom memory that moves the memory controller into the HBM base die rather than keeping it on the compute die.

NVIDIA's "Rubin CPX" GPU Reborn with HBM4 Memory, No More GDDR7

NVIDIA has reportedly revived its "Rubin CPX" AI accelerator project, which had previously been put on hold. Today, well-known supply chain analyst Ming Chi Kuo reported that NVIDIA is reintroducing the "Rubin CPX," now featuring HBM4 memory instead of the previously planned GDDR7. Late last year, NVIDIA announced its plans to develop a specialized accelerator derived from the "Rubin" GPU family, designed for large-scale agentic AI workloads. After the announcement, the project was reportedly paused, but NVIDIA has now redesigned the memory architecture. Previously, the "Rubin CPX" was slated to have 128 GB of GDDR7 memory, but it will now include 168 GB of HBM4 memory. This GPU SKU is housed in a separate rack with configurations ranging from 64 to 256 standalone CPX GPUs per rack.

This GPU is dedicated to prefill workloads, powering racks that manage input context for LLMs and KV cache processing. Essentially, NVIDIA is separating prefill from decode tasks, with CPX GPUs handling prefill and regular "Rubin" GPUs managing decode. A rack tray with eight CPX GPUs can handle 1.34 TB of long-context prefill and the associated KV cache, all utilizing HBM4 memory for faster processing and increased bandwidth. Since the previous design did not require HBM4 integration, NVIDIA has redesigned the package, likely using TSMC's CoWoS-S or CoWoS-L for packaging.

CXMT Starts Risk Production of HBM3E Memory

Chinese memory giant CXMT has reportedly begun risk production of HBM3E memory, according to The Information. This indicates that Chinese memory manufacturers are currently two generations behind South Korean companies, which are gradually transitioning to HBM4E memory production. However, this is a significant milestone for CXMT, which is on track to achieve a manufacturing capacity of around 350,000 DRAM wafers per month by the end of the year, with plans to increase that capacity in the coming years. It is reported that HBM3E manufacturing has started in very low quantities, signifying the commencement of risk production.

While we don't know the specifications of CXMT's HBM3E memory, we know that the standard JEDEC specification states that this must be a 1,024-bit width, and speeds of anywhere from 9.2 Gbps per pin to 12.4 Gbps, with most of the standard configurations targeting 9.6 Gbps per pin. The total bandwidth is around 1.2 TB/s, and capacities come in anywhere from 24 GB using 8-hi stacks or 36 GB using 12-high stacks of 24 Gb layers. However, given that CXMT progresses rapidly from risk production to mass production, we could see high volume manufacturing take place in just a few weeks.
CXMT HBM3E

NVIDIA Invests $3.5 Billion in MediaTek, Partners on NVLink Fusion

NVIDIA announced today that it is investing $3.5 billion in MediaTek and adding new layers of collaboration between the two silicon giants. It's important to note that NVIDIA and MediaTek are already working together, as MediaTek designed an SoC called GB10 that powers NVIDIA's RTX Spark consumer products and DGX Spark mini workstations. Both companies have confirmed that they will be approaching the collaboration through NVIDIA's NVLink Fusion ecosystem. NVLink Fusion serves as an IP and chiplet framework that allows non-NVIDIA processors and accelerators to become key participants in the company's data center fabric.

MediaTek will offer the NVLink Fusion platform to its customers, which include numerous ASIC clients like Google, enabling them to connect their XPUs to the NVLink Fusion scale-up fabric using photonic or classical copper interconnects. This includes the NVLink-C2C high-bandwidth fabric, which can connect multiple nearby XPUs and is also used in the upcoming NVIDIA "Rosa" CPUs. Additionally, MediaTek will offer customers NVIDIA's newly announced NVHBM, which integrates the controller into the 3D HBM stack, significantly enhancing performance and efficiency. Compared to standard HBM4E, NVIDIA claims up to 30% more memory bandwidth, 15% lower HBM power consumption, and up to 25% more usable compute die area on the processing unit.

SK hynix Eyes Intel Foundry for HBM4E Base Die Manufacturing

Intel Foundry might win the contract to manufacture base dies for HBM4E memory from SK hynix, according to the South Korean Herald. Reportedly, SK hynix is considering diversifying its base die supplier from solely TSMC to a dual sourcing strategy involving both TSMC and Intel, with Intel Foundry potentially securing a significant portion of the contract. As readers may recall, HBM4E memory allows for the implementation of a base die with custom logic, with DRAM dies stacked on top. Until now, SK hynix has only considered TSMC for this application, but now Intel is also being considered.

For instance, customers could implement custom logic like memory controllers and PHYs directly on the HBM4E base die, significantly reducing the area occupied by these components on the main compute chiplet. SK hynix would send the design to Intel, which would then provide these base dies to SK hynix. The South Korean memory giant would subsequently stack DRAM on top. This approach would free up space on the main compute tile in any AI accelerator for more processing units, reduce latency, and significantly improve performance. However, the question remains as to which Intel node would be used. Up until HBM3E, SK hynix used its own nodes to manufacture base dies. However, as those are 10 nm class nodes, customers are now requiring something more advanced.

SK hynix CEO Says Memory Shortage Will Last Through 2030

SK hynix expects the current memory shortage to persist through the end of 2030, with no clear signs of a slowdown yet, according to CEO Kwak Noh-Jung. Speaking after the company's groundbreaking ceremony for its new Indiana packaging facility, Kwak said any eventual slowdown would likely be the result of a gradual easing rather than the sharp price crashes memory markets have previously seen, per Reuters. SK hynix had previously flagged tight supply lasting through 2028 for commodity DRAM, so this latest comment pushes that prediction out further.

Kwak's reasoning is that memory products have moved away from being purely commodity parts. AI-driven demand has pushed customers toward customized DRAM and HBM configurations, which makes future demand easier for manufacturers to forecast and less prone to the abrupt oversupply swings that caused previous crashes.

SK hynix Breaks Ground on U.S. HBM Fab in Indiana, Targets Mass Production by Q2 2029

SK hynix Inc. (or "the company", www.skhynix.com) is opening a new future for AI cooperation between the United States and South Korea by establishing a first next-generation High Bandwidth Memory (HBM) production hub in the US. SK hynix announced today that it held a groundbreaking ceremony for an advanced packaging production facility for AI memory on the 27th (local time) at the Holloway Gymnasium, Purdue University, located in West Lafayette, Indiana.

The groundbreaking ceremony was attended by prominent US government and political figures, including Indiana Governor Mike Braun, US Senator Todd Young, Purdue University President Mitch Daniels, and Chairman of the Korea-US Alliance Foundation Robert Abrams. Kang Kyung-wha, Ambassador of South Korea to the United States, was also present at the event. From the SK Group, Vice Chairman Yu Jeong-Joon, Vice Chairman Lee Hyung-hee, CEO of SK hynix Kwak Noh-Jung attended.

AWS and NVIDIA to Deliver 2 Million Additional GPUs

Amazon Web Services (AWS), an Amazon.com, Inc. company (NASDAQ: AMZN), and NVIDIA (NASDAQ: NVDA) today announced a major expansion of their strategic collaboration to meet surging global demand for AI infrastructure as demand continues to accelerate. Building on already-rapid customer adoption of NVIDIA-accelerated compute on AWS, the companies plan to deploy 2 million additional NVIDIA GPUs across AWS's global infrastructure and deepen their work together across AI factories, CPUs, networking, open models, data processing and robotics, delivering co-engineered AI solutions that enable customers to accelerate AI development and deployment at unprecedented scale.

AI workloads are scaling at a swift pace, from how models are trained and run, to how data is processed, indexed and used to power intelligent applications. Customers are moving from pilot to production and scaling workloads across agentic AI, scientific discovery, enterprise automation and robotics. They need broader model choice, faster data pipelines and new capabilities for emerging use cases like physical AI. They also need confidence that the underlying infrastructure can keep pace with their own ability to innovate while maintaining the highest level of security and reliability for mission-critical workloads.

NVIDIA NVHBM Memory Promises 30% Higher Bandwidth Than HBM4E

NVIDIA has announced NVHBM, a custom high-bandwidth memory technology built into the HBM base die rather than on the compute die itself. This approach, which NVIDIA plans to use in its future GPUs, is now extended to third-party XPU customers through NVLink Fusion. The main idea behind it is rather simple, since standard HBM puts the memory controller on the compute die, that is consuming silicon that could otherwise be used for compute. NVHBM moves that controller into the 3D HBM stack, which has a notable effect on performance and efficiency. Compared to standard HBM4E, NVIDIA claims up to 30% more memory bandwidth, 15% lower HBM power consumption, and up to 25% more usable compute die area on the processing unit.

The area savings come primarily from a redesigned physical memory interface. Standard HBM uses wider interface connections that increase package footprint, on the other hand, the NVHBM custom PHY reduces that I/O area by up to 67% compared to JEDEC HBM4E. Also, the narrower interface simplifies interposer routing, freeing up to 80% more usable silicon across the layout. The reduced PHY footprint also means fewer routing constraints on the interposer, which matters when you're trying to pack multiple HBM stacks alongside a large compute die, explains NVIDIA in a dedicated blog post.

Memory Prices Soar; DRAM and NAND Flash to Account for 68% of Major CSP CapEx in 2027

According to TrendForce's latest memory industry research, major global cloud service providers (CSPs) are accelerating AI infrastructure investment, with total CapEx projected to surge 98% YoY in 2026 and rise another 50% in 2027. The rapid increase will be driven in part by soaring memory contract prices and robust procurement demand. TrendForce estimates that DRAM and NAND Flash combined will account for 47% of CSPs' total CapEx in 2026, with their share rising further to 68% in 2027.

TrendForce observes that the sharp rise in memory contract prices since the second half of 2025 has significantly increased memory's share of CSP spending. Server DRAM—a key procurement category for CSPs—saw contract prices rise by a cumulative 64% in 2H25, with a further jump of approximately 270% expected in 2026. Meanwhile, a similar trend is unfolding in NAND Flash, with enterprise SSD prices rising by around 35% in 2H25 and projected to surge by a cumulative 235% in 2026.

SK Hynix Next-Gen HBM Memory to Use Intel EMIB-T Packaging

Intel Foundry is achieving another significant success as SK hynix, a leading memory maker, is reportedly becoming a customer for EMIB advanced packaging. During Hot Chips 2026, SK hynix mentioned that it is collaborating with TSMC to integrate HBM memory into CoWoS-L, CoWoS-S, CoWoS-R, and most importantly, Intel EMIB. For instance, SK hynix's discussion focused on memory progressing from approximately 1,024 pins to 2,048 pins in the latest HBM4. The number of TSVs is increasing, and integration requires 2.5D packaging, hybrid bonding, as well as 3D DRAM integration to achieve next-generation memory technology with advanced AI accelerators.

As customers increasingly seek to diversify from TSMC's CoWoS, Intel's EMIB family offers many attractive options, particularly with EMIB-T. This variant includes TSVs to enable vertical power delivery across multiple stacked chips, supporting SK hynix's concept of vertical power delivery for 3D memory modules at the package level with EMIB-T.

NVIDIA Secures TSMC A16 Node for Next-Generation "Feynman" GPUs

According to supply chain sources and those close to TSMC, NVIDIA is already working on prototyping the replacement for its "Rubin" and "Rubin Ultra" GPU designs with the next-generation "Feynman" GPU microarchitecture. As noted in the latest report from DigiTimes, NVIDIA is opting for TSMC's A16 node, bypassing the N2 family of nodes entirely in favor of the more advanced 1.6 nm A16 design. Mass production is scheduled for the second half of 2028. The "Feynman" designs will rely on the backside power delivery in the A16 node, as well as on packaging technologies like 3D chiplets using SoIC, CoWoS-L 2.5D integration, and next-generation panel-level packaging.

Initially, NVIDIA will use SoIC 3D stacking technology to stack multiple chiplets into a single package, which will shorten the travel time between chips and reduce latency. These 3D chips will then be packaged side-by-side in a CoWoS-L or CoPoS packaging, creating a multi-kilowatt design capable of processing dozens of PetaFLOPS. For memory, NVIDIA will work with its partners to develop customized HBM, likely HBM4E, by the time "Feynman" reaches mass production. This customized memory includes a specialized base die that can contain logic elements like a memory controller or packet processing unit. Think of it as a way to pre-process data before it enters memory, or as a simple speedup, depending on what NVIDIA aims to achieve.

NVIDIA's Six-Years-Old A100 "Ampere" GPU to Remain in Use Until 2029

With the expansion of AI, every bit of available computing power is being utilized, and even NVIDIA's six-year-old A100 "Ampere" accelerator is being fully utilized at CoreWeave. According to CoreWeave, and confirmed by NVIDIA's CEO Jensen Huang, the company has signed an agreement with a customer to rent chips released more than half a decade ago for several more years, specifically through 2029. This demonstrates that NVIDIA's platforms remain in high demand, with chips released in 2020 expected to have a usable lifespan extending nearly to the end of the decade. CoreWeave customers have rented these chips through 2029 for AI training and inference. In late 2020, NVIDIA introduced a GA100 GPU SKU for the A100, featuring 6,912 CUDA cores and up to 80 GB of HBM2E memory. By today's standards, the core count may not match modern solutions, but in an era where memory shortages affect everyone, even older HBM2E is acceptable when there is 80 GB of it per card.

Despite the later-introduced "Hopper," "Blackwell," and modern "Rubin" generations offering significant, multifold improvements in efficiency, performance, and memory capacity, every available computing resource is currently being utilized. CoreWeave confirmed that a customer is renting this six-year-old GPU through 2029, indicating that it still holds value for someone. This GPU likely costs much less to access per hour than modern solutions, but it probably performs well enough that customers are still willing to pay for it. On his social media feed, NVIDIA CEO Jensen Huang posted the following message.

SK hynix Invests 54 Trillion Won in Yongin Y2 and Cheongju M17 to Secure Mid-to-Long-Term Production for AI Memory Demand

SK hynix Inc. announced today that it has decided to build new fabs in Yongin and Cheongju to respond to the continuously growing demand for memory in the AI era.
The company approved a total investment of approximately 54 trillion, 35.2 trillion won in Yongin "Y2" fab and 19.1 trillion won in the Cheongju "M17" fab, in a board meeting.

This decision represents execution of the mid-to-long-term investment strategy announced by the company last June. Under its master plan to invest 600 trillion won in the Yongin Semiconductor Cluster and 100 trillion won to expand its Cheongju production base, SK hynix is currently constructing its first fab in Yongin (Y1). With this latest decision, the company is embarking on the construction of subsequent fabs in both Yongin and Cheongju.

NEO Semiconductor Launches NEO.AI Memory Platform

NEO Semiconductor, a leading innovator in advanced AI and memory technologies, today announced the launch of NEO.AI, its next-generation AI memory platform designed to solve the two most significant memory bottlenecks limiting future artificial intelligence systems: on-chip memory (AI cache) and HBM capacity. As part of the platform launch, the company is officially unveiling X-SRAM, its breakthrough AI on-chip memory technology, alongside the latest progress on 3D X-DRAM, its revolutionary high-capacity HBM technology.

As AI models continue to grow in size and complexity, memory is becoming the primary bottleneck for AI performance. Conventional SRAM scaling has slowed significantly as technology nodes advance, while today's HBM remains constrained by the scaling limitations of conventional 2D DRAM. Together, these limitations form the AI Memory Wall.

Samsung Continues DRAM Market Share Lead, Micron Is Catching Up, Notes Report

According to Counterpoint Research's Global Memory Tracker update for the second quarter of 2026, memory manufacturers are adjusting their share of the global DRAM revenue. The report highlights that South Korean memory makers remain dominant, with 65% of global DRAM revenue going to Samsung and SK hynix. Samsung holds the top position, capturing 39% of the global DRAM revenue. The South Korean giant has reportedly resolved its manufacturing issues, and its foundry has delivered strong performance, widening the gap with other manufacturers. Price increases in regular DRAM and specialty solutions like HBM have significantly boosted the company's revenue, securing its stable number one spot.

In second place, SK hynix holds about 26% of the global revenue share. This is a decrease from the 39% share the company held in Q2 2025, despite its revenue growing 214% year-over-year. This indicates that while the DRAM market is expanding, Samsung is capturing a larger share of the new market growth, leading to a higher overall revenue share. SK hynix was the first to implement long-term agreements with customers, where price volatility is predetermined. This strategy involves encouraging customers into multi-year agreements rather than capitalizing on short-term price fluctuations.

Memory Makers Seal 2027 Deals: No Room for New Buyers

According to DigiTimes, industry insiders are now claiming that the entire memory production capacity for 2027 has been fully booked, well ahead of the schedule the industry expected. All of the big three memory makers—Samsung, SK hynix, and Micron—have sold out their memory capacity for the upcoming year, leaving no room for additional supply for third parties to purchase more DRAM wafers. Interestingly, the report notes that everyone from OEM server makers and PC makers to AI labs knows that July and August are crucial months for securing allocations for the following year. However, some businesses have been kept in the dark because nobody has been public about this out of fear of losing their allocation.

Memory makers have been pushing customers into long-term agreements with contracts ranging from three to five years, using an advance payment deposit model where customers essentially pre-pay for some of the memory capacity. These deals are made on an individual customer level. All of this combined signals that 2027 will be the worst year in recent history regarding memory shortages, meaning that only those who managed to sign agreements for supply will benefit, while the rest are left without as there simply isn't enough available DRAM. Only about 60-70% of the estimated demand can be met in 2027, leaving a significant amount of demand unmet and waiting for the 2028 supply.

Diverging Memory Market Outlook in 2027 as DRAM Supply Remains Tight While NAND Flash Supply Conditions Ease

TrendForce's latest research on the memory industry reveals that AI will remain the primary driver of memory demand in 2027. However, market dynamics are expected to diverge between DRAM and NAND Flash.

On the DRAM side, continued HBM capacity allocation, robust AI server demand, and growing procurement of CPU memory and HBM are expected to keep supply constrained and prices on an upward trajectory. By contrast, NAND Flash is projected to enter a looser supply environment in 2H27 as new production capacity comes online while consumer electronics demand remains weak, increasing downward pressure on prices.

SK hynix Announces 2Q26 Financial Results

SK hynix Inc. (or "the company," www.skhynix.com) announced today that it has recorded 79.3187 trillion won in revenues, 60.5426 trillion won in operating profit (with an operating margin of 76%), and 93.9226 trillion won in net profit (with a net margin of 118%), marking an all-time high quarterly performance.

Driven by sustained demand growth from expanding AI infrastructure investments, high-performance products for AI servers led price increases, enabling the company to surpass its previous record set in the prior quarter. Consequently, cumulative revenue for the first half of the year crossed the 100 trillion won mark for the first time in company history. Revenue and operating profit increased by 257% and 557% year-over-year, respectively.

SK Group and NVIDIA Expand Strategic Partnership Across AI Factories and Next-Generation Memory

SK Group and NVIDIA today announced plans for a $500-billion-plus comprehensive partnership to establish AI infrastructure serving the surging demand for global compute. The two sides signed letters of intent to formalize the agreement, which spans from AI factory construction to AI memory supply.

NVIDIA Vera Rubin Infrastructure and DSX Platform Drive 2-Gigawatt Build
Today's announcement builds on the decades-long technology partnership between SK Group and NVIDIA, including the recently announced plans for SK Telecom to build a 2-gigawatt-scale AI Cloud in Korea. This cloud will use the NVIDIA DSX platform and deploy NVIDIA Vera Rubin accelerated computing powered by SK hynix HBM4, with the first AI factory planned to come online in 2027. It will be built on the NVIDIA DSX full-stack AI factory architecture, which integrates NVIDIA accelerated computing, systems, software and partner technologies to deliver the lowest token cost at maximum energy efficiency. The two companies aim to accelerate large-scale AI infrastructure development, including sovereign, physical, agentic and enterprise AI services, and jointly address the increasing AI demand across the Asia-Pacific region, including South Korea.

SK hynix Explores US Fab Options to Keep Memory Prices Under Control

SK Group Chairman Chey Tae-won has come out with unusually direct comments on memory pricing, calling current semiconductor prices "abnormally high" and warning that the situation risks creating what he termed "chipflation", where rising chip costs push up finished product prices for consumers. Speaking at the Korea Chamber of Commerce and Industry Summer Forum in Jeju on July 15, Chey argued that supply needs to increase even if it means lower margins for semiconductor companies. His reasoning: AI companies can absorb higher costs, but PC and smartphone makers have a limited ability to pass those costs on to individual consumers. If prices keep climbing, the market shrinks and new players move in, an outcome he sees as bad for the South Korean semiconductor industry in the long term. The struggle is real, as is the threat from new competitors, as shortages at Samsung, SK hynix, and Micron have forced major PC OEMs to lock in DRAM supply deals with the Chinese memory producer CXMT.

On the supply side, the picture doesn't look like it's getting better soon. Chey predicted AI semiconductor demand could surge 60-100% next year, while production from major suppliers will not increase significantly. Since AI-related demand now accounts for over half the total semiconductor market, he expects overall demand to rise by at least 50-60% against a supply that is not keeping pace. "No company is significantly increasing supply next year; it's so dire I don't know if I should describe it as chaotic," he said. According to The Chosun Daily, Chey confirmed that SK hynix is looking at building a semiconductor factory in the United States. These plans could significantly expand SK hynix's US footprint. The company is already investing approximately $4 billion to build advanced packaging R&D facilities and HBM production lines in West Lafayette, Indiana. Construction began in 2026 and the site is scheduled to be operational by the second half of 2028. However, he also said that the company is currently looking for possible locations globally, prioritizing sites based on speed, scale and feasibility. No specific location or timeline was given.

JEDEC SPHBM4 Standard Enables HBM4-Class Bandwidth on Organic Substrates

JEDEC Solid State Technology Association, the global leader in standards development for the microelectronics industry, today announced the publication of JESD330-4: Standard Package High Bandwidth Memory (SPHBM4). SPHBM4 uses the same DRAM dies as HBM4, commonly used in artificial intelligence accelerators, with a new interface base die that enables mounting on standard organic substrates rather than silicon substrates. JESD330-4 is available for download from the JEDEC website.

JESD330-4 SPHBM is architected to operate at the same aggregate data throughput as HBM4 using fewer pins by operating at a higher frequency. Where the HBM4 interface has 2048 data signals, when published, SPHBM4 will define 512 data signals with 4:1 serialization to achieve the same bandwidth. This change allows the relaxed bump pitch required for connection to organic substrates.

Micron Breaks Ground on $9.3 Billion Hiroshima Fab Expansion

Micron has broken ground on a ¥1.5 trillion ($9.3 billion) factory expansion in Hiroshima Prefecture, Japan, with equipment installation scheduled for the second half of 2028 confirming the previous reports of a new HBM plant in Japan. The Japanese government is contributing up to ¥500 billion ($3 billion), bringing its total support for Micron to around ¥775 billion ($4.7 billion) to date. For the moment, Micron remains the only overseas DRAM manufacturer left on Japanese soil making it a point of strategic importance for Tokyo. The Hiroshima facility has a history with Micron. This is where the company produced its very first HBM wafer, while the site was acquired when it bought the bankrupt Japanese DRAM maker Elpida Memory back in 2013. The fab expansion will focus on advanced memory including HBM with around 80% of the required materials already sourced locally in Japan. The company is also building two leading-edge fabs in Boise, US, and broke ground earlier this year on a $100 billion production site near Syracuse, New York.

Separately, Micron and Ford announced today a long-term supply agreement covering memory and storage solutions for Ford's next-generation vehicle production. Micron is expanding automotive memory output and pointing to its Manassas, Virginia fab as part of the localized supply chain backing the deal.
Return to Keyword Browsing
Nov 17th, 2026 13:47 CST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts