 40
AMD Ryzen AI Halo Review - Local-AI Powerhouse with 128 GB of Memory
Video Generation »Image Generation
Image generation is where the integrated GPU on the Ryzen AI Halo is working well, with more than enough memory to hold the big diffusion models. A discrete card looks like the obvious choice, but the model does not fit here. Qwen-Image at full bf16 precision needs about 40 GB, more than a 32 GB RTX 5090 and far beyond a 16 GB 5060 Ti, so both fail right away. You can force a GPU into running it by offloading to system RAM or dropping to a smaller precision, but that is much slower as we've seen on the LLM page.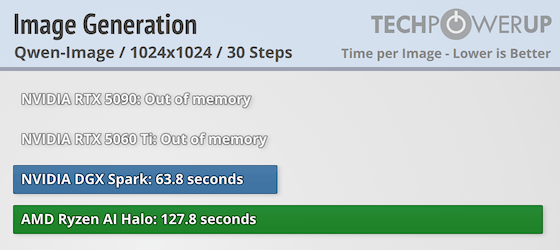
Running Qwen-Image at 30 steps, from the same default prompt and the same random seed, the Halo finished in about two minutes; the NVIDIA DGX Spark was twice as fast, around a minute. I think what's at play here is that CUDA is more mature, with better-optimized kernels. The output from the two boxes is visually identical, so this is purely a difference in speed.

Here is one of the images it produced at 1024×1024
Nov 13th, 2026 18:49 PST
change timezone
Latest GPU Drivers
New Forum Posts
- I'll flash a ASUS ROG Strix RX480 O8G in Cause of Code 43, as a Newbie (1)
- Opinion on Monitor Replacement (6)
- Tell me about your favourite graphics card (25)
- TMOG - post your benchmark results here (16)
- no "PhysX" workable (7)
- Microsoft Exchange/365 outages? (61)
- Unallocated space in ssd , is it normal? (18)
- Last game you purchased? (1401)
- Game Soundtracks You Love (1286)
- WarpCoreBench scores! (28)
Popular Reviews
- AMD Zen 6 Technical Deep Dive
- Corsair HX1000i Shift Crystal Review
- NZXT C1200 Platinum Review
- Upcoming Hardware Launches 2027 (Updated Nov 2026)
- ASUS ROG Strix B850-I Gaming Wi-Fi7 W Review
- Montech King 95 3D PRO Review
- NZXT H7 RGB+ Review
- NZXT H5 Review
- Phantom Blade Zero Performance Benchmark Review - 35 GPUs Tested
- XPG NIMBUS PLUS Review - Mid-range Chair With Strong Competitors
TPU on YouTube
Controversial News Posts
- NVIDIA Co-Founder and CEO Jensen Huang Officially Resigns (378)
- OpenAI CEO Argues Home PCs Waste the World's Limited DRAM Supply (152)
- NVIDIA Launches Investigation Into Jensen Huang's Relationship With Suspected Chinese Spy (136)
- Intel "Raptor Lake Next" 16-Core and 20-Core CPUs Surface (130)
- Legendary Game Studio BioWare Shuts Down Following EA Layoffs (104)
- Dell CEO Says the Memory Shortage Will Get Worse in 2027 (95)
- NVIDIA GeForce RTX 50-Series Scheduled for up to $500 Price Hike This Week (89)
- Modder Fits RTX 5090 With Four 8-Pin Connectors, Halving Current per Wire (80)