News Posts matching #GB200

Return to Keyword Browsing

Giga Computing Shows Data Center Portfolio and Infrastructure at NVIDIA GTC 2026 Including New NVIDIA Rubin Platforms

Giga Computing, a subsidiary of GIGABYTE and a leader in accelerated computing and infrastructure solutions, today announced new enterprise AI solutions that support NVIDIA Vera CPU and NVIDIA Vera Rubin platform, well as a new AI factory in Taiwan. The GIGABYTE booth at NVIDIA GTC shows scalable AI solutions that not only focus on performance and efficiency but also incorporate the software and infrastructure needed to build AI factories and other large GPU clusters. The GIGABYTE booth staff is ready to introduce the latest hardware and software for success in deploying accelerated computing.

Personal AI Supercomputers
With products spanning all segments of the supercomputer space, Giga Computing showcases professional desktop and deskside solutions that are ideal for AI development and accelerating AI training and inference workloads. These solutions are being used by data scientists and researchers in research institutions, government agencies, and enterprises.

GIGABYTE Powers Telecom AI Transformation with End-to-End Infrastructure at MWC 2026

GIGABYTE Technology, a global leader known for its engineering excellence in high-performance computing and AI servers, extends its comprehensive end-to-end AI infrastructure portfolio designed specifically for the telecommunications industry at MWC 2026. GIGABYTE's end-to-end product solutions enable operators to convert massive volumes of network data into intelligence, automation, and new revenue streams, as telecommunications networks evolve from data carriers into AI-powered digital platforms.

At the core of the telco-to-AI transformation is the AI Factory, where network and subscriber data are converted into operational intelligence and commercialized AI services. GIGABYTE addresses this need with GB300 NVL72, a liquid-cooled rack-scale platform integrating 72 NVIDIA Blackwell Ultra GPUs and 36 NVIDIA Grace CPUs in a single system. Connected via NVIDIA Quantum-X800 InfiniBand or NVIDIA Spectrum-X Ethernet and NVIDIA ConnectX -8 SuperNIC s, GB300 NVL72 is optimized for large-scale AI training and inference workloads, enabling operators to automate operations, optimize network planning, and deploy AI-driven services at telecom scale.

ASUS Reveals Optimized Liquid-Cooling Solutions and Strategic Partner Framework

ASUS today announced ASUS Optimized Liquid-Cooling Solutions and a strategic partner framework designed to address the escalating thermal, power, and density challenges of next-generation AI and high-performance computing data centers.

ASUS Optimized Liquid-Cooling Solutions for next-generation AI compute density
As AI and HPC workloads push compute density and power consumption beyond the capabilities of traditional air cooling, optimized liquid-cooling solutions by ASUS will provide the critical thermal management required for the next-generation NVIDIA Vera Rubin NVL72 system based data centers. By efficiently dissipating heat from high-performance CPUs, GPUs, and accelerator-dense racks, ASUS significantly reduces energy consumption, lowers PUE, and optimizes TCO while supporting unprecedented rack density.

ASUS Hardware Powers Taiwan's NCHC AI Supercomputer, Ranked #29 on TOP500

ASUS has announced that, in collaboration with the National Center for High-performance Computing (NCHC) to build the new AI supercomputer, the facility is now officially in operation. It features a dual-compute architecture that includes the cluster and the latest NVIDIA GB200 NVL72 system—Taiwan's first fully liquid-cooled AI supercomputer deployment of this architecture. The Nano4 NVIDIA HGX H200 system delivers up to 81.55 PFLOPS of performance and is ranked No. 29 on the TOP500 list, marking a meaningful milestone in strengthening Taiwan's AI-computing capabilities and accelerating its intelligent transformation.

NCHC spokesperson Dr. Chia-Lee Yang said: "As the designer of the Nano4, NCHC drove the architecture, liquid-cooling strategy, and system integration. Along with AI-infrastructure expertise from ASUS, this newly built system feeds advanced computes for generative AI, big data, deep learning, and HPC, unlocking unprecedented computational capabilities for both academia and industry."

Supermicro Showcases the Future of HPC Clusters and AI Infrastructure at SC25

Super Micro Computer, Inc. (SMCI), a Total IT Solution Provider for AI/ML, HPC, Cloud, Storage, and 5G/Edge, will showcase its latest AI Factory, HPC, and liquid-cooled data center innovations at Supercomputing 2025 (SC25) in St. Louis, Missouri. This broad portfolio, ranging from desktop workstations to rack-scale solutions, demonstrates Supermicro's commitment to powering the next generation of high-performance computing, scientific research, and enterprise AI deployments.

"Supermicro continues to lead the industry in delivering complete, next-generation infrastructure solutions in close collaboration with our technology partners," said Charles Liang, president and CEO of Supermicro. "At SC25, we are demonstrating our high-performance DCBBS architecture, direct liquid cooling, and rack-scale innovations, which empower customers to deploy AI and HPC workloads faster, more efficiently, and more sustainably."

Quantinuum Announces Commercial Launch of New Helios Quantum Computer

Quantinuum, the world leader in quantum computing, today announced the launch of Helios, the world's most accurate general-purpose commercial quantum computer, designed to accelerate quantum computing adoption by enterprises. With the highest fidelity of any commercial system and a first-of-its-kind real-time control engine, Helios enables developers to program a quantum computer in much the same way they program heterogeneous classical computers. A new, modern Python-based programming language called Guppy allows developers to seamlessly combine hybrid compute capabilities—quantum and classical—in a single program. Helios is now available to customers through Quantinuum's cloud service and on-premise offering.

"The next computing inflection point starts today," said Dr. Rajeeb Hazra, President & CEO of Quantinuum. "For the first time enterprises can access a highly accurate general purpose quantum computer to drive real world impact, transforming how industries innovate - from drug discovery to finance to advanced materials."

Supermicro Expands NVIDIA Collaboration, Focuses on U.S.-Made AI Systems for Government Use

Super Micro Computer, Inc. (SMCI), a Total IT Solution Provider for AI/ML, HPC, Cloud, Storage, and 5G/Edge, is showcasing its advanced AI infrastructure solutions at NVIDIA GTC in Washington, D.C. this week, highlighting systems tailored to meet the stringent requirements of federal customers. Supermicro announced its plans to deliver next-generation NVIDIA AI platforms, including the NVIDIA Vera Rubin NVL144 and NVIDIA Vera Rubin NVL144 CPX in 2026. Additionally, Supermicro introduces U.S.-manufactured, TAA (Trade Agreements Act)-compliant systems, including the high-density 2OU NVIDIA HGX B300 8-GPU system with up to 144 GPUs per rack and an expanded portfolio featuring a Super AI Station based on NVIDIA GB300 and the new rack-scale NVIDIA GB200 NVL4 HPC solutions.

"Our expanded collaboration with NVIDIA and our focus on U.S.-based manufacturing position Supermicro as a trusted partner for federal AI deployments. With our corporate headquarters, manufacturing, and R&D all based in San Jose, California, in the heart of Silicon Valley, we have an unparalleled ability and capacity to deliver first-to-market solutions are developed, constructed, validated (and manufactured) for American federal customers," said Charles Liang, president and CEO, Supermicro. "The result of many years of working hand-in-hand with our close partner NVIDIA—also based in Silicon Valley—Supermicro has cemented its position as a pioneer of American AI infrastructure development."

NVIDIA to Build Seven New AI Supercomputers for U.S. Government

NVIDIA today announced that it is working with the U.S. Department of Energy's national labs and the nation's leading companies to build America's AI infrastructure to support scientific discovery, economic growth and power the next industrial revolution.

"We are at the dawn of the AI industrial revolution that will define the future of every industry and nation," said Jensen Huang, founder and CEO of NVIDIA. "It is imperative that America lead the race to the future—this is our generation's Apollo moment. The next wave of inventions, discoveries and progress will be determined by our nation's ability to scale AI infrastructure. Together with our partners, we are building the most advanced AI infrastructure ever created, ensuring that America has the foundation for a prosperous future, and that the world's AI runs on American innovation, openness and collaboration, for the benefit of all."

ASUS Unveils AI Factory and Next-Gen Servers with NVIDIA HGX B300 systems at OCP 2025

ASUS today announced its participation in the 2025 OCP Global Summit, being held from October 13-16 at the San Jose Convention Center, booth #C15. At the event, ASUS unveiled its XA NB3I-E12 series AI servers, based on NVIDIA HGX B300 system integrated with NVIDIA ConnectX-8 InfiniBand SuperNICs, 5 PCIe expansion slots, 32 DIMM and 10 NVMe. Designed for enterprises and cloud service providers (CSPs) managing intensive AI workloads, these servers deliver outstanding performance and stability, unlocking the full potential of AI.

Starting this September, ASUS AI POD built on NVIDIA GB300 NVL72 and XA NB3I-E12 servers based on NVIDIA HGX B300 have begun shipping, giving enterprises and cloud service providers early access to cutting-edge AI performance and reliability.

Microsoft Unveils World's Biggest AI Datacenter, Housing Hundreds of Thousands of GPUs

Microsoft announced today that it will bring Fairwater, a purpose-built AI datacenter in Mount Pleasant, Wisconsin, online in early 2026. The new site is designed as the most powerful datacenter on the planet, serving as a hub for next-generation model training and inference. The campus covers 315 acres with roughly 1.2 million square feet across three buildings and will house hundreds of thousands of NVIDIA GB200 and GB300 GPUs linked by fiber, which can reportedly circle the globe 4.5 times. While we don't have information on the exact GPU count, Microsoft claims the installation will deliver about 10x the performance of today's fastest supercomputers for frontier AI workloads. With the fastest already deployed cluster being xAI's Colossus 1, this means that this system could have over half a million "Blackwell" and "Blackwell Ultra" GPUs.

Over 90% of compute capacity will use a closed-loop liquid cooling system that is filled during construction and continuously recirculated, backed by what the company describes as the planet's second-largest water-cooled chiller plant. Around 10% of servers will rely on outside air and switch to water cooling only on the hottest days. Storage and I/O are scaled for exabyte-class datasets, and the buildout involved 46.6 miles of deep foundation piles, 26.5 million pounds of structural steel, 120 miles of medium-voltage underground cable, 72.6 miles of mechanical piping, and an external cooling array that includes 172 20-foot fans.

NVIDIA Blackwell Ultra Sets the Bar in New MLPerf Inference Benchmark

Inference performance is critical, as it directly influences the economics of an AI factory. The higher the throughput of AI factory infrastructure, the more tokens it can produce at a high speed - increasing revenue, driving down total cost of ownership (TCO) and enhancing the system's overall productivity. Less than half a year since its debut at NVIDIA GTC, the NVIDIA GB300 NVL72 rack-scale system - powered by the NVIDIA Blackwell Ultra architecture - set records on the new reasoning inference benchmark in MLPerf Inference v5.1, delivering up to 1.4x more DeepSeek-R1 inference throughput compared with NVIDIA Blackwell-based GB200 NVL72 systems.

Blackwell Ultra builds on the success of the Blackwell architecture, with the Blackwell Ultra architecture featuring 1.5x more NVFP4 AI compute and 2x more attention-layer acceleration than Blackwell, as well as up to 288 GB of HBM3e memory per GPU. The NVIDIA platform also set performance records on all new data center benchmarks added to the MLPerf Inference v5.1 suite - including DeepSeek-R1, Llama 3.1 405B Interactive, Llama 3.1 8B and Whisper - while continuing to hold per-GPU records on every MLPerf data center benchmark.

OpenAI and Oracle Commit 4.5 GW Data Center Expansion to Stargate Network

OpenAI and Oracle today announced a binding agreement to add 4.5 gigawatts of power-dense data center capacity to the Stargate network, pushing the project past the 5 GW milestone and keeping it on track to house over two million AI chips. While SoftBank remains a name on Stargate's January press release, the Japanese conglomerate is not contributing capital to this specific tranche, leaving Oracle as the primary financier and operator for now. The new build-out will join Stargate I in Abilene, where Oracle delivered the first NVIDIA GB200 racks last month and where OpenAI is already running frontier model training workloads. Construction crews from more than twenty states are on site, and OpenAI projects that the expanded footprint will generate over 100,000 US jobs, spanning electricians, mechanical technicians, and indirect manufacturing roles, within the next four years.

The announcement arrives less than a week after the Wall Street Journal characterized Stargate as a "stalled" venture, a claim OpenAI CEO Sam Altman swiftly rebutted on X, affirming that total investment will "significantly exceed" the originally pledged $500 billion and that GPU counts are on pace to break the two-million-chip barrier this year. Site selection for the 4.5 GW increment remains under review, with Texas, Michigan, Wisconsin, and Wyoming under consideration. Oracle has reportedly placed a $40 billion order for additional NVIDIA silicon, showing the scale of its commitment. Power availability remains the critical constraint, as 4.5 GW equals the average draw of 3.5 million homes, prompting parallel negotiations with utilities for on-site generation and dedicated transmission lines. Abilene's H-shaped halls, each designed to hold 50,000 GB200s, serve as a live prototype, and lessons learned there, including liquid-cooling loops and modular substations, will be replicated across future campuses.

NVIDIA NVL72 GB200 Systems Accelerate the Journey to Useful Quantum Computing

The integration of quantum processors into tomorrow's supercomputers promises to dramatically expand the problems that can be addressed with compute—revolutionizing industries including drug and materials development.

In addition to being part of the vision for tomorrow's hybrid quantum-classical supercomputers, accelerated computing is dramatically advancing the work quantum researchers and developers are already doing to achieve that vision. And in today's development of tomorrow's quantum technology, NVIDIA GB200 NVL72 systems and their fifth-generation multinode NVIDIA NVLink interconnect capabilities have emerged as the leading architecture.

Supermicro Unveils Industry's Broadest Enterprise AI Solution Portfolio for NVIDIA Blackwell Architecture

Supermicro, Inc., a Total IT Solution Provider for AI, Cloud, Storage, and 5G/Edge, is announcing an expansion of the industry's broadest portfolio of solutions designed for NVIDIA Blackwell Architecture to the European market. The introduction of more than 30 solutions reinforces Supermicro's industry leadership by providing the most comprehensive and efficient solution stack for NVIDIA HGX B200, GB200 NVL72, and RTX PRO 6000 Blackwell Server Edition deployments, enabling rapid time-to-online for European enterprise AI factories across any environment. Through close collaboration with NVIDIA, Supermicro's solution stack enables the deployment of NVIDIA Enterprise AI Factory validated design and supports the upcoming introduction of NVIDIA Blackwell Ultra solutions later this year, including NVIDIA GB300 NVL72 and HGX B300.

"With our first-to-market advantage and broad portfolio of NVIDIA Blackwell solutions, Supermicro is uniquely positioned to meet the accelerating demand for enterprise AI infrastructure across Europe," said Charles Liang, president and CEO of Supermicro. "Our collaboration with NVIDIA, combined with our global manufacturing capabilities and advanced liquid cooling technologies, enables European organizations to deploy AI factories with significantly improved efficiency and reduced implementation timelines. We're committed to providing the complete solution stack enterprises need to successfully scale their AI initiatives."

ASUS Announces Key Milestone with Nebius and Showcases NVIDIA GB300 NVL72 System at GTC Paris 2025

ASUS today joined GTC Paris at VivaTech 2025 as a Gold Sponsor, highlighting its latest portfolio of AI infrastructure solutions and reinforcing its commitment to advancing the AI Factory vision with a full range of NVIDIA Blackwell Ultra solutions, delivering breakthrough performance from large-scale datacenter to personal desktop.

ASUS is also excited to announce a transformative partnership milestone in its partnership with Nebius. Together, the two companies are enabling a new era of AI innovation built on NVIDIA's advanced platforms. Building on the success of the NVIDIA GB200 NVL72 platform deployment, ASUS and Nebius are now moving forward with strategic collaborations featuring the next-generation NVIDIA GB300 NVL72 platform. This ongoing initiative underscores ASUS's role as a key enabler in AI infrastructure, committed to delivering scalable, high-performance solutions that help enterprises accelerate AI adoption and innovation.

NVIDIA Blackwell Delivers Breakthrough Performance in Latest MLPerf Training Results

NVIDIA is working with companies worldwide to build out AI factories—speeding the training and deployment of next-generation AI applications that use the latest advancements in training and inference. The NVIDIA Blackwell architecture is built to meet the heightened performance requirements of these new applications. In the latest round of MLPerf Training—the 12th since the benchmark's introduction in 2018—the NVIDIA AI platform delivered the highest performance at scale on every benchmark and powered every result submitted on the benchmark's toughest large language model (LLM)-focused test: Llama 3.1 405B pretraining.

The NVIDIA platform was the only one that submitted results on every MLPerf Training v5.0 benchmark—underscoring its exceptional performance and versatility across a wide array of AI workloads, spanning LLMs, recommendation systems, multimodal LLMs, object detection and graph neural networks. The at-scale submissions used two AI supercomputers powered by the NVIDIA Blackwell platform: Tyche, built using NVIDIA GB200 NVL72 rack-scale systems, and Nyx, based on NVIDIA DGX B200 systems. In addition, NVIDIA collaborated with CoreWeave and IBM to submit GB200 NVL72 results using a total of 2,496 Blackwell GPUs and 1,248 NVIDIA Grace CPUs.

NVIDIA Plans 800 V Power Infrastructure to Drive 1 MW AI Racks

AI infrastructure buildout is pushing data center desings beyond the limits of conventional power delivery. Traditional in-rack 54 V DC distribution was designed for racks drawing tens of kilowatts and cannot scale to the megawatt requirements for next-generation AI facilities. At GTC and Computex 2025, NVIDIA introduced a comprehensive solution: an end-to-end 800-volt high-voltage DC (HVDC) infrastructure that will support 1-megawatt AI racks and beyond, with deployments planned to begin in 2027. Cooling and cabling already place immense strain on rack designs. NVIDIA's current GB200 and GB300 NVL72 systems can draw up to 132 kW per rack—significantly more than the 50 to 80 kW that most data halls were built to handle. If rack power rises to the 700 kW to 1 MW range under a 54 V distribution, it would require roughly 64 U of chassis space devoted solely to copper busbars, which is almost the entire rack, and about 200 kg of copper per rack. For a 1 GW installation, that adds up to nearly half a million metric tons of copper.

NVIDIA's 800 V HVDC architecture eliminates multiple AC-to-DC and DC-to-DC conversion stages by consolidating them into a single grid-edge rectifier. From a 13.8 kV AC feed, power is converted directly to 800 V DC and then routed through row-level busways to each rack. Compact DC-DC modules in the rack step down the voltage for the GPUs. Fewer power supply units mean fewer fans, lower heat output, and a simpler electrical footprint. Beyond scalability, 800 V HVDC offers up to 5 percent gains in end-to-end efficiency and a 45 percent reduction in copper usage. This results in lower electricity costs and reduced infrastructure buildout costs. To drive industry adoption, NVIDIA has partnered with leaders across the power ecosystem. Silicon and power-electronics specialists such as Infineon, MPS, Navitas, ROHM, STMicroelectronics, and Texas Instruments are contributing components. System integrators, including Delta, Flex Power, Lead Wealth, LiteOn, and Megmeet, are developing power shelves. Data-center infrastructure companies Eaton, Schneider Electric, and Vert iv are standardizing protective devices at every boundary from the power room to the rack. Below you can compare the traditional rack system in the top to the newly proposed variation in the middle and the bottom part of the image. Thanks to HardwareLuxx, we can even see how it looks in reality.

NVIDIA & Microsoft Accelerate Agentic AI Innovation - From Cloud to PC

Agentic AI is redefining scientific discovery and unlocking research breakthroughs and innovations across industries. Through deepened collaboration, NVIDIA and Microsoft are delivering advancements that accelerate agentic AI-powered applications from the cloud to the PC. At Microsoft Build, Microsoft unveiled Microsoft Discovery, an extensible platform built to empower researchers to transform the entire discovery process with agentic AI. This will help research and development departments across various industries accelerate the time to market for new products, as well as speed and expand the end-to-end discovery process for all scientists.

Microsoft Discovery will integrate the NVIDIA ALCHEMI NIM microservice, which optimizes AI inference for chemical simulations, to accelerate materials science research with property prediction and candidate recommendation. The platform will also integrate NVIDIA BioNeMo NIM microservices, tapping into pretrained AI workflows to speed up AI model development for drug discovery. These integrations equip researchers with accelerated performance for faster scientific discoveries. In testing, researchers at Microsoft used Microsoft Discovery to detect a novel coolant prototype with promising properties for immersion cooling in data centers in under 200 hours, rather than months or years with traditional methods.

Report: Customers Show Little Interest in AMD Instinct MI325X Accelerators

AMD's Instinct MI325X accelerator has struggled to gain traction with large customers, according to extensive data from SemiAnalysis. Launched in Q2 2025, the MI325X arrived roughly nine months after NVIDIA's H200 and concurrently with NVIDIA's "Blackwell" mass-production roll-out. That timing proved unfavourable, as many buyers opted instead for Blackwell's superior cost-per-performance ratio. Early interest from Microsoft in 2024 failed to translate into repeat orders. After the initial test purchases, Microsoft did not place any further commitments. In response, AMD reduced its margin expectations in an effort to attract other major clients. Oracle and a handful of additional hyperscalers have since expressed renewed interest, but these purchases remain modest compared with NVIDIA's volume.

A fundamental limitation of the MI325X is its eight-GPU scale-up capacity. By contrast, NVIDIA's rack-scale GB200 NVL72 supports up to 72 GPUs in a single cluster. For large-scale AI inference and frontier-level reasoning workloads, that difference is decisive. AMD positioned the MI325X against NVIDIA's air-cooled HGX B200 NVL8 and HGX B300 NVL16 modules. Even in that non-rack-scale segment, NVIDIA maintains an advantage in both raw performance and total-cost-of-ownership efficiency. Nonetheless, there remains potential for the MI325X in smaller-scale deployments that do not require extensive GPU clusters. Smaller model inference should be sufficient for eight GPU clusters, where lots of memory bandwidth and capacity are the primary needs. AMD continues to improve its software ecosystem and maintain competitive pricing, so AI labs developing mid-sized AI models may find the MI325X appealing.

NVIDIA RTX PRO 6000 Appears in Early Listings: $11,000 in Japan, €9,000 in Europe

Despite featuring the biggest GB202 configuration—24,064 CUDA cores distributed across 188 streaming multiprocessors running at up to 2,617 MHz, paired with 96 GB of GDDR7 ECC memory—the RTX PRO 6000 'Blackwell' GPU from NVIDIA is yet to have an official launch date or pricing disclosed. Early European retailer listings show the card starting at €8,982, including 21 percent VAT. Some vendors are already asking for more than €10,900. However, business customers evaluating net costs can anticipate a significant saving, with a rough estimate of €7,430 before tax, subject to local tax regulations and import fees. NVIDIA is expected to offer the RTX PRO 6000 in several variants, including Workstation, Server, and Max-Q editions that tailor power envelopes and cooling designs to different professional environments.

In Japan, pre-release listings place the RTX PRO 6000 at ¥1,630,600 (around $11,326), reflecting a similar premium level. The appearance of these price tags suggests that initial shipments have quietly reached distributors well before any formal announcement. One Redditor even got his hands on it early, preparing for a trial run. Of course, before NVIDIA releases RTX PRO-optimized drivers, the performance will lag behind the gaming GeForce RTX 5090 SKU. Geared toward enterprise workstations and professional workloads that demand high memory capacity and massive compute performance, this pricing profile distinguishes the RTX PRO 6000 from gaming-grade SKUs. Still, it is below the server-grade GB200-based Blackwell GPUs aimed at AI and HPC workloads.

Oracle Cloud Infrastructure Bolstered by Thousands of NVIDIA Blackwell GPUs

Oracle has stood up and optimized its first wave of liquid-cooled NVIDIA GB200 NVL72 racks in its data centers. Thousands of NVIDIA Blackwell GPUs are now being deployed and ready for customer use on NVIDIA DGX Cloud and Oracle Cloud Infrastructure (OCI) to develop and run next-generation reasoning models and AI agents. Oracle's state-of-the-art GB200 deployment includes high-speed NVIDIA Quantum-2 InfiniBand and NVIDIA Spectrum-X Ethernet networking to enable scalable, low-latency performance, as well as a full stack of software and database integrations from NVIDIA and OCI.

OCI, one of the world's largest and fastest-growing cloud service providers, is among the first to deploy NVIDIA GB200 NVL72 systems. The company has ambitious plans to build one of the world's largest Blackwell clusters. OCI Superclusters will scale beyond 100,000 NVIDIA Blackwell GPUs to meet the world's skyrocketing need for inference tokens and accelerated computing. The torrid pace of AI innovation continues as several companies including OpenAI have released new reasoning models in the past few weeks.

NVIDIA Blackwell Platform Boosts Water Efficiency by Over 300x - "Chill Factor" for AI Infrastructure

Traditionally, data centers have relied on air cooling—where mechanical chillers circulate chilled air to absorb heat from servers, helping them maintain optimal conditions. But as AI models increase in size, and the use of AI reasoning models rises, maintaining those optimal conditions is not only getting harder and more expensive—but more energy-intensive. While data centers once operated at 20 kW per rack, today's hyperscale facilities can support over 135 kW per rack, making it an order of magnitude harder to dissipate the heat generated by high-density racks. To keep AI servers running at peak performance, a new approach is needed for efficiency and scalability.

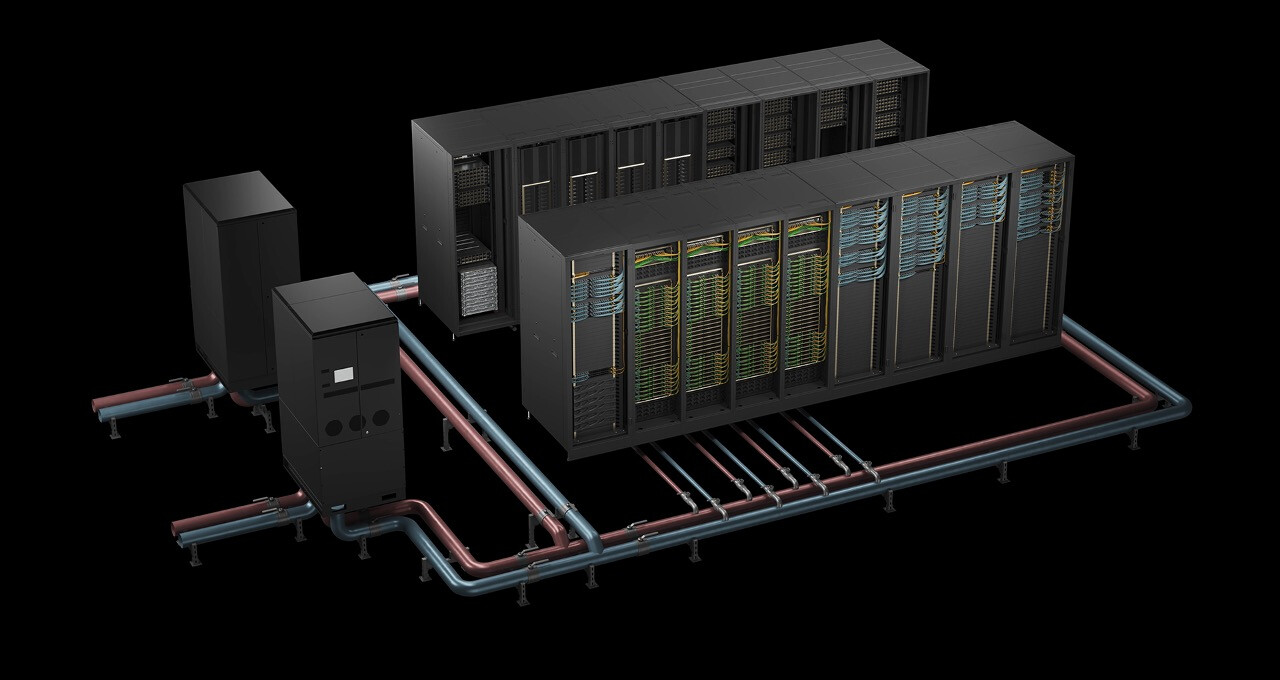
One key solution is liquid cooling—by reducing dependence on chillers and enabling more efficient heat rejection, liquid cooling is driving the next generation of high-performance, energy-efficient AI infrastructure. The NVIDIA GB200 NVL72 and the NVIDIA GB300 NVL72 are rack-scale, liquid-cooled systems designed to handle the demanding tasks of trillion-parameter large language model inference. Their architecture is also specifically optimized for test-time scaling accuracy and performance, making it an ideal choice for running AI reasoning models while efficiently managing energy costs and heat.

Huawei CloudMatrix 384 System Outperforms NVIDIA GB200 NVL72

Huawei announced its CloudMatrix 384 system super node, which the company touts as its own domestic alternative to NVIDIA's GB200 NVL72 system, with more overall system performance but worse per-chip performance and higher power consumption. While NVIDIA's GB200 NVL72 uses 36 Grace CPUs paired with 72 "Blackwell" GB200 GPUs, the Huawei CloudMatrix 384 system employs 384 Huawei Ascend 910C accelerators to beat NVIDIA's GB200 NVL72 system. It takes roughly five times more Ascend 910C accelerators to deliver nearly twice the GB200 NVL system performance, which is not good on per-accelerator bias, but excellent on per-system level of deployment. SemiAnalysis argues that Huawei is a generation behind in chip performance but ahead of NVIDIA in scale-up system design and deployment.

When you look at individual chips, NVIDIA's GB200 NVL72 clearly outshines Huawei's Ascend 910C, delivering over three times the BF16 performance (2,500 TeraFLOPS vs. 780 TeraFLOPS), more on-chip memory (192 GB vs. 128 GB), and faster bandwidth (8 TB/s vs. 3.2 TB/s). In other words, NVIDIA has the raw power and efficiency advantage at the chip level. But flip the switch to the system level, and Huawei's CloudMatrix CM384 takes the lead. It cranks out 1.7× the overall PetaFLOPS, packs in 3.6× more total HBM capacity, and supports over five times the number of GPUs and the associated bandwidth of NVIDIA's NVL72 cluster. However, that scalability does come with a trade-off, as Huawei's setup draws nearly four times more total power. A single GB200 NVL72 draws 145 kW of power, while a single Huawei CloudMatrix 384 draws ~560 kW. So, NVIDIA is your go-to if you need peak efficiency in a single GPU. If you're building a massive AI supercluster where total throughput and interconnect speed matter most, Huawei's solution actually makes a lot of sense. Thanks to its all-to-all topology, Huawei has delivered an AI training and inference system worth purchasing. When SMIC, the maker of Huawei's chips, gets to a more advanced manufacturing node, the efficiency of these systems will also increase.

Thousands of NVIDIA Grace Blackwell GPUs Now Live at CoreWeave

CoreWeave today became one of the first cloud providers to bring NVIDIA GB200 NVL72 systems online for customers at scale, and AI frontier companies Cohere, IBM and Mistral AI are already using them to train and deploy next-generation AI models and applications. CoreWeave, the first cloud provider to make NVIDIA Grace Blackwell generally available, has already shown incredible results in MLPerf benchmarks with NVIDIA GB200 NVL72 - a powerful rack-scale accelerated computing platform designed for reasoning and AI agents. Now, CoreWeave customers are gaining access to thousands of NVIDIA Blackwell GPUs.

"We work closely with NVIDIA to quickly deliver to customers the latest and most powerful solutions for training AI models and serving inference," said Mike Intrator, CEO of CoreWeave. "With new Grace Blackwell rack-scale systems in hand, many of our customers will be the first to see the benefits and performance of AI innovators operating at scale."

GPUs Could be Exempt from Massive Trump Tariffs Through USMCA Assembly Loophole

High-performance GPUs manufactured in Taiwan could now enter the US market tariff-free through a technical loophole in the United States-Mexico-Canada Agreement (USMCA), found by a research firm SemiAnalysis. Companies can route Taiwan-made GPUs through assembly facilities in Mexico and Canada, effectively circumventing the 32% import duty that would otherwise apply to direct shipments from Taiwan. The exemption hinges on a Most-Favored-Nation clause within the USMCA framework that specifically classifies digital processing units (HTS 8471.50), automatic data processing machine units (HTS 8471.80), and their associated components (HTS 8473.30) as "originating goods." This classification applies regardless of manufacturing origin, creating a duty-free pathway for NVIDIA HGX boards, GB200 baseboards, and RTX GPU cards that undergo final assembly in North American facilities.

The strategy capitalizes on two complementary policy mechanisms. First, President Trump's March 7 executive orders maintained existing USMCA exemptions, preserving the duty-free status for compliant goods from Canada and Mexico. Second, the USMCA's expanded definition of originating products creates a classification framework that treats assembled servers and related components as North American products despite their core manufacturing in Taiwan. For US technology firms, the additional logistical complexity of cross-border assembly operations is offset by eliminating substantial import duties on these high-value components. This practice mirrors established protocols in agricultural imports, where products like Mexican avocados gain preferential treatment under similar origin rules. The global supply chain is adapting quickly, especially in high-margin areas like GPUs, which power AI workloads. We are yet to see how companies set up manufacturing and logistics in the new era of tariff-driven narrative.
Return to Keyword Browsing
Nov 11th, 2026 03:13 CST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts