News Posts matching #Grace

Return to Keyword Browsing

Bang & Olufsen Crafts Beo Grace - A Century of Design Distilled Into Beautiful, Wearable Sound

Bang & Olufsen's new Beo Grace earpieces combine a slim aluminium form with outstanding sound performance, embodying the brand's uncompromising mastery in uniting acoustic innovation with timeless design and craftsmanship. Born from Bang & Olufsen's relentless pursuit of perfection and inspired by fine jewellery, Beo Grace fuses miniaturised design with audio innovation, bringing exceptional sound that fits effortlessly in your pocket.

"Beo Grace is more than a new product, it is a symbol of the century ahead. Inspired by the elegance of fine jewellery and crafted from our signature aluminium, it distils everything Bang & Olufsen has stood for since 1925: uncompromising sound, enduring craftsmanship, and timeless beauty. With Beo Grace we are bringing our heritage of acoustic ingenuity into a form you can wear - a piece of design sculpture that ushers in a new era of wearable sound," says Bang & Olufsen CEO Kristian Teär.

NVIDIA Buys $5B Worth of Intel, RTX iGPUs Coming to x86, Shares up 25%

NVIDIA and Intel today announced one of the largest industry collaborations in recent years, jointly developing multiple generations of consumer PC and data center products, utilizing the best design teams from both companies. According to the latest announcement, NVIDIA is investing $5 billion at $23.28 per share, making NVIDIA one of Intel's largest shareholders, with a 4.9% stake in the total company. The goal of this collaboration is split into two verticals. One—and perhaps the most interesting one—is the integration of NVIDIA RTX GPUs inside Intel x86 System-on-Chips (SoCs), which Intel's own Arc GPUs previously powered. Intel once even considered tapping AMD with its "Kaby Lake G" design, which never progressed beyond generation one. Now, NVIDIA's RTX GPUs will become the standard for integrated graphics, powering millions of laptops, handheld devices, and possibly even desktop processors.

The second pillar of this collaboration is the development of custom x86 CPUs for NVIDIA, which will be integrated into NVIDIA's AI infrastructure platforms. Spanning multiple verticals such as DGX workstations, HGX servers, and NVIDIA SuperPODs. NVIDIA currently uses a mix of its self-developed Arm-based Grace/Vera CPUs, as well as x86 CPUs in some HGX systems. For now, this has served NVIDIA well, and its data center roadmap indicates that NVIDIA will continue to ship these custom CPUs through its product family. However, with custom x86 CPUs fine-tuned for NVIDIA, Intel will gain significant share in the AI training and inference infrastructure, where NVIDIA previously completely bypassed both x86 vendors with custom Arm designs. For example, Intel's designs, such as Clearwater Forest Xeons, are coming soon with up to 288 "Darkmont" E-cores on a massive chiplet package using the 18A node. This should be a perfect companion for NVIDIA's accelerators, and we could even see some customized versions that offer lower core counts but higher frequencies, all within NVIDIA's SuperPODs with hundreds of GPUs.

Jupiter Boots Up: Europe's Fastest Supercomputer Runs on NVIDIA Grace Hopper

Europe's high-performance computing sector received a significant boost today as the Jupiter supercomputer was officially powered on at the Jülich Supercomputing Center. The modular exascale system delivers a peak of nearly one ExaFLOP (930 PetaFLOPS) of FP64 performance and debuts as the fastest machine in Europe, positioned at number four on the Top500 list. Built around NVIDIA Grace Hopper technology, the booster contributes approximately 793 PetaFLOPs of FP64, while each compute node features four GH200 accelerators, resulting in a fleet of 23,752 accelerators across 5,938 nodes, all mounted in 125 server racks. Those GH200-class accelerators are noted for their strong energy efficiency, with published figures of nearly 60.5 GigaFLOPS per watt, and an accelerator farm drawing on the order of double-digit megawatts of power. Jupiter is primarily designed for AI workloads. Hence, it delivers over 90 ExaFLOPS in AI's favorite FP8 format.

Reported build costs are estimated to be near €500 million, and European planners anticipate a multibillion-euro expansion will be required to close capacity gaps, with figures of around €60 billion cited for deployments through 2030. Planners envision roughly 13 specialized AI data centers and gigafactory-scale facilities, with Jülich a candidate for expansion. Backers say this is about digital sovereignty, keeping critical infrastructure close to European research and industry rather than depending on foreign cloud providers. Operationally, Jupiter will support climate modelling, materials simulation and biological research, complemented by an inference module, Jarvis, for fast model serving. For Europe, Jupiter is meant to be both a capability and a signal: an energy-conscious exascale platform designed to anchor AI work and catalyze further regional investment.

Acer Unveils the Veriton GN100 AI Mini Workstation Built on the NVIDIA GB10 Superchip

Acer today introduced the Veriton GN100 AI Mini Workstation, a compact yet powerful computer designed to run large AI models locally, minimizing dependence on cloud services and helping reduce associated costs.

The device is built on the NVIDIA GB10 Grace Blackwell Superchip, delivering up to 1 PFLOPS of FP4 AI performance. This powerhouse combines next-generation CUDA cores, fifth-gen Tensor Cores, and 20 Arm-based CPU cores, backed by 128 GB of unified system memory and 4 TB of NVMe M.2 SSD storage. This robust configuration enables server-grade performance in a mini-PC form factor.

NVIDIA Dissects GB10 Superchip SoC with 20 CPU Cores and 6,144 CUDA GPU Cores

At Hot Chips 2025, NVIDIA offered a detailed look at the GB10 "Grace Blackwell" superchip, presenting a compact multi-die design meant to bring datacenter capabilities to a desktop-sized workstation. The chip pairs a MediaTek-sourced Arm CPU die with a Blackwell GPU die in a 2.5D package built on TSMC's 3 nm process. The CPU side implements 20 Arm v9.2 cores split into two clusters of ten, each cluster backed by a 16 MB shared L3 (32 MB total) while each core retains private L2 storage. The memory subsystem is a unified LPDDR5X-9400 fabric on a 256-bit bus, supporting up to 128 GB and delivering roughly 301 GB/s of raw bandwidth to the package. High-speed I/O is concentrated on the CPU die, while NVMe storage and peripherals ride PCIe lanes there, and a ConnectX-7 NIC is attached via a PCIe Gen 5 x8 link to enable multi-unit networking.

NVIDIA described the GPU die as a scaled Blackwell configuration tuned for low-power, small-form-factor operation. The quoted peak throughput is approximately 31 TeraFLOPS for FP32 and around 1,000 TOPS when using NVIDIA's NVFP4 reduced-precision format. The GPU carries a large 24 MB L2 that can act as a higher-level cache visible to the CPU, creating a coherent cache hierarchy across the two dies. NVIDIA states that the inter-die C2C link offers aggregate bandwidth on the order of 600 GB/s, enabling low-latency sharing without requiring heavy software-managed copying. The package is rated at approximately 140 W TDP and exposes multi-display outputs (DisplayPort alt-mode plus HDMI 2.1a options) alongside security and virtualization features intended for professional workloads.

NVIDIA Ports CUDA to RISC-V, Betting Big on Open-Source ISA

During the RISC-V Summit in China, NVIDIA's Frans Sijstermans, vice president of hardware engineering, officially announced that NVIDIA has ported its massive CUDA software library to RISC-V ISA, signaling that the company sees RISC-V adoption accelerating in every aspect of the hardware stack, and that it could be a perfect match for NVIDIA GPUs. Historically, NVIDIA ported its CUDA platform to every major instruction set, including x86, Arm, PowerPC, and even Sun's SPARC. This is done to ensure that if any platform takes off in the enterprise or any segment, NVIDIA is there from the start to support it and allow its GPUs to run at full speed. Now, the $4 trillion company is making a bet that RISC-V will be the next desirable ISA to bring full support for.

NVIDIA envisions systems where its GPUs are the center of any acceleration, and supplementary RISC-V CPUs oversee CUDA drivers, application logic, and the operating system, orchestrating parallel workloads entirely within the CUDA ecosystem. The diagram shown at the summit highlights a DPU handling networking tasks, creating a cohesive trio of compute, control, and data-movement elements. If you recall, NVIDIA already uses NV-RISC-V CPU inside its GPUs for handling control logic on the GPU itself. That demonstrates NVIDIA's strategy to build heterogeneous platforms that combine RISC-V controllers with its GPUs, DPUs, and networking silicon. Now that CUDA is fully supported on RISC-V, NVIDIA could look into alternatives for its Grace CPU to be built on the RISC-V ISA. As the open-source ISA slowly breaks into the server space with the RVA23 specification, which NVIDIA mandates for CUDA support, we could see some interesting heterogeneous designs.

Europe Builds AI Infrastructure With NVIDIA to Fuel Region's Next Industrial Transformation

NVIDIA today announced it is working with European nations, and technology and industry leaders, to build NVIDIA Blackwell AI infrastructure that will strengthen digital sovereignty, support economic growth and position the continent as a leader in the AI industrial revolution. France, Italy, Spain and the U.K. are among the nations building domestic AI infrastructure with an ecosystem of technology and cloud providers, including Domyn, Mistral AI, Nebius and Nscale, and telecommunications providers, including Orange, Swisscom, Telefónica and Telenor.

These deployments will deliver more than 3,000 exaflops of NVIDIA Blackwell compute resources for sovereign AI, enabling European enterprises, startups and public sector organizations to securely develop, train and deploy agentic and physical AI applications. NVIDIA is establishing and expanding AI technology centers in Germany, Sweden, Italy, Spain, the U.K. and Finland. These centers build on NVIDIA's history of collaborating with academic institutions and industry through the NVIDIA AI Technology Center program and NVIDIA Deep Learning Institute to develop the AI workforce and scientific discovery throughout the regions.

Pegatron Unveils AI-Optimized Server Innovations at GTC Paris 2025

PEGATRON, a globally recognized Design, Manufacturing, and Service (DMS) provider, is showcasing its latest AI server solutions at GTC Paris 2025. Built on NVIDIA Blackwell architecture, PEGATRON's cutting-edge systems are tailored for AI training, reasoning, and enterprise-scale deployment.

NVIDIA GB300 NVL72
At the forefront is the RA4802-72N2, built on the NVIDIA GB300 NVL72 rack system, featuring 72 NVIDIA Blackwell Ultra GPUs and 36 NVIDIA Grace CPUs. Designed for AI factories, it boosts output by up to 50X. PEGATRON's in-house developed Coolant Distribution Unit (CDU) delivers 310 kW of cooling capacity with redundant hot-swappable pumps, ensuring performance and reliability for mission-critical workloads.

NVIDIA Blackwell Delivers Breakthrough Performance in Latest MLPerf Training Results

NVIDIA is working with companies worldwide to build out AI factories—speeding the training and deployment of next-generation AI applications that use the latest advancements in training and inference. The NVIDIA Blackwell architecture is built to meet the heightened performance requirements of these new applications. In the latest round of MLPerf Training—the 12th since the benchmark's introduction in 2018—the NVIDIA AI platform delivered the highest performance at scale on every benchmark and powered every result submitted on the benchmark's toughest large language model (LLM)-focused test: Llama 3.1 405B pretraining.

The NVIDIA platform was the only one that submitted results on every MLPerf Training v5.0 benchmark—underscoring its exceptional performance and versatility across a wide array of AI workloads, spanning LLMs, recommendation systems, multimodal LLMs, object detection and graph neural networks. The at-scale submissions used two AI supercomputers powered by the NVIDIA Blackwell platform: Tyche, built using NVIDIA GB200 NVL72 rack-scale systems, and Nyx, based on NVIDIA DGX B200 systems. In addition, NVIDIA collaborated with CoreWeave and IBM to submit GB200 NVL72 results using a total of 2,496 Blackwell GPUs and 1,248 NVIDIA Grace CPUs.

NVIDIA Reportedly Postpones SOCAMM Rollout; Could Debut with Next-gen "Rubin" AI GPUs

Around mid-February, South Korean sources alleged that NVIDIA was in the process of developing an innovative new memory form factor. The System on Chip Advanced Memory Module (SOCAMM) design is reportedly a collaborative effort. Team Green's usual set of memory partners—SK Hynix, Samsung, and Micron—were mentioned in early 2025 news articles. Just over a month later, official press material revealed a key forthcoming deployment—Micron stated: "(our) SOCAMM (product), a modular LPDDR5X memory solution, was developed in collaboration with NVIDIA to support the NVIDIA GB300 Grace Blackwell Ultra Superchip. In a (rumored) blow to all involved parties, ZDNet Korea posits that Team Green has postponed the commercialization of their "next-generation low-power DRAM module" IP. According to industry moles, the SOCAMM standard will not debut with this generation of enterprise-focused "Grace-Blackwell" chips. Instead, fresher theories indicate a postponement into next-gen territories—possibly rescheduled to arrive alongside the firm's "Rubin" GPU architecture.

NVIDIA has reportedly sent out notices to major memory partners—(alleged) May 14 updates were received by Samsung Electronics and SK Hynix (in South Korea) and Micron (USA). As a result, SOCAMM supply timelines are (apparently) adjusted. A newer "Cordelia" board design—acting as a substrate for GB300 chips, and compatible with SOCAMM—was in the picture. The latest whispers suggest a return to an existing "Bianca" board configuration, that supports current-gen LPDDR memory modules. ZDNet believes that company engineers have run into several obstacles: "Blackwell chips have been continuously experiencing difficulties in securing design and packaging yields. In fact, the 'Cordelia' board is known to have reliability issues, such as data loss, and SOCAMM has reliability issues, such as heat dissipation characteristics." NVIDIA briefly previewed its futuristic "Rubin Ultra" AI GPU design during GTC 2025—on-stage, a "second half of 2027" release window was teased.

Lenovo Unveils ThinkStation PGX - Offering Big AI Innovation in an SFF Package

Lenovo has announced the ThinkStation PGX, a compact, personal AI developer workstation. The ThinkStation PGX is ideal for AI researchers and developers, data scientists, practitioners, students, and application engineers who need a purpose-built, compact, and powerful AI desktop solution that works immediately out of the box. Built on the NVIDIA GB10 Grace Blackwell Superchip providing up to 1 PetaFlop (1000 TOPS) of AI performance, the ThinkStation PGX can tackle large generative AI models of up to 200 billion parameters. With 128 GB of coherent unified system memory, developers can experiment, fine-tune, or inference the latest generation of reasoning AI models. To double down on computing power, developers can connect two ThinkStation PGX systems together to work with even larger AI models up to 405 billion parameters.

The ThinkStation PGX comes preconfigured with the NVIDIA DGX OS, and the NVIDIA AI software stack, along with familiar tools and frameworks like PyTorch and Jupyter. Developers can instantly prototype, fine-tune, and inference large AI models from the desktop and seamlessly deploy to the data center or cloud. "By collaborating with NVIDIA to deliver a high-performance, yet compact device, Lenovo is empowering AI developers, researchers, data scientists, and students to accelerate their workloads and adoption of breakthrough innovation in generative AI."—Rob Herman, Vice President, Worldwide Workstation and Client AI Business at Lenovo.

Kingdom of Saudi Arabia & NVIDIA Announce Building of AI Factories in the Region

NVIDIA and the Kingdom of Saudi Arabia (KSA) have announced partnerships to transform the country into a global powerhouse in AI, cloud and enterprise computing, digital twins and robotics. During a state visit today with U.S. President Donald Trump and His Royal Highness Prince Mohammed bin Salman bin Abdulaziz Al Saud, Crown Prince and Prime Minister of Saudi Arabia, NVIDIA founder and CEO Jensen Huang said that the effort will harness sovereign AI infrastructure and expertise to propel Saudi Arabia to the ranks of global hyperscale AI leaders. "AI, like electricity and internet, is essential infrastructure for every nation," Huang said. "Together with HUMAIN, we are building AI infrastructure for the people and companies of Saudi Arabia to realize the bold vision of the Kingdom."

"Our partnership with NVIDIA is a bold step forward in realizing the Kingdom's ambitions to lead in AI and advanced digital infrastructure," said Tareq Amin, CEO of HUMAIN. "Together, we are building the capacity, capability and a new globally enabled community to shape a future powered by intelligent technology and empowered people."

NVIDIA Wins Multiple COMPUTEX Best Choice Awards

NVIDIA today received multiple accolades at COMPUTEX's Best Choice Awards, in recognition of innovation across the company. The NVIDIA GeForce RTX 5090 GPU won the Gaming and Entertainment category award; the NVIDIA Quantum-X Photonics InfiniBand switch system won the Networking and Communication category award; NVIDIA DGX Spark won the Computer and System category award; and the NVIDIA GB200 NVL72 system and NVIDIA Cosmos world foundation model development platform won Golden Awards. The awards recognize the outstanding functionality, innovation and market promise of technologies in each category. Jensen Huang, founder and CEO of NVIDIA, will deliver a keynote at COMPUTEX on Monday, May 19, at 11 a.m. Taiwan time.

GB200 NVL72 and NVIDIA Cosmos Go Gold
NVIDIA GB200 NVL72 and NVIDIA Cosmos each won Golden Awards. The NVIDIA GB200 NVL72 system connects 36 NVIDIA Grace CPUs and 72 NVIDIA Blackwell GPUs in a rack-scale design. It delivers 1.4 exaflops of AI performance and 30 terabytes of fast memory, as well as 30x faster real-time trillion-parameter large language model inference with 25x energy efficiency compared with the NVIDIA H100 GPU. By design, the GB200 NVL72 accelerates the most compute-intensive AI and high-performance computing workloads, including AI training and data processing for engineering design and simulation. NVIDIA Cosmos accelerates physical AI development by enabling developers to build and deploy world foundation models with unprecedented speed and scale.

MSI Teases EdgeXpert MS-C931 - an NVIDIA DGX Spark-based Desktop AI Supercomputer

MSI IPC, a global leader in industrial computing and AI-driven solutions, is set to unveil its latest innovations at COMPUTEX 2025, held from May 20 to 23 at the Taipei Nangang Exhibition Center. Visitors can explore MSI IPC's cutting-edge technologies at Booth J0506, Hall 1, 1F.

Introducing the EdgeXpert MS-C931: A Desktop AI Supercomputer
MSI IPC will unveil the EdgeXpert MS-C931, a desktop AI supercomputer built on the NVIDIA DGX Spark platform. Powered by the NVIDIA GB10 Grace Blackwell Superchip, the EdgeXpert MS-C931 delivers 1,000 AI TOPS FP4 performance, equipped with high-speed ConnectX 7 networking, 128 GB unified memory, and support for large language models. Designed for AI developers and researchers, it is ideal for applications in education, finance, and healthcare industries.

ASUS Introduces a New Class of NVIDIA-powered Desktop AI Supercomputers

They say that the most difficult part of transportation planning is last-mile delivery. A network of warehouses and trucks can bring products within a mile of almost all customers, but logistical challenges and costs add up quickly in the process of delivering those goods to the right doors at the right time. There's a similar pattern in the AI space. Massive data center installations have empowered astonishing cloud-based AI services, but many researchers, developers, and data scientists need the power of an AI supercomputer to travel that last mile. They need machines that offer the convenience and space-saving design of a desktop PC, but go well above and beyond the capabilities of consumer-grade hardware, especially when it comes to available GPU memory.

Enter a new class of AI desktop supercomputers, powered by ASUS and NVIDIA. The upcoming ASUS AI supercomputer lineup, spearheaded by the ASUS ExpertCenter Pro ET900N G3 desktop PC and ASUS Ascent GX10 mini-PC, wield the latest NVIDIA Grace Blackwell superchips to deliver astounding performance in AI workflows. For those who need local, private supercomputing resources, but for whom a data center or rack server installation isn't feasible, these systems provide a transformative opportunity to seize the capabilities of AI.

GIGABYTE to Present End-to-End AI Portfolio at COMPUTEX 2025

GIGABYTE Technology, a global leader in computing innovation, will return to COMPUTEX 2025 from May 20 to 23 under the theme "Omnipresence of Computing: AI Forward." Demonstrating how GIGABYTE's complete spectrum of solutions spanning the AI lifecycle, from data center training to edge deployment and end-user applications reshapes the infrastructure to meet the next-gen AI demands.

As generative AI continues to evolve, so do the demands for handling massive token volumes, real-time data streaming, and high-throughput compute environments. GIGABYTE's end-to-end portfolio - ranging from rack-scale infrastructure to servers, cooling systems, embedded platforms, and personal computing—forms the foundation to accelerate AI breakthroughs across industries.

Huawei CloudMatrix 384 System Outperforms NVIDIA GB200 NVL72

Huawei announced its CloudMatrix 384 system super node, which the company touts as its own domestic alternative to NVIDIA's GB200 NVL72 system, with more overall system performance but worse per-chip performance and higher power consumption. While NVIDIA's GB200 NVL72 uses 36 Grace CPUs paired with 72 "Blackwell" GB200 GPUs, the Huawei CloudMatrix 384 system employs 384 Huawei Ascend 910C accelerators to beat NVIDIA's GB200 NVL72 system. It takes roughly five times more Ascend 910C accelerators to deliver nearly twice the GB200 NVL system performance, which is not good on per-accelerator bias, but excellent on per-system level of deployment. SemiAnalysis argues that Huawei is a generation behind in chip performance but ahead of NVIDIA in scale-up system design and deployment.

When you look at individual chips, NVIDIA's GB200 NVL72 clearly outshines Huawei's Ascend 910C, delivering over three times the BF16 performance (2,500 TeraFLOPS vs. 780 TeraFLOPS), more on-chip memory (192 GB vs. 128 GB), and faster bandwidth (8 TB/s vs. 3.2 TB/s). In other words, NVIDIA has the raw power and efficiency advantage at the chip level. But flip the switch to the system level, and Huawei's CloudMatrix CM384 takes the lead. It cranks out 1.7× the overall PetaFLOPS, packs in 3.6× more total HBM capacity, and supports over five times the number of GPUs and the associated bandwidth of NVIDIA's NVL72 cluster. However, that scalability does come with a trade-off, as Huawei's setup draws nearly four times more total power. A single GB200 NVL72 draws 145 kW of power, while a single Huawei CloudMatrix 384 draws ~560 kW. So, NVIDIA is your go-to if you need peak efficiency in a single GPU. If you're building a massive AI supercluster where total throughput and interconnect speed matter most, Huawei's solution actually makes a lot of sense. Thanks to its all-to-all topology, Huawei has delivered an AI training and inference system worth purchasing. When SMIC, the maker of Huawei's chips, gets to a more advanced manufacturing node, the efficiency of these systems will also increase.

Thousands of NVIDIA Grace Blackwell GPUs Now Live at CoreWeave

CoreWeave today became one of the first cloud providers to bring NVIDIA GB200 NVL72 systems online for customers at scale, and AI frontier companies Cohere, IBM and Mistral AI are already using them to train and deploy next-generation AI models and applications. CoreWeave, the first cloud provider to make NVIDIA Grace Blackwell generally available, has already shown incredible results in MLPerf benchmarks with NVIDIA GB200 NVL72 - a powerful rack-scale accelerated computing platform designed for reasoning and AI agents. Now, CoreWeave customers are gaining access to thousands of NVIDIA Blackwell GPUs.

"We work closely with NVIDIA to quickly deliver to customers the latest and most powerful solutions for training AI models and serving inference," said Mike Intrator, CEO of CoreWeave. "With new Grace Blackwell rack-scale systems in hand, many of our customers will be the first to see the benefits and performance of AI innovators operating at scale."

Quantum Machines Anticipates Collaborative Breakthroughs at NVIDIA's New Research Center

Quantum Machines (QM), a leading provider of advanced quantum control solutions, today announced its intention to work with NVIDIA at its newly established NVIDIA Accelerated Quantum Research Center (NVAQC), unveiled at the GTC global AI conference. The Boston-based center aims to advance quantum computing research with accelerated computing, including integrating quantum processors with AI- supercomputing to overcome significant challenges in the quantum computing space. As quantum computing rapidly evolves, the integration of quantum processors with powerful AI supercomputers becomes increasingly essential. These accelerated quantum supercomputers are pivotal for advancing quantum error correction, device control, and algorithm development.

Quantum Machines joins other quantum computing pioneers, including Quantinuum and QuEra, along with academic partners from Harvard and MIT, in working with NVIDIA at the NVAQC to develop pioneering research. Quantum Machines will work with NVIDIA to integrate its NVIDIA GB200 Grace Blackwell Superchips with QM's advanced quantum control technologies, including the OPX1000. This integration will facilitate rapid, high-bandwidth communication between quantum processors and classical supercomputers. QM and NVIDIA thereby lay the essential foundations for quantum error correction and robust quantum algorithm execution. By reducing latency and enhancing processing efficiency, QM and NVIDIA solutions will significantly accelerate practical applications of quantum computing.

Supermicro Adds Portfolio for Next Wave of AI with NVIDIA Blackwell Ultra Solutions

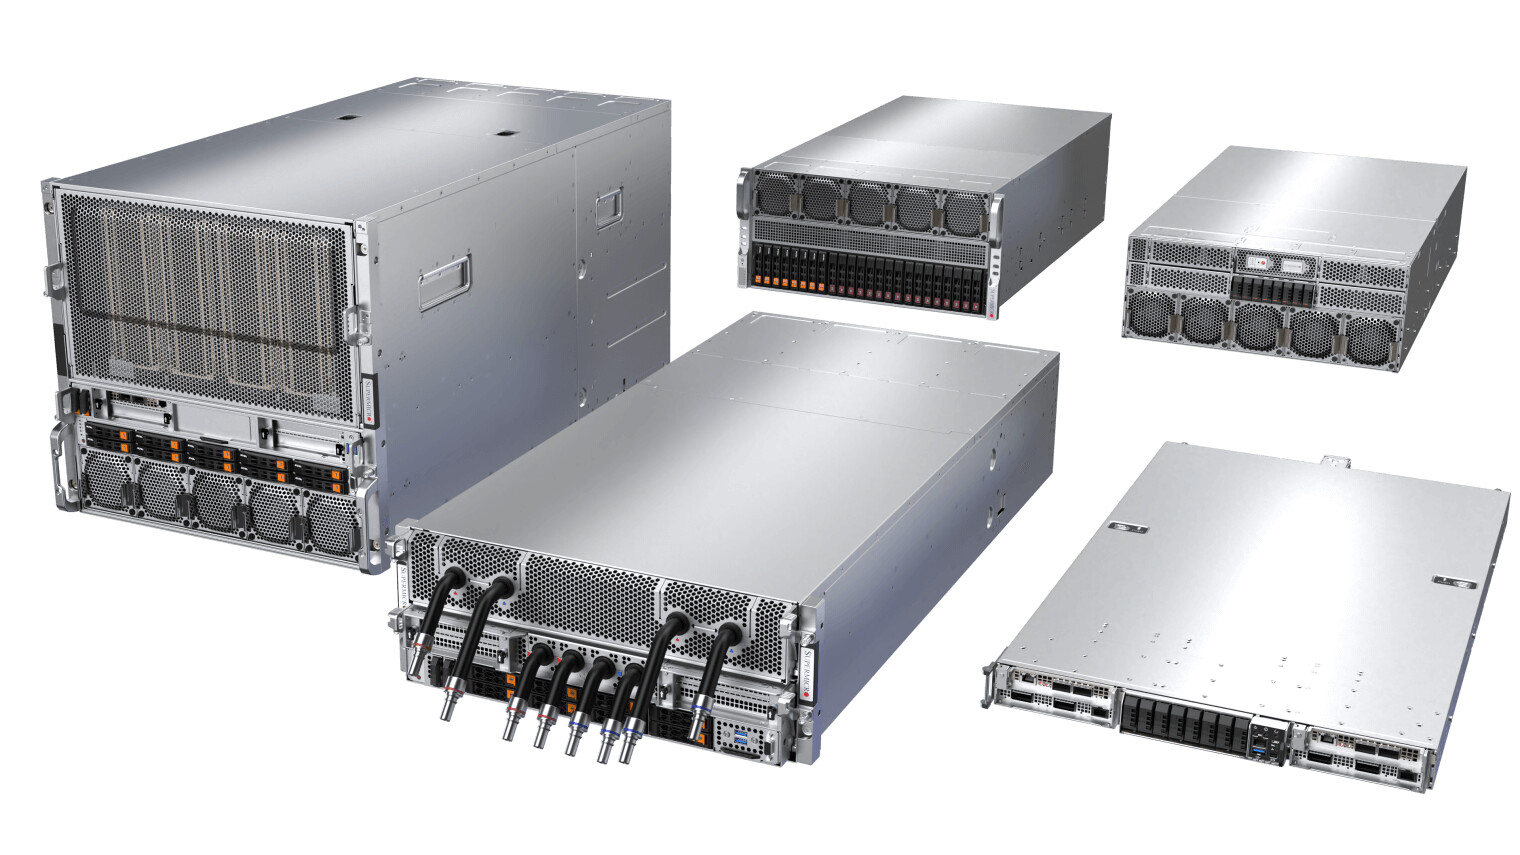
Supermicro, Inc., a Total IT Solution Provider for AI, Cloud, Storage, and 5G/Edge, is announcing new systems and rack solutions powered by the NVIDIA's Blackwell Ultra platform, featuring the NVIDIA HGX B300 NVL16 and NVIDIA GB300 NVL72 platforms. Supermicro and NVIDIA's new AI solutions strengthen leadership in AI by delivering breakthrough performance for the most compute-intensive AI workloads, including AI reasoning, agentic AI, and video inference applications.

"At Supermicro, we are excited to continue our long-standing partnership with NVIDIA to bring the latest AI technology to market with the NVIDIA Blackwell Ultra Platforms," said Charles Liang, president and CEO, Supermicro. "Our Data Center Building Block Solutions approach has streamlined the development of new air and liquid-cooled systems, optimized to the thermals and internal topology of the NVIDIA HGX B300 NVL16 and GB300 NVL72. Our advanced liquid-cooling solution delivers exceptional thermal efficiency, operating with 40℃ warm water in our 8-node rack configuration, or 35℃ warm water in double-density 16-node rack configuration, leveraging our latest CDUs. This innovative solution reduces power consumption by up to 40% while conserving water resources, providing both environmental and operational cost benefits for enterprise data centers."

Lenovo Announces Hybrid AI Advantage with NVIDIA Blackwell Support

Today, at NVIDIA GTC, Lenovo unveiled new Lenovo Hybrid AI Advantage with NVIDIA solutions designed to accelerate AI adoption and boost business productivity by fast-tracking agentic AI that can reason, plan and take action to reach goals faster. The validated, full-stack AI solutions enable enterprises to quickly build and deploy AI agents for a broad range of high-demand use cases, increasing productivity, agility and trust while accelerating the next wave of AI reasoning for the new era of agentic AI.

New global IDC research commissioned by Lenovo reveals that ROI remains the greatest AI adoption barrier, despite a three-fold spend increase. AI agents are revolutionizing enterprise workflows and lowering barriers to ROI by supporting employees with complex problem-solving, coding, and multistep planning that drives speed, innovation and productivity. As CIOs and business leaders seek tangible return on AI investment, Lenovo is delivering hybrid AI solutions that unleash and customize agentic AI at every scale.

Giga Computing Showcases Rack Scale Solutions at NVIDIA GTC 2025

Giga Computing, a subsidiary of GIGABYTE and an industry leader in generative AI servers and advanced cooling technologies, today announced participation at NVIDIA GTC 2025 to bring to the market the best in GPU-based solutions for generative AI, media acceleration, and large language models (LLM). To this end, GIGABYTE booth #1409 at NVIDIA GTC showcases a rack-scale turnkey AI solution, GIGAPOD, that offers both air and liquid-cooling designs for the NVIDIA HGX B300 NVL16 system. Also, on display at the booth is a compute node from the newly announced NVIDIA GB300 NVL72 rack-scale solution. And for modularized compute architecture are two servers supporting the newly announced NVIDIA RTX PRO 6000 Blackwell Server Edition.

Complete AI solution - GIGAPOD
With the depth of expertise in hardware and system design, Giga Computing has combined infrastructure hardware, platform software, and architecting service to deliver scalable units composed of GIGABYTE GPU servers with NVIDIA GPU baseboards, while running GIGABYTE POD Manager, a powerful software suite designed to enhance operational efficiency, streamline management, and optimize resource utilization. GIGAPOD's scalable unit is designed for either nine air-cooled racks or five liquid-cooled racks. Giga Computing offers two approaches for the same goal, one powerful GPU cluster using NVIDIA HGX Hopper and Blackwell GPU platforms at scale to meet demand for all AI data centers.

ASUS Introduces Ascent GX10 AI Supercomputer Powered by NVIDIA GB10 Grace Blackwell Superchip

ASUS today announces its groundbreaking AI supercomputer, ASUS Ascent GX10, powered by the state-of-the-art NVIDIA GB10 Grace Blackwell Superchip. This revolutionary device places the formidable capabilities of a petaFLOP-scale AI supercomputer directly onto the desks of developers, AI researchers and data scientists around the globe.

As the size and complexity of generative AI models grow, local development efforts face increasing challenges. Prototyping, tuning and inferencing large models require substantial memory and compute performance. To address these needs, Ascent GX10 is designed to provide developers with a powerful, economical desktop solution for AI development.

NVIDIA to Consume 77% of Silicon Wafers Dedicated to AI Accelerators in 2025

Investment bank Morgan Stanley has estimated that an astonishing 77% of all globally produced silicon wafers dedicated to AI accelerators will be consumed by none other than NVIDIA. Often, investment research by large investment banks like Morgan Stanley includes information from the semiconductor supply chain, which is constantly expanding to meet NVIDIA's demands. When looking at wafer volume for AI accelerators, it is estimated that in 2024, NVIDIA captured nearly 51% of wafer consumption for its chips, more than half of all demand. With NVIDIA's volume projected to grow to 77%, this represents more than a 50% year-over-year increase, which is incredible for a company of NVIDIA's size. Right now, NVIDIA is phasing out its H100 accelerators in favor of Blackwell 100/200 and the upcoming 300 series of GPUs paired with Grace CPUs.

NVIDIA is accelerating its product deployment timeline and investing a lot in its internal research and development. Morgan Stanley also projects that NVIDIA will invest almost $16 billion in its R&D budget, enough to endure four to five years of development cycles running three design teams sequentially and still delivering new products on an 18-24 month cadence. The scale of this efficiency and development rivals everyone else in the industry. With all this praise, NVIDIA's Q4 revenue report is coming in exactly a week on February 26, so we have to see what its CEO, Jensen Huang, will deliver and show some estimates for the coming months.

NVIDIA GB300 "Blackwell Ultra" Will Feature 288 GB HBM3E Memory, 1400 W TDP

NVIDIA "Blackwell" series is barely out with B100, B200, and GB200 chips shipping to OEMs and hyperscalers, but the company is already setting in its upgraded "Blackwell Ultra" plans with its upcoming GB300 AI server. According to UDN, the next generation NVIDIA system will be powered by the B300 GPU chip, operating at 1400 W and delivering a remarkable 1.5x improvement in FP4 performance per card compared to its B200 predecessor. One of the most notable upgrades is the memory configuration, with each GPU now sporting 288 GB of HBM3e memory, a substantial increase from the previous 192 GB of GB200. The new design implements a 12-layer stack architecture, advancing from the GB200's 8-layer configuration. The system's cooling infrastructure has been completely reimagined, incorporating advanced water cooling plates and enhanced quick disconnects in the liquid cooling system.

Networking capabilities have also seen a substantial upgrade, with the implementation of ConnectX 8 network cards replacing the previous ConnectX 7 generation, while optical modules have been upgraded from 800G to 1.6T, ensuring faster data transmission. Regarding power management and reliability, the GB300 NVL72 cabinet will standardize capacitor tray implementation, with an optional Battery Backup Unit (BBU) system. Each BBU module costs approximately $300 to manufacture, with a complete GB300 system's BBU configuration totaling around $1,500. The system's supercapacitor requirements are equally substantial, with each NVL72 rack requiring over 300 units, priced between $20-25 per unit during production due to its high-power nature. The GB300, carrying Grace CPU and Blackwell Ultra GPU, also introduces the implementation of LPCAMM on its computing boards, indicating that the LPCAMM memory standard is about to take over servers, not just laptops and desktops. We have to wait for the official launch before seeing LPCAMM memory configurations.
Return to Keyword Browsing
Nov 11th, 2026 04:07 CST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts