News Posts matching #InfiniBand

Return to Keyword Browsing

Dell Introduces PowerEdge XE8812 Server with NVIDIA Vera Rubin NVL4 Architecture

Dell Technologies (NYSE: DELL) introduces the Dell PowerEdge XE8812 server, a new addition to the Dell AI Factory with NVIDIA, purpose-built for the world's most demanding HPC and AI workloads, featuring NVIDIA Vera Rubin NVL4 architecture and delivering up to 144 GPUs per rack. The announcement comes as Dell AI Factory deployments accelerate worldwide, advancing sovereign AI initiatives, engineering and design workflows, and genomic science.

Why it matters
As AI and HPC simulation workloads converge, the scale and pace of these workloads are outgrowing what incremental infrastructure upgrades can keep up with. At the same time, organizations are pushing the boundaries of science and industry, resulting in a need for platforms that deliver a generational leap.

Giga Computing Shows Data Center Portfolio and Infrastructure at NVIDIA GTC 2026 Including New NVIDIA Rubin Platforms

Giga Computing, a subsidiary of GIGABYTE and a leader in accelerated computing and infrastructure solutions, today announced new enterprise AI solutions that support NVIDIA Vera CPU and NVIDIA Vera Rubin platform, well as a new AI factory in Taiwan. The GIGABYTE booth at NVIDIA GTC shows scalable AI solutions that not only focus on performance and efficiency but also incorporate the software and infrastructure needed to build AI factories and other large GPU clusters. The GIGABYTE booth staff is ready to introduce the latest hardware and software for success in deploying accelerated computing.

Personal AI Supercomputers
With products spanning all segments of the supercomputer space, Giga Computing showcases professional desktop and deskside solutions that are ideal for AI development and accelerating AI training and inference workloads. These solutions are being used by data scientists and researchers in research institutions, government agencies, and enterprises.

GIGABYTE Powers Telecom AI Transformation with End-to-End Infrastructure at MWC 2026

GIGABYTE Technology, a global leader known for its engineering excellence in high-performance computing and AI servers, extends its comprehensive end-to-end AI infrastructure portfolio designed specifically for the telecommunications industry at MWC 2026. GIGABYTE's end-to-end product solutions enable operators to convert massive volumes of network data into intelligence, automation, and new revenue streams, as telecommunications networks evolve from data carriers into AI-powered digital platforms.

At the core of the telco-to-AI transformation is the AI Factory, where network and subscriber data are converted into operational intelligence and commercialized AI services. GIGABYTE addresses this need with GB300 NVL72, a liquid-cooled rack-scale platform integrating 72 NVIDIA Blackwell Ultra GPUs and 36 NVIDIA Grace CPUs in a single system. Connected via NVIDIA Quantum-X800 InfiniBand or NVIDIA Spectrum-X Ethernet and NVIDIA ConnectX -8 SuperNIC s, GB300 NVL72 is optimized for large-scale AI training and inference workloads, enabling operators to automate operations, optimize network planning, and deploy AI-driven services at telecom scale.

NVIDIA H100 GPU Cluster on CoreWeave AI Cloud Platform Breaks Graph500 Run Record

The world's top-performing system for graph processing at scale was built on a commercially available cluster. NVIDIA last month announced a record-breaking benchmark result of 410 trillion traversed edges per second (TEPS), ranking No. 1 on the 31st Graph500 breadth-first search (BFS) list. Performed on an accelerated computing cluster hosted in a CoreWeave data center in Dallas, the winning run used 8,192 NVIDIA H100 GPUs to process a graph with 2.2 trillion vertices and 35 trillion edges. This result is more than double the performance of comparable solutions on the list, including those hosted in national labs.

To put this performance in perspective, say every person on Earth has 150 friends. This would represent 1.2 trillion edges in a graph of social relationships. The level of performance recently achieved by NVIDIA and CoreWeave enables searching through every friend relationship on Earth in just about three milliseconds. Speed at that scale is half the story—the real breakthrough is efficiency. A comparable entry in the top 10 runs of the Graph500 list used about 9,000 nodes, while the winning run from NVIDIA used just over 1,000 nodes, delivering 3x better performance per dollar.

Supermicro Intros New 4U and 2-OU (OCP) Liquid-Cooled NVIDIA Blackwell HGX B300 Systems

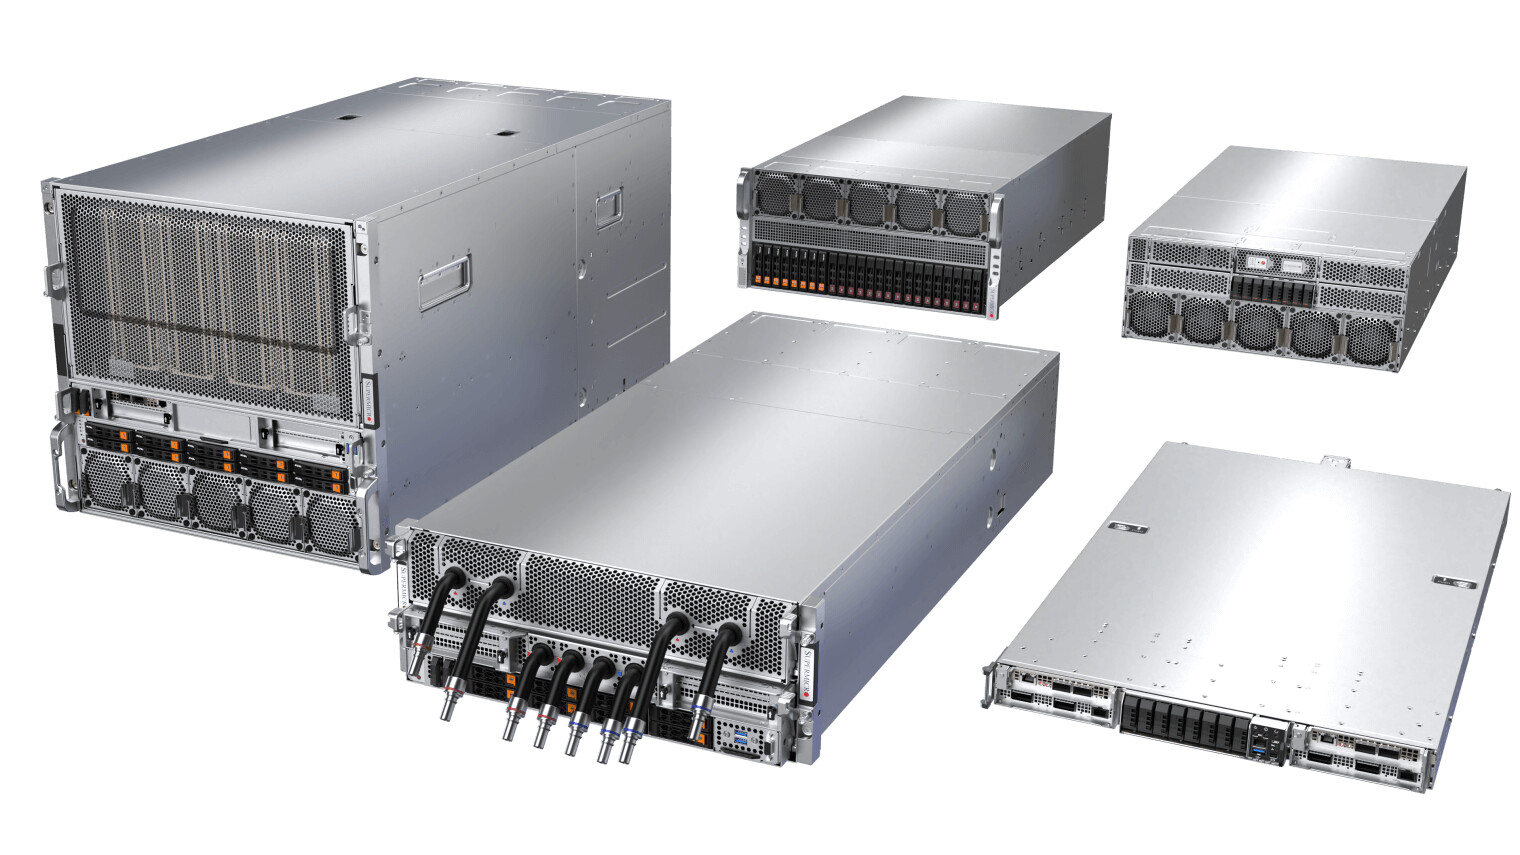
Super Micro Computer, Inc. (SMCI), a Total IT Solution Provider for AI, Cloud, Storage, and 5G/Edge, today announced the expansion of its NVIDIA Blackwell architecture portfolio with the introduction and shipment availability of new 4U and 2-OU (OCP) liquid-cooled NVIDIA HGX B300 systems. These latest additions are a key part of Supermicro's Data Center Building Block Solutions (DCBBS) that deliver unprecedented GPU density and power efficiency for hyperscale data centers and AI factory deployments.

"With AI infrastructure demand accelerating globally, our new liquid-cooled NVIDIA HGX B300 systems deliver the performance density and energy efficiency that hyperscalers and AI factories need today," said Charles Liang, president and CEO of Supermicro. "We're now offering the industry's most compact NVIDIA HGX B300 solutions—achieving up to 144 GPUs in a single rack—while reducing power consumption and cooling costs through our proven direct liquid-cooling technology. Through our DCBBS, this is how Supermicro enables our customers to deploy AI at scale: faster time-to market, maximum performance per watt, and end-to-end integration from design to deployment."

TOP500: El Capitan Retains #1 as JUPITER Becomes Europe's First Exascale System

The 66th edition of the TOP500 list of the world's most powerful supercomputers was announced today at the SC25 Conference in St Louis, Missouri. The new list reflects continued U.S. leadership in high-performance computing (HPC), historic European milestones, and growing global diversity across architectures and energy-efficient design.

El Capitan Extends Leadership Across Benchmarks
The El Capitan system at Lawrence Livermore National Laboratory (LLNL) remains the undisputed leader of global HPC. Based on the HPE Cray EX255a architecture, powered by AMD 4th Gen EPYC CPUs and AMD Instinct MI300A accelerators, El Capitan achieved 1.809 Exaflop/s on the HPL benchmark—a significant remeasurement that further strengthens its position as the fastest computer in the world. El Capitan also dominates the HPCG benchmark, delivering 17.41 HPCG-Petaflop/s, making it the #1 for real-world application performance. On the HPL-MxP mixed-precision benchmark, it recorded 16.7 Exaflop/s, confirming its versatility in AI and data-driven workloads. With 11.34 million cores and an energy efficiency of 60.9 GFlops/Watt, El Capitan exemplifies the current generation of exascale computing.

ASUS Showcases NVIDIA GB300 NVL72 at SC25

ASUS announced a showcase of its comprehensive AI infrastructure portfolio accelerated by NVIDIA Blackwell and Blackwell Ultra architectures at Supercomputing 2025 (SC25). Driven by the strategy of 'Ubiquitous AI. Incredible Possibilities.', ASUS infrastructure goes all in AI strategy, aiming to accelerate clients' time to market with superior computing performance. ASUS stands as a total infrastructure solution provider, offering robust, scalable, cloud and on-premise solutions for diverse AI workloads. This is achieved through the seamless integration of the latest NVIDIA compute platforms with advanced cooling, network orchestration, and large-scale deployment capabilities. By providing a full spectrum of AI solutions, from personal workstations to national supercomputing systems, ASUS is committed to democratizing access to powerful AI technologies for everyone.

Rack-scale AI infrastructure with NVIDIA GB300 NVL72
At the top of the portfolio, the XA GB721-E2, ASUS AI POD built on NVIDIA GB300 NVL72, embodies a field-proven rack-scale AI architecture, accelerated by 72 NVIDIA Blackwell Ultra GPUs and 36 NVIDIA Grace CPUs. Combining a 100% liquid-cooling system with integrated switch trays, the system delivers deployment-ready scalability and energy-efficient performance, offering 10-petaflops-class computing power for enterprise AI and national-cloud workloads.

HPE Unveils Newest Additions to Its Next-Generation Cray Supercomputing Portfolio

HPE (NYSE:HPE) today announces the newest additions to the next-generation HPE Cray supercomputing portfolio that provide industry-leading compute density, designed to meet the needs of artificial intelligence (AI) demands while performing at-scale. This HPE Cray Supercomputing portfolio expansion includes three multipartner, multi-workload compute blades, unified management software and high-performance interconnect support, establishing one of the most powerful supercomputing architectures in the industry for research laboratories, sovereign entities and large enterprises that are increasingly turning to AI to advance their simulations and drive scientific discovery.

"Global organizations relying on supercomputing are looking for better computing performance for all of their workloads," said Trish Damkroger, senior vice president and general manager, HPC and AI Infrastructure Solutions at HPE. "Our new HPE Cray Supercomputing platform is the answer to customers' needs for higher performance density with a unified AI and HPC architecture that is engineered for groundbreaking outcomes. HPE is proud to share our unwavering commitment to AI and supercomputing as the engine of innovation and scientific discovery, advancing the way people live and work."

HPE to Build "Mission" and "Vision" Supercomputers Featuring NVIDIA Vera Rubin

HPE today announced, in partnership with the U.S. Department of Energy (DOE), National Nuclear Security Administration (NNSA) and Los Alamos National Laboratory (LANL), that it has been selected to deliver two state-of-the-art supercomputers, named "Mission" and "Vision". The next-generation systems will be based on the new direct liquid-cooled HPE Cray Supercomputing GX5000 system and feature upcoming NVIDIA Vera Rubin Superchips. Mission and Vision are part of the DOE's $370 million investment to accelerate scientific discovery, advance AI initiatives and strengthen national security.

"For decades, HPE and Los Alamos National Laboratory have collaborated on innovative supercomputing designs that deliver powerful capabilities to solve complex scientific challenges and bolster national security efforts," said Trish Damkroger, senior vice president and general manager, HPC & AI Infrastructure Solutions at HPE. "We are proud to continue powering the lab's journey with the upcoming Mission and Vision systems. These innovations will be among the first to feature next-generation HPE Cray supercomputing architecture to drive AI innovation and scientific impact."

NVIDIA to Build Seven New AI Supercomputers for U.S. Government

NVIDIA today announced that it is working with the U.S. Department of Energy's national labs and the nation's leading companies to build America's AI infrastructure to support scientific discovery, economic growth and power the next industrial revolution.

"We are at the dawn of the AI industrial revolution that will define the future of every industry and nation," said Jensen Huang, founder and CEO of NVIDIA. "It is imperative that America lead the race to the future—this is our generation's Apollo moment. The next wave of inventions, discoveries and progress will be determined by our nation's ability to scale AI infrastructure. Together with our partners, we are building the most advanced AI infrastructure ever created, ensuring that America has the foundation for a prosperous future, and that the world's AI runs on American innovation, openness and collaboration, for the benefit of all."

ASUS Launches XA NB3I-E12 AI Server Built with NVIDIA HGX B300

ASUS today announced the shipment of the XA NB3I-E12 AI server, built on the NVIDIA HGX B300 platform. Delivering next-generation AI performance and reliability, XA NB3I-E12 gives enterprises and cloud-service providers (CSPs) early access to cutting-edge computing capabilities for the AI era. Accelerated by eight NVIDIA Blackwell Ultra GPUs and dual Intel Xeon 6 Scalable processors, ASUS XA NB3I-E12 is engineered for intensive AI workloads. With eight NVIDIA ConnectX-8 InfiniBand SuperNICs, five PCIe expansion slots, 32 DIMMs, 10 NVMe drives, and dual 10 Gb LAN, it transforms data into intelligence for real-world automation. The system is ideal for enterprises and CSPs running large language models (LLMs), research institutions and universities performing scientific computing, and the financial and automotive sectors focused on AI model training and inference.

Microsoft Azure Unveils World's First NVIDIA GB300 NVL72 Supercomputing Cluster for OpenAI

Microsoft Azure today announced the new NDv6 GB300 VM series, delivering the industry's first supercomputing-scale production cluster of NVIDIA GB300 NVL72 systems, purpose-built for OpenAI's most demanding AI inference workloads. This supercomputer-scale cluster features over 4,600 NVIDIA Blackwell Ultra GPUs connected via the NVIDIA Quantum-X800 InfiniBand networking platform. Microsoft's unique systems approach applied radical engineering to memory and networking to provide the massive scale of compute required to achieve high inference and training throughput for reasoning models and agentic AI systems.

Today's achievement is the result of years of deep partnership between NVIDIA and Microsoft purpose-building AI infrastructure for the world's most demanding AI workloads and to deliver infrastructure for the next frontier of AI. It marks another leadership moment, ensuring that leading-edge AI drives innovation in the United States.

Giga Computing Launches NVIDIA HGX B300-Powered Flagship Server

Giga Computing, a subsidiary of GIGABYTE Group and a pioneer in generative AI and high-performance computing (HPC) servers, today announced the launch of its new flagship server, GIGABYTE G894-SD3-AAX7. This 8U dual-processor platform supports NVIDIA HGX B300 and is designed to accelerate AI training, inference, and complex HPC workloads, delivering unparalleled performance and scalability.

Leading-Edge AI Reasoning and High-Performance Computing Platform
The G894-SD3-AAX7 combines the latest hardware innovations in a compact 8U, air-cooled chassis, maximizing both system performance and expansion capabilities:
  • NVIDIA HGX B300 Support: The 8-GPU HGX B300 platform integrates 8x NVIDIA Blackwell Ultra GPUs with NVIDIA NVLink and NVLink Switch to deliver 1.8 TB/s GPU-GPU bandwidth and 14.4 TB/s total bandwidth for scalable AI performance.
  • Powerful Processor Configuration: Dual Intel Xeon 6700/6500 series processors with 32 DDR5 DIMM slots, delivering robust compute for next-generation AI training and HPC applications.
  • Ultra-High-Speed Networking: Equipped with 8x 800 Gb/s OSFP InfiniBand or 16x 400 Gb/s Ethernet ports via NVIDIA ConnectX-8 SuperNICs, enabling high-throughput performance for large-scale data center workloads.

Giga Computing Expands NVIDIA RTX PRO Server Portfolio

Giga Computing, a subsidiary of GIGABYTE Group, today announced the availability of the XL44-SX2-AAS1 server, integrating NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs with the NVIDIA BlueField-3 DPU and NVIDIA ConnectX-8 SuperNICs, this breakthrough platform unifies computing and high-speed data transfer to empower the next generation of enterprise AI.

Breakthrough in Compute and Networking Integration
The XL44-SX2-AAS1 is an NVIDIA RTX PRO Server, combining the NVIDIA Blackwell architecture with the new NVIDIA ConnectX-8 SuperNIC Switch Boards to deliver unprecedented AI performance and interconnect:
  • Extreme AI Acceleration: The XL44-SX2-AAS1 is a high-density, high-performance server built on the NVIDIA MGX modular reference design. The system is accelerated by up to eight NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs, each featuring 96 GB of GDDR7 memory, enabling generative AI, 3D rendering, and scientific simulations.

Supermicro Expands Its NVIDIA Blackwell System Portfolio with New Liquid-Cooled and Air-Cooled Systems

Supermicro, Inc., a Total IT Solution Provider for AI, HPC, Cloud, Storage, and 5G/Edge, today announced the expansion of its NVIDIA Blackwell system portfolio with the new 4U DLC-2 liquid-cooled NVIDIA HGX B200 system ready for volume shipment and the introduction of an air-cooled 8U front I/O system. Tailored to the most demanding large-scale AI training and cloud-scale inference workloads, Supermicro's new systems streamline the deployment, management, and maintenance of air- or liquid-cooled AI infrastructure and are designed to support coming NVIDIA HGX B300 platforms, allowing easy front I/O access, simplifying cabling, improving thermal efficiency and compute density, and reducing operational expenses (OPEX).

"Supermicro's DLC-2 enabled NVIDIA HGX B200 system leads our portfolio to achieve greater power savings and faster time to online for AI Factory deployments," said Charles Liang, CEO and president, Supermicro. "Our Building Block architecture enables us to quickly deliver solutions exactly as our customers request. Supermicro's extensive portfolio now can offer precisely optimized NVIDIA Blackwell solutions to a diverse range of AI infrastructure environments, whether deploying into an air- or liquid-cooled facility."

NVIDIA Blackwell Delivers Breakthrough Performance in Latest MLPerf Training Results

NVIDIA is working with companies worldwide to build out AI factories—speeding the training and deployment of next-generation AI applications that use the latest advancements in training and inference. The NVIDIA Blackwell architecture is built to meet the heightened performance requirements of these new applications. In the latest round of MLPerf Training—the 12th since the benchmark's introduction in 2018—the NVIDIA AI platform delivered the highest performance at scale on every benchmark and powered every result submitted on the benchmark's toughest large language model (LLM)-focused test: Llama 3.1 405B pretraining.

The NVIDIA platform was the only one that submitted results on every MLPerf Training v5.0 benchmark—underscoring its exceptional performance and versatility across a wide array of AI workloads, spanning LLMs, recommendation systems, multimodal LLMs, object detection and graph neural networks. The at-scale submissions used two AI supercomputers powered by the NVIDIA Blackwell platform: Tyche, built using NVIDIA GB200 NVL72 rack-scale systems, and Nyx, based on NVIDIA DGX B200 systems. In addition, NVIDIA collaborated with CoreWeave and IBM to submit GB200 NVL72 results using a total of 2,496 Blackwell GPUs and 1,248 NVIDIA Grace CPUs.

Doudna Supercomputer Will be Powered by NVIDIA's Next-gen Vera Rubin Platform

Ready for a front-row seat to the next scientific revolution? That's the idea behind Doudna—a groundbreaking supercomputer announced today at Lawrence Berkeley National Laboratory in Berkeley, California. The system represents a major national investment in advancing U.S. high-performance computing (HPC) leadership, ensuring U.S. researchers have access to cutting-edge tools to address global challenges. "It will advance scientific discovery from chemistry to physics to biology and all powered by—unleashing this power—of artificial intelligence," U.S. Energy Secretary Chris Wright (pictured above) said at today's event.

Also known as NERSC-10, Doudna is named for Nobel laureate and CRISPR pioneer Jennifer Doudna. The next-generation system announced today is designed not just for speed but for impact. Powered by Dell Technologies infrastructure with the NVIDIA Vera Rubin architecture, and set to launch in 2026, Doudna is tailored for real-time discovery across the U.S. Department of Energy's most urgent scientific missions. It's poised to catapult American researchers to the forefront of critical scientific breakthroughs, fostering innovation and securing the nation's competitive edge in key technological fields.

NVIDIA & Microsoft Accelerate Agentic AI Innovation - From Cloud to PC

Agentic AI is redefining scientific discovery and unlocking research breakthroughs and innovations across industries. Through deepened collaboration, NVIDIA and Microsoft are delivering advancements that accelerate agentic AI-powered applications from the cloud to the PC. At Microsoft Build, Microsoft unveiled Microsoft Discovery, an extensible platform built to empower researchers to transform the entire discovery process with agentic AI. This will help research and development departments across various industries accelerate the time to market for new products, as well as speed and expand the end-to-end discovery process for all scientists.

Microsoft Discovery will integrate the NVIDIA ALCHEMI NIM microservice, which optimizes AI inference for chemical simulations, to accelerate materials science research with property prediction and candidate recommendation. The platform will also integrate NVIDIA BioNeMo NIM microservices, tapping into pretrained AI workflows to speed up AI model development for drug discovery. These integrations equip researchers with accelerated performance for faster scientific discoveries. In testing, researchers at Microsoft used Microsoft Discovery to detect a novel coolant prototype with promising properties for immersion cooling in data centers in under 200 hours, rather than months or years with traditional methods.

Dell Technologies Unveils Next Generation Enterprise AI Solutions with NVIDIA

The world's top provider of AI-centric infrastructure, Dell Technologies, announces innovations across the Dell AI Factory with NVIDIA - all designed to help enterprises accelerate AI adoption and achieve faster time to value.

Why it matters
As enterprises make AI central to their strategy and progress from experimentation to implementation, their demand for accessible AI skills and technologies grows exponentially. Dell and NVIDIA continue the rapid pace of innovation with updates to the Dell AI Factory with NVIDIA, including robust AI infrastructure, solutions and services that streamline the path to full-scale implementation.

MiTAC Computing Launches the Latest Scale-out AI Server G4527G6 by NVIDIA MGX at Computex 2025

MiTAC Computing Technology Corporation, a leading server platform design, manufacturer, and a subsidiary of MiTAC Holdings Corporation (TSE:3706), will present its latest innovations in AI infrastructure at COMPUTEX 2025. At booth M1110, MiTAC Computing will display its next-level AI server platforms MiTAC G4527G6, fully optimized for NVIDIA MGX architecture, which supports NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs and the NVIDIA H200 NVL platform to address the evolving demands of enterprise AI workloads.

Next-Gen AI with High-Performance Computing
With the increasing adoption of generative AI and accelerated computing, MiTAC Computing introduces the latest NVIDIA MGX-based server solution, the MiTAC G4527G6, designed to support complex AI and high-performance computing (HPC) workloads. Built on Intel Xeon 6 processors, the G4527G6 accommodates up to eight NVIDIA GPUs, 8 TB of DDR5-6400 memory, sixteen hot-swappable E1.s drives, and an NVIDIA BlueField-3 DPU for efficient north-south connectivity. Crucially, it integrates four next-generation NVIDIA ConnectX-8 SuperNICs, delivering up to 800 gigabits per second (Gb/s) of NVIDIA InfiniBand and Ethernet networking—significantly enhancing system performance for AI factories and cloud data center environments.

NVIDIA Discusses the Revenue-Generating Potential of AI Factories

AI is creating value for everyone—from researchers in drug discovery to quantitative analysts navigating financial market changes. The faster an AI system can produce tokens, a unit of data used to string together outputs, the greater its impact. That's why AI factories are key, providing the most efficient path from "time to first token" to "time to first value." AI factories are redefining the economics of modern infrastructure. They produce intelligence by transforming data into valuable outputs—whether tokens, predictions, images, proteins or other forms—at massive scale.

They help enhance three key aspects of the AI journey—data ingestion, model training and high-volume inference. AI factories are being built to generate tokens faster and more accurately, using three critical technology stacks: AI models, accelerated computing infrastructure and enterprise-grade software. Read on to learn how AI factories are helping enterprises and organizations around the world convert the most valuable digital commodity—data—into revenue potential.

NVIDIA Wins Multiple COMPUTEX Best Choice Awards

NVIDIA today received multiple accolades at COMPUTEX's Best Choice Awards, in recognition of innovation across the company. The NVIDIA GeForce RTX 5090 GPU won the Gaming and Entertainment category award; the NVIDIA Quantum-X Photonics InfiniBand switch system won the Networking and Communication category award; NVIDIA DGX Spark won the Computer and System category award; and the NVIDIA GB200 NVL72 system and NVIDIA Cosmos world foundation model development platform won Golden Awards. The awards recognize the outstanding functionality, innovation and market promise of technologies in each category. Jensen Huang, founder and CEO of NVIDIA, will deliver a keynote at COMPUTEX on Monday, May 19, at 11 a.m. Taiwan time.

GB200 NVL72 and NVIDIA Cosmos Go Gold
NVIDIA GB200 NVL72 and NVIDIA Cosmos each won Golden Awards. The NVIDIA GB200 NVL72 system connects 36 NVIDIA Grace CPUs and 72 NVIDIA Blackwell GPUs in a rack-scale design. It delivers 1.4 exaflops of AI performance and 30 terabytes of fast memory, as well as 30x faster real-time trillion-parameter large language model inference with 25x energy efficiency compared with the NVIDIA H100 GPU. By design, the GB200 NVL72 accelerates the most compute-intensive AI and high-performance computing workloads, including AI training and data processing for engineering design and simulation. NVIDIA Cosmos accelerates physical AI development by enabling developers to build and deploy world foundation models with unprecedented speed and scale.

Oracle Cloud Infrastructure Bolstered by Thousands of NVIDIA Blackwell GPUs

Oracle has stood up and optimized its first wave of liquid-cooled NVIDIA GB200 NVL72 racks in its data centers. Thousands of NVIDIA Blackwell GPUs are now being deployed and ready for customer use on NVIDIA DGX Cloud and Oracle Cloud Infrastructure (OCI) to develop and run next-generation reasoning models and AI agents. Oracle's state-of-the-art GB200 deployment includes high-speed NVIDIA Quantum-2 InfiniBand and NVIDIA Spectrum-X Ethernet networking to enable scalable, low-latency performance, as well as a full stack of software and database integrations from NVIDIA and OCI.

OCI, one of the world's largest and fastest-growing cloud service providers, is among the first to deploy NVIDIA GB200 NVL72 systems. The company has ambitious plans to build one of the world's largest Blackwell clusters. OCI Superclusters will scale beyond 100,000 NVIDIA Blackwell GPUs to meet the world's skyrocketing need for inference tokens and accelerated computing. The torrid pace of AI innovation continues as several companies including OpenAI have released new reasoning models in the past few weeks.

Thousands of NVIDIA Grace Blackwell GPUs Now Live at CoreWeave

CoreWeave today became one of the first cloud providers to bring NVIDIA GB200 NVL72 systems online for customers at scale, and AI frontier companies Cohere, IBM and Mistral AI are already using them to train and deploy next-generation AI models and applications. CoreWeave, the first cloud provider to make NVIDIA Grace Blackwell generally available, has already shown incredible results in MLPerf benchmarks with NVIDIA GB200 NVL72 - a powerful rack-scale accelerated computing platform designed for reasoning and AI agents. Now, CoreWeave customers are gaining access to thousands of NVIDIA Blackwell GPUs.

"We work closely with NVIDIA to quickly deliver to customers the latest and most powerful solutions for training AI models and serving inference," said Mike Intrator, CEO of CoreWeave. "With new Grace Blackwell rack-scale systems in hand, many of our customers will be the first to see the benefits and performance of AI innovators operating at scale."

Supermicro Adds Portfolio for Next Wave of AI with NVIDIA Blackwell Ultra Solutions

Supermicro, Inc., a Total IT Solution Provider for AI, Cloud, Storage, and 5G/Edge, is announcing new systems and rack solutions powered by the NVIDIA's Blackwell Ultra platform, featuring the NVIDIA HGX B300 NVL16 and NVIDIA GB300 NVL72 platforms. Supermicro and NVIDIA's new AI solutions strengthen leadership in AI by delivering breakthrough performance for the most compute-intensive AI workloads, including AI reasoning, agentic AI, and video inference applications.

"At Supermicro, we are excited to continue our long-standing partnership with NVIDIA to bring the latest AI technology to market with the NVIDIA Blackwell Ultra Platforms," said Charles Liang, president and CEO, Supermicro. "Our Data Center Building Block Solutions approach has streamlined the development of new air and liquid-cooled systems, optimized to the thermals and internal topology of the NVIDIA HGX B300 NVL16 and GB300 NVL72. Our advanced liquid-cooling solution delivers exceptional thermal efficiency, operating with 40℃ warm water in our 8-node rack configuration, or 35℃ warm water in double-density 16-node rack configuration, leveraging our latest CDUs. This innovative solution reduces power consumption by up to 40% while conserving water resources, providing both environmental and operational cost benefits for enterprise data centers."
Return to Keyword Browsing
Nov 11th, 2026 04:20 CST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts