 40
AMD Ryzen AI Halo Review - Local-AI Powerhouse with 128 GB of Memory
Image Generation »AI Agents
There has been so much hype around "agents," so we tested them of course for this review. But let's explain the term first: an agent is a language model running in a loop with a job to do. Instead of answering one prompt, and then stopping, and waiting for human feedback, it makes a plan, does a step, reads the result, and keeps going until the task is finished—often calling several models or external tools, like to fetch a web page, along the way. It is how the "do it for me" tools work, from coding assistants to research bots. This matters for the Halo because an agent is not just one long answer. It is many short calls, each one re-reading everything so far, which is a very different load than a single chat reply.To test it we built a small agent and gave it a job that is easy to judge: write a fairy tale. Instead of the simple job, which is one model writing the whole story, a planning agent splits it into twelve scenes, a pool of writer agents handles each scene by itself, and an editor agent stitches them together, fourteen model calls in total, all running on the Ryzen AI Halo box. We provide one prompt, and the rest happens automatically.
A simple prompt for the AI agent testa fairy tale that blends Cinderella and Sleeping Beauty, that a young child could follow
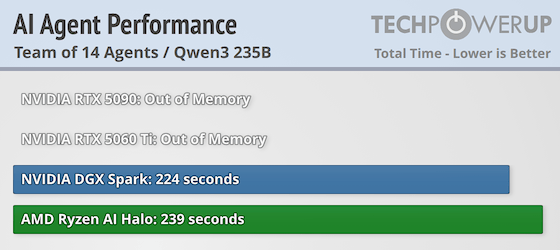
We started benchmarking with the same frontier-size model from the LLM pages, Qwen3-235B. On our two comparison GPUs it did not run at all: both the RTX 5090 and the RTX 5060 Ti died with an out-of-memory error before writing a single word. The Halo and the Spark both run it pretty well, and finish the job in around four minutes.
The obvious answer to "out of memory" on the GPUs is to run a smaller model.
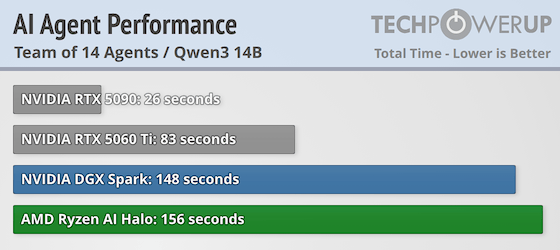
That's why I also tried the 14-billion parameter Qwen3-14B, which fits both cards. It is fast, too, the RTX 5090 powered through the same writing task in just 26 seconds, much faster than the Ryzen AI Halo and DGX Spark.
But, especially for an agent, speed certainly is not the first thing you should consider as a primary metric. It's far more important to get things right, and that's where the results separate pretty cleanly.
Output Quality
We gave both models the same (intentionally) short one-line prompt. This makes it easy for all of us to judge the writing, because we all know the stories.14B ModelShe slipped out the back door and ran into the cool night. The stars shone above her, lighting her way. She reached the village and found a small shop with soft lights glowing inside. There, she met a kind prince who smiled at her and offered her a warm, magical glass slipper.Not bad, but there's not much scene-setting, so the mental picture you build as you read never amounts to much, and it doesn't really come to life. I also noticed that the AI really liked to use a lot of "she," "she," "she."
235B ModelThe grand hall glittered with lights. Lila stepped inside, her blue dress shimmering like the night sky. Heads turned... the prince asked her to dance. They twirled, laughing as they moved. Then, far away, a clock began to chime. Midnight! Lila's heart pounded. She broke free and ran, leaving behind a single glass slipper.With the 235B model things are different. You read it and immediately visualize the scene, and it clicks for you. The writing style is MUCH better, too. These differences run through the whole story. The 14B completely forgot one important event: the pricked finger that causes the sleep, so its heroine simply turns up asleep in a glass coffin for no reason. It even tells the scene of the prince finding her two times—almost word for word. The 235B on the other hand wrote nice, varied sentences that read like a story someone wrote on purpose.
Both models obviously know Cinderella and Sleeping Beauty, but only the bigger one was able to fold them together into a single story a child would be interested in, and that model will not run on any non-enterprise GPU; only the Ryzen AI Halo (and DGX Spark) can tackle it.
But the Cloud
The obvious question here is what about cloud-based models like ChatGPT and Claude? That's why I built a test using Anthropic's Claude Fable, one of their best models. Just to confirm, this was an apples-to-apples comparison, not a single easy prompt: the same planner, the same twelve blind writers, the same stitching agent, each writer seeing only the outline and the story so far, exactly as on the offline Ryzen AI Halo.Claude FableIn a kingdom where the snow never quite melted, there lived a girl named Ella who slept each night in the warm gray cinders by the hearth, because it was the only corner her stepmother had not taken from her.Wow. The results are impressive, and it really wove Cinderella and Sleeping Beauty into a single plot and touched on small details it had planted several scenes earlier, like birds that the girl feeds at the start, which return at the end to lead the prince through the thorns.
On the night of the royal ball, an old spinning wheel in the attic turned all by itself and spun her a gown out of the ashes, and a pair of slippers so clear they looked like two cupfuls of winter air.
"Be home before the clock finishes midnight," the spinning wheel whispered, "for the last stroke is the hour the sleeping falls."
Ella danced until the eleventh chime. And the prince, who had never once seen a girl laugh at the cinders still caught in her hair, forgot to let go of her hand - so that when the twelfth bell rang, they both fell asleep mid-step, and the whole glittering ballroom with them, for a hundred years and a day.
There's no sugar-coating this, and I think we can all agree here: the cloud frontier is still ahead of anything you can run at home. What the Ryzen AI Halo gives you is a capable model that you control, running offline and private, without sharing any info to AI companies, on hardware that you paid for once, without any subscription.
Nov 13th, 2026 21:36 CST
change timezone
Latest GPU Drivers
New Forum Posts
- Tell me about your favourite graphics card (26)
- Crimson Desert (31)
- RenoDX HDR - how to view the differnce Before&After in game? (0)
- Displayport DP80 3M (10ft) cable that can achieve 80gbps stable? (5)
- I'll flash a ASUS ROG Strix RX480 O8G in Cause of Code 43, as a Newbie (1)
- Opinion on Monitor Replacement (6)
- TMOG - post your benchmark results here (16)
- no "PhysX" workable (7)
- Microsoft Exchange/365 outages? (61)
- Unallocated space in ssd , is it normal? (18)
Popular Reviews
- AMD Zen 6 Technical Deep Dive
- Corsair HX1000i Shift Crystal Review
- NZXT C1200 Platinum Review
- Upcoming Hardware Launches 2027 (Updated Nov 2026)
- ASUS ROG Strix B850-I Gaming Wi-Fi7 W Review
- Montech King 95 3D PRO Review
- NZXT H7 RGB+ Review
- NZXT H5 Review
- Phantom Blade Zero Performance Benchmark Review - 35 GPUs Tested
- XPG NIMBUS PLUS Review - Mid-range Chair With Strong Competitors
TPU on YouTube
Controversial News Posts
- NVIDIA Co-Founder and CEO Jensen Huang Officially Resigns (379)
- OpenAI CEO Argues Home PCs Waste the World's Limited DRAM Supply (152)
- NVIDIA Launches Investigation Into Jensen Huang's Relationship With Suspected Chinese Spy (136)
- Intel "Raptor Lake Next" 16-Core and 20-Core CPUs Surface (130)
- Legendary Game Studio BioWare Shuts Down Following EA Layoffs (104)
- Dell CEO Says the Memory Shortage Will Get Worse in 2027 (95)
- NVIDIA GeForce RTX 50-Series Scheduled for up to $500 Price Hike This Week (89)
- Modder Fits RTX 5090 With Four 8-Pin Connectors, Halving Current per Wire (80)