News Posts matching #Neoverse

Return to Keyword Browsing

Supermicro Expands Data Center Building Block Solutions Flexibility with Arm-Based Platforms and OCP Systems for Next-Gen AI Infrastructure

Super Micro Computer, Inc. , an AI, Enterprise, Storage, 5G/Edge Total Solution provider, today expanded its Data Center Building Block Solutions (DCBBS) portfolio with new Arm -based server platforms powered by the new Arm AGI CPU, and new Open Compute Project (OCP) ORv3-compliant rack offerings. Supermicro leads the industry with over 20 OCP Inspired systems, which incorporate various OCP technologies and form factors, to simplify open data center deployments.

"Supermicro continues to advance its DCBBS with an expanded portfolio of Arm-based platforms and OCP systems for next-gen AI and HPC," said Charles Liang, president and CEO of Supermicro. "With high-density, liquid-cooled systems and energy-efficient Arm architectures, we enable scalable, flexible data centers that maximize performance-per-watt and accelerate AI adoption across cloud and enterprise environments."

Arm Enters Silicon Business for the First Time with Data Center AGI CPU

Arm has made a significant move stepping into production silicon for the first time in its history with the launch of the Arm AGI CPU, a data center processor designed specifically for agentic AI workloads. For over three decades, Arm has been purely an IP licensing business. With the launch of its AGI CPU series, Arm made a fundamental shift in how the company positions itself in the market. The AGI CPU is built on a 3 nm process, packs up to 136 Neoverse V3 cores, runs at a 300 W TDP, and delivers 6 GB/s of memory bandwidth per core at under 100 ns latency. It supports up to 6 TB per chip and DDR5-8800 speeds. On the I/O side, the chip features 96 PCIe Gen 6 lanes along with CXL 3.0 and AMBA CHI (Coherent Hub Interface) links. Each core handles a dedicated program thread, which Arm says eliminates throttling and idle threads under sustained load.

Specifically important in the data center business, density figures are notable. Air-cooled systems can fit up to 8,160 cores per rack, while liquid-cooled systems push that above 45,000. Data centers are expected to need more than four times the current CPU capacity per gigawatt to keep up, and Arm is arguing that x86 architecture carries too much overhead and complexity for this new class of workload. Arm claims more than 2x performance per rack versus x86, adding that this can translate to potential savings of up to $10 billion per gigawatt of AI data center capacity.

Microsoft Rolls Out Cobalt 200 CPU with 132 Arm Cores

Microsoft has unveiled the Cobalt 200, a custom server processor designed for its Azure cloud infrastructure. According to the company, the chip offers approximately a 50% performance increase over its previous Cobalt 100 design and enhances energy efficiency. Some Cobalt 200 systems are already operational in Microsoft datacenters, with wider customer availability anticipated in 2026. This positions the Cobalt 200 as a key hardware component for many Azure services. The processor is built using Arm Neoverse V3 technology in a dual-chiplet layout, totaling 132 cores, and is manufactured on TSMC's 3 nm node. The design emphasizes precise power control, allowing each core to operate at its own voltage and frequency. This means each core can independently boost performance based on workload demands. The processor also includes a substantial 192 MB of L3 cache and 12 memory channels.

Additionally, Microsoft has integrated specialized accelerators for compression and cryptographic tasks, which the company states make up about 33% of typical cloud operations. This allows these functions to run without occupying general-purpose cores. Microsoft took a unique approach by modeling over 140 real-world Azure scenarios and employing AI-driven simulations to evaluate more than 350,000 configuration options before finalizing the architecture. Initial results from production deployments are promising, with one collaboration service noting a 45% improvement in performance and a 35% reduction in compute requirements compared to the previous platform. The chip also includes hardware memory encryption by default and supports Arm confidential compute features to enhance workload isolation for enterprise customers.

Arm Q2 FYE26 Revenue Surpasses $1 Billion for Third Consecutive Quarter

Arm (NASDAQ: ARM) published a letter to its shareholders containing results for the second quarter of fiscal year 2026 ended September 30, 2025. The infographic below offers the key highlights.

Here are what the results mean and how they were achieved:
  • Surpassing $1 billion for the third consecutive quarter, as Arm reported second-quarter revenue of $1.14 billion, up 34% year-over-year. Revenue was above the high end of guidance, and non-GAAP EPS finished above the high end.
  • Royalty revenue rose 21% year-over-year to $620 million, driven by the continued adoption of Arm technology with higher royalty rates per chip, such as Armv9 and Arm Compute Subsystems (CSS), and increased usage of Arm-based chips in data centers.
  • Three new Arm CSS licenses signed in the quarter, one each in smartphones, tablet, and data centers, bringing the total to 19 licenses with 11 companies, with five customers already shipping CSS-based chips. Samsung will also leverage CSS for its Exynos family of chipsets, which means the top four Android phone vendors are now shipping CSS-powered devices.
    • In Q2, Arm launched the Lumex CSS platform, our most advanced smartphone platform to date, delivering up to 5x faster AI performance on a new generation of Arm C1 CPUs with Arm Scalable Matrix Extension 2 (SME2) and up to 3x the energy savings, alongside up to 2x AI and graphics performance through the integration with the new Arm Mali G1-Ultra GPU compared to the prior generations. The ecosystem is already embracing Lumex, with leading applications, such as Alipay, Gmail, and YouTube, accelerating on-device inference and real-time personalization, and partners, such as MediaTek, designing Lumex configurations into its next-generation chips for new flagship smartphones from Oppo and vivo.

SiPearl Launches Athena1 Sovereign Processor Dedicated to Dual-Use

SiPearl, the European fabless designer of sovereign high-performance energy-efficient processors for HPC, AI and data centers, today announced the launch of the Athena1 processor for dual-use applications.

Based on the unique expertise in Europe developed for the design of Rhea1 (SiPearl's first generation processor, dedicated to HPC), Athena1 will offer features specifically tailored to the workloads of government, defense and aerospace applications. These include, for example, secure communications and intelligence, cryptography and encryption, intelligence processing, tactical networks, electronic detection or local data processing on vehicles.

NVIDIA Blackwell-Powered Jetson Thor Now Available, Accelerating the Age of General Robotics

NVIDIA today announced the general availability of the NVIDIA Jetson AGX Thor developer kit and production modules, powerful new robotics computers designed to power millions of robots across industries including manufacturing, logistics, transportation, healthcare, agriculture and retail. Early adopters include industry leaders Agility Robotics, Amazon Robotics, Boston Dynamics, Caterpillar, Figure, Hexagon, Medtronic and Meta, while 1X, John Deere, OpenAI and Physical Intelligence are evaluating Jetson Thor to advance their physical AI capabilities.

"We've built Jetson Thor for the millions of developers working on robotic systems that interact with and increasingly shape the physical world," said Jensen Huang, founder and CEO of NVIDIA. "With unmatched performance and energy efficiency, and the ability to run multiple generative AI models at the edge, Jetson Thor is the ultimate supercomputer to drive the age of physical AI and general robotics."
Arm Q1 FYE26 Revenue Exceeds $1 Billion for Second Consecutive Quarter

Today Arm (NASDAQ:ARM) published a letter to its shareholders containing the company's results for its first quarter of fiscal year 2026 ended June 30, 2025. The infographic below provides the key highlights:
Here are what the results mean and how they were achieved:
  • Record revenues for an Arm first quarter, crossing the $1 billion quarterly revenue milestone for the second consecutive quarter and delivering the second-best revenue quarter ever.
  • Royalty revenue rose 25% year-over-year to $585 million, driven by the growing adoption of the Armv9 architecture, increasing number of chips based on Arm Compute Subsystems (CSS), and use of Arm-based chips in datacenters.

Xsight Labs Announced Availability of Its Arm-Based E1-SoC for Cloud and Edge AI Data Centers

Xsight Labs, a leading fabless semiconductor company providing end-to-end connectivity for next-generation hyperscale, edge and AI data center networks, today announced availability of its Arm -based E1-SoC for cloud and edge AI data centers. The E-Series is the only product of its kind to provide full control plane and data path programmability and is the industry's highest performance software-defined DPU (Data Processing Unit). Xsight Labs is taking orders now for its E1-SoC and the E1-Server, the first-to-market 800G DPU.

E1 is the first SoC in the E-Series, Xsight Labs' SDN (Software Defined Network) Infrastructure Processor product family of fully programmable network accelerators. Built on TSMC's advanced 5 nm process technology, the E1-SoC will begin shipping to customers and ecosystem partners.

Arm Introduces New Product Naming for PC, Infrastructure, Mobile, and More

Arm today announced a simpler, more intuitive naming scheme for its compute platforms to help developers and manufacturers better understand which solutions suit their needs. Under the new naming structure, infrastructure-grade server CPU products will be known as Arm Neoverse, the name previously reserved for Arm's core IP for server CPUs. The PC lineup will adopt the name Arm Niva, while Arm Lumex will convey its focus on mobile performance to smartphones and tablets. Automotive applications, which require both safety certification and high compute capacity, will fall under Arm Zena. Finally, Arm Orbis will cover IoT and embedded devices, offering a tailored edge AI platform for everything from sensors to earbuds.

In addition to the market-specific names, Arm is overhauling its IP numbering system to align with generational releases. Future cores will carry labels such as Ultra, Premium, Pro, Nano, and Pico to indicate relative performance and power characteristics. Combining a clear platform identity with a descriptive performance tier, this two-tier approach should make it easier for partners to plan long-term roadmaps and pick the right building blocks for their designs. Arm's GPU technology will continue under the well-known Mali brand, but Mali will now be presented explicitly as a component within each platform rather than a separate product. By integrating Mali GPUs into Neoverse, Niva, Lumex, Zena, and Orbis, Arm aims to deliver fully validated subsystems instead of standalone IP pieces.

AMD Discusses EPYC's "No Compromise" Driving of Performance and Efficiency

One of the main pillars that vendors of Arm-based processors often cite as a competitive advantage versus x86 processors is a keen focus on energy efficiency and predictability of performance. In the quest for higher efficiency and performance, Arm vendors have largely designed out the ability to operate on multiple threads concurrently—something that most enterprise-class CPUs have enabled for years under the technology description of "SMT"—which was also created in the name of enabling performance and efficiency benefits.

Arm vendors often claim that SMT brings security risks, creates performance unpredictability from shared resource contention and drives added cost and energy needed to implement SMT. Interestingly, Arm does support multi-threading in its Neoverse E1-class processor family for embedded uses such as automotive. Given these incongruities, this blog intends to provide a bit more clarity to help customers assess what attributes of performance and efficiency really bring them value for their critical workloads.

Arm and Partners Develop AI CPU: Neoverse V3 CSS Made on 2 nm Samsung GAA FET

Yesterday, Arm has announced significant progress in its Total Design initiative. The program, launched a year ago, aims to accelerate the development of custom silicon for data centers by fostering collaboration among industry partners. The ecosystem has now grown to include nearly 30 participating companies, with recent additions such as Alcor Micro, Egis, PUF Security, and SEMIFIVE. A notable development is a partnership between Arm, Samsung Foundry, ADTechnology, and Rebellions to create an AI CPU chiplet platform. This collaboration aims to deliver a solution for cloud, HPC, and AI/ML workloads, combining Rebellions' AI accelerator with ADTechnology's compute chiplet, implemented using Samsung Foundry's 2 nm Gate-All-Around (GAA) FET technology. The platform is expected to offer significant efficiency gains for generative AI workloads, with estimates suggesting a 2-3x improvement over the standard CPU design for LLMs like Llama3.1 with 405 billion parameters.

Arm's approach emphasizes the importance of CPU compute in supporting the complete AI stack, including data pre-processing, orchestration, and advanced techniques like Retrieval-augmented Generation (RAG). The company's Compute Subsystems (CSS) are designed to address these requirements, providing a foundation for partners to build diverse chiplet solutions. Several companies, including Alcor Micro and Alphawave, have already announced plans to develop CSS-powered chiplets for various AI and high-performance computing applications. The initiative also focuses on software readiness, ensuring that major frameworks and operating systems are compatible with Arm-based systems. Recent efforts include the introduction of Arm Kleidi technology, which optimizes CPU-based inference for open-source projects like PyTorch and Llama.cpp. Notably, as Google claims, most AI workloads are being inferenced on CPUs, so creating the most efficient and most performant CPUs for AI makes a lot of sense.

NVIDIA Cancels Dual-Rack NVL36x2 in Favor of Single-Rack NVL72 Compute Monster

NVIDIA has reportedly discontinued its dual-rack GB200 NVL36x2 GPU model, opting to focus on the single-rack GB200 NVL72 and NVL36 models. This shift, revealed by industry analyst Ming-Chi Kuo, aims to simplify NVIDIA's offerings in the AI and HPC markets. The decision was influenced by major clients like Microsoft, who prefer the NVL72's improved space efficiency and potential for enhanced inference performance. While both models perform similarly in AI large language model (LLM) training, the NVL72 is expected to excel in non-parallelizable inference tasks. As a reminder, the NVL72 features 36 Grace CPUs, delivering 2,592 Arm Neoverse V2 cores with 17 TB LPDDR5X memory with 18.4 TB/s aggregate bandwidth. Additionally, it includes 72 Blackwell GB200 SXM GPUs that have a massive 13.5 TB of HBM3e combined, running at 576 TB/s aggregate bandwidth.

However, this shift presents significant challenges. The NVL72's power consumption of around 120kW far exceeds typical data center capabilities, potentially limiting its immediate widespread adoption. The discontinuation of the NVL36x2 has also sparked concerns about NVIDIA's execution capabilities and may disrupt the supply chain for assembly and cooling solutions. Despite these hurdles, industry experts view this as a pragmatic approach to product planning in the dynamic AI landscape. While some customers may be disappointed by the dual-rack model's cancellation, NVIDIA's long-term outlook in the AI technology market remains strong. The company continues to work with clients and listen to their needs, to position itself as a leader in high-performance computing solutions.

MediaTek Joins Arm Total Design to Shape the Future of AI Computing

MediaTek announced today at COMPUTEX 2024 that the company has joined Arm Total Design, a fast-growing ecosystem that aims to accelerate and simplify the development of products based on Arm Neoverse Compute Subsystems (CSS). Arm Neoverse CSS is designed to meet the performance and efficiency needs of AI applications in the data center, infrastructure systems, telecommunications, and beyond.

"Together with Arm, we're enabling our customers' designs to meet the most challenging workloads for AI applications, maximizing performance per watt," said Vince Hu, Corporate Vice President at MediaTek. "We will be working closely with Arm as we expand our footprint into data centers, utilizing our expertise in hybrid computing, AI, SerDes and chiplets, and advance packaging technologies to accelerate AI innovation from the edge to the cloud."

European Supercomputer Chip SiPearl Rhea Delayed, But Upgraded with More Cores

The rollout of SiPearl's much-anticipated Rhea processor for European supercomputers has been pushed back by a year to 2025, but the delay comes with a silver lining - a significant upgrade in core count and potential performance. Originally slated to arrive in 2024 with 72 cores, the homegrown high-performance chip will now pack 80 cores when it eventually launches. This decisive move by SiPearl and its partners is a strategic choice to ensure the utmost quality and capabilities for the flagship European processor. The additional 12 months will allow the engineering teams to further refine the chip's architecture, carry out extensive testing, and optimize software stacks to take full advantage of Rhea's computing power. Now called the Rhea1, the chip is a crucial component of the European Processor Initiative's mission to develop domestic high-performance computing technologies and reduce reliance on foreign processors. Supercomputer-scale simulations spanning climate science, drug discovery, energy research and more all require astonishing amounts of raw compute grunt.

By scaling up to 80 cores based on the latest Arm Neoverse V1, Rhea1 aims to go toe-to-toe with the world's most powerful processors optimized for supercomputing workloads. The SiPearl wants to utilize TSMC's N6 manufacturing process. The CPU will have 256-bit DDR5 memory connections, 104 PCIe 5.0 lanes, and four stacks of HBM2E memory. The roadmap shift also provides more time for the expansive European supercomputing ecosystem to prepare robust software stacks tailored for the upgraded Rhea silicon. Ensuring a smooth deployment with existing models and enabling future breakthroughs are top priorities. While the delay is a setback for SiPearl's launch schedule, the substantial upgrade could pay significant dividends for Europe's ambitions to join the elite ranks of worldwide supercomputer power. All eyes will be on Rhea's delivery in 2025, mainly from Europe's governments, which are funding the project.

Google Launches Axion Arm-based CPU for Data Center and Cloud

Google has officially joined the club of custom Arm-based, in-house-developed CPUs. As of today, Google's in-house semiconductor development team has launched the "Axion" CPU based on Arm instruction set architecture. Using the Arm Neoverse V2 cores, Google claims that the Axion CPU outperforms general-purpose Arm chips by 30% and Intel's processors by a staggering 50% in terms of performance. This custom silicon will fuel various Google Cloud offerings, including Compute Engine, Kubernetes Engine, Dataproc, Dataflow, and Cloud Batch. The Axion CPU, designed from the ground up, will initially support Google's AI-driven services like YouTube ads and Google Earth Engine. According to Mark Lohmeyer, Google Cloud's VP and GM of compute and machine learning infrastructure, Axion will soon be available to cloud customers, enabling them to leverage its performance without overhauling their existing applications.

Google's foray into custom silicon aligns with the strategies of its cloud rivals, Microsoft and Amazon. Microsoft recently unveiled its own AI chip for training large language models and an Arm-based CPU called Cobalt 100 for cloud and AI workloads. Amazon, on the other hand, has been offering Arm-based servers through its custom Graviton CPUs for several years. While Google won't sell these chips directly to customers, it plans to make them available through its cloud services, enabling businesses to rent and leverage their capabilities. As Amin Vahdat, the executive overseeing Google's in-house chip operations, stated, "Becoming a great hardware company is very different from becoming a great cloud company or a great organizer of the world's information."

Arm Launches Next-Generation Neoverse CSS V3 and N3 Designs for Cloud, HPC, and AI Acceleration

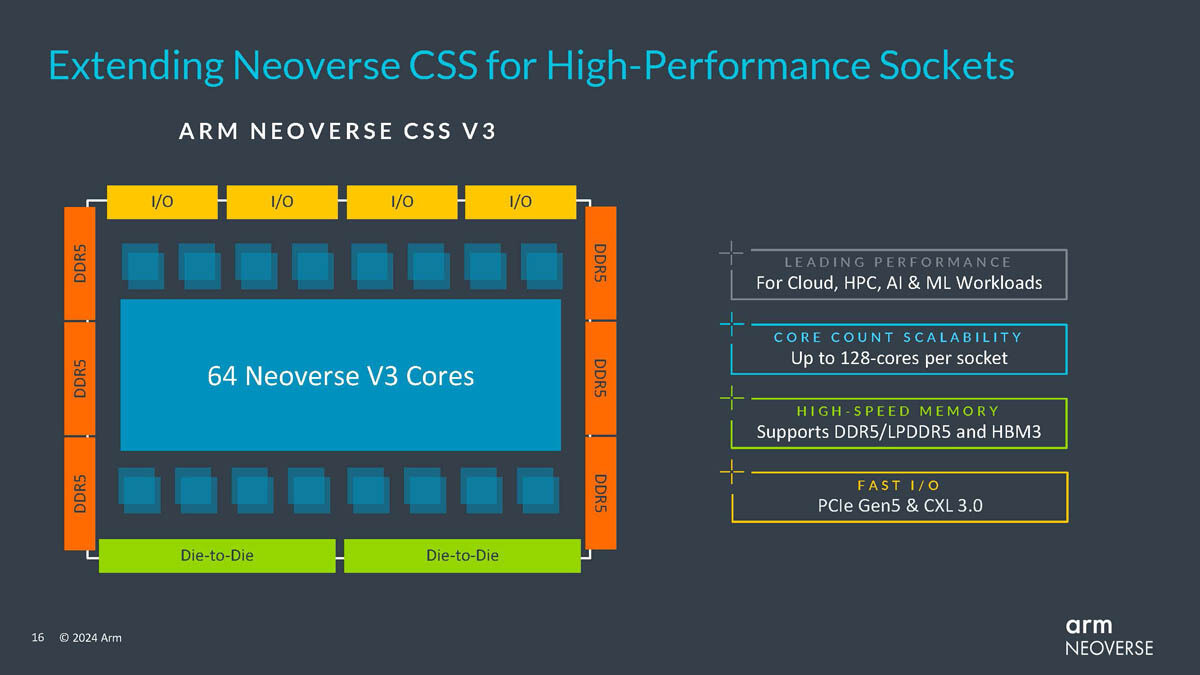
Last year, Arm introduced its Neoverse Compute Subsystem (CSS) for the N2 and V2 series of data center processors, providing a reference platform for the development of efficient Arm-based chips. Major cloud service providers like AWS with Graviton 4 and Trainuium 2, Microsoft with Cobalt 100 and Maia 100, and even NVIDIA with Grace CPU and Bluefield DPUs are already utilizing custom Arm server CPU and accelerator designs based on the CSS foundation in their data centers. The CSS allows hyperscalers to optimize Arm processor designs specifically for their workloads, focusing on efficiency rather than outright performance. Today, Arm has unveiled the next generation CSS N3 and V3 for even greater efficiency and AI inferencing capabilities. The N3 design provides up to 32 high-efficiency cores per die with improved branch prediction and larger caches to boost AI performance by 196%, while the V3 design scales up to 64 cores and is 50% faster overall than previous generations.

Both the N3 and V3 leverage advanced features like DDR5, PCIe 5.0, CXL 3.0, and chiplet architecture, continuing Arm's push to make chiplets the standard for data center and cloud architectures. The chiplet approach enables customers to connect their own accelerators and other chiplets to the Arm cores via UCIe interfaces, reducing costs and time-to-market. Looking ahead, Arm has a clear roadmap for its Neoverse platform. The upcoming CSS V4 "Adonis" and N4 "Dionysus" designs will build on the improvements in the N3 and V3, advancing Arm's goal of greater efficiency and performance using optimized chiplet architectures. As more major data center operators introduce custom Arm-based designs, the Neoverse CSS aims to provide a flexible, efficient foundation to power the next generation of cloud computing.

Intel Foundry Services Get 18A Order: Arm-based 64-Core Neoverse SoC

Faraday Technology Corporation, a Taiwanese silicon IP designer, has announced plans to develop a new 64-core system-on-chip (SoC) utilizing Intel's most advanced 18A process technology. The Arm-based SoC will integrate Arm Neoverse compute subsystems (CSS) to deliver high performance and efficiency for data centers, infrastructure edge, and 5G networks. This collaboration brings together Faraday, Arm, and Intel Foundry Services. Faraday will leverage its ASIC design and IP solutions expertise to build the SoC. Arm will provide the Neoverse compute subsystem IP to enable scalable computing. Intel Foundry Services will manufacture the chip using its cutting-edge 18A process, which delivers one of the best-in-class transistor performance.

The new 64-core SoC will be a key component of Faraday's upcoming SoC evaluation platform. This platform aims to accelerate customer development of data center servers, high-performance computing ASICs, and custom SoCs. The platform will also incorporate interface IPs from the Arm Total Design ecosystem for complete implementation and verification. Both Arm and Intel Foundry Services expressed excitement about working with Faraday on this advanced Arm-based custom silicon project. "We're thrilled to see industry leaders like Faraday and Intel on the cutting edge of Arm-based custom silicon development," said an Arm spokesperson. Intel SVP Stuart Pann said, "We are pleased to work with Faraday in the development of the SoC based on Arm Neoverse CSS utilizing our most competitive Intel 18A process technology." The collaboration represents Faraday's strategic focus on leading-edge technologies to meet evolving application requirements. With its extensive silicon IP portfolio and design capabilities, Faraday wants to deliver innovative solutions and break into next-generation computing design.

Microsoft Introduces 128-Core Arm CPU for Cloud and Custom AI Accelerator

During its Ignite conference, Microsoft introduced a duo of custom-designed silicon made to accelerate AI and excel in cloud workloads. First of the two is Microsoft's Azure Cobalt 100 CPU, a 128-core design that features a 64-bit Armv9 instruction set, implemented in a cloud-native design that is set to become a part of Microsoft's offerings. While there aren't many details regarding the configuration, the company claims that the performance target is up to 40% when compared to the current generation of Arm servers running on Azure cloud. The SoC has used Arm's Neoverse CSS platform customized for Microsoft, with presumably Arm Neoverse N2 cores.

The next and hottest topic in the server space is AI acceleration, which is needed for running today's large language models. Microsoft hosts OpenAI's ChatGPT, Microsoft's Copilot, and many other AI services. To help make them run as fast as possible, Microsoft's project Athena now has the name of Maia 100 AI accelerator, which is manufactured on TSMC's 5 nm process. It features 105 billion transistors and supports various MX data formats, even those smaller than 8-bit bit, for maximum performance. Currently tested on GPT 3.5 Turbo, we have yet to see performance figures and comparisons with competing hardware from NVIDIA, like H100/H200 and AMD, with MI300X. The Maia 100 has an aggregate bandwidth of 4.8 Terabits per accelerator, which uses a custom Ethernet-based networking protocol for scaling. These chips are expected to appear in Microsoft data centers early next year, and we hope to get some performance numbers soon.

Socionext Announces Collaboration with Arm and TSMC on 2nm Multi-Core Leading CPU Chiplet Development

Socionext today announced a collaboration with Arm and TSMC for the development of an innovative power-optimized 32-core CPU chiplet in TSMCʼs 2 nm silicon technology, delivering scalable performance for hyperscale data center server, 5/6G infrastructure, DPU and edge-of- network markets.

The engineering samples are targeted to be available in 1H2025. This advanced CPU chiplet proof-of-concept using Arm Neoverse CSS technology is designed for single or multiple instantiations within a single package, along with IO and application-specific custom chiplets to optimize performance for a variety of end applications.

Arm and Synopsys Strengthen Partnership to Accelerate Custom Silicon on Advanced Nodes

Synopsys today announced it has expanded its collaboration with Arm to provide optimized IP and EDA solutions for the newest Arm technology, including the Arm Neoverse V2 platform and Arm Neoverse Compute Subsystem (CSS). Synopsys has joined Arm Total Design where Synopsys will leverage their deep design expertise, the Synopsys.ai full-stack AI-driven EDA suite, and Synopsys Interface, Security, and Silicon Lifecycle Management IP to help mutual customers speed development of their Arm-based CSS solutions. The expanded partnership builds on three decades of collaboration to enable mutual customers to quickly develop specialized silicon at lower cost, with less risk and faster time to market.

"With Arm Total Design, our aim is to enable rapid innovation on Arm Neoverse CSS and engage critical ecosystem expertise at every stage of SoC development," said Mohamed Awad, senior vice president and general manager, Infrastructure Line of Business at Arm. "Our deep technical collaboration with Synopsys to deliver pre-integrated and validated IP and EDA tools will help our mutual customers address the industry's most complex computing challenges with specialized compute."

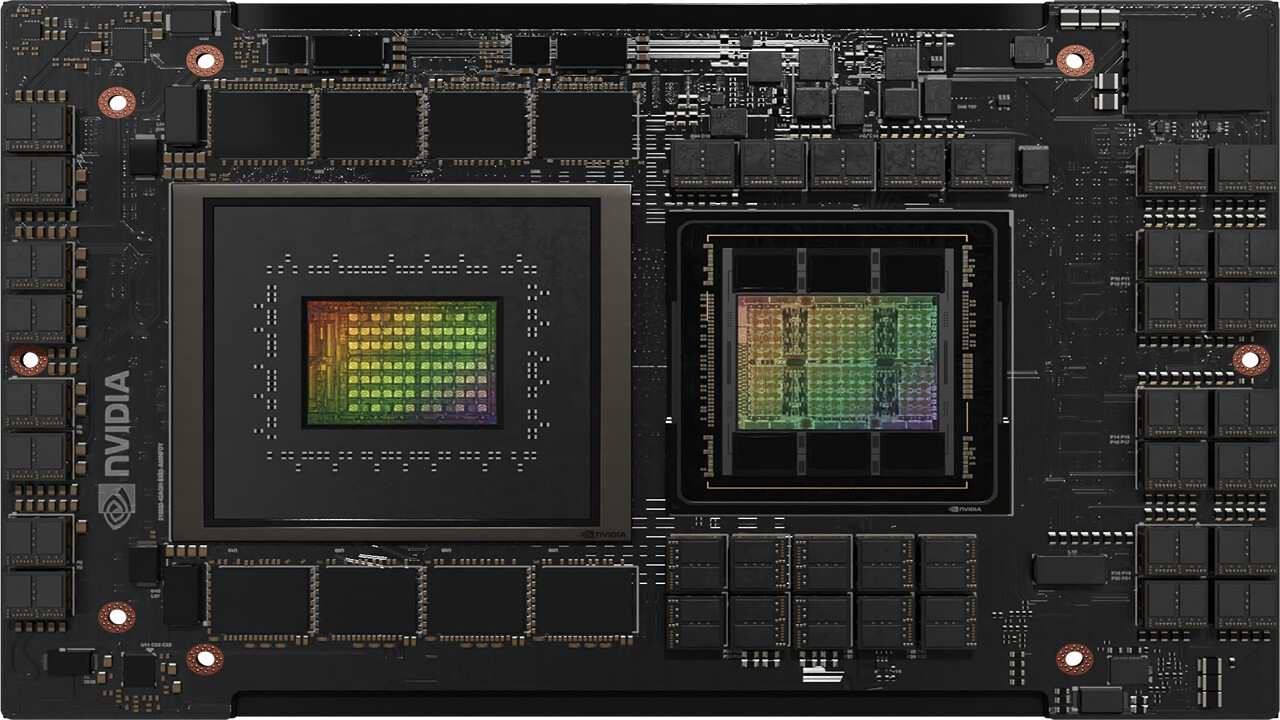
NVIDIA Unveils Next-Generation GH200 Grace Hopper Superchip Platform With HMB3e

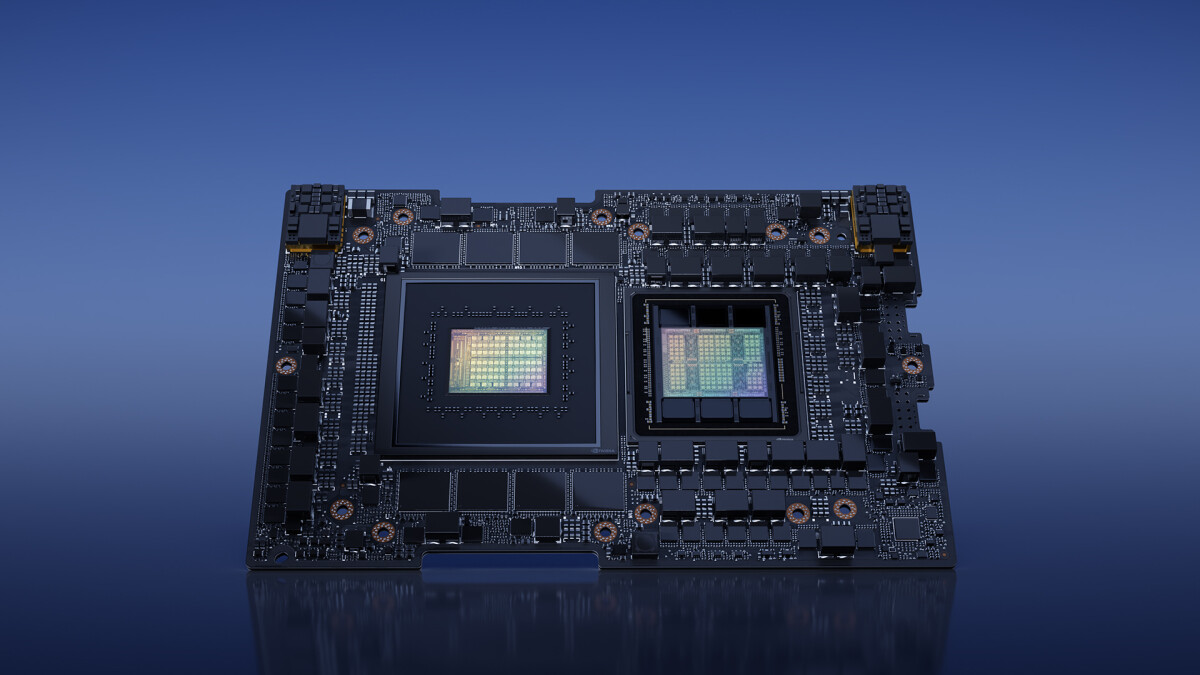
NVIDIA today announced the next-generation NVIDIA GH200 Grace Hopper platform - based on a new Grace Hopper Superchip with the world's first HBM3e processor - built for the era of accelerated computing and generative AI. Created to handle the world's most complex generative AI workloads, spanning large language models, recommender systems and vector databases, the new platform will be available in a wide range of configurations. The dual configuration - which delivers up to 3.5x more memory capacity and 3x more bandwidth than the current generation offering - comprises a single server with 144 Arm Neoverse cores, eight petaflops of AI performance and 282 GB of the latest HBM3e memory technology.

"To meet surging demand for generative AI, data centers require accelerated computing platforms with specialized needs," said Jensen Huang, founder and CEO of NVIDIA. "The new GH200 Grace Hopper Superchip platform delivers this with exceptional memory technology and bandwidth to improve throughput, the ability to connect GPUs to aggregate performance without compromise, and a server design that can be easily deployed across the entire data center."

China Hosts 40% of all Arm-based Servers in the World

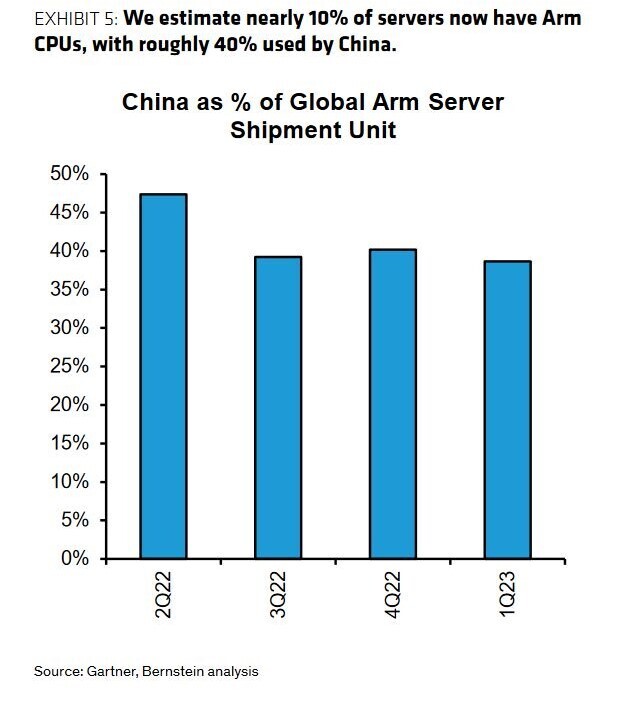
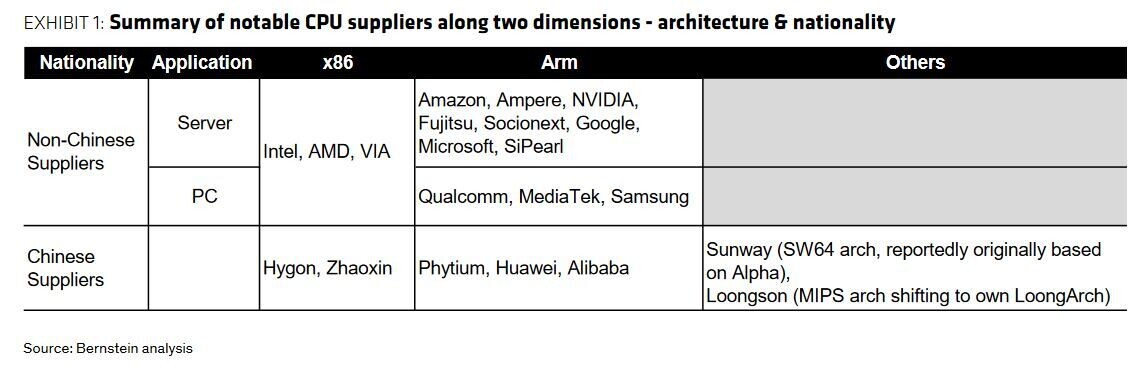
The escalating challenges in acquiring high-performance x86 servers have prompted Chinese data center companies to accelerate the shift to Arm-based system-on-chips (SoCs). Investment banking firm Bernstein reports that approximately 40% of all Arm-powered servers globally are currently being used in China. While most servers operate on x86 processors from AMD and Intel, there's a growing preference for Arm-based SoCs, especially in the Chinese market. Several global tech giants, including AWS, Ampere, Google, Fujitsu, Microsoft, and Nvidia, have already adopted or developed Arm-powered SoCs. However, Arm-based SoCs are increasingly favorable for Chinese firms, given the difficulty in consistently sourcing Intel's Xeon or AMD's EPYC. Chinese companies like Alibaba, Huawei, and Phytium are pioneering the development of these Arm-based SoCs for client and data center processors.

However, the US government's restrictions present some challenges. Both Huawei and Phytium, blacklisted by the US, cannot access TSMC's cutting-edge process technologies, limiting their ability to produce competitive processors. Although Alibaba's T-Head can leverage TSMC's latest innovations, it can't license Arm's high-performance computing Neoverse V-series CPU cores due to various export control rules. Despite these challenges, many chip designers are considering alternatives such as RISC-V, an unrestricted, rapidly evolving open-source instruction set architecture (ISA) suitable for designing highly customized general-purpose cores for specific workloads. Still, with the backing of influential firms like AWS, Google, Nvidia, Microsoft, Qualcomm, and Samsung, the Armv8 and Armv9 instruction set architectures continue to hold an edge over RISC-V. These companies' support ensures that the software ecosystem remains compatible with their CPUs, which will likely continue to drive the adoption of Arm in the data center space.

NVIDIA Collaborates With SoftBank Corp. to Power SoftBank's Next-Gen Data Centers Using Grace Hopper Superchip for Generative AI and 5G/6G

NVIDIA and SoftBank Corp. today announced they are collaborating on a pioneering platform for generative AI and 5G/6G applications that is based on the NVIDIA GH200 Grace Hopper Superchip and which SoftBank plans to roll out at new, distributed AI data centers across Japan. Paving the way for the rapid, worldwide deployment of generative AI applications and services, SoftBank will build data centers that can, in collaboration with NVIDIA, host generative AI and wireless applications on a multi-tenant common server platform, which reduces costs and is more energy efficient.

The platform will use the new NVIDIA MGX reference architecture with Arm Neoverse-based GH200 Superchips and is expected to improve performance, scalability and resource utilization of application workloads. "As we enter an era where society coexists with AI, the demand for data processing and electricity requirements will rapidly increase. SoftBank will provide next-generation social infrastructure to support the super-digitalized society in Japan," said Junichi Miyakawa, president and CEO of SoftBank Corp. "Our collaboration with NVIDIA will help our infrastructure achieve a significantly higher performance with the utilization of AI, including optimization of the RAN. We expect it can also help us reduce energy consumption and create a network of interconnected data centers that can be used to share resources and host a range of generative AI applications."

NVIDIA Grace Drives Wave of New Energy-Efficient Arm Supercomputers

NVIDIA today announced a supercomputer built on the NVIDIA Grace CPU Superchip, adding to a wave of new energy-efficient supercomputers based on the Arm Neoverse platform. The Isambard 3 supercomputer to be based at the Bristol & Bath Science Park, in the U.K., will feature 384 Arm-based NVIDIA Grace CPU Superchips to power medical and scientific research, and is expected to deliver 6x the performance and energy efficiency of Isambard 2, placing it among Europe's most energy-efficient systems.

It will achieve about 2.7 petaflops of FP64 peak performance and consume less than 270 kilowatts of power, ranking it among the world's three greenest non-accelerated supercomputers. The project is being led by the University of Bristol, as part of the research consortium the GW4 Alliance, together with the universities of Bath, Cardiff and Exeter.

India Homegrown HPC Processor Arrives to Power Nation's Exascale Supercomputer

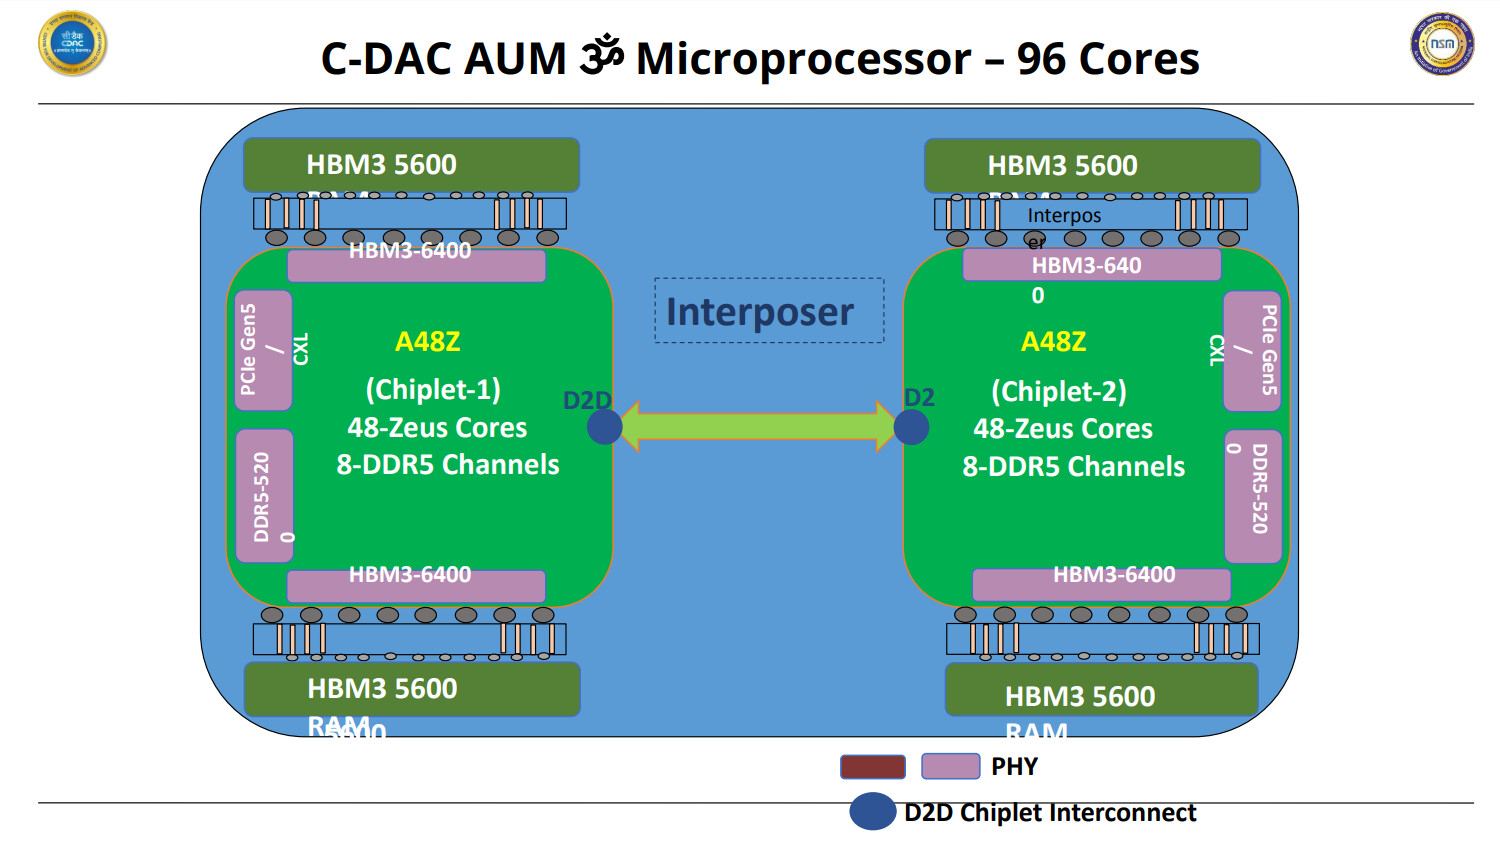
With more countries creating initiatives to develop homegrown processors capable of powering powerful supercomputing facilities, India has just presented its development milestone with Aum HPC. Thanks to information from the report by The Next Platform, we learn that India has developed a processor for powering its exascale high-performance computing (HPC) system. Called Aum HPC, the CPU was developed by the National Supercomputing Mission of the Indian government, which funded the Indian Institute of Science, the Department of Science and Technology, the Ministry of Electronics and Information Technology, and C-DAC to design and manufacture the Aum HPC processors and create strong, strong technology independence.

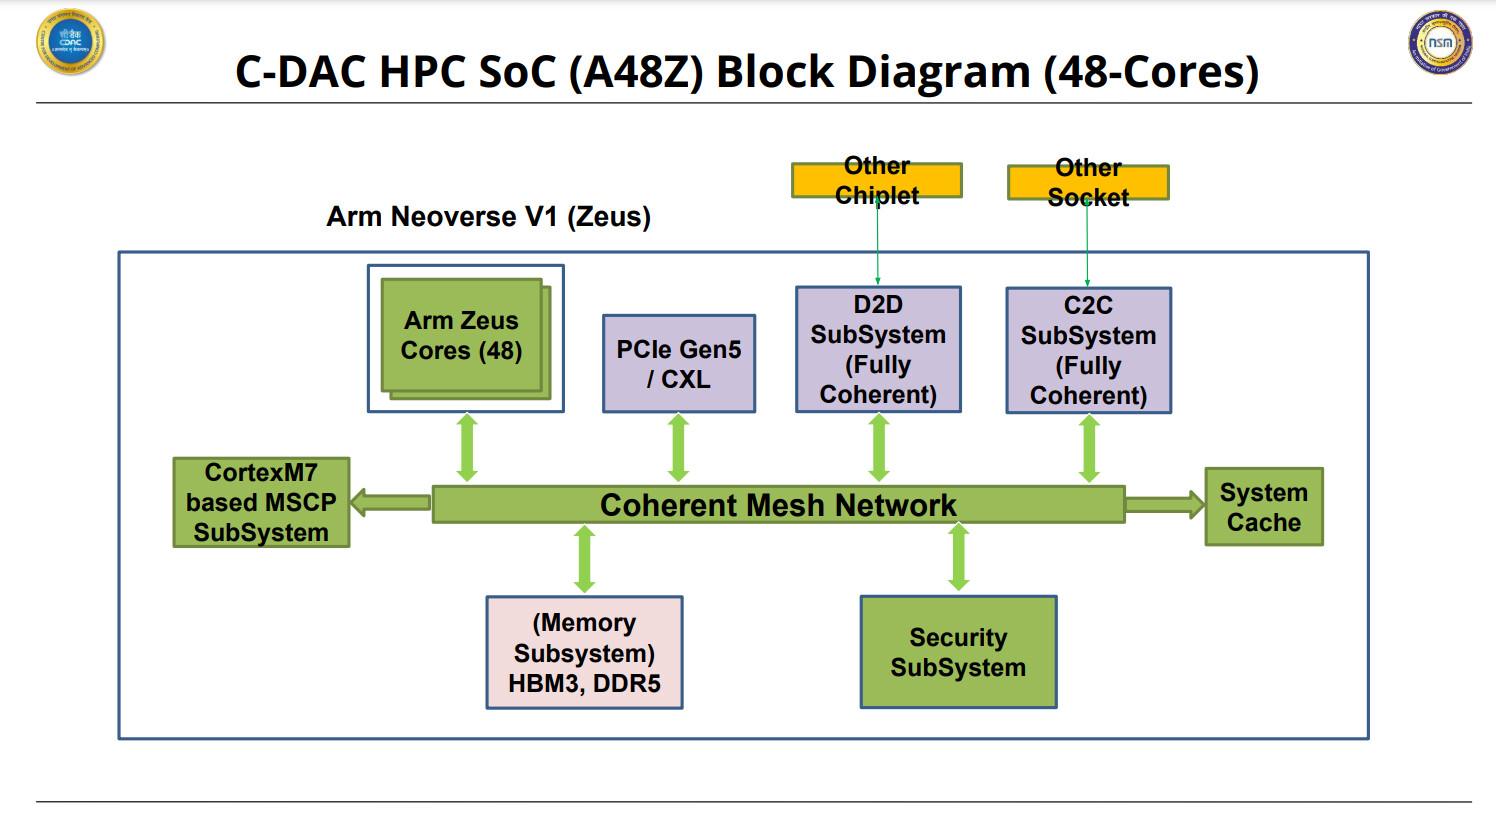
The Aum HPC is based on Armv8.4 CPU ISA and represents a chiplet processor. Each compute chiplet features 48 Arm Zeus Cores based on Neoverse V1 IP, so with two chiplets, the processor has 96 cores in total. Each core gets 1 MB of level two cache and 1 MB of system cache, for 96 MB L2 cache and 96 MB system cache in total. For memory, the processor uses 16-channel 32-bit DDR5-5200 with a bandwidth of 332.8 GB/s. To expand on that, HBM memory is present, and there is 64 GB of HBM3 with four controllers capable of achieving a bandwidth of 2.87 TB/s. As far as connectivity, the Aum HPC processor has 64 PCIe Gen 5 Lanes with CXL enabled. It is manufactured on a 5 nm node from TSMC. With a 3.0 GHz typical and 3.5+ GHz turbo frequency, the Aum HPC processor is rated for a TDP of 300 Watts. It is capable of producing 4.6+ TeraFLOPS per socket. Below are illustrations and tables comparing Aum HPC to Fujitsy A64FX, another Arm HPC-focused design.
Return to Keyword Browsing
Nov 11th, 2026 03:59 CST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts