News Posts matching #AMX

Return to Keyword Browsing

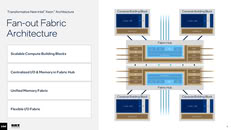
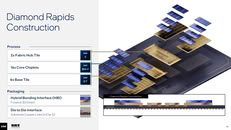
Intel Details Xeon 7 "Diamond Rapids" Package Design at HOT CHIPS

Intel, in a detailed presentation, detailed the package design of its next-generation Xeon 7 "Diamond Rapids" server processor. The processor is designed to be a versatile serial processing powerhouse for enterprise-scale agentic AI. Intel's design goal with the processor is to offer up to 256 P-cores, cushioned by up to 1.28 GB of last-level cache, per socket. The chip also features contemporary I/O, including PCI-Express Gen 6. Intel is leveraging its latest in-house foundry node, the Intel 18A-P, to design the core complex chiplets.

Xeon 7 "Diamond Rapids" is built on essentially the same disaggregation philosophy as AMD EPYC—that of CPU cores being spun out in small groups of CPU core complexes (CCXs) contained in CPU core dies (CCDs), groups of which interface with a centralized server I/O die (sIOD), which serves as a system agent and I/O hub. The "Diamond Rapids" MCM consists of two Fabric Hub Tiles (FHTs), four CPU core Base Tiles, and a total of 16 core chiplets, each containing 16 "Panther Cove" P-cores. The core-count per compute base tile is 64, and four of these add up to 256 cores.
Intel Announces Xeon 600 Workstation Processors Implementing "Redwood Cove" P-cores

Intel launches the new Xeon 600 series "Granite Rapids-WS" processors targeting workstations and HEDTs (high-end desktops). These had been announced in February. These processors mainly target AI development, where you take advantage of Intel AMX (FP16) accelerators, and a fully-fledged AVX-512 instruction set, along with a large PCIe I/O. The key talking point with this processor is its Compute complex. The processor comes with up to 86 "Redwood Cove" P-cores. These are the same P-cores powering Core Ultra "Meteor Lake" processors, and feature Hyper-Threading, besides a full-fat AVX-512 pipeline. The top-speed SKU hence comes with an 86-core/172-thread configuration, with a maximum Turbo Boost frequency of 4.80 GHz. Intel claims that the core-configuration offers a 61% multithreaded performance gain over the previous generation.

The Intel Xeon 600 series is built in the LGA4710 package, and supports Intel W890 chipset. It is configured with an 8-channel DDR5 memory interface (16 sub-channels), supporting up to 4 TB of ECC DDR5 memory, with speeds of up to DDR5-8000 being supported. The processor's PCIe root complex puts out 128 PCI-Express Gen 5 lanes. Intel is also offering CPU overclocking features with these processors. There are as many as 11 processor models, with core-counts ranging from the top 86-core/172-thread down to 12-core/24-thread, all models come with 8-channel ECC DDR5 memory and PCI-Express 5.0 x128. All processor models support Intel vPro remote manageability feature-set.

Intel Publishes "Granite Rapids-WS" Xeon 600 Turbo Frequencies, AVX-512 and AMX Slash Boost Speeds

In early February, Intel finally updated its HEDT sector with the latest "Granite Rapids-WS" Xeon 600 Series processors for workstations. The company has now published a detailed table of turbo frequencies that provides specifics on each core's boost frequency in workloads like SSE, AVX2, AVX-512, and AMX, showing how much these workloads allow the CPU cores to boost. This means that during a continuous workload like AMX, these CPUs can only run at a sustained frequency defined in the tables below. At the very top of the new "Granite Rapids-WS" stack is the Xeon 698X, featuring 86 cores and 172 threads, backed by 336 MB of L3 cache. The chip runs at a 2.0 GHz base clock, boosting up to 4.8 GHz with Turbo Boost Max 3.0, or 4.6 GHz under Turbo Boost 2.0. This CPU is fully unlocked, allowing overclocking, which is still relatively rare in the Xeon workstation space.

In non-AVX workloads, this CPU can boost up to 4.8 GHz, while its lowest-performing core, numbered 86, sits at 3.0 GHz. However, AVX2 turbo frequencies cause a significant frequency downgrade, as the base frequency drops to 1.7 GHz, and the slowest core drops to 2.9 GHz when boosting across its 86-core design. Following this are the AVX-512 turbo frequencies, which see this flagship SKU running at a base clock speed of only 1.3 GHz and only 2.5 GHz across its 86 cores. Perhaps the most demanding turbo frequency testing occurs when AMX is enabled, resulting in a base frequency of only 1.1 GHz and only 2.0 GHz across all cores at once. This significant reduction comes from the demanding scenarios of these vector and matrix instruction processing, which are very heavy on the CPU.
More information about other SKUs and details in AVX2, AVX-512, and AMX turbo frequencies follow.

More Evidence for AVX10 and APX Support in Intel "Nova Lake" Emerge

Intel's advanced features like AVX10, APX, and AMX instruction sets—designed for 512-bit acceleration and fast vector/matrix multiplication for tasks such as content creation, encoding/decoding, and AI—may not be exclusive to Intel Xeon processors. We could potentially see them in consumer "Nova Lake" processors. According to the Netwide Assembler (NASM), an assembler for the x86 CPU, Nova Lake might introduce these features in consumer PCs once again. A few weeks ago, it was believed that Nova Lake wouldn't include any of Intel's advanced x86 extensions. The latest GCC compiler patch indicated that the initial Nova Lake enablement does not incorporate AVX10, AMX, or APX. This suggested that support for these new x86 instructions might be absent from the next-generation CPU.

Initially, Intel chose to disable AVX-512 for the "Alder Lake" and "Raptor Lake" client-oriented CPU lineups, meaning that only server-grade Xeon CPUs benefited from the accelerated 512-bit data paths. With the release of NASM 3.0 and its subsequent 3.1 update, we are once again optimistic that Nova Lake will bring 512-bit acceleration to its client CPUs. Rumored to feature up to 52 cores, including 16 P-Cores, 32 E-Cores, and 4 LPE-Cores, Nova Lake could be an ideal CPU for gaming and workstation tasks, covering a wide range of scenarios and workloads, except for server applications, which are reserved for Xeon. Additionally, it could take advantage of the extensive ecosystem of AVX-accelerated software available today.

Intel "Nova Lake" Could Arrive Without AVX10, APX, and AMX Support

Intel is still finalizing its next-generation "Nova Lake" specifications. However, the core microarchitecture has been done, the NPU design is finished and upgraded, and the instruction set is finalized. It could be the case that these consumer CPUs will again lack support for Intel's AVX10, APX, and AMX instruction set—designed to encompass 512-bit acceleration and fast vector/matrix multiplication for tasks like content creation, encoding/decoding, AI, and much more—remaining exclusive to Intel Xeon processors. According to the latest GCC compiler patch, the initial Nova Lake enablement patch does not include AVX10, AMX, or APX. This might suggest that support for these new x86 instructions could be missing from the next-generation CPU. Initially, Intel decided to disable AVX-512 for "Alder Lake" and "Raptor Lake" client-oriented CPU lineups, meaning that only server-grade Xeon CPUs got the accelerated 512-bit data paths.

This GCC patch seems to contradict the findings from August, when Intel introduced AVX10.2 support for "future Intel Core processors" in the oneDNN software library, likely targeting the Nova Lake series. We need to wait for more information from other enablement patches or direct confirmation from Intel regarding whether AVX10, APX, and AMX will be included in the 52-core Nova Lake SKUs. Enabling fast vector and matrix acceleration on 52 cores would be ideal for consumers, content creators, gamers, and workstation users alike. In comparison, AMD introduced full AVX-512 support with its "Zen 5" cores across its product range, providing a performance boost in optimized applications for both desktop and server CPUs. This marked the first time AMD did not emulate 512-bit AVX, which previously required splitting 512-bit data into two 256-bit units to be processed over two cycles.

Intel "Diamond Rapids" Xeon CPU to Feature up to 192 P-Cores and 500 W TDP

Intel's next-generation "Oak Stream" platform is preparing to accommodate the upcoming "Diamond Rapids" Xeon CPU generation, and we are receiving more interesting details about the top-end configurations Intel will offer. According to the HEPiX TechWatch working group, the Diamond Rapids Intel Xeon 7 will feature up to 192 P-cores in the top-end SKU, split across four 48-core tiles. Intel has dedicated two primary SKU separators, where some models use eight-channel DDR5 memory, and the top SKUs will arrive with 16-channel DDR5 memory. Using MRDIMM Gen 2 for memory will enable Intel to push transfer rates to 12,800 MT/s per DIMM, providing massive bandwidth across 16 channels and keeping the "Panther Cove" cores busy with sufficient data. Intel planned the SoC to reach up to 500 W in a single socket.

As one of the first mass-produced 18A node products, Diamond Rapids will be the first to support Intel's APX, also featuring numerous improvements to the efficiency of AMX. Intel also plans to embed native support for more floating-point number formats, such as NVIDIA's TF32, and lower-precision FP8. As most of the world's inference is good enough to run on a CPU, Intel aims to accelerate basic inference operations for smaller models, enabling power users to run advanced workloads on CPUs alone. With a 1S, 2S, and 4S LGA 9324 configuration, Diamond Rapids will offer 768 cores in a single server rack, with a power usage of only 2000 W. Supporting external accelerators will be provided via the PCIe Gen 6 connector. Scheduled for arrival in 2026, Intel could time the launch to coincide with its upcoming "Jaguar Shores" AI accelerators, making a perfect pair for a complete AI system.

Supermicro Begins Volume Shipments of Max-Performance Servers Optimized for AI, HPC, Virtualization, and Edge Workloads

Supermicro, Inc. a Total IT Solution Provider for AI/ML, HPC, Cloud, Storage, and 5G/Edge is commencing shipments of max-performance servers featuring Intel Xeon 6900 series processors with P-cores. The new systems feature a range of new and upgraded technologies with new architectures optimized for the most demanding high-performance workloads including large-scale AI, cluster-scale HPC, and environments where a maximum number of GPUs are needed, such as collaborative design and media distribution.

"The systems now shipping in volume promise to unlock new capabilities and levels of performance for our customers around the world, featuring low latency, maximum I/O expansion providing high throughput with 256 performance cores per system, 12 memory channels per CPU with MRDIMM support, and high performance EDSFF storage options," said Charles Liang, president and CEO of Supermicro. "We are able to ship our complete range of servers with these new application-optimized technologies thanks to our Server Building Block Solutions design methodology. With our global capacity to ship solutions at any scale, and in-house developed liquid cooling solutions providing unrivaled cooling efficiency, Supermicro is leading the industry into a new era of maximum performance computing."

Intel Gaudi 2 Remains Only Benchmarked Alternative to NV H100 for Generative AI Performance

Today, MLCommons published results of the industry-standard MLPerf v4.0 benchmark for inference. Intel's results for Intel Gaudi 2 accelerators and 5th Gen Intel Xeon Scalable processors with Intel Advanced Matrix Extensions (Intel AMX) reinforce the company's commitment to bring "AI Everywhere" with a broad portfolio of competitive solutions. The Intel Gaudi 2 AI accelerator remains the only benchmarked alternative to Nvidia H100 for generative AI (GenAI) performance and provides strong performance-per-dollar. Further, Intel remains the only server CPU vendor to submit MLPerf results. Intel's 5th Gen Xeon results improved by an average of 1.42x compared with 4th Gen Intel Xeon processors' results in MLPerf Inference v3.1.

"We continue to improve AI performance on industry-standard benchmarks across our portfolio of accelerators and CPUs. Today's results demonstrate that we are delivering AI solutions that deliver to our customers' dynamic and wide-ranging AI requirements. Both Intel Gaudi and Xeon products provide our customers with options that are ready to deploy and offer strong price-to-performance advantages," said Zane Ball, Intel corporate vice president and general manager, DCAI Product Management.

Google: CPUs are Leading AI Inference Workloads, Not GPUs

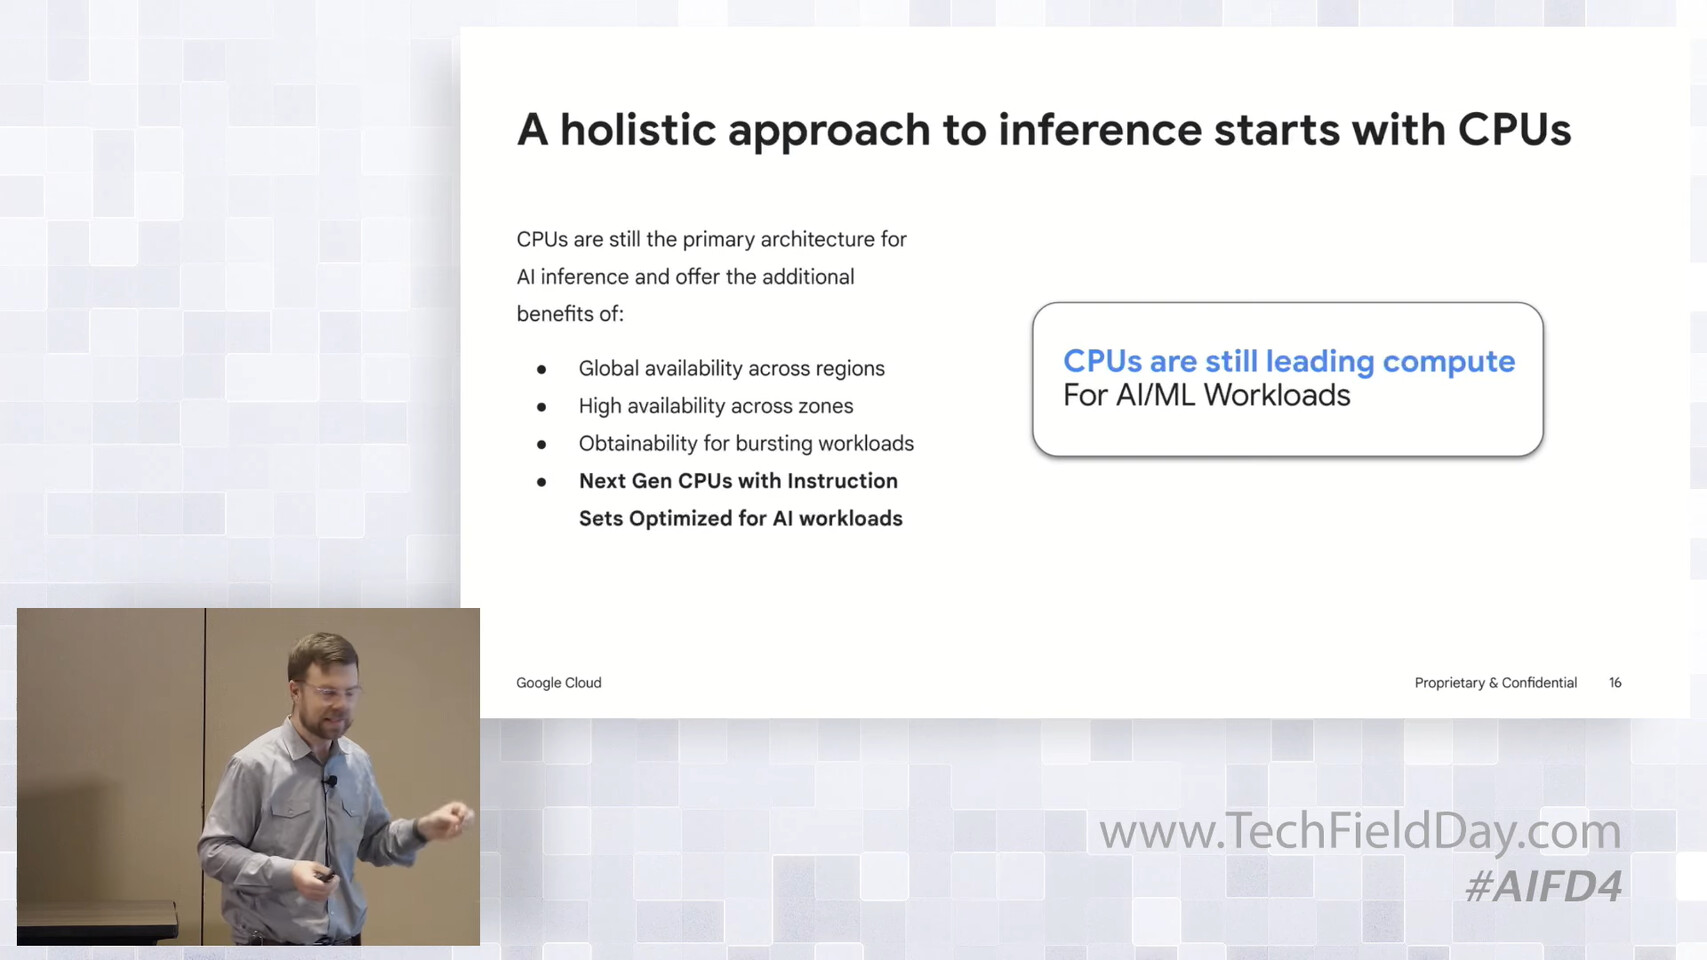
The AI infrastructure of today is mostly fueled by the expansion that relies on GPU-accelerated servers. Google, one of the world's largest hyperscalers, has noted that CPUs are still a leading compute for AI/ML workloads, recorded on their Google Cloud Services cloud internal analysis. During the TechFieldDay event, a speech by Brandon Royal, product manager at Google Cloud, explained the position of CPUs in today's AI game. The AI lifecycle is divided into two parts: training and inference. During training, massive compute capacity is needed, along with enormous memory capacity, to fit ever-expanding AI models into memory. The latest models, like GPT-4 and Gemini, contain billions of parameters and require thousands of GPUs or other accelerators working in parallel to train efficiently.

On the other hand, inference requires less compute intensity but still benefits from acceleration. The pre-trained model is optimized and deployed during inference to make predictions on new data. While less compute is needed than training, latency and throughput are essential for real-time inference. Google found out that, while GPUs are ideal for the training phase, models are often optimized and run inference on CPUs. This means that there are customers who choose CPUs as their medium of AI inference for a wide variety of reasons.

Intel "Emerald Rapids" Die Configuration Leaks, More Details Appear

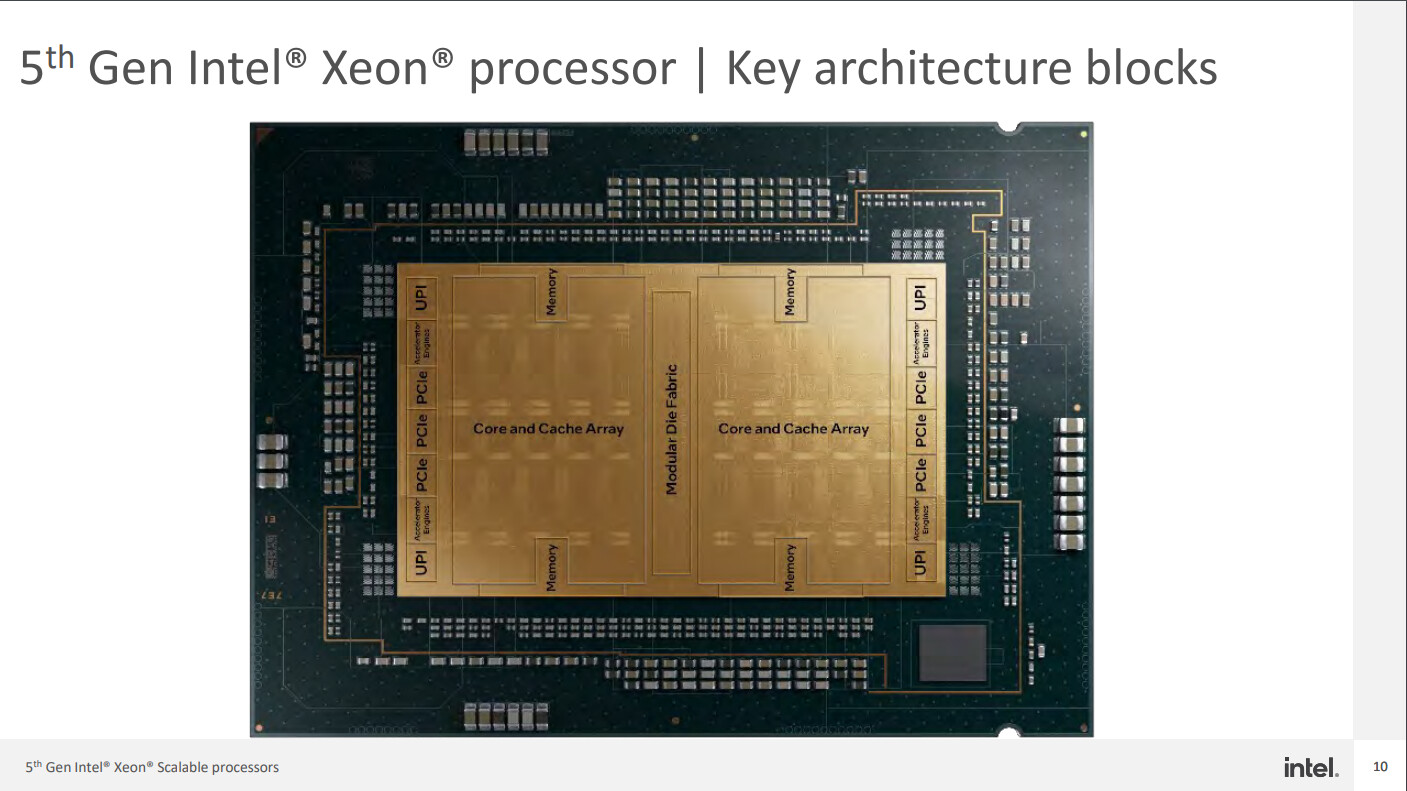
Thanks to the leaked slides obtained by @InstLatX64, we have more details and some performance estimates about Intel's upcoming 5th Generation Xeon "Emerald Rapids" CPUs, boasting a significant performance leap over its predecessors. Leading the Emerald Rapids family is the top-end SKU, the Xeon 8592+, which features 64 cores and 128 threads, backed by a massive 480 MB L3 cache pool. The upcoming lineup shifts from a 4-tile to a 2-tile design to minimize latency and improve performance. The design utilizes the P-Core architecture under the Raptor Cove ISA and promises up to 40% faster performance than the current 4th Generation "Sapphire Rapids" CPUs in AI applications utilizing Intel AMX engine. Each chiplet has 35 cores, three of which are disabled, and each tile has two DDR5-5600 MT/s memory controllers, which operate two memory channels each and translating that into eight-channel design. There are three PCIe controllers per die, making it six in total.

Newer protocols and AI accelerators also back the upcoming lineup. Now, the Emerald Rapids family supports the Compute Express Link (CXL) Types 1/2/3 in addition to up to 80 PCIe Gen 5 lanes and enhanced Intel Ultra Path Interconnect (UPI). There are four UPI controllers spread over two dies. Moreover, features like the four on-die Intel Accelerator Engines, optimized power mode, and up to 17% improvement in general-purpose workloads make it seem like a big step up from the current generation. Much of this technology is found on the existing Sapphire Rapids SKUs, with the new generation enhancing the AI processing capability further. You can see the die configuration below. The 5th Generation Emerald Rapids designs are supposed to be official on December 14th, just a few days away.

Intel Innovation 2023: Bringing AI Everywhere

As the world experiences a generational shift to artificial intelligence, each of us is participating in a new era of global expansion enabled by silicon. It's the "Siliconomy," where systems powered by AI are imbued with autonomy and agency, assisting us across both knowledge-based and physical-based tasks as part of our everyday environments.
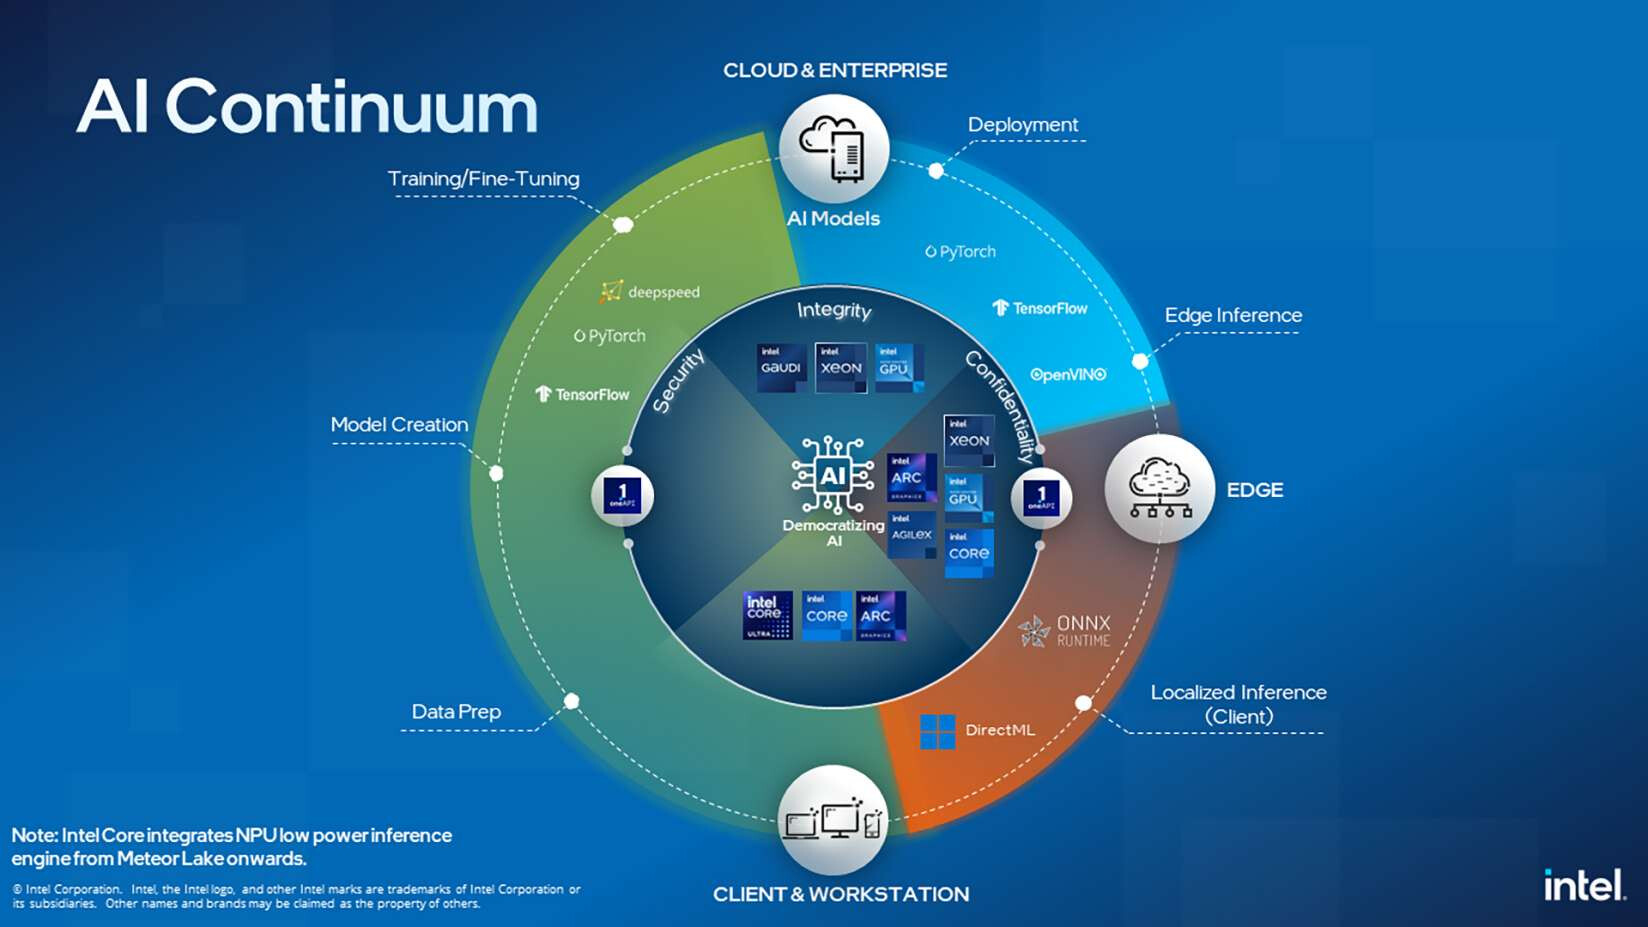
At Intel Innovation, the company unveiled technologies to bring AI everywhere and to make it more accessible across all workloads - from client and edge to network and cloud. These include easy access to AI solutions in the cloud, better price performance for Intel data center AI accelerators than the competition offers, tens of millions of new AI-enabled Intel PCs shipping in 2024 and tools for securely powering AI deployments at the edge.

Intel Launches New Xeon Workstation Processors - the Ultimate Solution for Professionals

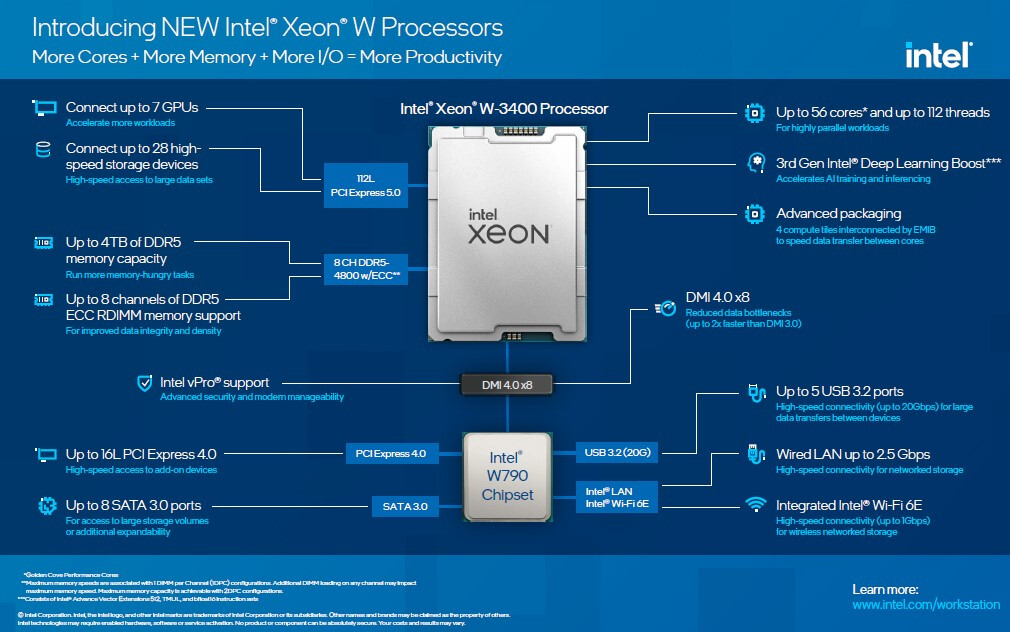
Intel today announced the new Intel Xeon W-3400 and Intel Xeon W-2400 desktop workstation processors (code-named Sapphire Rapids), led by the Intel Xeon w9-3495X, Intel's most powerful desktop workstation processor ever designed. Built for professional creators, these new Xeon processors provide massive performance for media and entertainment, engineering and data science professionals. With a breakthrough new compute architecture, faster cores and new embedded multi-die interconnect bridge (EMIB) packaging, the Xeon W-3400 and Xeon W-2400 series of processors enable unprecedented scalability for increased performance.

"For more than 20 years, Intel has been committed to delivering the highest quality workstation platforms - combining high-performance compute and rock-solid stability - for professional PC users across the globe. Our new Intel Xeon desktop workstation platform is uniquely designed to unleash the innovation and creativity of professional creators, artists, engineers, designers, data scientists and power users - built to tackle both today's most demanding workloads as well as the professional workloads of the future." -Roger Chandler, Intel vice president and general manager, Creator and Workstation Solutions, Client Computing Group

Intel Outs First Xeon Scalable "Sapphire Rapids" Benchmarks, On-package Accelerators Help Catch Up with AMD EPYC

Intel in the second day of its InnovatiON event, turned attention to its next-generation Xeon Scalable "Sapphire Rapids" server processors, and demonstrated on-package accelerators. These are fixed-function hardware components that accelerate specific kinds of popular server workloads (i.e. run them faster than a CPU core can). With these, Intel hopes to close the CPU core-count gap it has with AMD EPYC, with the upcoming "Zen 4" EPYC chips expected to launch with up to 96 cores per socket in its conventional variant, and up to 128 cores per socket in its cloud-optimized variant.

Intel's on-package accelerators include AMX (advanced matrix extensions), which accelerate recommendation-engines, natural language processing (NLP), image-recognition, etc; DLB (dynamic load-balancing), which accelerates security-gateway and load-balancing; DSA (data-streaming accelerator), which speeds up the network stack, guest OS, and migration; IAA (in-memory analysis accelerator), which speeds up big-data (Apache Hadoop), IMDB, and warehousing applications; a feature-rich implementation of the AVX-512 instruction-set for a plethora of content-creation and scientific applications; and lastly, the QAT (QuickAssist Technology), with speed-ups for data compression, OpenSSL, nginx, IPsec, etc. Unlike "Ice Lake-SP," QAT is now implemented on the processor package instead of the PCH.

Intel Xeon W9-3495 Sapphire Rapids HEDT CPU with 56 Cores and 112 Threads Appears

Intel's upcoming Sapphire Rapids processors will not only be present in the server sector but will also span the high-end desktop (HEDT) platform. Today, according to the findings of a Twitter user, @InstLatX64, we have an appearance of Intel's upcoming Sapphire Rapids HEDT SKU in Kernel.org boot logs. Named Intel Xeon W9-3495, this model features 56 cores and 112 threads. While there is no specific information about base and boost frequencies, we know that the SKU supports AVX-512 and AMX instructions. This is a welcome addition, as we have seen Intel disable AVX-512 on consumer chips altogether.

With a high core count and additional instructions for Deep Learning, this CPU will power workstations sometimes in the future. With the late arrival of Sapphire Rapids for servers, a HEDT variant should follow.

New Intel XPU Innovations Target HPC and AI

At the 2021 International Supercomputing Conference (ISC) Intel is showcasing how the company is extending its lead in high performance computing (HPC) with a range of technology disclosures, partnerships and customer adoptions. Intel processors are the most widely deployed compute architecture in the world's supercomputers, enabling global medical discoveries and scientific breakthroughs. Intel is announcing advances in its Xeon processor for HPC and AI as well as innovations in memory, software, exascale-class storage, and networking technologies for a range of HPC use cases.

"To maximize HPC performance we must leverage all the computer resources and technology advancements available to us," said Trish Damkroger, vice president and general manager of High Performance Computing at Intel. "Intel is the driving force behind the industry's move toward exascale computing, and the advancements we're delivering with our CPUs, XPUs, oneAPI Toolkits, exascale-class DAOS storage, and high-speed networking are pushing us closer toward that realization."

Intel's Upcoming Sapphire Rapids Server Processors to Feature up to 56 Cores with HBM Memory

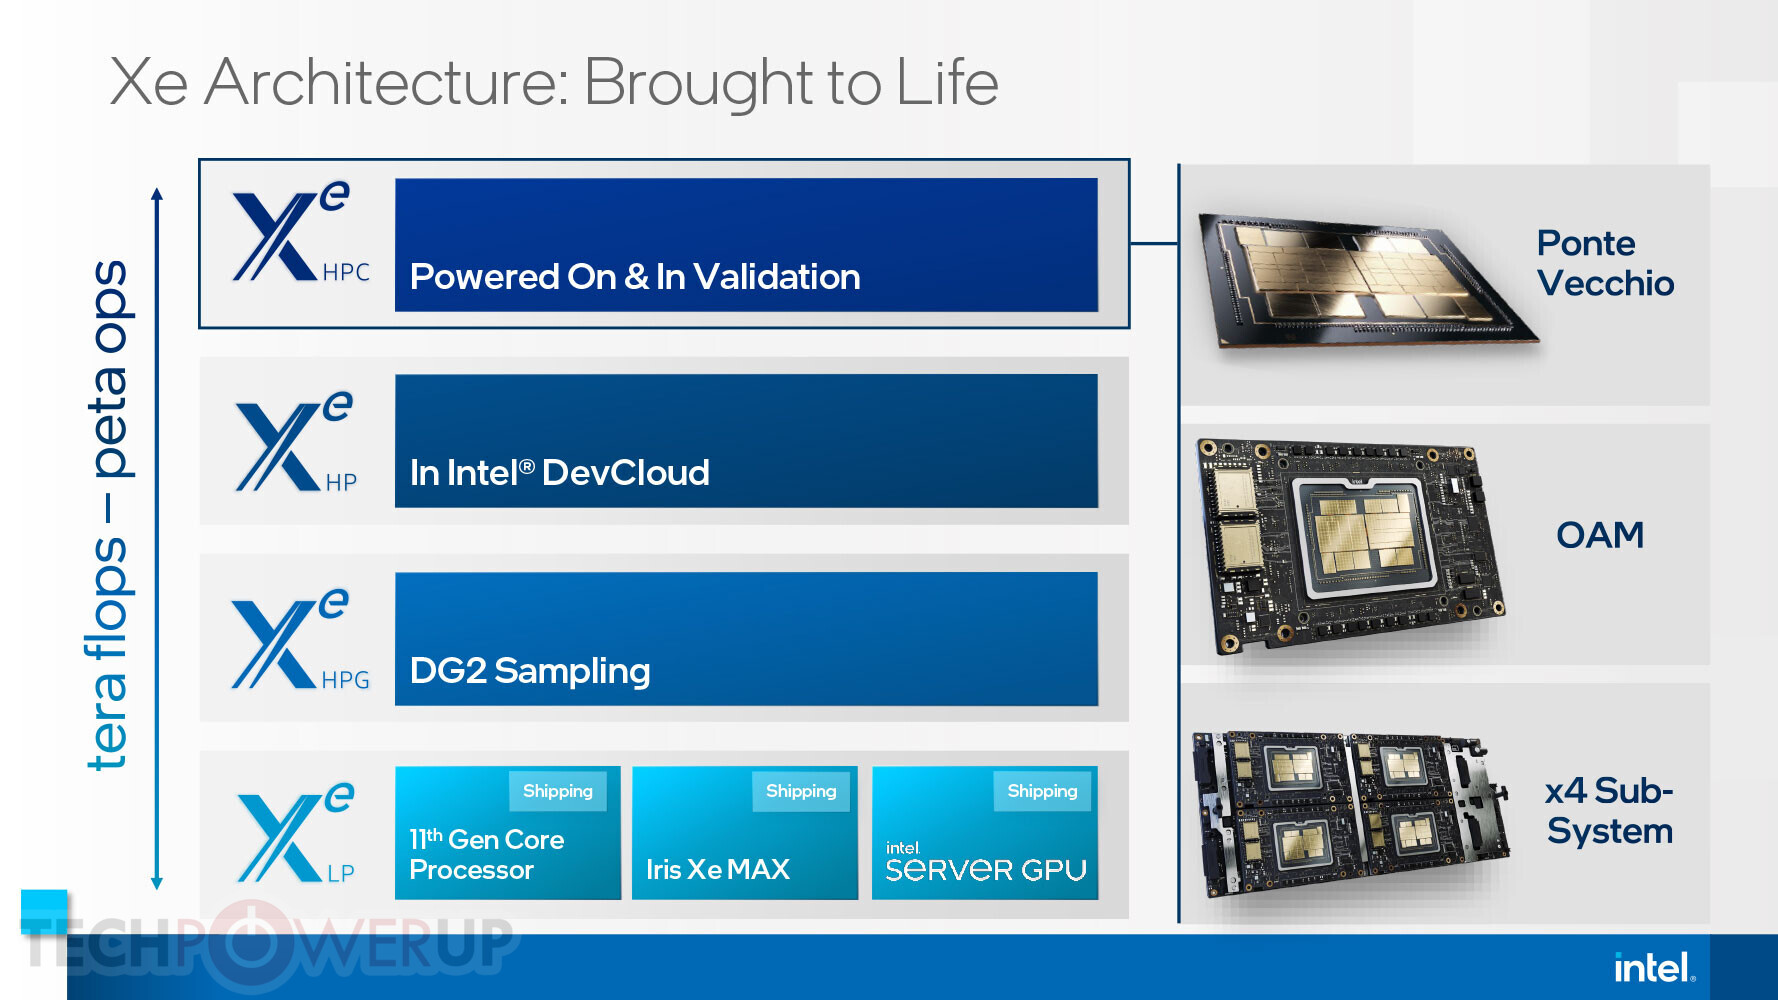
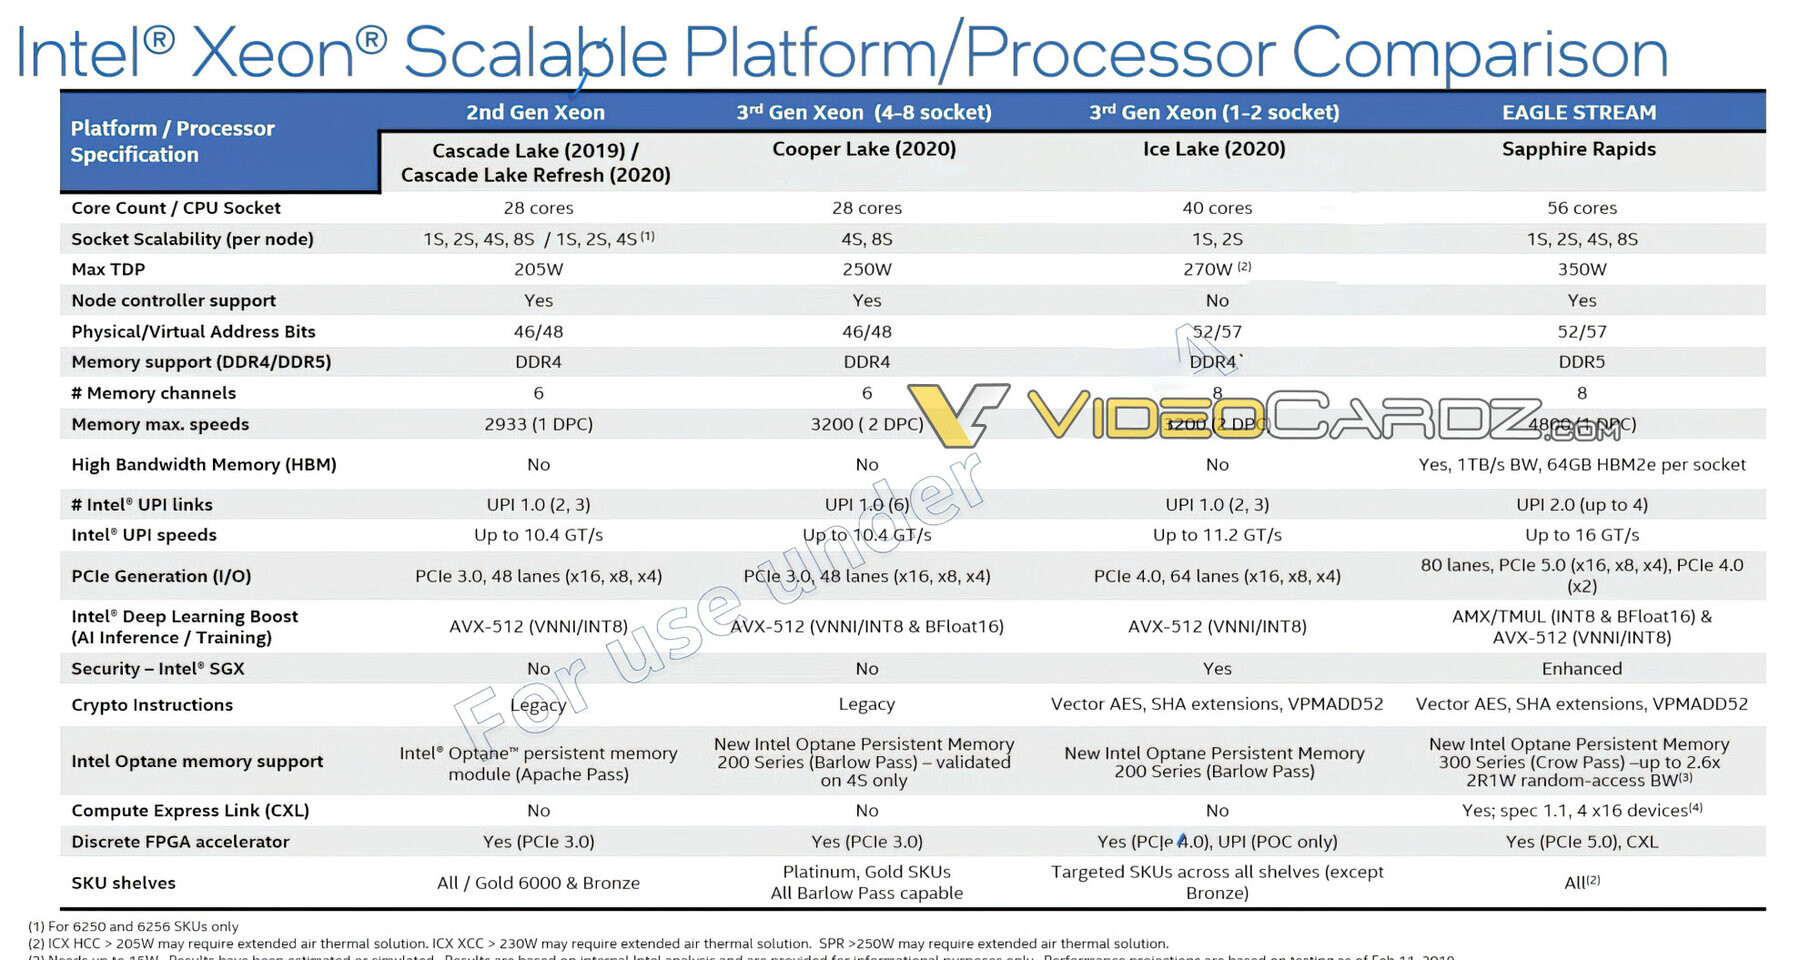
Intel has just launched its Ice Lake-SP lineup of Xeon Scalable processors, featuring the new Sunny Cove CPU core design. Built on the 10 nm node, these processors represent Intel's first 10 nm shipping product designed for enterprise. However, there is another 10 nm product going to be released for enterprise users. Intel is already preparing the Sapphire Rapids generation of Xeon processors and today we get to see more details about it. Thanks to the anonymous tip that VideoCardz received, we have a bit more details like core count, memory configurations, and connectivity options. And Sapphire Rapids is shaping up to be a very competitive platform. Do note that the slide is a bit older, however, it contains useful information.

The lineup will top at 56 cores with 112 threads, where this processor will carry a TDP of 350 Watts, notably higher than its predecessors. Perhaps one of the most interesting notes from the slide is the department of memory. The new platform will make a debut of DDR5 standard and bring higher capacities with higher speeds. Along with the new protocol, the chiplet design of Sapphire Rapids will bring HBM2E memory to CPUs, with up to 64 GBs of it per socket/processor. The PCIe 5.0 standard will also be present with 80 lanes, accompanying four Intel UPI 2.0 links. Intel is also supposed to extend the x86_64 configuration here with AMX/TMUL extensions for better INT8 and BFloat16 processing.

Intel Updates Its ISA Manual with Advanced Matrix Extension Reference

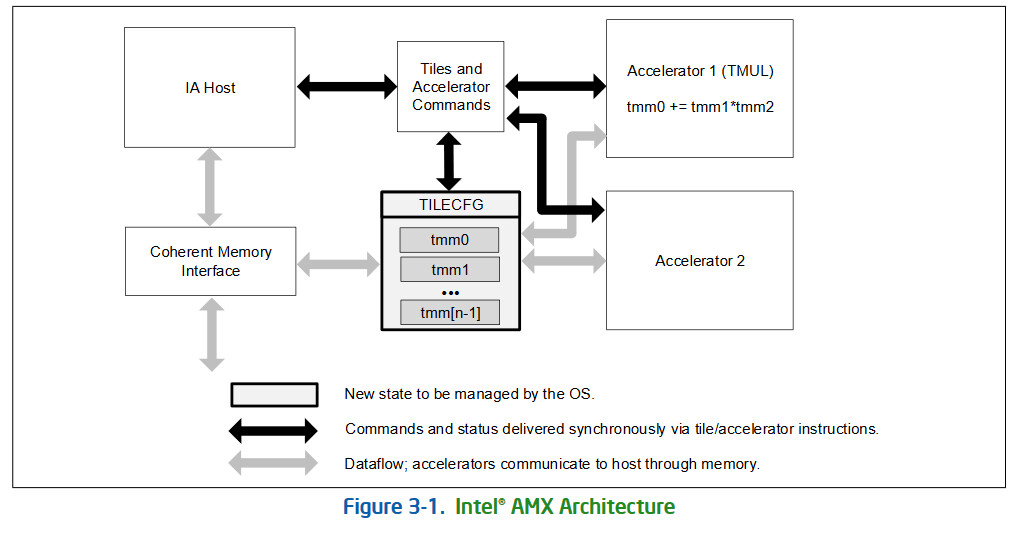
Intel today released and updated version of its "Architecture Instruction Set Extensions and Future Features Programming" Reference document with the latest advanced matrix extension (AMX) programming reference. This gives us some insights into AMX and how it works. While we will not go in too much depth here, the AMX is pretty simple. Intel describes it as the following: "Intel Advanced Matrix Extensions (Intel AMX) is a new 64-bit programming paradigm consisting of two components: a set of 2-dimensional registers (tiles) representing sub-arrays from a larger 2-dimensional memory image, and an accelerator able to operate on tiles, the first implementation is called TMUL (tile matrix multiply unit)." In other words, this represents another matrix processing extension that can be used for a wide variety of workload, mainly machine learning processing. The first microarchitecture that will implement the new extension is Sapphire Rapids Xeon processor. You can find more about AMX here.
Intel AMX
Return to Keyword Browsing
Nov 12th, 2026 00:02 CST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts