Monday, October 26th 2026

Intel APX Support Lands in Windows 11 Ahead of "Nova Lake" Launch
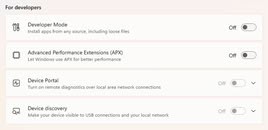
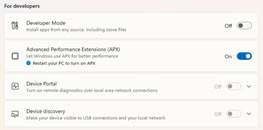
Intel's Advanced Performance Extensions (APX) are officially supported on Windows 11 PCs. However, there are currently no consumer PCs capable of utilizing APX. Intel's APX is set to debut with the "Nova Lake" processors in early 2027, but software development has been ongoing to ensure new features are ready before the processors reach retailers. In Windows 11 build 29695 for insiders, there is a toggle that allows you to enable APX for better performance. This indicates that Microsoft has prepared the APX optimizations across Windows, which will enhance everyday tasks and handle workloads with more processing power.
Intel APX is an extension to the x86-64 ISA that adds more registers and introduces new features to boost workloads across various use cases. Intel has designed APX to double the number of general-purpose registers in a CPU from 16 to 32, along with specific optimization paths to ensure compiled code is optimized to take advantage of the additional CPU capacity, resulting in performance improvements. Although this is a minor tweak, the data paths that follow are much more efficient. Intel reports around 10% fewer instructions in compiled code for Intel APX, even though the new instruction lengths are larger. This means the overall efficiency of executed tasks will consume fewer CPU cycles, freeing up resources for more tasks and boosting system performance.
 APX will also complement Advanced Vector Extensions, with AVX10.2 being the target for "Nova Lake." Since AVX10.2 requires both P-cores and E-cores to support AVX-512 acceleration, this suggests that "Coyote Cove" P-cores and "Arctic Wolf" E-cores for "Nova Lake" will be capable of advanced vector processing, significantly enhancing CPU capabilities. With "Nova Lake" expected to feature a 52-core design, having a large set of cores processing AVX-512 could potentially give Intel an advantage in the desktop CPU market.
Source:
XenoPanther on X
Intel APX is an extension to the x86-64 ISA that adds more registers and introduces new features to boost workloads across various use cases. Intel has designed APX to double the number of general-purpose registers in a CPU from 16 to 32, along with specific optimization paths to ensure compiled code is optimized to take advantage of the additional CPU capacity, resulting in performance improvements. Although this is a minor tweak, the data paths that follow are much more efficient. Intel reports around 10% fewer instructions in compiled code for Intel APX, even though the new instruction lengths are larger. This means the overall efficiency of executed tasks will consume fewer CPU cycles, freeing up resources for more tasks and boosting system performance.


26 Comments on Intel APX Support Lands in Windows 11 Ahead of "Nova Lake" Launch
Why wouldn't this just be on by default?
Maybe it's a "beta", and there may be some bugs etc. I'd expect this to be on by default in future.
Not every feature of APX is yielding performance benefits in the first generation (an example). Most likely this will be corrected in future CPU generations, just like AVX-512 performance issues were.
It's good that the toggle is available in an accessible manner since historically turning off CPU features on Windows was complicated (bit-banging DWORDs in the registry and having to edit BCD come to mind).
Compilers take your readable code in englishish and convert that to the instructions the CPU actually executes: machine code. We often look at machine code in assembly language which is easier to read than the actual hexadecimal code the CPU processes.
Let's take an example in pseudo code
In x86 assembly it would look like this:
mov eax, 5 (move the value 5 to the 32 bit register A)
mov ebx, 10 (move the value 10 to the 32 bit register B)
add eax, ebx (add B to A)
push eax (put the value A on the stack to take off later, if this were a functional subroutine), or
mov ecx, eax (if you actually wanted the value in the c register. Horses for courses)
In the pseudocode, the DECLARE AS INTEGER means nothing to the CPU, but the compiler understands it can use the faster 32bit CPU registers (A, B, C, D) rather than the much slower FPU registers (actually x87 uses a FPU stack to do the math... it's a legacy from decades ago, how they work is an interesting read).
In x86 we have ONLY 4 registers that can do these kind of integer operations. (Even though there are other registers, you can't really use them in the same way, because they are stack pointers or reference registers or flags)
In x86_64 we have an additional 8 general purpose registers (R8-R16) that behave in the same way as A, B, C, D. So now we have 12 registers for doing stuff (again, there are more registers but you can't or shouldn't use them for doing stuff like this or you'll get a crash as a result of misusing stack pointers and so forth)
However, to access these additional 8 general purpose registers we need to tell the CPU to use them, and it requires an extra one byte of memory to do so. It's a special opcode prefix "REX" (0b0100) to say, what comes next needs to be interpreted differently, and now refers to a new set of instructions using these new registers. Without the REX command, the following hexadecimal code would do something entirely different!
As you can see, under x86_64 we have more flexibility but it is cumbersome. It takes more program memory to use these new registers, and consequently, a little more time unless your memory, cache and pipeline can optimise the latency of additional memory access and processing completely away. However, the gain is that now we don't have to keep recycling the primary registers A, B, C, D and storing temporary results somewhere, but have the new 8 registers to help streamline code and execution for a speedup. You need a VERY SMART compiler to take advantage of these new registers using old program codebase. Writing compilers to optimise old code is very complex. Even more so when CPUs have "errata" where things don't always behave properly. So, to get the best performance, old code often needs to be rewritten cognisant of the new architecture so it will use the new commands in the most efficient way.
The pseudocode program c ← 5+10+20+30+40+50 can only be done in x86 by breaking it down into components and cycling through the calculation step by step whereas in x86_64 you could do it without recycling registers by using EAX, EBX, R8, R9, R10, R11. It can (depending on what you are actually doing) make the program smaller and the code faster to execute because you can avoid steps associated with "marshalling the yard" or juggling just the 4 registers A, B, C, D.
However, something complied in x86_64 cannot now be run on x86. The x86 would not understand the REX command and would therefore process the subsequent commands in their original form and not in the modified, use the new registers, execution mode. It would either crash or get garbage out.
Essentially, the same thing is happening in APX. We now have an additional 16 registers to work with. But we need to tell the CPU to use them, using a special opcode or flag, and then what comes next in the hexadecimal machine code is interpreted differently. So again, a program complied for APX will not work in x86 or x86_64 that doesn't understand what to do with this opcode. And because the new registers don't exist in the old architecture, you'd either get a crash or garbage out.
So Windows 11 compiled for APX will not work on a CPU without APX. Whereas Windows 11 compiled for x86_64 will work fine on a CPU with APX but because it does not use these new registers there can
be no improvement in code execution speeds.
Now if Windows 11 is compiled to work on BOTH APX and non-APX x86_64 it needs to have different codepaths depending on whether the CPU "flag" shows if APX instruction exists or not. That means more DLLs as in APX DLLs specifically complied for APX instructions, or BIGGER DLLs that contain the separate codepaths within them.
What a PITA. So many different compiler versions of code creating so many versions of code designed to execute on different architectures. This is very different than bigger cache, faster pipeline, more efficient code execution, parallel execution, speculative branching etc. where the same complied code just runs faster or more efficiently on the new architecture.
So why is Intel doing this? Because ARM RISC has 32 registers and smashes Intel in certain applications. And Intel hopes that in those niche situations, performance gaps can be closed. There are certain applications where the go-to is now ARM. I guess Intel needs to try and address that.
Will it make noticeable performance improvement to Windows 11 for us, desktop users? I don't think so. The 10% fewer instructions that Intel is quoting is interesting but how does this correlate with performance? Might be zero for general productivity software, but it might be much higher for special server or niche applications. I'll watch this space.
But 10% fewer instructions in execution on APX CPU still needs more HDD! Since to be compatible with x86_64 the actual programs will need the original 100% + new codepath 90% = 190% in memory/disk!
references
wiki.osdev.org/CPU_Registers_x86
wiki.osdev.org/CPU_Registers_x86-64
en.wikipedia.org/wiki/REX_prefix
intel dumping Pcores is indeed very likely
I think what you mean by "APX doesn't need to recompile to get benefits from it" is that a non-APX function can call an APX function without knowing that it is calling an APX function. Yes, this was a design goal of APX. In this sense you are right, but only in this sense.
- The extra 16 general-purpose 64-bit registers lower the need to spill registers to the stack frame in a larger function, and can enable loop unrolling in cases in which it wasn't previously beneficial
- 3-operand general-purpose instructions can eliminate a subsequent MOV instruction, and can lower the need to spill registers to the stack frame because the values of both input registers are preserved (in case of 2-operand instructions: value of 1 input register is preserved, the other input register is overwritten).
Not every program is a Windows program. Gentoo Linux (which compiles most packages from their source code during installation) will have no problems to transition to APX on the very same day the Gentoo user upgrades the CPU to Nova Lake in 2027+. It is likely that performance-oriented Linux distributions, such as Arch Linux, will start providing binary APX-only packages. Thus, bigger DLLs is a problem specific to Windows and to Linux distributions that prefer long-term stability over performance.For those not too familiar with low-level programming, this means a lot of small branching logic (if/switch) can be completely eliminated resulting in larger sections of linear code, which means fewer pipeline stalls, increased front-end efficiency and higher utilization of execution ports.
This is the largest architectural overhaul of the x86 ISA in decades, yet most miss the core features of it.
The increase of general purpose registers and three-operand instructions are more low-hanging fruit to reduce e.g. register shuffling / unnecessary load/stores preventing the CPU from effectively feeding the pipeline.
I do expect though that it will take some time for compilers to harness the full potential of the new conditional instructions. The benefits of more registers and three-operand instructions will be immediate though. And I wouldn't expect Nova Lake and Diamond Rapids to be fully fine-tuned either, wait for the second or third iteration before judging it.
Would APX boost SSE/AVX/FMA throughput?
- SSE instructions are in legacy encoding space
- AVX/AVX2 instructions are in VEX encoding space
- AVX-512 instructions are in EVEX encoding space
- Additionally, AVX/AVX2 instructions have an EVEX encoding if the CPU supports AVX512VL (most AVX-512 CPUs support this)
The answer to your question is: APX improves throughput of vector instructions only if those instructions have memory operands. For example: vpaddd ymm0, ymm1, [RAX+R21] where R21 is an APX register.For software relying on Microsoft's compiler it will probably take a while though, they only got "experimental" support back in May. But gcc has had support for a good while already.
Compared to porting software to ARM it should be trivial though, at least in theory; just change a flag and recompile. There shouldn't be any compatibility issues or new APIs required, so aside from compiler bugs there shouldn't be logical bugs. But the faster execution may expose some underlying designs flaws in code though, i.e. race conditions etc.
Microsoft have been patching schedulers without a major new version for years now, Windows 11 was most likely released to obsolete old hardware and allow then to ditch the old UI.
APX will have more significant benefits for user-interactive applications and games than big server workloads, so basically anything that's logic-heavy. Zen 7 will feature the much more obscure AMX, which currently mainly have "AI" uses, and requires major die space. APX by comparison is fairly easy to implement, and will likely yield even greater gains for AMD than Intel, as their current designs are wider but have a weaker front-end.