News Posts matching #TPU

Return to Keyword Browsing

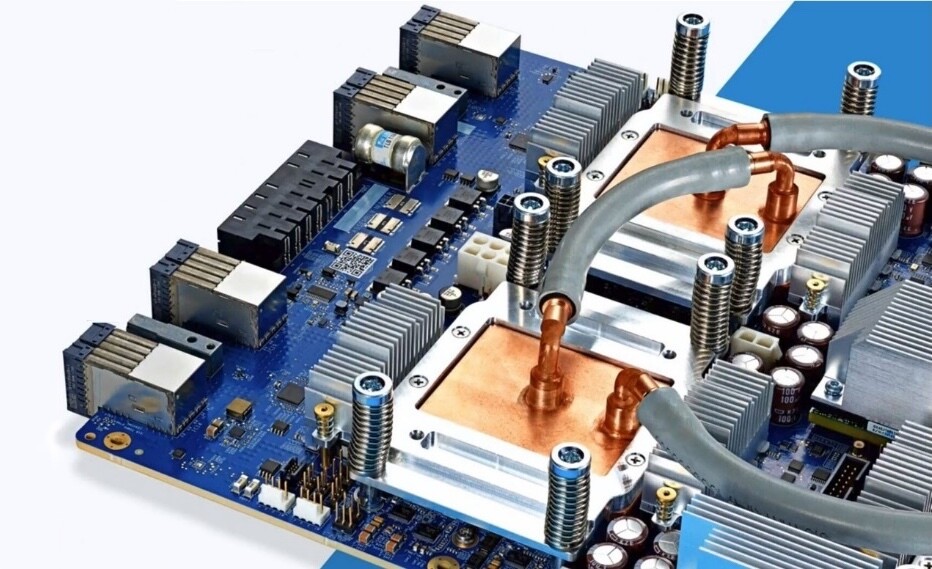
Google Extends Tensor Processor Unit Series with TPU 8tx and 8i Max

While we've always co-designed our TPUs in partnership with Google DeepMind, we're now increasingly getting feedback from external organizations on their specific needs. With computing moving from human to agent scale, businesses are asking for accelerators that can reason across AI models' massive context windows. In addition, some highly regulated customers are asking for specialized encryption capabilities for unique workloads.

The new TPU systems we are announcing today address this new reality. Coupled with our recent PyTorch announcements, our aim is to make TPUs more easily accessible to every developer and Cloud customer. By combining modular custom silicon with an open and easy-to-use software stack, we can deliver new hardware and system configurations at the pace of the AI industry.
Majority of TPU Users Don't See Microsoft's Promised Windows 11 Improvements

A few months ago, Microsoft promised its Windows enthusiast community that the company would implement a major overhaul to improve performance and stability in the Windows 11 operating system. We conducted a poll and received nearly 33,000 responses from the community to answer one question: Are you experiencing the promised improvements in Windows 11? However, the findings are quite polarized, as the majority of the enthusiast community doesn't actually notice any difference before and after the promise was made. Among all respondents, 43.4% voted that there are no noticeable improvements. This represents thousands of Windows 11 users worldwide who are not seeing any enhancement in their day-to-day operations with Microsoft's latest operating system.

What is perhaps more alarming is that many enthusiasts report a worse experience following Microsoft's promises. About 38.1% of the voters indicated they are experiencing actual degradation in day-to-day operations, as Microsoft continues to push updates that negatively impact everyday use and introduce more bugs. Notably, a recent example is the Windows 11 August update, which reset custom cursors to an oversized default one. In some cases, the color and size settings don't stick, no matter how many times they are changed. This update has also caused gameplay issues, such as forced crashes, random freezing, errors, and unexpected device restarts due to RGB peripherals.

Google Introduces Its Eighth Generation of Custom Tensor Processor Unit

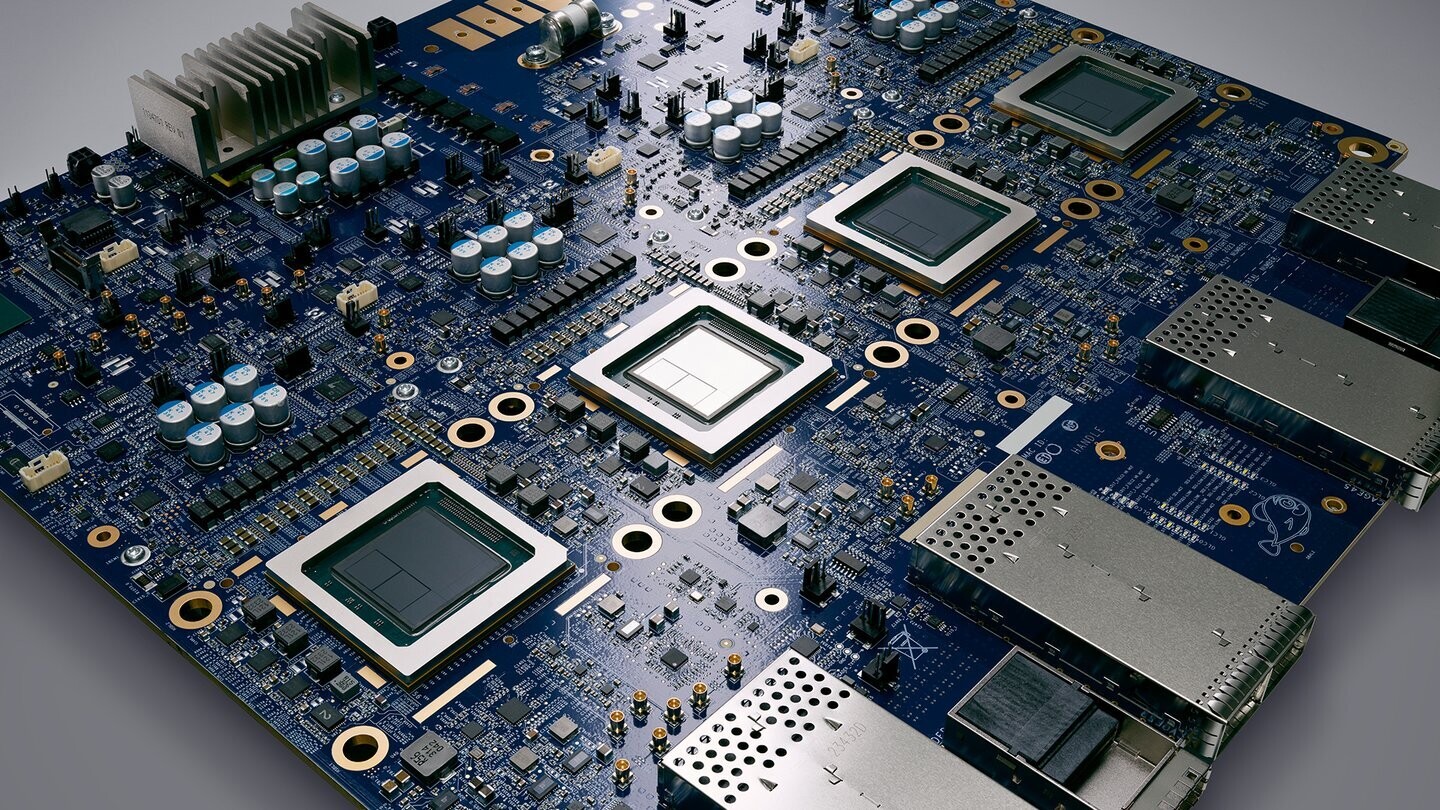
Today at Google Cloud Next, we are introducing the eighth generation of Google's custom Tensor Processor Unit (TPU), coming soon with two distinct, purpose-built architectures for training and inference: TPU 8t and TPU 8i. These two chips are designed to power our custom-built supercomputers, to drive everything from cutting-edge model training and agent development, to massive inference workloads. TPUs have been powering leading foundation models, including Gemini, for years. These 8th generation TPUs together will deliver scale, efficiency and capabilities across training, serving and agentic workloads.

In this age of AI agents, models must reason through problems, execute multistep workflows and learn from their own actions in continuous loops. This places a new set of demands on infrastructure, and TPU 8t and TPU 8i were designed in partnership with Google DeepMind to take on the most demanding AI workloads and adapt to evolving model architectures at scale.

Intel Foundry Nears Major Customer Wins as Apple, AMD, Google, and NVIDIA Weigh Deals

Intel Foundry has been attracting significant attention from the industry lately, with some of the world's largest companies expected to announce new foundry commitments this fall, according to UBS Group. The investment bank has reported that Intel Foundry is on the brink of securing many new contracts scheduled for this fall, citing the release of version 1.0 of the 14A node process design kit (PDK) as a key catalyst. There have been numerous rumors that Apple, AMD, NVIDIA, Google, and Broadcom are considering utilizing Intel's silicon manufacturing, including the 18A, 18A-P, and 18A-PT nodes, as well as the upcoming 14A node. Apple is rumored to manufacture some of its M-Series "Apple Silicon" laptop processors in 2027 using the 18A-P node, while Google might leverage Intel's EMIB and Foveros 3D advanced packaging technology for some of its TPU designs.

Companies regularly evaluate leading industry nodes but often choose TSMC's manufacturing due to its reliability, high volume capacity, and advanced packaging, which has produced numerous high-performance and low-power designs at scale. However, Intel Foundry has been investing significant resources and logistics into attracting external clients, leading UBS to anticipate multiple foundry commitments being announced this fall. Late last year, we learned that Apple was waiting for Intel to release the 18A-P PDK version 1.0 or 1.1, scheduled for Q1 and Q2 of 2026, respectively. As we are now in Q2, we are awaiting further confirmation to see if Apple proceeded with the deal, but UBS expects it did.

AI Arms Race Targets Google TPUs as DOJ Charges Ex-Googler with Espionage

The AI arms race is now in full swing, and corporate espionage is reaching levels beyond what we previously imagined. According to the United States Department of Justice (DOJ), former Google software engineer Linwei Ding has been convicted of economic espionage and theft of confidential AI technology, specifically related to Google Tensor Processing Units (TPUs). An FBI investigation revealed that the ex-Googler was suspected of stealing information about the entire infrastructure surrounding TPUs, including chip architecture, external connectivity, and more. The DOJ concluded that Linwei Ding was acting for the benefit of the People's Republic of China (PRC), with the primary goal of stealing sensitive intellectual property that Google has spent years and billions of US Dollars developing. Naturally, Google collaborated with the FBI to protect its intellectual property and found the former employee guilty of stealing as many as two thousand pages of confidential information.
U.S. Department of JusticeThe trade secrets contained detailed information about the architecture and functionality of Google's custom Tensor Processing Unit chips and systems and Google's Graphics Processing Unit systems, the software that allows the chips to communicate and execute tasks, and the software that orchestrates thousands of chips into a supercomputer capable of training and executing cutting-edge AI workloads. The trade secrets also pertained to Google's custom-designed SmartNIC, a type of network interface card used to facilitate high speed communication within Google's AI supercomputers and cloud networking products.

Microsoft Introduces Its Newest AI Accelerator: Maia 200

Today, we're proud to introduce Maia 200, a breakthrough inference accelerator engineered to dramatically improve the economics of AI token generation. Maia 200 is an AI inference powerhouse: an accelerator built on TSMC's 3 nm process with native FP8/FP4 tensor cores, a redesigned memory system with 216 GB HBM3e at 7 TB/s and 272 MB of on-chip SRAM, plus data movement engines that keep massive models fed, fast and highly utilized. This makes Maia 200 the most performant, first-party silicon from any hyperscaler, with three times the FP4 performance of the third generation Amazon Trainium, and FP8 performance above Google's seventh generation TPU. Maia 200 is also the most efficient inference system Microsoft has ever deployed, with 30% better performance per dollar than the latest generation hardware in our fleet today.

Maia 200 is part of our heterogenous AI infrastructure and will serve multiple models, including the latest GPT-5.2 models from OpenAI, bringing performance per dollar advantage to Microsoft Foundry and Microsoft 365 Copilot. The Microsoft Superintelligence team will use Maia 200 for synthetic data generation and reinforcement learning to improve next-generation in-house models. For synthetic data pipeline use cases, Maia 200's unique design helps accelerate the rate at which high-quality, domain-specific data can be generated and filtered, feeding downstream training with fresher, more targeted signals.

MediaTek Reportedly Prioritizing Development of AI ASICs Over Mobile Chips

MediaTek's growing partnership with Google has reportedly prompted a shift in development priorities; industry insiders propose an ongoing "realignment" of internal resources. The alleged formation of a dedicated ASIC division seems to be draining staff away from the more visible Dimensity mobile chip projects—by previous announcements, a very important aspect of the Taiwanese fabless semiconductor firm's business. Going back to March 2025, MediaTek and Google partnered up on the making of a seventh-gen "Ironwood" Tensor Processing Unit (TPU) design. Later in the year, it emerged that MediaTek engineers were assisting on Google's even more futuristic "Zebrafish" TPUv8x project.

Industry analysts posit that the demands of formulating Google's complex/intricate 3 nm TPU v7 design has taken precedence within MediaTek operations; prompting the rumored formation of a full-fledged ASIC department. Another key factor seems to be a tight timeline that leads to significant volume orders of Google TPUs. According to a Commercial Times Taiwan news article, mass production is expected to start within the third quarter of 2026. Future targets include five million units pumped out by 2027, followed by an ambitious seven million unit goal in 2028. Similarly, Broadcom is "actively preparing production capacity" for its Google TPU collaboration. Local reportage points out that Rick Tsai—MediaTek's Vice Chairman and CEO—anticipates pleasing financial results related to his team's "first ASIC project." Smooth progress in 2026 could lead to an approximate $1 billion revenue contribution, with forecasts of several billion dollars in 2027. Another major earner could emerge from a speculated deal with Meta—MediaTek's second ASIC project is said to be based on an unnamed 2 nm node process.

NVIDIA Powers Nearly 72% of Cloud Accelerator Locations, AMD at 5.8%

The cloud accelerator market share study was conducted at UBS bank, one of the leading research hubs and close followers of market trends. According to UBS, NVIDIA commands 71.2% of the cloud accelerator location share, which includes GPUs and other types of ASICs. The study also included AMD, and other ASICs. For the AMD front, the situation is entirely different as the data shows AMD only captures 5.8% of the cloud accelerator location share. The remaining portion is split between ASICs designed by the likes of AWS, Meta, Broadcom, MediaTek, and many others, which command 22.3%.

For NVIDIA, the company has managed to penetrate its GPUs in 258 datacenter locations, serving as cloud GPU providers. This is a significant number considering that some of these customers are ordering tens and even hundreds of thousands of GPUs at once, especially as the demand expands. NVIDIA is still the backbone of the entire AI infrastructure, and even its older GPUs, which include A100 and H100, are capturing a significant part of the GPU cloud market share. As "Blackwell" SKUs, designed for a million GPU scale systems, are scaled, and we enter the "Rubin" era, NVIDIA's lead may only expand.

Google Prepares TPUv8ax for Training and TPUv8x for Inference

Google's custom AI infrastructure is beginning to draw external interest, and the company has reportedly developed two new TPU versions: one designed for AI inference and another optimized for training. With the eighth generation of TPU designs, Google has introduced the TPUv8ax "Sunfish" for training AI models like Gemini, and the TPUv8x "Zebrafish" for large-scale model inference. For "Sunfish," Google has partnered with Broadcom and its custom design team, which handles end-to-end design, memory, supporting hardware, and packaging, providing Google with a finished product ready for integration into its extensive server infrastructure.

For the inference-focused "Zebrafish" TPUv8x, Google has enlisted MediaTek's assistance, but only in a limited capacity. Google is sourcing wafers and memory directly from suppliers, while MediaTek contributes to supporting chips and packaging efforts, areas where Google has limited expertise. This means that a lot of chip design efforts are now processed in-house, easing reliance on external partners. However, since Google is not yet up to speed with the full-stack chip design, some help is still needed. The concrete performance figures and memory capacities are still unknown. However, we expect another leap over the TPUv7 "Ironwood," which carries 4,614 TeraFLOPS at FP8 precision and 192 GB of HBM memory.

Tachyum Defends TPU Trademark from Infringement by Google TPU

Tachyum announced that it is beginning to take steps to defend the use of its registered TPU trademark. Tachyum initially applied for trademark status in September 2015 and has held the rights to TPU (for its AI Tachyum Processing Unit) since October 2020. Google recently filed for similar trademark protection of Google TPU for its Tensor Processing Unit on November 21st of this year.

Tachyum is requesting Google to stop using TPU as a part of a descriptor for its Google TPU and will petition the U.S. Trademark Office to defend its legal claims to the term. Trademarks are important and valuable property of companies in much the same way that patents, copyrights and other intellectual property assignments are. Tachyum offers its TPU AI intellectual property as a licensable core, allowing developers to take full advantage of intelligent, datacenter-trained AI when making IoT and Edge devices. Tachyum is the only owner of the TPU trademark within the AI space.

China Eyes Chip-Stacking Path to Narrow the Gap with NVIDIA

China's semiconductor industry is looking to bridge its technology gap with NVIDIA by stacking mature logic nodes with high-bandwidth memory and new compute architectures, according to remarks from Wei Shaojun, vice president of the China Semiconductor Industry Association. Speaking at an event in Shenzhen (via ESM China), Wei said that 14 nm logic chips, far behind the 4 nm-class silicon used in NVIDIA's current AI GPUs, could reach comparable performance if paired with 18 nm DRAM using 3D hybrid bonding and a near-memory computing architecture. The approach reduces data movement and improves energy efficiency by placing compute elements directly beside memory. The concept mirrors Huawei's recent strategy of "stacking and clustering" chips as a workaround to US export controls, which block China's access to advanced nodes such as 5 nm and below. Huawei has argued that performance can still scale by increasing chip integration density instead of relying on cutting-edge lithography.

Wei emphasized that his proposed design uses a fully domestic supply chain, 14 nm logic and 18 nm DRAM are both covered by current US export restrictions, limiting access to foreign production. He also noted that the global AI ecosystem remains heavily dependent on NVIDIA hardware and CUDA software, calling it a "triple dependence" across models, architectures, and development tools. Chinese GPU alternatives are emerging, including Zhonghao Xinying, a startup founded by Google engineer Yanggong Yifa. The company claims its custom ASIC TPU accelerator can reach "up to 1.5x" the compute performance of NVIDIA's older A100 GPU.

Google's Gemini AI Wins a Gold Medal at International Math Olympiad

The inflection point for difficult problem-solving using AI has arrived as Google's best AI model, Gemini with Deep Thinking enabled, has officially won a gold medal at the International Math Olympiad (IMO). Solving some of the world's toughest math challenges involves reasoning and logic that often require unique solutions and creative approaches. Google's DeepMind team has officially verified these results, and IMO President Prof. Dr. Gregor Dolinar noted that "We can confirm that Google DeepMind has reached the much-desired milestone, earning 35 out of a possible 42 points—a gold medal score. Their solutions were astonishing in many respects. IMO graders found them to be clear, precise and most of them easy to follow."

While this may seem like a "computers are good at math" moment, it is fundamentally different. The Gemini model used here employs end-to-end natural processing, utilizing text inputs from problem descriptions to generate mathematical proofs in a manner that IMO graders found clear and precise. Google's performance this year was due to an upgraded version of Gemini Deep Think, an enhanced reasoning layer designed to tackle complex questions. The design integrates the company's latest research, including parallel thinking, allowing the model to explore and synthesize multiple solution paths simultaneously before committing to a final answer, thereby moving beyond a single linear chain of reasoning. All of this is proof that AI's reasoning is slowly advancing into self-sufficient data processing, which can be achieved through a multistep, layered approach. Google's Gemini officially completed all of this within a 4.5-hour time window, qualifying it for an achievement.

NVIDIA's Dominance Challenged as Largest AI Lab Adopts Google TPUs

NVIDIA's AI hardware dominance is challenged as the world's leading AI lab, OpenAI, taps into Google TPU hardware, showing significant efforts to move away from single-vendor solutions. In June 2025, OpenAI began leasing Google Cloud's Tensor Processing Units to handle ChatGPT's increasing inference workload. This is the first time OpenAI has relied on non-NVIDIA chips in large-scale production. Until recently, NVIDIA GPUs powered both model training and inference for OpenAI's products. Training large language models on those cards remains costly, but it was a periodic process. Inference, by contrast, runs continuously and carries its own substantial expense. ChatGPT now serves more than 100 million daily active users, including 25 million paid subscribers. Inference operations account for nearly half of OpenAI's estimated $40 billion annual compute budget. Google's TPUs, like v6e "Trillium" provide a more cost-effective solution for steady-state inference, as they are designed specifically for high throughput and low latency.

Beyond cost savings, this decision reflects OpenAI's desire to reduce reliance on any single vendor. Microsoft Azure has been its primary cloud provider since early investments and collaborations. However, GPU supply shortages and price fluctuations exposed a weakness in relying too heavily on a single source. By adding Google Cloud to its infrastructure mix, OpenAI gains greater flexibility, avoids vendor lock-in, and can scale more smoothly during usage peaks. For Google, winning OpenAI as a TPU customer offers strong validation for its in-house chip development. TPUs were once reserved almost exclusively for internal projects such as powering the Gemini model. Now, they are attracting leading organizations like Apple and Anthropic. Note that, beyond v6e inference, Google also designs TPUs for training (yet-to-be-announced v6p), which means companies can scale their entire training runs on Google's infrastructure on demand.

AMD Radeon RX 9070 GRE Spotted in GPU-Z v2.65.1 Support List

Earlier in the month, keen observers of Team Red activities were taken aback by whispers of a mysterious Radeon RX 9070 GRE GPU. Up until then, many assumed that AMD's engineering team was readying Radeon RX 9060 Series cards for launch in Q2'25. A source in China claimed that the next wave of RDNA 4 would arrive in the shape of a not-yet-official "Great Radeon Edition" (GRE) design; allegedly derived from Team Red's Navi 48 GPU die. Certain groups of skeptics have questioned the validity of this leak; many believe that the speculated Radeon RX 9060 XT model will launch ahead of a rumored GRE sibling.

Late last week, TechPowerUp's GPU-Z utility was updated to version 2.65.0 form—supported hardware lists were populated with several new additions. As highlighted by VideoCardz, the presence of Radeon RX 9070 GRE and NVIDIA GeForce RTX 5060 Ti 16 GB GPUs points to potential imminent releases. In the case of Team Green, lower end "Blackwell" graphics cards are launching this week—as disclosed by insiders. AMD's Radeon RX 9070 GRE 12 GB card is expected to release as a Chinese market exclusive; possibly as a substitute for "difficult to acquire" Radeon RX 9070 16 GB (non-XT) AIB products.

Safe Superintelligence Inc. Uses Google TPUs Instead of Regular GPUs for Next-Generation Models

It seems like Google aims to grab a bit of the market share from NVIDIA and AMD by offering startups large compute deals and allowing them to train their massive AI models on the Google Cloud Platform (GCP). One such case is the OpenAI co-founder Ilya Sutskever's Safe Superintelligence Inc. (SSI) startup. According to a GCP post, SSI is "partnering with Google Cloud to use TPUs to accelerate its research and development efforts toward building a safe, superintelligent AI." Google's latest TPU v7p, codenamed Ironwood, was released yesterday. Carrying 4,614 TeraFLOPS of FP8 precision and 192 GB of HBM memory, these TPUs are interconnected using Google's custom ICI infrastructure and are scaled to configurations in pods of 9,216 chips, where Ironwood delivers 42.5 ExaFLOPS of total computing power.

For AI training, this massive power will allow AI models to quickly go over training, accelerating research iterations and ultimately accelerating model development. For SSI, the end goal is a simple mission: achieving ASI with safety at the front. "We approach safety and capabilities in tandem, as technical problems to be solved through revolutionary engineering and scientific breakthroughs. We plan to advance capabilities as fast as possible while making sure our safety always remains ahead," notes the SSI website, adding that "Our singular focus means no distraction by management overhead or product cycles, and our business model means safety, security, and progress are all insulated from short-term commercial pressures."

Google Unveils Seventh-Generation AI Processor: Ironwood

Google has rolled out its seventh-generation AI chip, Ironwood, which aims to boost AI application performance. This processor focuses on "inference" computing—the quick calculations needed for chatbot answers and other AI outputs. Ironwood stands as one of the few real options to NVIDIA's leading AI processors coming from Google's ten-year multi-billion-dollar push to develop it. These tensor processing units (TPUs) are exclusively available through Google's cloud service or to its internal engineers.

According to Google Vice President Amin Vahdat, Ironwood combines functions from previously separate designs while increasing memory capacity. The chip can operate in groups of up to 9,216 processors and delivers twice the performance-per-energy ratio compared to last year's Trillium chip. When configured in pods of 9,216 chips, Ironwood delivers 42.5 Exaflops of computing power. This is more than 24 times the computational capacity of El Capitan, currently the world's largest supercomputer, which provides only 1.7 Exaflops per pod.

Google Teams up with MediaTek for Next-Generation TPU v7 Design

According to Reuters, citing The Information, Google will collaborate with MediaTek to develop its seventh-generation Tensor Processing Unit (TPU), which is also known as TPU v7. Google maintains its existing partnership with Broadcom despite the new MediaTek collaboration. The AI accelerator is scheduled for production in 2026, and TSMC is handling manufacturing duties. Google will lead the core architecture design while MediaTek manages I/O and peripheral components, as Economic Daily News reports. This differs from Google's ongoing relationship with Broadcom, which co-develops core TPU architecture. The MediaTek partnership reportedly stems from the company's strong TSMC relationship and lower costs compared to Broadcom.

There is also a possibility that MediaTek could design inference-focused TPU v7 chips while Broadcom focuses on training architecture. Nonetheless, the development of TPU is a massive market as Google is using so many chips that it could use a third company, hypothetically. The development of TPU continues Google's vertical integration strategy for AI infrastructure. Google reduces dependency on NVIDIA hardware by designing proprietary AI chips for internal R&D and cloud operations. At the same time, competitors like OpenAI, Anthropic, and Meta rely heavily on NVIDIA's processors for AI training and inference. At Google's scale, serving billions of queries a day, designing custom chips makes sense from both financial and technological sides. As Google develops its own specific workloads, translating that into hardware acceleration is the game that Google has been playing for years now.

Lenovo Releases Two New Duet Chromebooks

Lenovo elevates productivity and enjoyment on-the-go with Chromebook Duet (11", 9) and Chromebook Duet EDU G2, two 10.95-inch convertible laptops with 2K display that balance design and performance. Encased in a full metal chassis with Corning Gorilla Glass for ultimate durability and complemented by a soft protective folio, the Chromebook Duet (11", 9) is a portable companion that entertains, adapts, and encourages you to create. A learning resource for students and teachers, the Chromebook Duet EDU G2 takes durability to the next level with a rugged case and detachable keyboard.

"Modern society is constantly on the move, a challenge to traditional notions of productivity and leisure based on being stationary, while underscoring the necessity of having a portable and efficient laptop," said Benny Zhang, Executive Director and General Manager of Chromebooks in Lenovo's Intelligent Devices Group. "The Lenovo Chromebook Duet and Lenovo Chromebook Duet EDU G2 powered by MediaTek Kompanio 838 processor with AI-enabled NPU are versatile companions for work, play, learning and everything in between."

Apple Trained its Apple Intelligence Models on Google TPUs, Not NVIDIA GPUs

Apple has disclosed that its newly announced Apple Intelligence features were developed using Google's Tensor Processing Units (TPUs) rather than NVIDIA's widely adopted hardware accelerators like H100. This unexpected choice was detailed in an official Apple research paper, shedding light on the company's approach to AI development. The paper outlines how systems equipped with Google's TPUv4 and TPUv5 chips played a crucial role in creating Apple Foundation Models (AFMs). These models, including AFM-server and AFM-on-device, are designed to power both online and offline Apple Intelligence features introduced at WWDC 2024. For the training of the 6.4 billion parameter AFM-server, Apple's largest language model, the company utilized an impressive array of 8,192 TPUv4 chips, provisioned as 8×1024 chip slices. The training process involved a three-stage approach, processing a total of 7.4 trillion tokens. Meanwhile, the more compact 3 billion parameter AFM-on-device model, optimized for on-device processing, was trained using 2,048 TPUv5p chips.

Apple's training data came from various sources, including the Applebot web crawler and licensed high-quality datasets. The company also incorporated carefully selected code, math, and public datasets to enhance the models' capabilities. Benchmark results shared in the paper suggest that both AFM-server and AFM-on-device excel in areas such as Instruction Following, Tool Use, and Writing, positioning Apple as a strong contender in the AI race despite its relatively late entry. However, Apple's penetration tactic into the AI market is much more complex than any other AI competitor. Given Apple's massive user base and millions of devices compatible with Apple Intelligence, the AFM has the potential to change user interaction with devices for good, especially for everyday tasks. Hence, refining AI models for these tasks is critical before massive deployment. Another unexpected feature is transparency from Apple, a company typically known for its secrecy. The AI boom is changing some of Apple's ways, and revealing these inner workings is always interesting.
OpenAI in Talks with Broadcom About Developing Custom AI Chips to Power Next Generation Models

According to The Information, OpenAI is reportedly in talks with Broadcom about developing a custom AI accelerator to power OpenAI's growing demand for high-performance solutions. Broadcom is a fabless chip designer known for a wide range of silicon solutions spanning from networking, PCIe, SSD controllers, and PHYs all the way up to custom ASICs. The latter part is what OpenAI wants to focus on, but all the aforementioned IP developed by Broadcom is of use in a data center. Suppose OpenAI decides to use Broadcom's solutions. In that case, the fabless silicon designer offers a complete vertical stack of products for inter-system communication using various protocols such as PCIe, system-to-system communication using Ethernet networking with Broadcom Tomahawk 6 and future revisions, alongside storage solutions and many other complimentary elements of a data center.

As a company skilled in making various IPs, it also makes ASIC solutions for other companies and has assisted Google in the making of its Tensor Processing Unit (TPU), which is now in its sixth generation. Google TPUs are massively successful as Google deploys millions of them and provides AI solutions to billions of users across the globe. Now, OpenAI wants to be part of the AI chip game, and Broadcom could come to the rescue with its already-established AI success and various other data center componentry to help make a custom AI accelerator to power OpenAI's infrastructure needed for the next generation of AI models. With each new AI model released by OpenAI, compute demand spikes by several orders of magnitude, and having an AI accelerator that exactly matches their need will help the company move faster and run even bigger AI models.

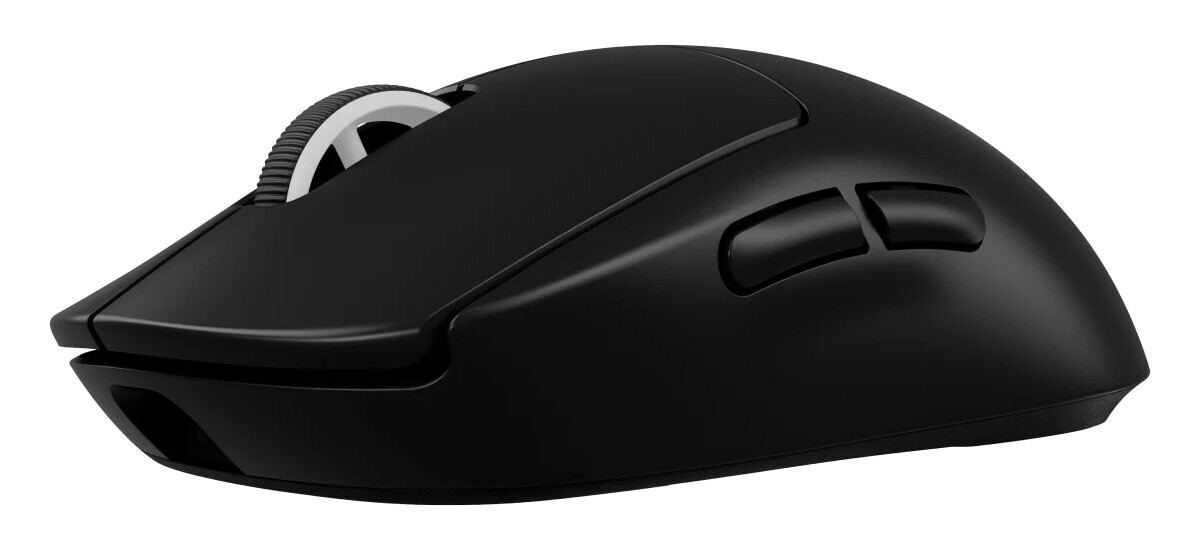
Logitech G Pro X Superlight 2 Gets 4 kHz Response Rate Upgrade

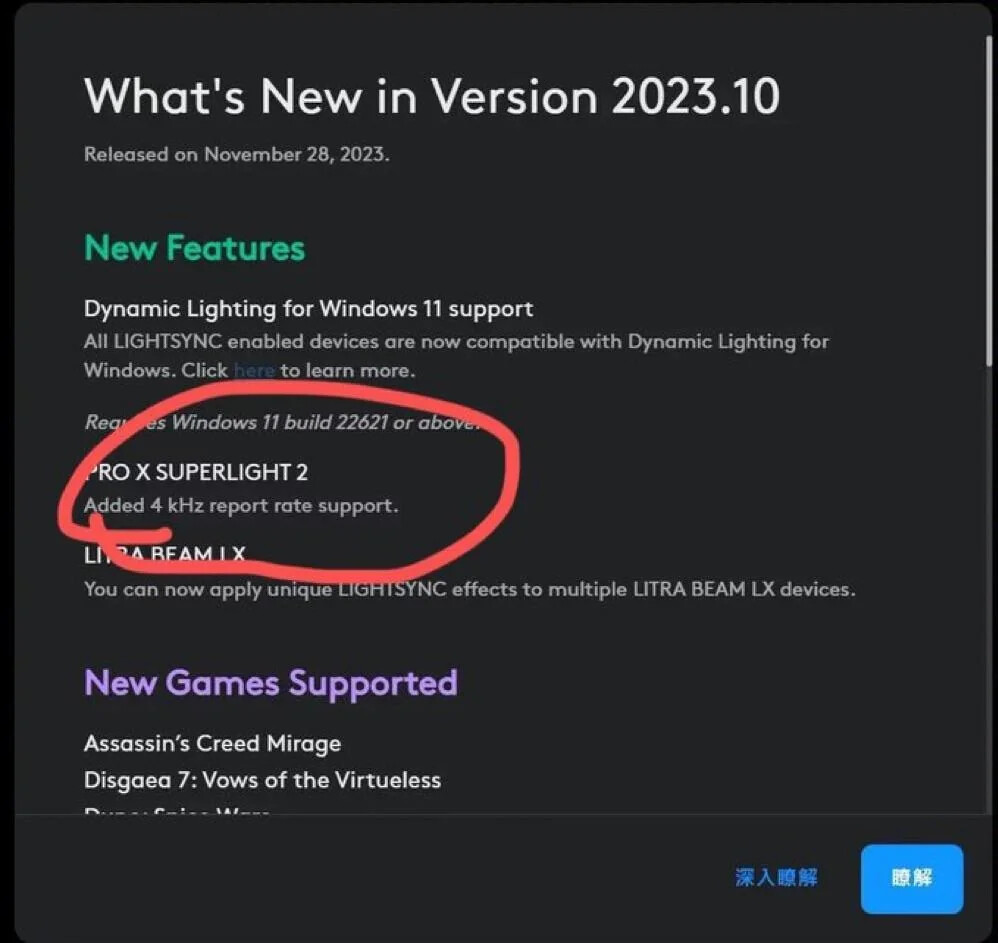
Logitech's G PRO X SUPERLIGHT 2 wireless gaming mouse arrived last September with an MSRP of $159—at the time, cutting-edge peripheral enthusiasts were expecting a mighty upgrade over the ultra popular 2020 iteration. TPU's resident mouse guru—pzogel—had a "hard time making a case for the Pro X Superlight 2," when comparing it to the preceding model. Additionally, the Superlight 2's closest rival—Razer's Viper V2 Pro when combined with their 4K HyperPolling Wireless Dongle—was deemed technologically superior. A November 2023 leak revealed that Logitech was readying an intriguing firmware update—the Superlight 2 was set to be upgraded with a 4 kHz report rate mode.

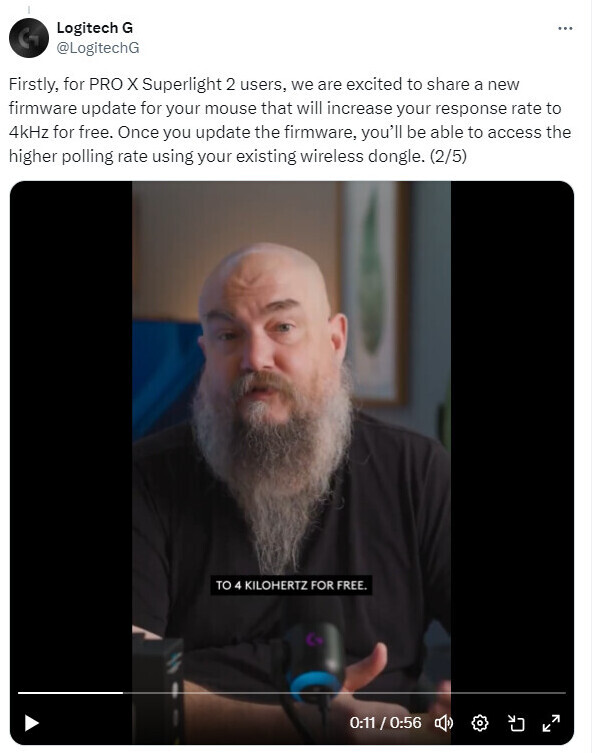
The launch specification of 2 kHz (maximum) was a disappointing aspect, considering that many cheaper alternatives had already rolled out with higher polling rates (via external dongles). Logitech's latest G HUB software update brings good news for PRO X Superlight 2 users: "we are excited to share a new firmware update for your mouse that will increase your report rate to 4 kHz for free. Once you update the firmware, you'll be able to access the higher report rate in G HUB using your existing wireless dongle. For more information, visit our YouTube channel for an update from Chris Pate." In TPU's late October review, pzogel noted that the 2000 Hz rate: "comes at a price, which is reduced battery life." We hope to see a revisit with the newly implemented 4000 Hz mode tested out.

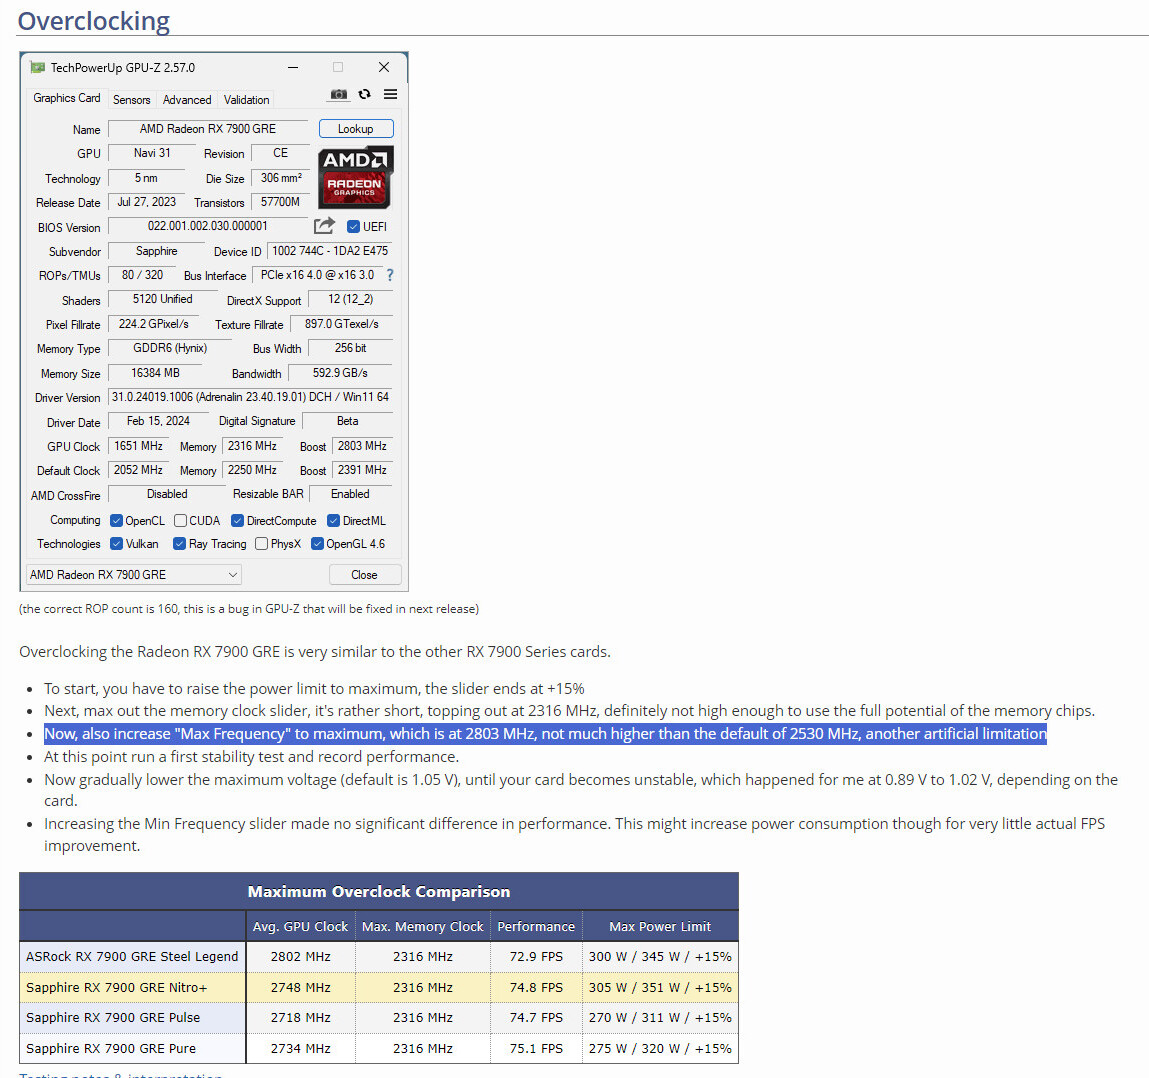
AMD to Address "Bugged" Limited Overclocking on Radeon RX 7900 GRE GPU

TechPowerUp's resident GPU reviewer extraordinaire—W1zzard—has grappled with a handful of custom design AMD Radeon RX 7900 GRE 16 GB models. Team Red and its board partners are pushing a proper/widespread Western release of the formerly China market-exclusive "Golden Rabbit Edition" GPU. TPU's initial review selection of three Sapphire cards and a lone ASRock Steel Legend OC variant garnered two Editor's Choice Awards, and two Highly Recommended badges. Sapphire's Radeon RX 7900 GRE Nitro+ was also honored with a "...But Expensive" tag, due to its MSRP of $600—the premium tier design was one of last year's launch day models in China. Western reviewers have latched onto a notable GRE overclocking limitation—all of TPU's review samples were found to have "overclocking artificially limited by AMD." Steve Walton of Hardware Unboxed has investigated whether the GRE's inherent heavily limited power specification was less of an issue on Sapphire's Nitro+ variant—check out his "re-re-review" video below.

The higher board power design—305 W OC TGP limit and 351 W total board power—is expected to exhibit "up to 10% higher performance than Radeon RX 7800 XT" according to VideoCardz, but falls short. TPU's W1zzard found the GRE Nitro+ card's maximum configurable clock of 2803 MHz: "Overclocking worked quite well on our card, we gained over 8% in real-life performance, which is well above what we usually see, but less than other GRE cards tested today. Sapphire's factory OC eats into OC potential, and maximizes performance out of the box instead. Unfortunately AMD restricted overclocking on their card quite a lot, probably to protect sales of the RX 7900 XT. While NVIDIA doesn't have any artificial limitations for overclockers, AMD keeps limiting the slider lengths for many models, this is not a gamer-friendly approach. For the GRE, both GPU and memory overclocking could definitely go higher based on the results that we've seen in our reviews today." An AMD representative has contacted Hardware Unboxed, in reaction to yesterday's Update review—the GRE's overclocking limitation is a "bug," and a fix is in the works. This situation is a bit odd, given that the Golden Rabbit Edition is not a brand-new product.

Google Faces Potential Billion-Dollar Damages in TPU Patent Dispute

Tech giant Google is embroiled in a high-stakes legal battle over the alleged infringement of patents related to its Tensor Processing Units (TPUs), custom AI accelerator chips used to power machine learning applications. Massachusetts-based startup Singular Computing has accused Google of incorporating architectures described in several of its patents into the design of the TPU without permission. The disputed patents, first filed in 2009, outline computer architectures optimized for executing a high volume of low-precision calculations per cycle - an approach well-suited for neural network-based AI. In a 2019 lawsuit, Singular argues that Google knowingly infringed on these patents in developing its TPU v2 and TPU v3 chips introduced in 2017 and 2018. Singular Computing is seeking between $1.6 billion and $5.19 billion in damages from Google.

Google denies these claims, stating that its TPUs were independently developed over many years. The company is currently appealing to have Singular's patents invalidated, which would undermine the infringement allegations. The high-profile case highlights mounting legal tensions as tech giants race to dominate the burgeoning field of AI hardware. With billions in potential damages at stake, the outcome could have major implications for the competitive landscape in cloud-based machine learning services. As both sides prepare for court, the dispute underscores the massive investments tech leaders like Google make to integrate specialized AI accelerators into their cloud infrastructures. Dominance in this sphere is a crucial strategic advantage as more industries embrace data-hungry neural network applications.

Update 17:25 UTC: According to Reuters, Google and Singular Computing have settled the case with details remaining private for the time being.

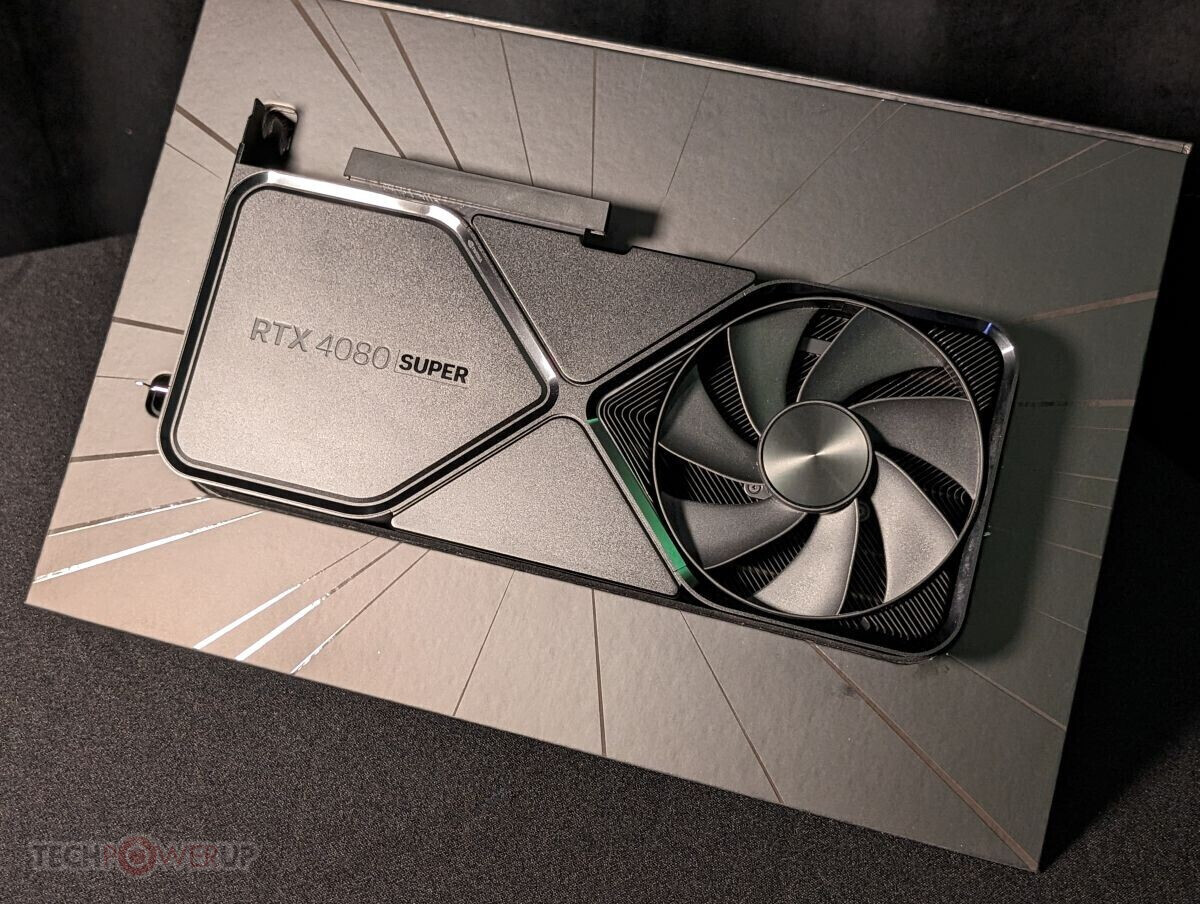
NVIDIA GeForce RTX 4080 SUPER GPUs Pop Up in Geekbench Browser

We are well aware that NVIDIA GeForce RTX 4080 SUPER graphics cards are next up on the review table (January 31)—TPU's W1zzard has so far toiled away on getting his evaluations published on time for options further down the Ada Lovelace SUPER food chain. This process was interrupted briefly by the appearance of custom Radeon RX 7600 XT models, but today's attention soon returned to another batch of GeForce RTX 4070 Ti SUPER cards. Reviewers are already toying around with driver-enabled GeForce RTX 4080 SUPER sample units—under strict confidentiality conditions—but the occasional leak is expected to happen. The appropriately named Benchleaks social media account has kept track of emerging test results.

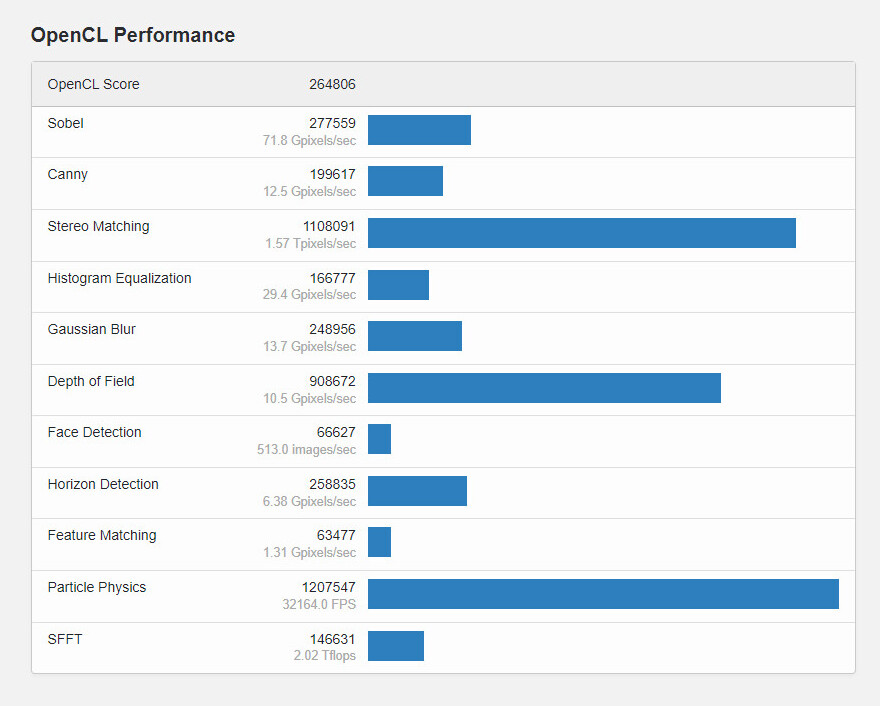
The Geekbench Browser database was updated earlier today with premature GeForce RTX 4080 SUPER GPU test results—one entry highlighted by Benchleaks provides a quick look at the card's prowess in three of Geekbench 5.1's graphics API trials: Vulkan, CUDA and OpenCL. VideoCardz points out that all of the scores could be fundamentally flawed; in particular the Vulkan result of 100378 points—the regular (non-SUPER) GeForce RTX 4080 GPU can achieve almost double that figure in Geekbench 6. The SUPER's other results included a Geekbench 5 CUDA score of 309554, and an achievement of 264806 points in OpenCL. A late morning entrant looks to be hitting the right mark—an ASUS testbed (PRIME Z790-A WIFI + Intel Core i9-13900KF) managed to score 210551 points in Geekbench 6.2.2 Vulkan.

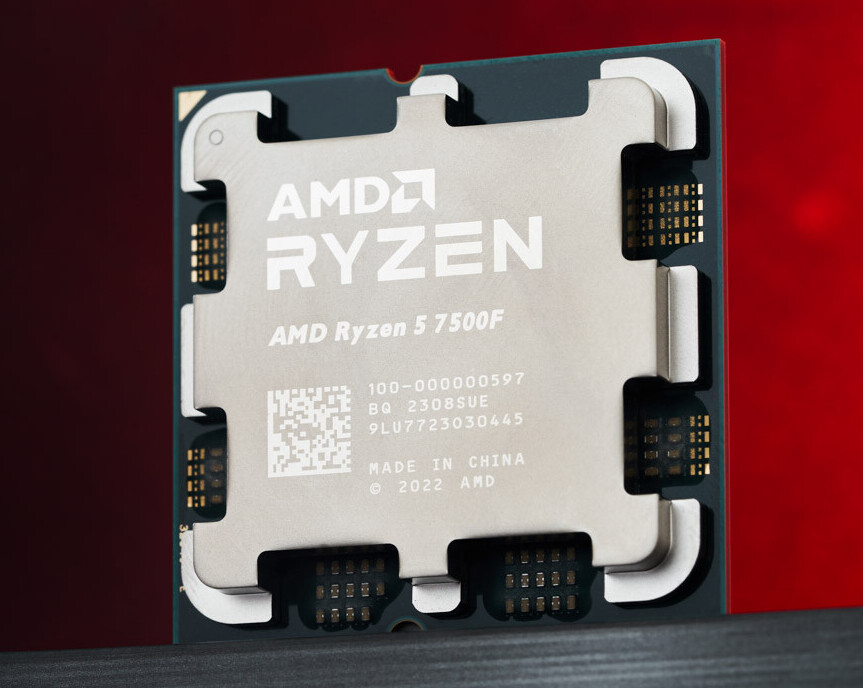
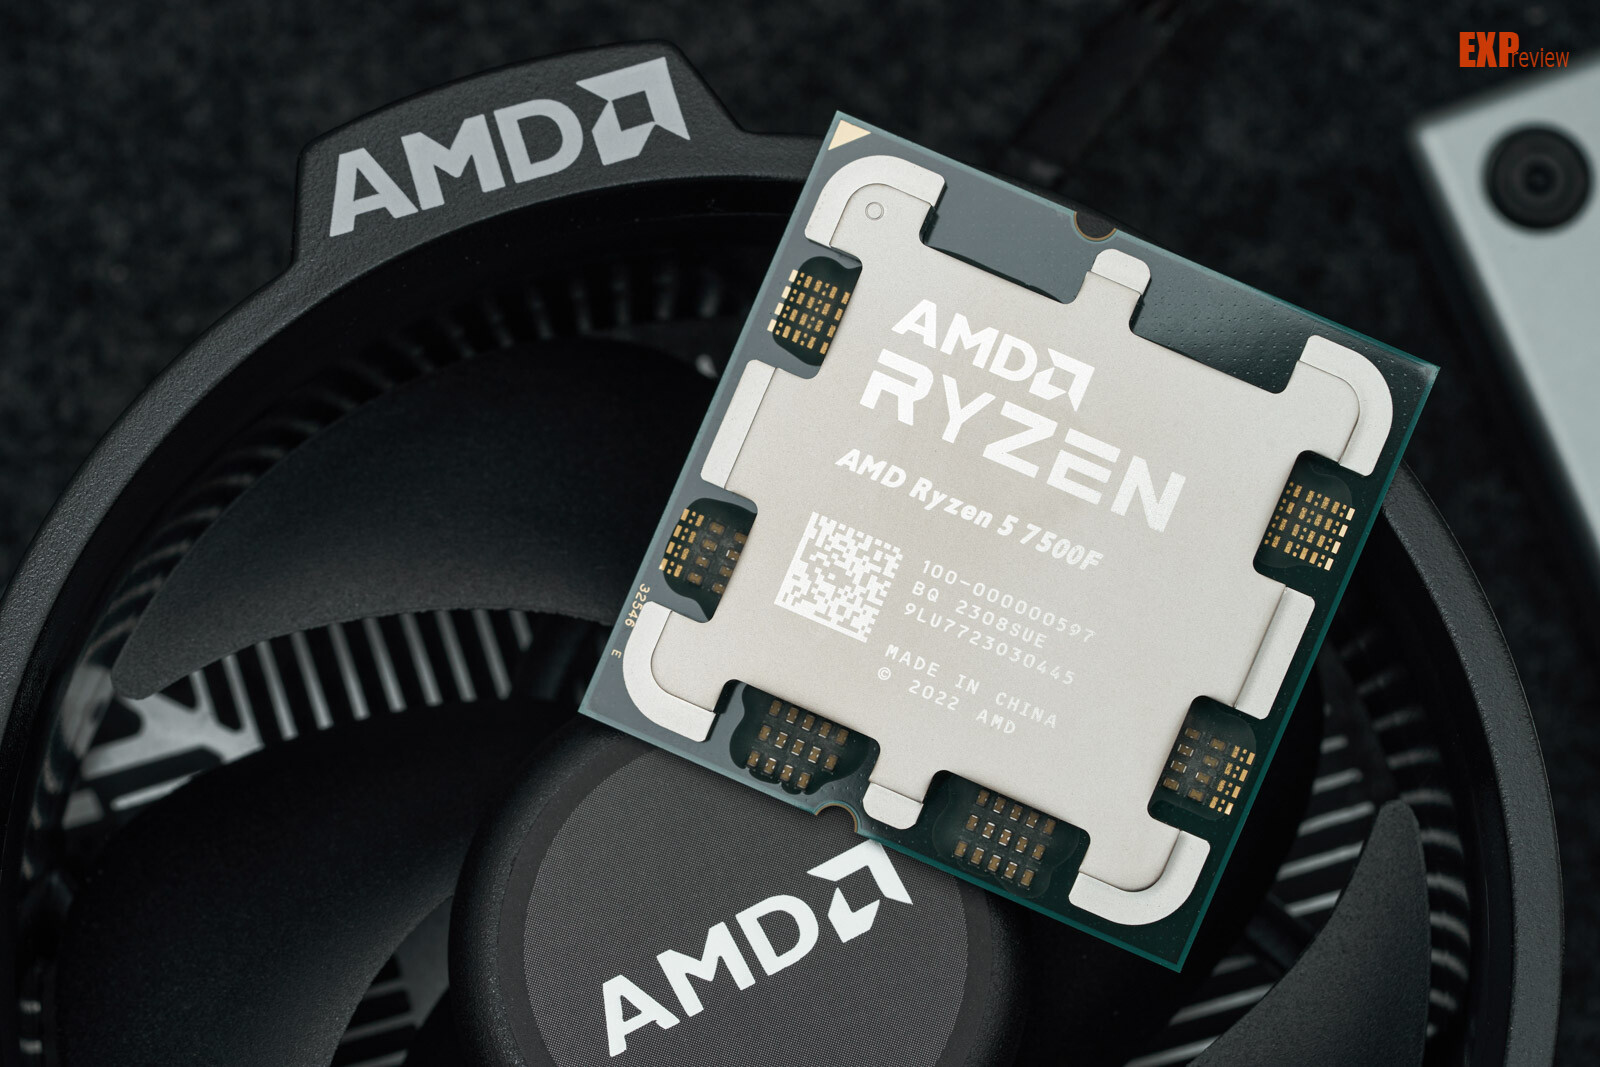
AMD Germany Confirms Ryzen 5 7500F's Western Release Strategy

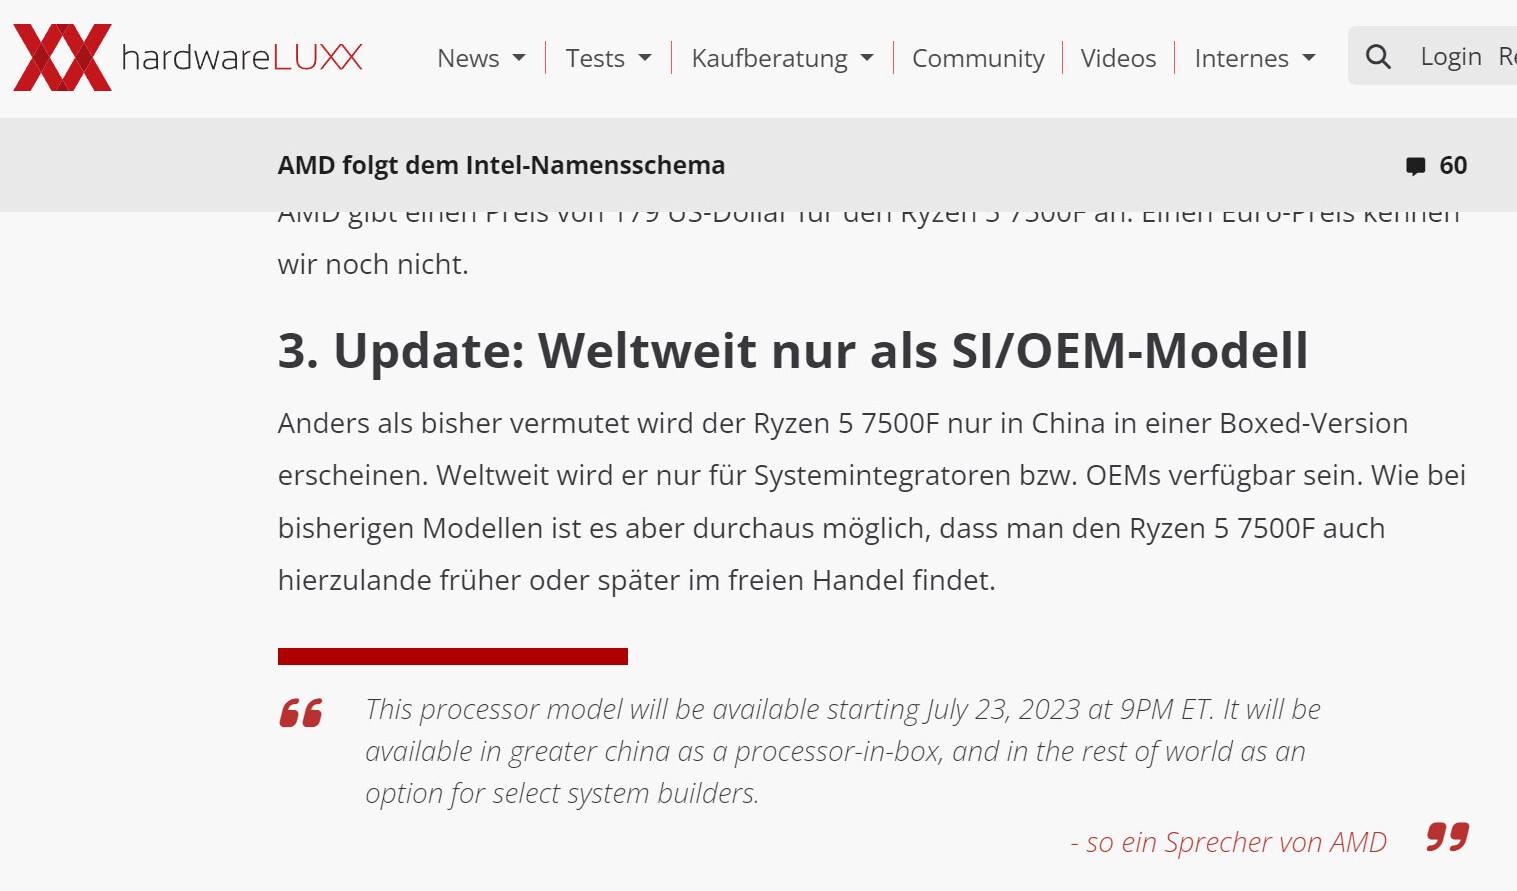
AMD is preparing its Ryzen 5 7500F processor for a global launch according to reports from earlier today—Team Red's German operation has since informed local media outlets about its updated international release strategy for the iGPU-less Zen 4 desktop SKU. Markus Lindner, a regional company spokesman stated: "This processor model will be available starting July 23, 2023 at 9PM ET. It will be available in greater China as a processor-in-box, and in the rest of world as an option for select system builders."

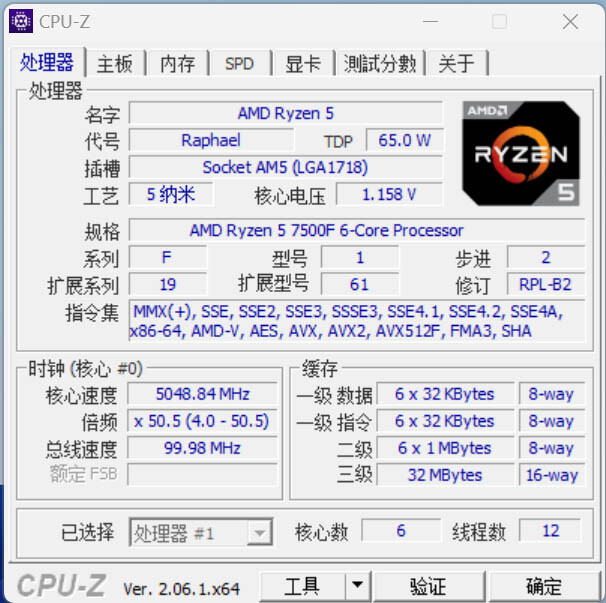
Chinese reviewers have been getting hands-on experience with the Ryzen 5 7500F, with early reports pointing to impressive performance for its price point ($180) when lined up against competing Intel Core i5-13400 and i5-13400F CPUs. International buyers could express concern regarding AMD Germany's mentioning that availability will be somewhat limited to system integrators. Hopefully these "select system builders" will have good distribution links to retail outlets—70% of TPU quick poll participants expressed interest in seeing a western launch (prior to AMD's "global" announcement).
Return to Keyword Browsing
Nov 11th, 2026 03:59 CST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts