Tuesday, January 27th 2015

GTX 970 Memory Drama: Plot Thickens, NVIDIA has to Revise Specs
It looks like NVIDIA's first response to the GeForce GTX 970 memory allocation controversy clearly came from engineers who were pulled out of their weekend plans, and hence was too ambiguously technical (even for us). It's only on Monday that NVIDIA PR swung into action, offering a more user-friendly explanation on what the GTX 970 issue is, and how exactly did they carve the GM204 up, when creating the card.
According to an Anandtech report, which cites that easy explanation from NVIDIA, the company was not truthful about specs of GTX 970, at launch. For example, the non-public document NVIDIA gave out to reviewers (which gives them detailed tech-specs), had clearly mentioned ROP count of the GTX 970 to be 64. Reviewers used that count in their reviews. TechPowerUp GPU-Z shows ROP count as reported by the driver, but it has no way of telling just how many of those "enabled" ROPs are "active." The media reviewing the card were hence led to believe that the GTX 970 was carved out by simply disabling three out of sixteen streaming multiprocessors (SMMs), the basic indivisible subunits of the GM204 chip, with no mention of other components like the ROP count, and L2 cache amount being changed from the GTX 980 (a full-fledged implementation of this silicon).
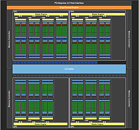 NVIDIA explained to Anandtech that there was a communication-gap between the engineers (the people who designed the GTX 970 ASIC), and the technical marketing team (the people who write the Reviewer's Guide document, and draw the block-diagram). This team was unaware that with "Maxwell," you could segment components previously thought indivisible, or that you could "partial disable" components.
It turns out that in addition to three SMX units being disabled (resulting in 1,664 CUDA cores), NVIDIA reduced the L2 cache (last-level cache) on this chip to 1.75 MB, down from 2 MB, and also disabled a few ROPs. The ROP count is effectively 56, and not 64. The last 8 ROPs aren't "disabled." They're active, but not used, because their connection to the crossbar is too slow (we'll get to that in a bit). The L2 cache is a key component of the "crossbar." Think of the crossbar as a town-square for the GPU, where the various components of the GPU talk to each other by leaving and picking-up data labeled with "from" and "to" addresses. The crossbar routes data between the four Graphics Processing Clusters (GPCs), and the eight memory controllers of 64-bit bus width each (which together make up its 256-bit wide memory interface), and is cushioned by the L2 cache.
The L2 cache itself is segmented, and isn't a monolithic slab of SRAM. Each of the eight memory controllers on the GM204 is ideally tied to its segment of the L2 cache. Also tied to these segments are segments of ROPs. With NVIDIA reducing the L2 cache amount by disabling one such segment. Its component memory controller is instead rerouted to the cache segment of a neighbouring memory controller. Access to the crossbar for that memory controller is hence slower. To make sure there are no issues caused to the interleaving of these memory controllers, adding up to the big memory amount figure that the driver can address, NVIDIA partitioned the 4 GB of memory to two segments. The first is 3.5 GB large, and is made up of memory controllers with access to their own segments of the L2; the second segment is 512 MB in size, and is tied to that memory controller which is rerouted.
The way this partitioning works, is that the 3.5 GB partition can't be read while the 512 MB one is being read. Only to an app that's actively using the entire 4 GB of memory, there will be a drop in performance, because the two segments aren't being read at the same time. The GPU is either addressing the 3.5 GB segment, or the 512 MB one. Hence, there's a drop in performance to be expected, again, for apps that use up the entire 4 GB of memory.
While it's technically correct that the GTX 970 has a 256-bit wide memory interface, and given its 7.00 GHz (GDDR5-effective) memory clock, that translates to 224 GB/s of bandwidth on paper, not all of that memory is uniformly fast. You have 3.5 GB of it having normal access to the crossbar (the town-square of the GPU), and 512 MB of it having slower access. Therefore, the 3.5 GB segment really just has 196 GB/s of memory bandwidth (7.00 GHz x 7 ways to reach the crossbar x 32-bit width per chip), which can be said with certainty. Nor can we say how this segment affects the performance of the memory controller whose crossbar port it's using, if the card is using its full 4 GB. We can't tell how fast the 512 MB second segment really is. But it's impossible for the second segment to make up 28 GB/s (of the 224 GB/s), since NVIDIA itself claims this segment is running slower. Therefore NVIDIA's claims of GTX 970 memory bandwidth being 224 GB/s at reference clocks is inaccurate.
Why NVIDIA chose to reduce cache size and ROP count will remain a mystery. We can't imagine that the people designing the chip will not have sufficiently communicated this to the driver and technical marketing teams. To claim that technical marketing didn't get this the first time around, seems like a hard-sell. We're pretty sure that NVIDIA engineers read reviews, and if they saw "64 ROPs" on a first-page table, they would have reported it up the food-chain at NVIDIA. An explanation about this hardware change should have taken up an entire page in the technical documents the first time around, and NVIDIA could have saved itself a lot of explanation, much of it through the press.
Source:
Anandtech
According to an Anandtech report, which cites that easy explanation from NVIDIA, the company was not truthful about specs of GTX 970, at launch. For example, the non-public document NVIDIA gave out to reviewers (which gives them detailed tech-specs), had clearly mentioned ROP count of the GTX 970 to be 64. Reviewers used that count in their reviews. TechPowerUp GPU-Z shows ROP count as reported by the driver, but it has no way of telling just how many of those "enabled" ROPs are "active." The media reviewing the card were hence led to believe that the GTX 970 was carved out by simply disabling three out of sixteen streaming multiprocessors (SMMs), the basic indivisible subunits of the GM204 chip, with no mention of other components like the ROP count, and L2 cache amount being changed from the GTX 980 (a full-fledged implementation of this silicon).
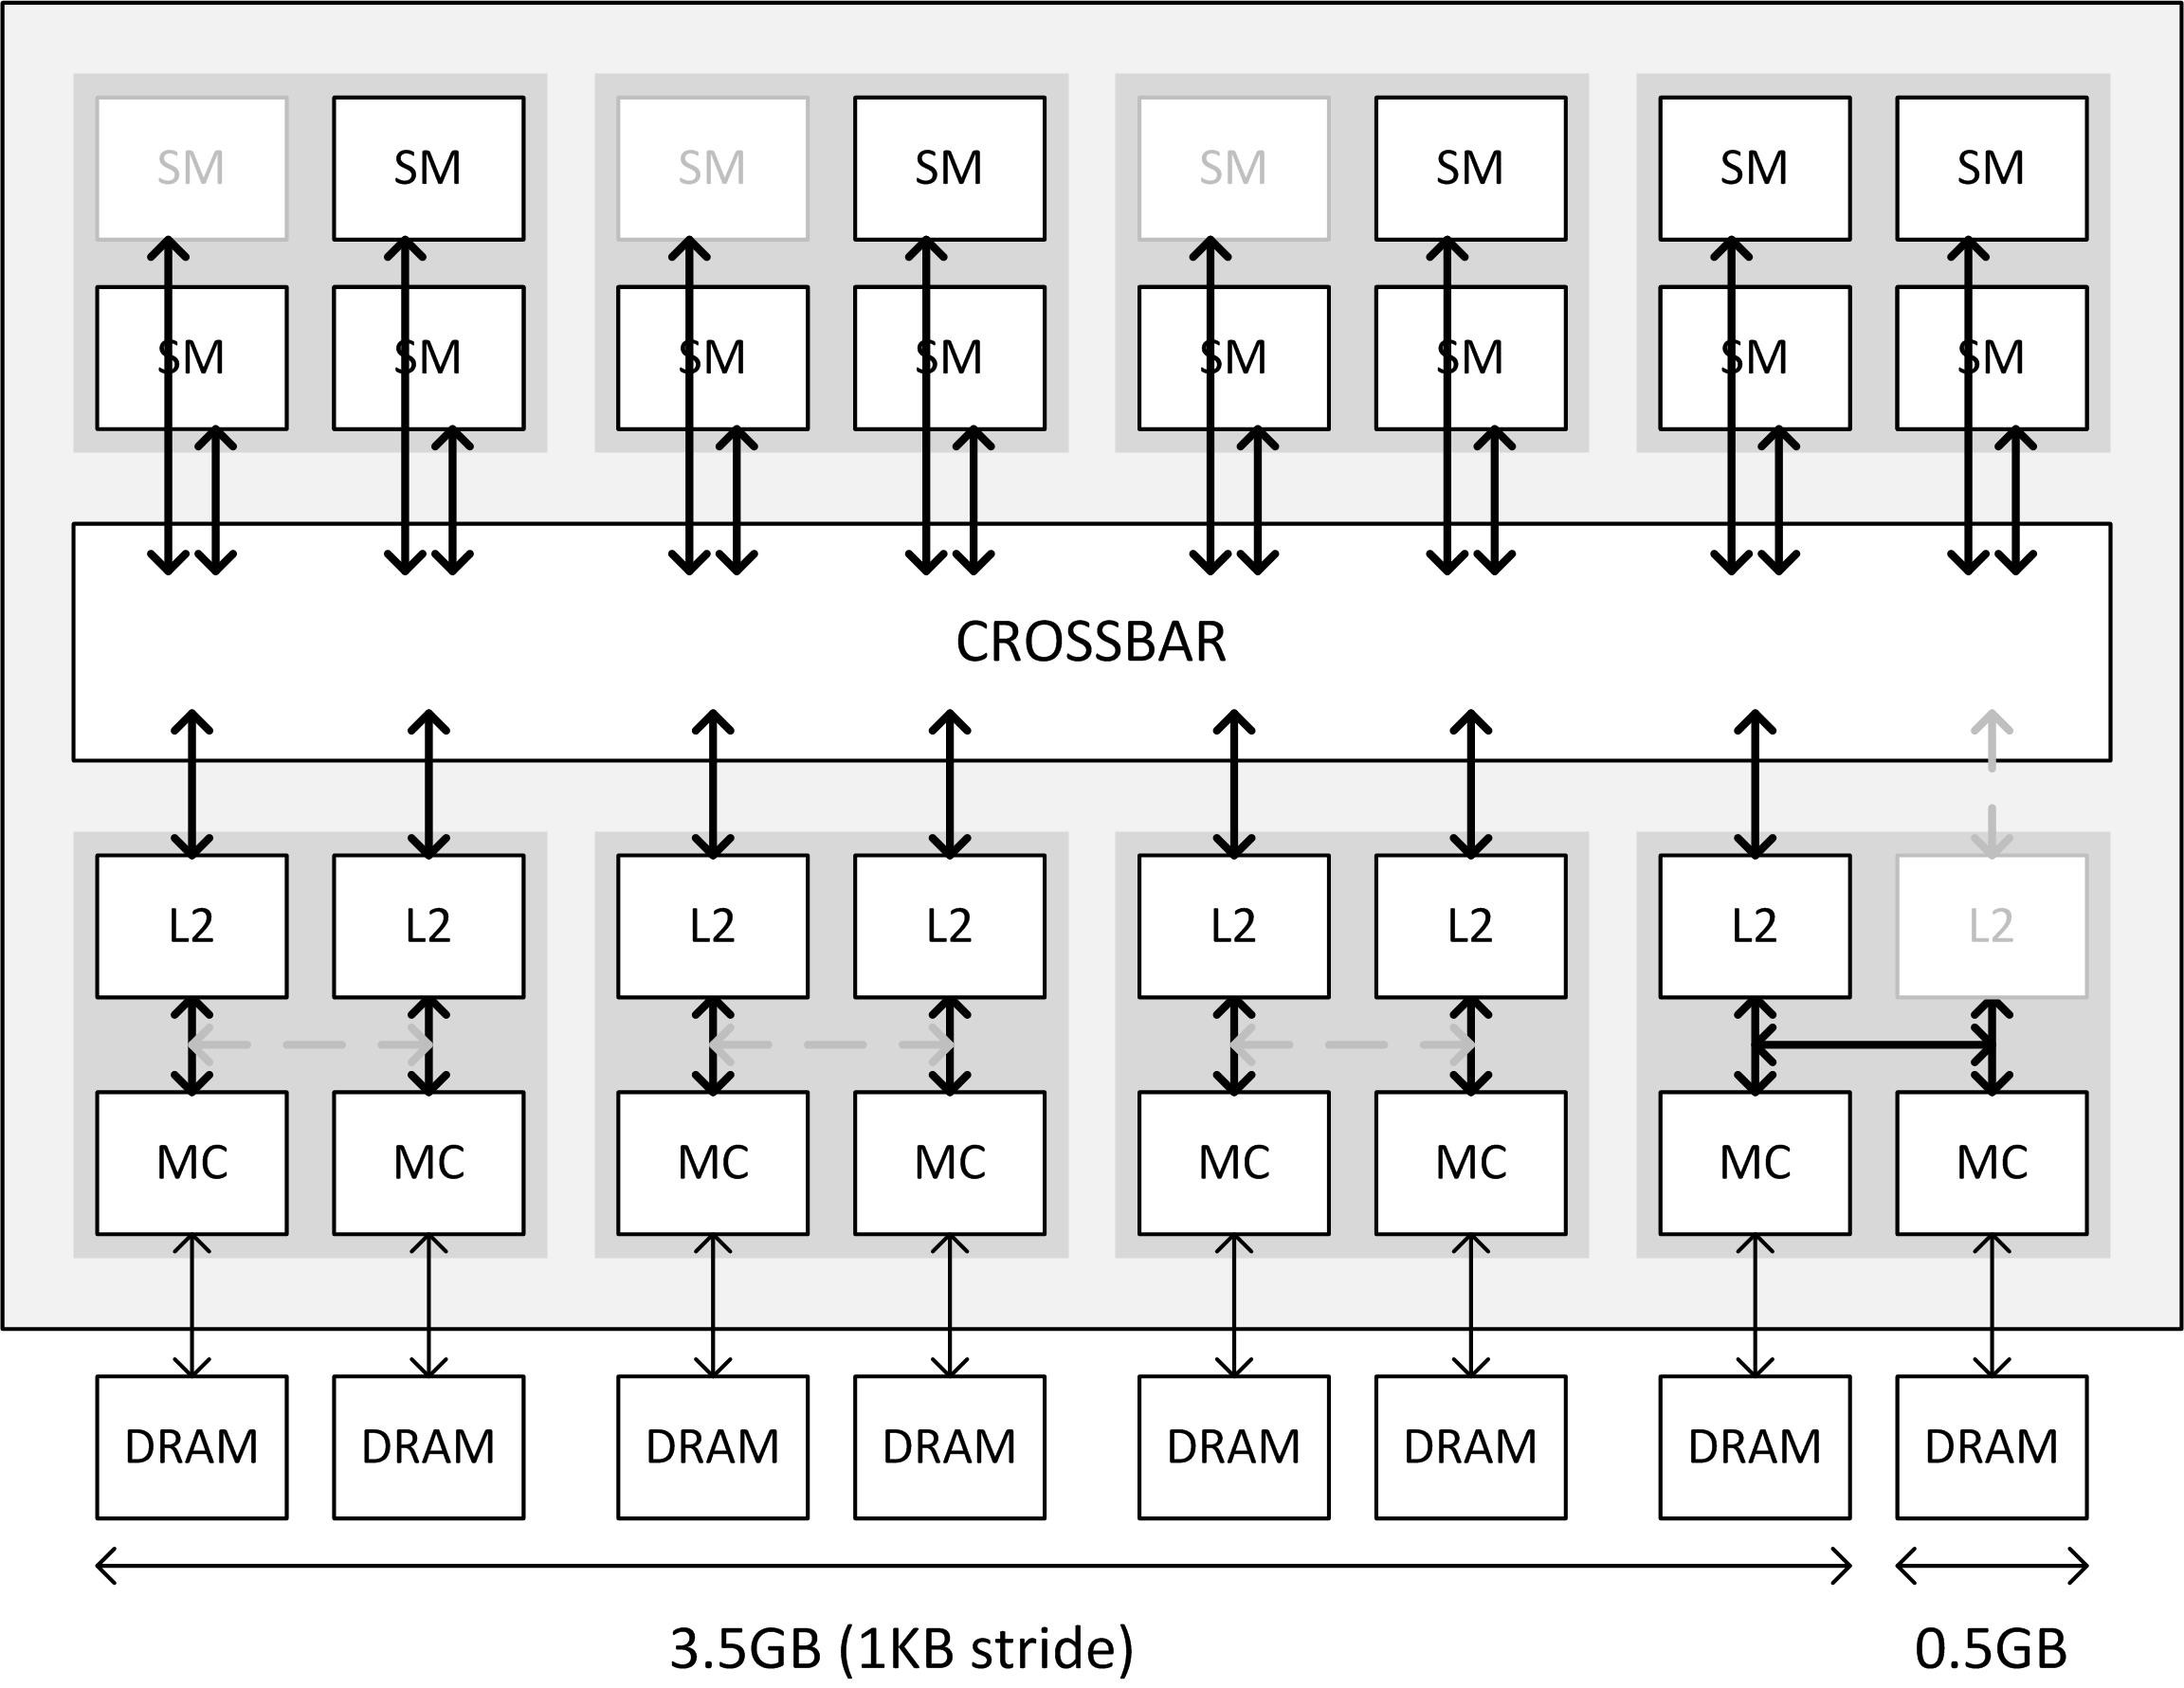

It turns out that in addition to three SMX units being disabled (resulting in 1,664 CUDA cores), NVIDIA reduced the L2 cache (last-level cache) on this chip to 1.75 MB, down from 2 MB, and also disabled a few ROPs. The ROP count is effectively 56, and not 64. The last 8 ROPs aren't "disabled." They're active, but not used, because their connection to the crossbar is too slow (we'll get to that in a bit). The L2 cache is a key component of the "crossbar." Think of the crossbar as a town-square for the GPU, where the various components of the GPU talk to each other by leaving and picking-up data labeled with "from" and "to" addresses. The crossbar routes data between the four Graphics Processing Clusters (GPCs), and the eight memory controllers of 64-bit bus width each (which together make up its 256-bit wide memory interface), and is cushioned by the L2 cache.
The L2 cache itself is segmented, and isn't a monolithic slab of SRAM. Each of the eight memory controllers on the GM204 is ideally tied to its segment of the L2 cache. Also tied to these segments are segments of ROPs. With NVIDIA reducing the L2 cache amount by disabling one such segment. Its component memory controller is instead rerouted to the cache segment of a neighbouring memory controller. Access to the crossbar for that memory controller is hence slower. To make sure there are no issues caused to the interleaving of these memory controllers, adding up to the big memory amount figure that the driver can address, NVIDIA partitioned the 4 GB of memory to two segments. The first is 3.5 GB large, and is made up of memory controllers with access to their own segments of the L2; the second segment is 512 MB in size, and is tied to that memory controller which is rerouted.
The way this partitioning works, is that the 3.5 GB partition can't be read while the 512 MB one is being read. Only to an app that's actively using the entire 4 GB of memory, there will be a drop in performance, because the two segments aren't being read at the same time. The GPU is either addressing the 3.5 GB segment, or the 512 MB one. Hence, there's a drop in performance to be expected, again, for apps that use up the entire 4 GB of memory.
While it's technically correct that the GTX 970 has a 256-bit wide memory interface, and given its 7.00 GHz (GDDR5-effective) memory clock, that translates to 224 GB/s of bandwidth on paper, not all of that memory is uniformly fast. You have 3.5 GB of it having normal access to the crossbar (the town-square of the GPU), and 512 MB of it having slower access. Therefore, the 3.5 GB segment really just has 196 GB/s of memory bandwidth (7.00 GHz x 7 ways to reach the crossbar x 32-bit width per chip), which can be said with certainty. Nor can we say how this segment affects the performance of the memory controller whose crossbar port it's using, if the card is using its full 4 GB. We can't tell how fast the 512 MB second segment really is. But it's impossible for the second segment to make up 28 GB/s (of the 224 GB/s), since NVIDIA itself claims this segment is running slower. Therefore NVIDIA's claims of GTX 970 memory bandwidth being 224 GB/s at reference clocks is inaccurate.
Why NVIDIA chose to reduce cache size and ROP count will remain a mystery. We can't imagine that the people designing the chip will not have sufficiently communicated this to the driver and technical marketing teams. To claim that technical marketing didn't get this the first time around, seems like a hard-sell. We're pretty sure that NVIDIA engineers read reviews, and if they saw "64 ROPs" on a first-page table, they would have reported it up the food-chain at NVIDIA. An explanation about this hardware change should have taken up an entire page in the technical documents the first time around, and NVIDIA could have saved itself a lot of explanation, much of it through the press.
138 Comments on GTX 970 Memory Drama: Plot Thickens, NVIDIA has to Revise Specs
I never like the idea of a gimped GPU with a bit of it disabled since it reduces performance and unbalances the design and this is a graphic example of exactly why this is bad. This is the sort of reason why I always insist on getting the top GPU in the range. Yeah, it costs me a lot of money, but I also don't have to put up with garbage like this.
I have lodged a formal complaint with the ACCC ( I'm in Australia ) Have forwarded my formal complaint to Nvidia and my local retailer Umart. Under Australian consumer law i'm entitled to a refund.
Let's see what eventuates from this.....
They are in damage control for sure. Too late now !
A play a fair few games that take over 3.5GB ram and it would just annoy me just being sold some thing that is not truly what it claims.
Maybe Peter will sell you his.
Heck, can we even ask for a refund because we have bought something that not according to the spec?
Just so people know its real and your not flamed..
www.digitalstormonline.com/unlocked/video-memory-usage-at-4k-uhd-resolutions-idnum146/
EDIT:You can hit 3.5+GB with them without mods. And i know WD can hit that under 1080P.
1. each Maxwell smm can only address 4 pixels per clock meaning even with the rops present they r pretty much useless.
2 Maxwell is having this dilemma because it's the trade off nvidia made when they made Maxwell a more cache dependant design than it is on external bus width.
3. Bus width is meaningless when the gpu computer units can't handle the throughput, it's almost like having 5 lanes open at a movie theater counter but with only 2 employees working
This being said this is more reason to stop looking at theoretical specs and actually measure real time performance. Had it been that memory bandwidth was properly measured it would've been obvious that gtx 970 has lower throughout than a gtx980 despite sharing the same memory width and "rops". And last but not least I wanna see more benchmarks on amd cards measuring the effectiveness/efficiency of the memory width vs throughput of gcn and have a more lower level look at architecture in general because I can't help but think amd just goes extreme on certain aspects and slaps random hardware on their chips, idk if anyone noticed but gcn cards have insane variance in efficiency between different chips because the design has become "less modular?" Or should I say too modular? Meaning the parts on the chip are too independent of each other while nvidia has a more focused graphics module containing pretty much everything at the perfect ratio with as little bottlenecks as possible so when they scale up and down the ratio of rendering/throughput remains unchanged across the board, the downside is less flexibility to customize specs which caused this gtx970 dilemma, but the benefit is having consistency and less chance of a "hit or miss"
The world we live in.
We'll see how long "performance is the only thing that matters" sticks around. Next GPU rumor/release thread -->