News Posts matching #B300

Return to Keyword Browsing

NVIDIA RTX PRO 5500 Listing Spotted at $17,999, More Than the Flagship RTX PRO 6000

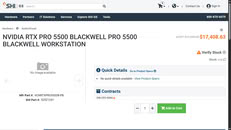
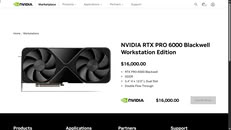
The NVIDIA RTX PRO 5500 "Blackwell" workstation card has shown up at a US retailer, and it surprisingly costs more than the flagship RTX PRO 6000. As spotted by Alex Ziskind on X and corroborated by Videocardz, SHI Government Solutions listed the PNY-built model (VCNRTXPRO5500B-PB) with an MSRP of $17,999 and a discounted price of $17,408.63. NVIDIA's own US marketplace, on the other hand, lists the RTX PRO 6000 for $16,000, even though that card has more CUDA cores (24,064 vs. 21,760) and more memory (96 GB vs. 84 GB). So even at SHI's discounted price, the cut-down card costs around $1,400 more. NVIDIA hasn't announced official pricing since it quietly added the RTX PRO 5500 to its lineup in September, so it isn't clear whether the $17,999 figure comes from NVIDIA or PNY.

Videocardz points out that Chinese demand is probably a big factor behind the RTX PRO 5500's price. According to Reuters, ByteDance, Alibaba, and Tencent have ordered over 3 million RTX PRO 5500 cards at roughly $11,400 each, with total orders from China reportedly topping 6 million. One source said NVIDIA can make no more than 3 million of them in 2027. With the B300 barred from China and the H200 reviewed case by case, the RTX PRO 5500 is one of the strongest NVIDIA GPUs Chinese firms can still buy. The card also packs 28 GDDR7 modules at a time, even as memory prices keep climbing. With orders far ahead of supply, it's reasonable to expect RTX PRO 5500 pricing to stay high for a while.
More Intel Nova Lake-S Desktop GPUs Appear in Linux 7.3

The list of Intel Nova Lake-S Xe3 desktop GPUs supported by Linux has grown in a recent Linux kernel driver patch that will make it to Linux 7.3. The driver update adds device IDs labelled 0xD74A and 0xD748 and drops 0xD744, bringing the list of total Nova Lake-S desktop GPUs supported by Linux to seven. This doesn't necessarily confirm the number of SKUs that will be available in the upcoming Xe3 series, however, it is an indication that Intel may be working on as many as seven SKUs that may or not make it to market. Intel also improved its media engine, with the Protected Xe Path no longer requiring HuC firmware to be loaded in kernel—it will be moved to user space instead.

Previous rumors indicated that Nova Lake-S would be using Xe3 graphics for the Core Ultra 400-series desktop CPUs, which is the same graphics tech used in the current Panther Lake Arc B300-series iGPUs and the Arc G3 Extreme SoC that has made its way into a number of gaming handhelds. It's unclear if Intel will include its most powerful Arc B390 iGPU in the desktop line-up, but Nova Lake-S is expected to have a focus on AI-accelerated workloads, which would benefit from additional GPU cores, aside from the built-in NPU. Recently, news also broke that Intel was preparing two gaming-specific SKUs with massive bLLC cache for the Nova Lake-S line-up. For more information about the latest driver update, check the full notes in the pull request.

Intel "Nova Lake" to Use Xe3 Graphics and Xe3P Display/Media Engine

Intel's upcoming "Nova Lake" CPU generation, part of the Core Ultra 400 series, will be a major refresh of the company's P and E-core hybrid design. While many specifications have been largely leaked, the exact integrated GPU configuration remained a mystery until now. One of the most reliable Intel leakers, Jaykihn, has revealed that Intel plans to use the Xe3 generation of graphics, which is found in the current "Panther Lake" Arc B300 series of integrated GPUs. The display and media engine will come from the Xe3P "Crescent Island." Previously, we reported the source's claim that the "Nova Lake" display and media engine would incorporate some IP elements from the Xe4 "Druid" generation of graphics. However, the actual underlying hardware is not related to Xe4 and instead borrows IP from Xe3P.

Intel's plans for "Nova Lake" are focused on late 2026, with the entire lineup expected to roll out in early 2027. The platform will support DDR5 memory at 8,000 MT/s out of the box, without any overclocking. This indicates an improved integrated memory controller on the Nova Lake platform, which seems ready to handle those speeds even before XMP or factory-overclocked modules are considered. It also suggests that Intel is pushing memory support further than its current controller, which reaches DDR5-7200 on the current "Arrow Lake Refresh," alongside the new core IP and updated configuration.

Global AI Server Shipments Forecast to Grow Over 28% YoY in 2026, with a Rising Share of ASIC-Based Systems

North American CSPs' continued investments in AI infrastructure are expected to increase global AI server shipments by more than 28% YoY in 2026, according to the latest market research from TrendForce. The rapid growth of AI inference services is boosting demand for general-purpose servers, supporting both replacement and expansion efforts. Consequently, TrendForce predicts that total global server shipments, including AI servers, will accelerate from 2025, with a 12.8% YoY growth in 2026.

The server market from 2024 to 2025 primarily centered on training advanced large language models (LLMs), utilizing AI servers with GPUs and HBM for parallel computing. However, starting in the second half of 2025, the growth of AI agents, LLaMA-based applications, and Copilot upgrades shifted CSP's focus toward inference services as a monetization strategy. AI inference workloads are now deployed not only on dedicated AI server racks but also on general-purpose servers that handle pre- and post-inference computing and storage.

ASUS Showcases ExpertCenter Pro ET900N G3 at CES 2026

ASUS today announced the showcase of ExpertCenter Pro ET900N G3 at CES 2026, underscoring its commitment to delivering enterprise-grade AI infrastructure in accessible, deskside form factors. The all-new ET900N G3—accelerated by the NVIDIA GB300 Grace Blackwell Ultra Desktop Platform—sets a new standard for deskside AI supercomputers, combining extreme performance, unified memory architecture, and data-center-class connectivity.

Solving the last-mile challenge of modern AI development
AI development has reached extraordinary heights through massive cloud and data-center infrastructure, yet many researchers, developers, and data scientists still face a 'last-mile' challenge. While cloud services offer immense scale, countless workflows require local, private, and immediate compute power—especially for training, fine-tuning, or running large AI models that exceed the limits of traditional workstations. What these professionals need is a system that delivers data-center-class performance in a familiar, easily deployable deskside form factor.

Framework Pushes DDR5 Pricing 50% Higher Amid Shortage

Framework has published an official company blog post announcing that it is preparing a 50% price increase for its DDR5 memory upgrade configurations. In an effort to remain transparent with customers, the company has stated that it intends to raise the price of DDR5 memory available in Framework Laptop DIY Edition orders by 50%. This decision is a direct response to the significantly higher costs the company is facing from its DRAM suppliers and distributors. As a result, the company cannot absorb all of these cost increases on its own and needs to pass some of them on to the consumer.

The company will not increase the prices of its existing pre-configured systems that include DRAM, as these were acquired at earlier, standard prices. As the memory market becomes more volatile, this might be just the first wave of price hikes, since the company cannot absorb the added costs of new memory orders. Since Framework manufactures various components, from laptops to mini-PCs, the company uses a mix of DDR5, LPDDR5X, and GDDR. All of these are in tight supply due to the AI boom depleting any remaining DRAM inventory.

NVIDIA Reaffirms Support for FP64, Next-Gen GPU to Bring HPC Improvements

NVIDIA's recent generations of GPUs, such as "Hopper" and "Blackwell," have been known for stalling their high-performance computing (HPC) oriented FP64 double-precision performance. However, the company is not inherently abandoning the HPC space and has confirmed for HPCWire that 64-bit floating point data is not going away. According to Dion Harris, the senior director of HPC and AI hyperscale infrastructure solutions at NVIDIA, the company is "definitely looking to bring some additional [FP64] capabilities in our future gen architectures. We are very serious about making sure that we can deliver the required performance to power those simulation workloads."

The acceleration of 64-bit floating-point data paths is crucial for the HPC community, particularly in the life sciences. When a workload demands sustained high-precision support, NVIDIA's recent generations have not met expectations. For comparison, NVIDIA's current most powerful B300 "Blackwell Ultra" accelerator achieves only 1.2 TeraFLOPS of FP64 performance. In contrast, the older H200 "Hopper" reaches an impressive 34 TeraFLOPS of FP64 compute at its peak. For FP8 low-precision, the B300 delivers 9 PetaFLOPS, while the H200 provides 3.958 PetaFLOPS.

Supermicro Intros New 4U and 2-OU (OCP) Liquid-Cooled NVIDIA Blackwell HGX B300 Systems

Super Micro Computer, Inc. (SMCI), a Total IT Solution Provider for AI, Cloud, Storage, and 5G/Edge, today announced the expansion of its NVIDIA Blackwell architecture portfolio with the introduction and shipment availability of new 4U and 2-OU (OCP) liquid-cooled NVIDIA HGX B300 systems. These latest additions are a key part of Supermicro's Data Center Building Block Solutions (DCBBS) that deliver unprecedented GPU density and power efficiency for hyperscale data centers and AI factory deployments.

"With AI infrastructure demand accelerating globally, our new liquid-cooled NVIDIA HGX B300 systems deliver the performance density and energy efficiency that hyperscalers and AI factories need today," said Charles Liang, president and CEO of Supermicro. "We're now offering the industry's most compact NVIDIA HGX B300 solutions—achieving up to 144 GPUs in a single rack—while reducing power consumption and cooling costs through our proven direct liquid-cooling technology. Through our DCBBS, this is how Supermicro enables our customers to deploy AI at scale: faster time-to market, maximum performance per watt, and end-to-end integration from design to deployment."

NVIDIA and AWS Expand Full-Stack Partnership

At AWS re:Invent, NVIDIA and Amazon Web Services expanded their strategic collaboration with new technology integrations across interconnect technology, cloud infrastructure, open models and physical AI. As part of this expansion, AWS will support NVIDIA NVLink Fusion—a platform for custom AI infrastructure—for deploying its custom-designed silicon, including next-generation Trainium4 chips for inference and agentic AI model training, Graviton CPUs for a broad range of workloads and the Nitro System virtualization infrastructure.

Using NVIDIA NVLink Fusion, AWS will combine NVIDIA NVLink scale-up interconnect and the NVIDIA MGX rack architecture with AWS custom silicon to increase performance and accelerate time to market for its next-generation cloud-scale AI capabilities. AWS is designing Trainium4 to integrate with NVLink and NVIDIA MGX, the first of a multigenerational collaboration between NVIDIA and AWS for NVLink Fusion. AWS has already deployed MGX racks at scale with NVIDIA GPUs. Integrating NVLink Fusion will allow AWS to further simplify deployment and systems management across its platforms.

Supermicro Showcases the Future of HPC Clusters and AI Infrastructure at SC25

Super Micro Computer, Inc. (SMCI), a Total IT Solution Provider for AI/ML, HPC, Cloud, Storage, and 5G/Edge, will showcase its latest AI Factory, HPC, and liquid-cooled data center innovations at Supercomputing 2025 (SC25) in St. Louis, Missouri. This broad portfolio, ranging from desktop workstations to rack-scale solutions, demonstrates Supermicro's commitment to powering the next generation of high-performance computing, scientific research, and enterprise AI deployments.

"Supermicro continues to lead the industry in delivering complete, next-generation infrastructure solutions in close collaboration with our technology partners," said Charles Liang, president and CEO of Supermicro. "At SC25, we are demonstrating our high-performance DCBBS architecture, direct liquid cooling, and rack-scale innovations, which empower customers to deploy AI and HPC workloads faster, more efficiently, and more sustainably."

NVIDIA Wins Every MLPerf Training v5.1 Benchmark

In the age of AI reasoning, training smarter, more capable models is critical to scaling intelligence. Delivering the massive performance to meet this new age requires breakthroughs across GPUs, CPUs, NICs, scale-up and scale-out networking, system architectures, and mountains of software and algorithms. In MLPerf Training v5.1—the latest round in a long-running series of industry-standard tests of AI training performance—NVIDIA swept all seven tests, delivering the fastest time to train across large language models (LLMs), image generation, recommender systems, computer vision and graph neural networks.

NVIDIA was also the only platform to submit results on every test, underscoring the rich programmability of NVIDIA GPUs, and the maturity and versatility of its CUDA software stack.

Liquid Cooling for NVIDIA GB300 "Blackwell Ultra" NVL72 Costs Nearly $50,000

NVIDIA's "Blackwell Ultra" server racks are undoubtedly powerful, but they demand significant system cooling. NVIDIA promotes the GB300 NVL72 as the top configuration: these liquid-cooled racks, built with Grace Blackwell Ultra Superchips, achieve exascale-class dense FP4 performance and offer substantial improvements in throughput-per-megawatt compared to previous HGX platforms. However, this extreme performance mandates massive cooling systems, which can cost around $50,000. According to a valuation model from investment bank Morgan Stanley, NVIDIA is spending nearly $50,000 on cooling for the 72-GPU configuration within its Oberon rack. With each chip rated at 1,400 W TDP, traditional air-based cooling solutions are not feasible.

Considering that there are 72 GPUs rated up to 1,400 W, that is over 100 kW from GPUs alone. Add 32 "Grace" CPUs that are powering the system, and you have more than a 100 kW of heat at the peak load. Morgan Stanley models the rack as containing 18 compute trays (each consuming roughly 6.6 kW but needing cooling for about 6.2 kW) alongside nine switch trays. The firm values the cooling components for a single compute tray at about $2,260, which multiplies to roughly $40,680 across the rack. Switch-tray cooling adds about $1,020 per tray, or $9,180 total. High-performance cold plates are singled out as the most expensive parts in the BOM, with per-unit prices in the low hundreds.
Amazon Secures $38 Billion Deal to Host OpenAI's NVIDIA GB200/GB300 AI Servers

Amazon Web Services (AWS) and OpenAI have signed a $38 billion deal spanning several years, seven to be more precise, to boost OpenAI's AI operations using AWS's high-end cloud setup. This agreement lets OpenAI use clusters with hundreds of thousands of NVIDIA GB200 and GB300 GPUs, the complete planned capacity is expected to be deployed for use by the end of 2026. These GPUs are set up across Amazon EC2 UltraServers linked by a fast, high-capacity network built to handle both inference and large-scale model training. AWS's previous experience managing clusters exceeding 500,000 chips has been a key factor in OpenAI's decision.

The new infrastructure is expected to serve a range of OpenAI applications, from ChatGPT inference workloads to training next-generation foundation models. OpenAI's move to AWS comes after a series of recent partnerships with NVIDIA, AMD, Microsoft, Broadcom, and Oracle making sure they can tap into a mix of high-end chips and cloud systems. OpenAI CEO Sam Altman stated that the company plans to invest $1.4 trillion to build 30 gigawatts of computing capacity, equivalent to the power consumption of roughly 25 million U.S. households. So far, OpenAI has partnered with NVIDIA for 10 GW, AMD for 6 GW, and Oracle for 4.5 GW of compute capacity, moving steadily toward its stated goal of building a 30 GW AI infrastructure network.

Giga Computing Showcases Scalable Next-Gen AI and Visualization Solutions at NVIDIA GTC DC 2025

Giga Computing, a subsidiary of GIGABYTE and an industry innovator and leader in AI hardware and advanced cooling solutions, today announced its participation in NVIDIA GTC DC (Oct. 28-29). With the importance of AI and scalable solutions, Giga Computing demonstrates how innovation in hardware and software can drive forth the transformation into the AI-driven era. These solutions will empower developers, researchers, and creators to achieve more, from the desktop to the data center, and discussions are being held at the GIGABYTE booth #528.

The booth features four flagship GIGABYTE systems: the AI TOP ATOM, the W775-V10 workstation, the XL44-SX2 (NVIDIA RTX PRO Server), and a liquid-cooled G4L4-SD3 AI server. Together, these GIGABYTE solutions built on the NVIDIA Blackwell architecture to enable efficient, high-performance AI and visualization workloads spanning every compute tier.

NVIDIA to Build Seven New AI Supercomputers for U.S. Government

NVIDIA today announced that it is working with the U.S. Department of Energy's national labs and the nation's leading companies to build America's AI infrastructure to support scientific discovery, economic growth and power the next industrial revolution.

"We are at the dawn of the AI industrial revolution that will define the future of every industry and nation," said Jensen Huang, founder and CEO of NVIDIA. "It is imperative that America lead the race to the future—this is our generation's Apollo moment. The next wave of inventions, discoveries and progress will be determined by our nation's ability to scale AI infrastructure. Together with our partners, we are building the most advanced AI infrastructure ever created, ensuring that America has the foundation for a prosperous future, and that the world's AI runs on American innovation, openness and collaboration, for the benefit of all."

ASUS Launches XA NB3I-E12 AI Server Built with NVIDIA HGX B300

ASUS today announced the shipment of the XA NB3I-E12 AI server, built on the NVIDIA HGX B300 platform. Delivering next-generation AI performance and reliability, XA NB3I-E12 gives enterprises and cloud-service providers (CSPs) early access to cutting-edge computing capabilities for the AI era. Accelerated by eight NVIDIA Blackwell Ultra GPUs and dual Intel Xeon 6 Scalable processors, ASUS XA NB3I-E12 is engineered for intensive AI workloads. With eight NVIDIA ConnectX-8 InfiniBand SuperNICs, five PCIe expansion slots, 32 DIMMs, 10 NVMe drives, and dual 10 Gb LAN, it transforms data into intelligence for real-world automation. The system is ideal for enterprises and CSPs running large language models (LLMs), research institutions and universities performing scientific computing, and the financial and automotive sectors focused on AI model training and inference.

ASRock Rack Unveils NVIDIA HGX B300 Servers with Waterless Liquid Cooling Solution

ASRock Rack Inc., a leading innovative server company, today announced the launch of the 4U16X-GNR2/ZC, which uniquely integrates NVIDIA HGX B300 platform with ZutaCore HyperCool waterless direct liquid cooling (DLC). The breakthrough platform will be showcased at the Open Compute Project (OCP) Global Summit 2025, taking place October 14-16 at the San Jose Convention Center, Booth C31.

The rapid growth of AI is driving demand for powerful, efficient infrastructure across industries. To support this expansion, liquid cooling is becoming essential for managing heat in high-performance AI factories. By maximizing efficiency and reducing operational costs, liquid-cooled AI factories are key to accelerating AI adoption and powering the next wave of innovation.

ASUS Unveils AI Factory and Next-Gen Servers with NVIDIA HGX B300 systems at OCP 2025

ASUS today announced its participation in the 2025 OCP Global Summit, being held from October 13-16 at the San Jose Convention Center, booth #C15. At the event, ASUS unveiled its XA NB3I-E12 series AI servers, based on NVIDIA HGX B300 system integrated with NVIDIA ConnectX-8 InfiniBand SuperNICs, 5 PCIe expansion slots, 32 DIMM and 10 NVMe. Designed for enterprises and cloud service providers (CSPs) managing intensive AI workloads, these servers deliver outstanding performance and stability, unlocking the full potential of AI.

Starting this September, ASUS AI POD built on NVIDIA GB300 NVL72 and XA NB3I-E12 servers based on NVIDIA HGX B300 have begun shipping, giving enterprises and cloud service providers early access to cutting-edge AI performance and reliability.

Giga Computing Showcases AI-Centric Server Solutions at GITEX Global 2025

Giga Computing, a subsidiary of GIGABYTE and a global leader in AI servers and advanced cooling technologies, announced its participation in GITEX Global 2025, featuring nVent and Iceotope at GIGABYTE booth H10-18. As a trusted partner in the AIDC Infra ecosystem, Giga Computing designs and delivers high-performance AI servers. nVent is a leader in high density liquid cooling, rear-door heat exchangers (RDHx), IT server racks and cabinets, manifolds and iPDUs. Iceotope liquid cooling solutions offer enterprises and cloud service providers a unique combination of peak thermal efficiency and deployment flexibility. Working together, they underscore a collaborative ecosystem supported by a joint commitment to energy-efficient and sustainable AI infrastructure.

Driving Growth and Innovation in the Middle East
Participation in GITEX reflects Giga Computing's commitment to building a strong presence in the Middle East market, a region experiencing a rapid digital transformation and AI adoption. As one of the world's top-tier AI server suppliers, Giga Computing is bringing its complete AI data center solutions to the Middle East, providing enterprises, hyperscalers, and emerging AI innovators with scalable infrastructure designed for cutting-edge workloads.

Microsoft Unveils World's Biggest AI Datacenter, Housing Hundreds of Thousands of GPUs

Microsoft announced today that it will bring Fairwater, a purpose-built AI datacenter in Mount Pleasant, Wisconsin, online in early 2026. The new site is designed as the most powerful datacenter on the planet, serving as a hub for next-generation model training and inference. The campus covers 315 acres with roughly 1.2 million square feet across three buildings and will house hundreds of thousands of NVIDIA GB200 and GB300 GPUs linked by fiber, which can reportedly circle the globe 4.5 times. While we don't have information on the exact GPU count, Microsoft claims the installation will deliver about 10x the performance of today's fastest supercomputers for frontier AI workloads. With the fastest already deployed cluster being xAI's Colossus 1, this means that this system could have over half a million "Blackwell" and "Blackwell Ultra" GPUs.

Over 90% of compute capacity will use a closed-loop liquid cooling system that is filled during construction and continuously recirculated, backed by what the company describes as the planet's second-largest water-cooled chiller plant. Around 10% of servers will rely on outside air and switch to water cooling only on the hottest days. Storage and I/O are scaled for exabyte-class datasets, and the buildout involved 46.6 miles of deep foundation piles, 26.5 million pounds of structural steel, 120 miles of medium-voltage underground cable, 72.6 miles of mechanical piping, and an external cooling array that includes 172 20-foot fans.

Giga Computing Launches NVIDIA HGX B300-Powered Flagship Server

Giga Computing, a subsidiary of GIGABYTE Group and a pioneer in generative AI and high-performance computing (HPC) servers, today announced the launch of its new flagship server, GIGABYTE G894-SD3-AAX7. This 8U dual-processor platform supports NVIDIA HGX B300 and is designed to accelerate AI training, inference, and complex HPC workloads, delivering unparalleled performance and scalability.

Leading-Edge AI Reasoning and High-Performance Computing Platform
The G894-SD3-AAX7 combines the latest hardware innovations in a compact 8U, air-cooled chassis, maximizing both system performance and expansion capabilities:
  • NVIDIA HGX B300 Support: The 8-GPU HGX B300 platform integrates 8x NVIDIA Blackwell Ultra GPUs with NVIDIA NVLink and NVLink Switch to deliver 1.8 TB/s GPU-GPU bandwidth and 14.4 TB/s total bandwidth for scalable AI performance.
  • Powerful Processor Configuration: Dual Intel Xeon 6700/6500 series processors with 32 DDR5 DIMM slots, delivering robust compute for next-generation AI training and HPC applications.
  • Ultra-High-Speed Networking: Equipped with 8x 800 Gb/s OSFP InfiniBand or 16x 400 Gb/s Ethernet ports via NVIDIA ConnectX-8 SuperNICs, enabling high-throughput performance for large-scale data center workloads.

China Blocks Tech Firms from Buying NVIDIA AI Accelerators

China has reportedly banned its domestic technology firms from purchasing NVIDIA AI accelerators to promote the adoption of domestic AI accelerators. According to sources close to the Financial Times, the Cyberspace Administration of China (CAC) instructed several technology giants, including Alibaba, Baidu, and Tencent, to stop their independent evaluation and procurement of NVIDIA's export-modified AI accelerators. This includes chips like the RTX PRO 6000D, a variant of the RTX PRO 6000 designed for the Chinese market. There is no mention of the modified "Blackwell Ultra" single-die B30A accelerators, which were intended as a China-specific alternative to the GB300, offering half the compute power.

This directive from Beijing indicates that, despite Chinese tech giants' interest in NVIDIA-supplied AI accelerators due to their superior software and computing capabilities, regulators aim to promote domestic AI accelerators from companies like Huawei and Cambricon. These domestic chips are built on older technology nodes, primarily because of China's limited access to cutting-edge manufacturing and the absence of modern EUV tools for its domestic fabs. An insider told the Financial Times that "the top-level consensus now is there's going to be enough domestic supply to meet demand without having to buy NVIDIA chips." This suggests that the current ambitions of Chinese AI labs could be fully met with domestic chips. However, training and running frontier-level models on non-NVIDIA hardware remains a persistent challenge.

NVIDIA Blackwell Ultra Sets the Bar in New MLPerf Inference Benchmark

Inference performance is critical, as it directly influences the economics of an AI factory. The higher the throughput of AI factory infrastructure, the more tokens it can produce at a high speed - increasing revenue, driving down total cost of ownership (TCO) and enhancing the system's overall productivity. Less than half a year since its debut at NVIDIA GTC, the NVIDIA GB300 NVL72 rack-scale system - powered by the NVIDIA Blackwell Ultra architecture - set records on the new reasoning inference benchmark in MLPerf Inference v5.1, delivering up to 1.4x more DeepSeek-R1 inference throughput compared with NVIDIA Blackwell-based GB200 NVL72 systems.

Blackwell Ultra builds on the success of the Blackwell architecture, with the Blackwell Ultra architecture featuring 1.5x more NVFP4 AI compute and 2x more attention-layer acceleration than Blackwell, as well as up to 288 GB of HBM3e memory per GPU. The NVIDIA platform also set performance records on all new data center benchmarks added to the MLPerf Inference v5.1 suite - including DeepSeek-R1, Llama 3.1 405B Interactive, Llama 3.1 8B and Whisper - while continuing to hold per-GPU records on every MLPerf data center benchmark.

NVIDIA's Export-Compliant B30A for China Priced at Roughly Twice the H20

As NVIDIA acquired an export license for its "Hopper" H20 GPU, the company immediately prepared to ship a modified "Blackwell" B30A design. Interestingly, sources close to Reuters note that the demand from Chinese companies is massive even for the older H20 GPU, despite Beijing regulators warning against the use of NVIDIA-supplied hardware in new data center buildouts. As H20 in China sells for around $10,000- $12,000, the new B30A will be priced at double that amount, around $20,000-$24,000, with the lower range possibly reserved for larger volume shipments. Sources also note that Chinese firms believe this is a good deal, given the performance and software compatibility that NVIDIA brings with its hardware.

Designed as a single-die design, it utilizes the same base die as the dual-die B300 and embeds a single one into the package, achieving half the performance to comply with export regulations. Based on the Blackwell Ultra (B300) numbers, the export-compliant single-die B30A would be expected to deliver roughly 7.5 PetaFLOPS FP4, 3.75 PetaFLOPS FP6/FP8, 1.875 PetaFLOPS FP16/BF16, and 0.94 PetaFLOPS at TF32, about half the peak throughput of the dual-die B300. Additionally, NVIDIA could generate a substantial amount of sales in the Chinese market, as rewriting the entire infrastructure to use Chinese domestic accelerators would require more time, which could significantly offset China's AI ambitions. Hence, while domestic accelerators mature in design and software, NVIDIA's GPUs are in everlasting demand. While the timeline for B30A GPU shipment is unknown, we expect to see the first Chinese AI labs getting their hands on these accelerators in the next few weeks.

NVIDIA "Blackwell Ultra" Brings PCIe Gen 6 and 1.5x NVFP4 Performance Boost

NVIDIA's long-anticipated "Blackwell Ultra" is the final form of the Blackwell family before the transition to "Rubin." However, this silicon doesn't seem to share much resemblance with its predecessors, especially in terms of I/O and performance. On its blog, NVIDIA detailed the silicon design of its latest creation and all the accompanying features like enhanced software support and optimizations. One of the most striking aspects of the Blackwell Ultra, designed for AI servers, is its use of PCIe Gen 6, whereas the consumer Blackwell and regular server Blackwell use PCIe Gen 5. Made using the TSMC 4NP node, the massive Ultra chip features 208 billion transistors, which is 2.6 times more than the last generation Hopper, based solely on raw transistor count. This comes with a 1,400 W TDP, which means a massive cooling system is a must.

When it comes to performance, Blackwell Ultra delivers approximately 1.5 times denser NVFP4 compute compared to Blackwell, resulting in higher tokens-per-second on inference and improved throughput for large-batch training. The chip pairs 160 SMs across two reticle dies via NVIDIA's NV-HBI link, bringing a 10 TB/s die-to-die fabric, 288 GB of HBM3E at up to 8 TB/s bandwidth, and fifth-generation Tensor Cores tuned for NVFP4. Attention-layer throughput benefits from the doubled performance of special function units (SFUs) for transcendental operations, reducing softmax latency and enhancing reasoning responsiveness.
Blackwell Ultra Blackwell Ultra Blackwell Ultra
Return to Keyword Browsing
Nov 11th, 2026 03:09 CST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts