News Posts matching #Instinct

Return to Keyword Browsing

ASUS Showcases Full-Stack AI Infrastructure at SC26, Featuring Intel and AMD Platforms

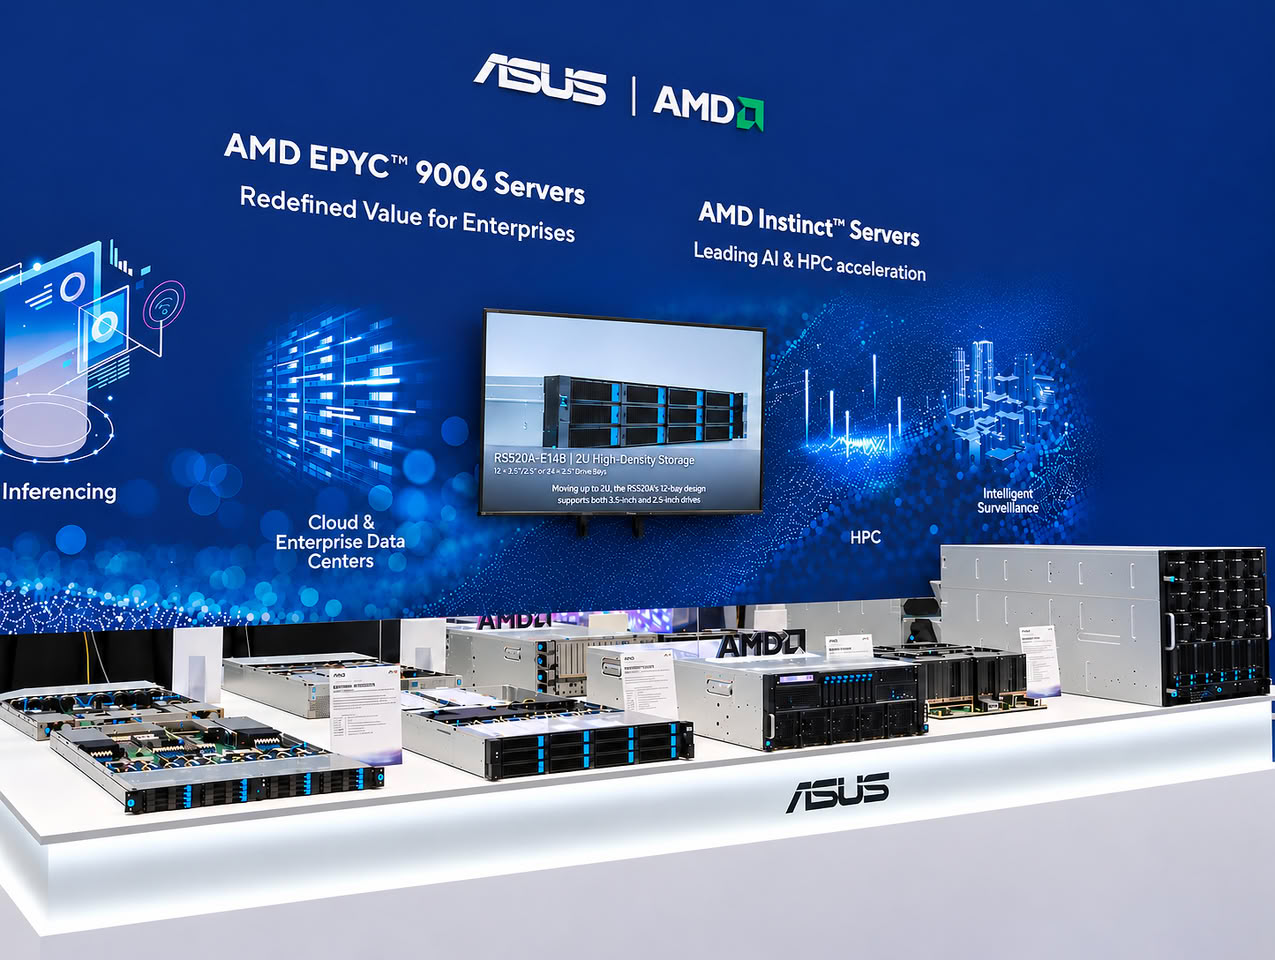
At SC26, ASUS unveils a unified AI Factory blueprint that gives enterprises the flexibility to build AI infrastructure around their workloads, performance targets, and deployment needs. Spanning AMD, Intel and NVIDIA platforms—from rack-scale AI systems and enterprise servers to edge computing—ASUS brings architectural choice together with integrated engineering, automated manufacturing, rigorous validation, and lifecycle support. With volume shipments of its latest rack-scale AI systems underway this quarter, ASUS demonstrates how it turns next-generation computing architectures into deployment-ready infrastructure, helping enterprises move from AI ambition to real-world implementation with greater confidence, consistency, and scalability.

Next-gen power redefines value for enterprise
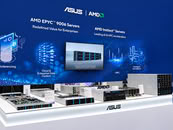
For computationally intensive enterprise deployments, ASUS showcases its lineup powered by the 6th Gen AMD EPYC 9006 processor family, giving organizations more control over compute density, storage capacity and rack space. The dual-socket 1U RS700A-E14B-R16U combines PCIe 6.0 connectivity with support for up to 16 E3.S drives for demanding data and compute services. Single-socket alternatives address different deployment priorities: the 2U RS520A-E14B-R12U offers flexible GPU and NVMe configurations, while the compact 1U RS500A-E14B-R12U concentrates high-speed storage and DC-MHS serviceability in a smaller footprint. At the accelerator level, ESC8000A-E13P supports AMD Instinct MI350P, and the air-cooled XA AM3A-E13 integrates eight AMD Instinct MI355X GPUs for compute-intensive model development and scientific simulation. Across both CPU and GPU offerings, ASUS emphasizes configuration flexibility and serviceability to help customers tailor infrastructure to budget, facility and application requirements.
AMD-Powered Lux Supercomputer Opens to Scientific Users at Oak Ridge

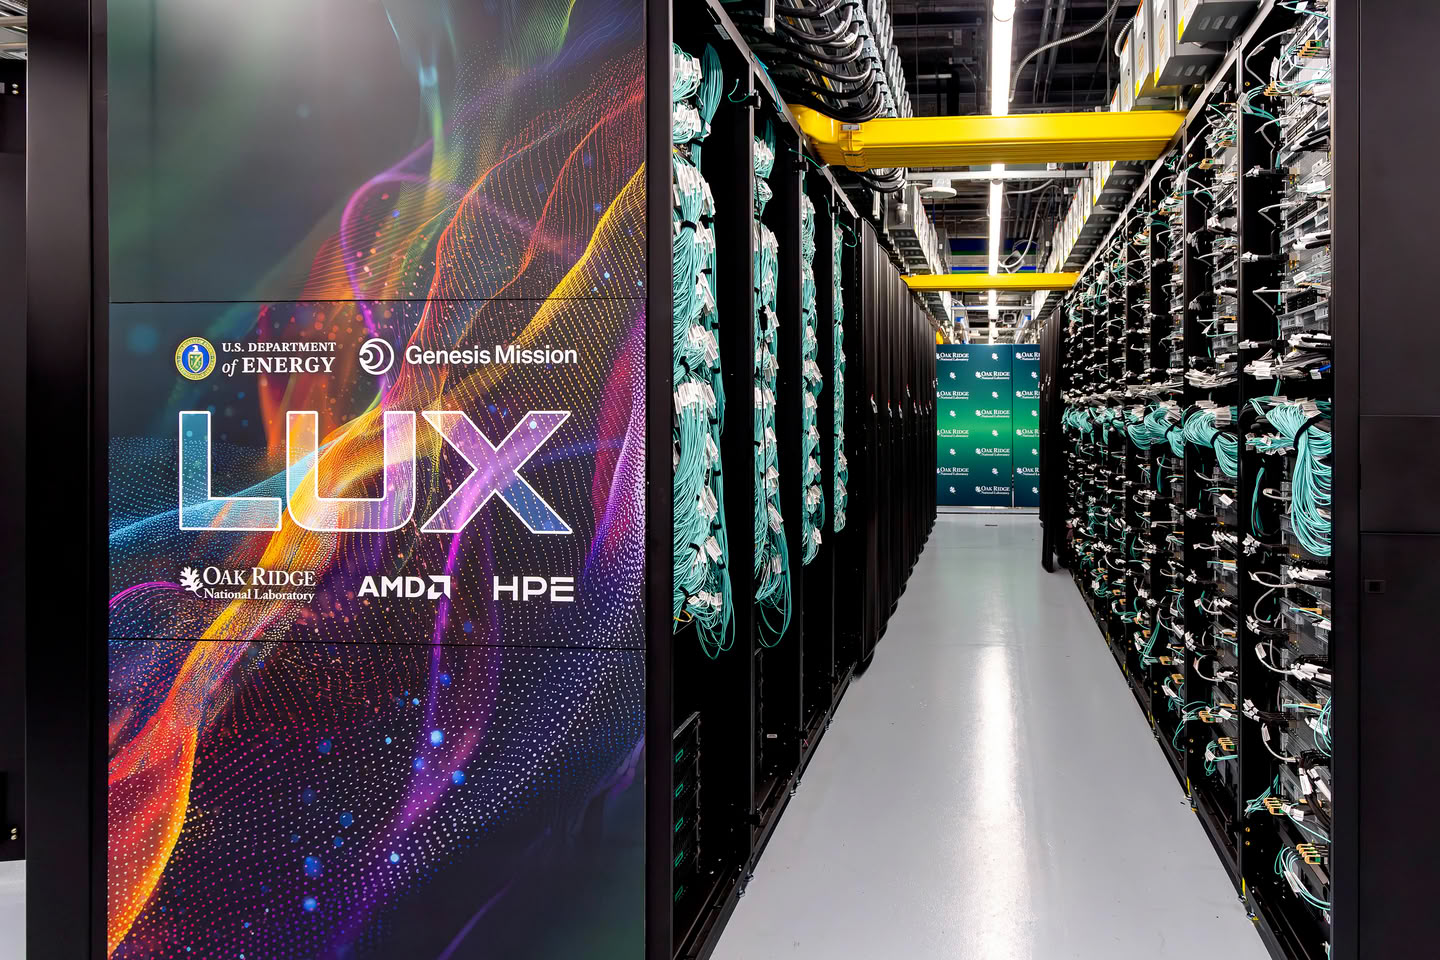
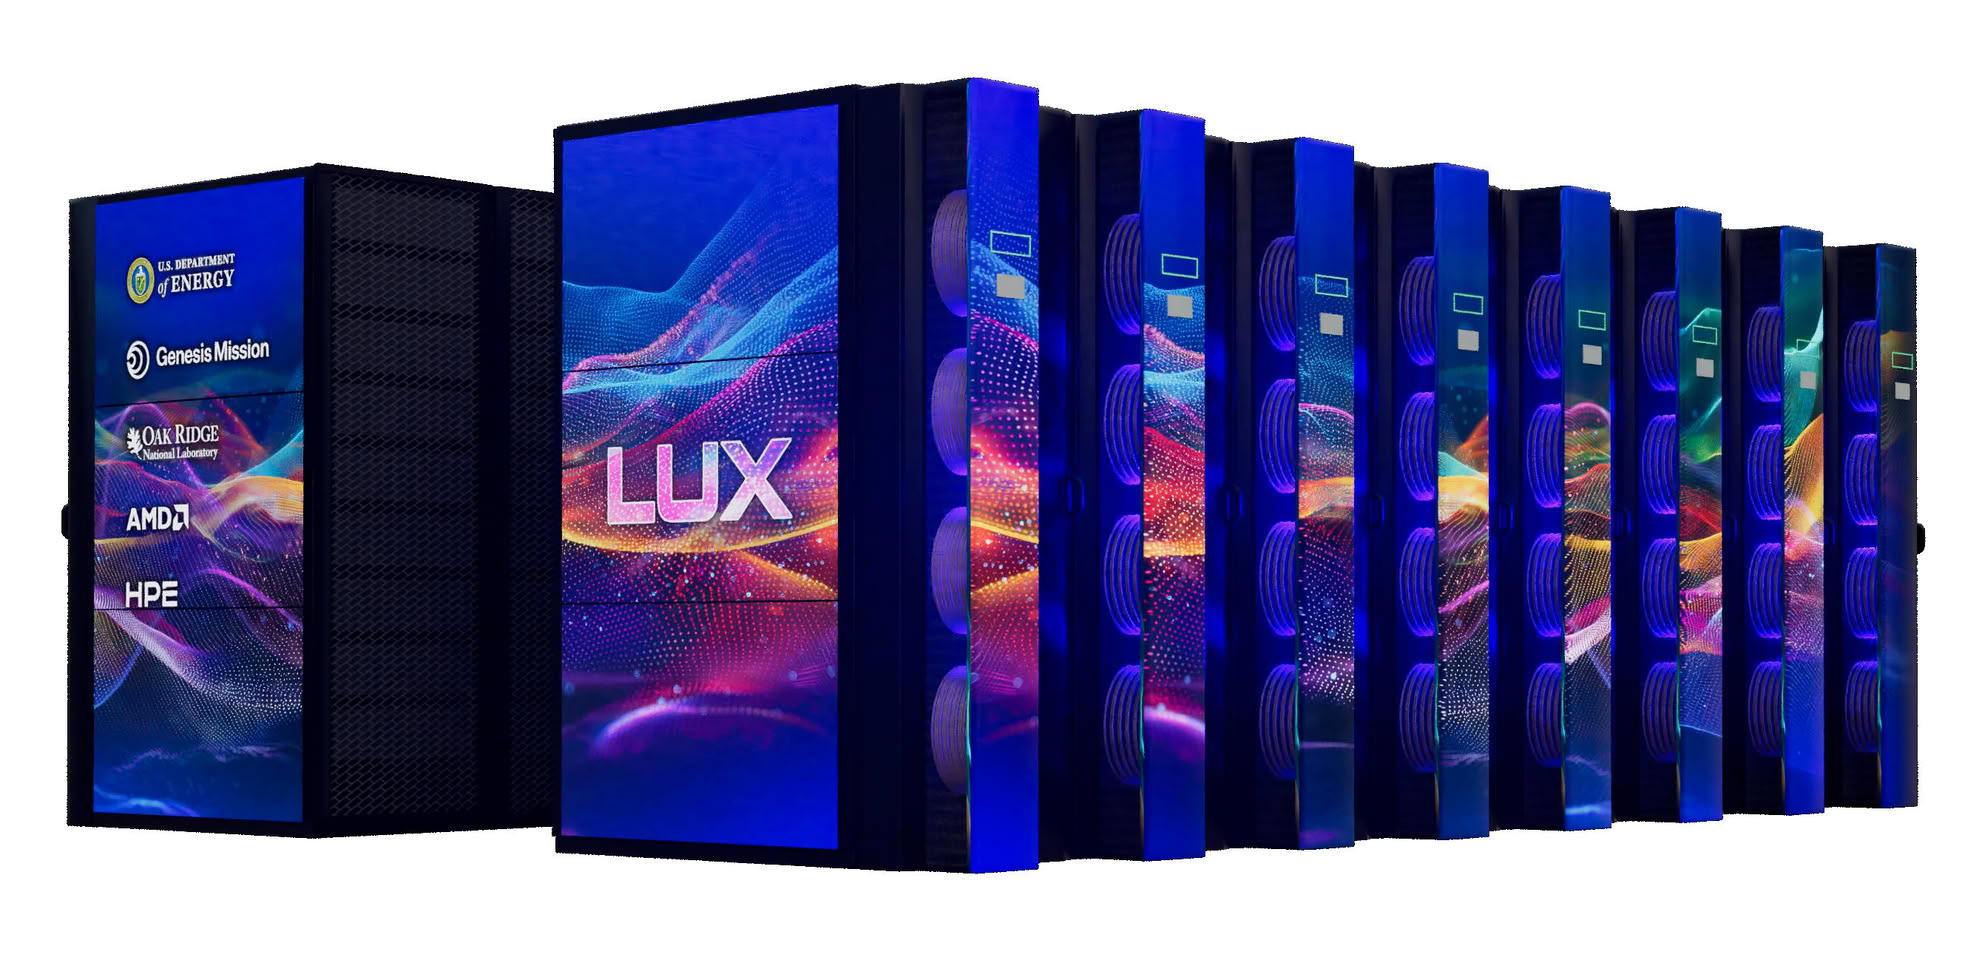
AMD (NASDAQ: AMD) today announced that the Lux SI + HPC supercomputer is open to scientific users at the U.S. Department of Energy's (DOE) Oak Ridge National Laboratory (ORNL). Ranked No. 14 on today's TOP500 list of the world's most powerful supercomputers, Lux was developed through a public-private partnership between AMD and the DOE. The supercomputer provides the first dedicated U.S. AI Factory for the Genesis Mission, the DOE-led initiative to advance AI-driven science.

Lux brings together AMD EPYC processors, AMD Instinct MI355X GPUs, AMD Pensando networking and AMD ROCm software in a system built by HPE. The system combines AI with high-performance modeling and simulation to expand U.S. capabilities in science, energy and national security.

Samsung's 2 nm Taylor Fab 2 Reportedly Fully Booked, Mostly by AMD

Samsung has reportedly booked the entire planned output of its second fab in Taylor, Texas, and most of it is going to AMD. According to an exclusive from Korea's Maeil Business Newspaper, citing industry sources, Taylor Fab 2 will make HBM base dies for AMD and NVIDIA on a 2 nm process, with AMD's orders making up the bulk of it. Apparently, AMD's volume alone is enough to stretch the fab's capacity. Samsung declined to comment, saying it can't confirm customer-related details.

These aren't AMD's CPUs or GPUs, though. The base die is the logic chip at the bottom of an HBM stack, and Samsung plans to pair the Texas-made dies with DRAM produced in South Korea and ship them as finished HBM. Its current HBM4 and the sampled HBM4E use 4 nm base dies, so 2 nm or smaller seems aimed at later HBM generations. The deal also follows Lisa Su's visit to Samsung in October, where Samsung reportedly wanted foundry orders from AMD in return for the HBM that AMD urgently needs. A March MOU had already made Samsung the primary HBM4 supplier for the Instinct MI455X.

AMD Guidance Points to Its First Quarter Ever With More Revenue Than Intel

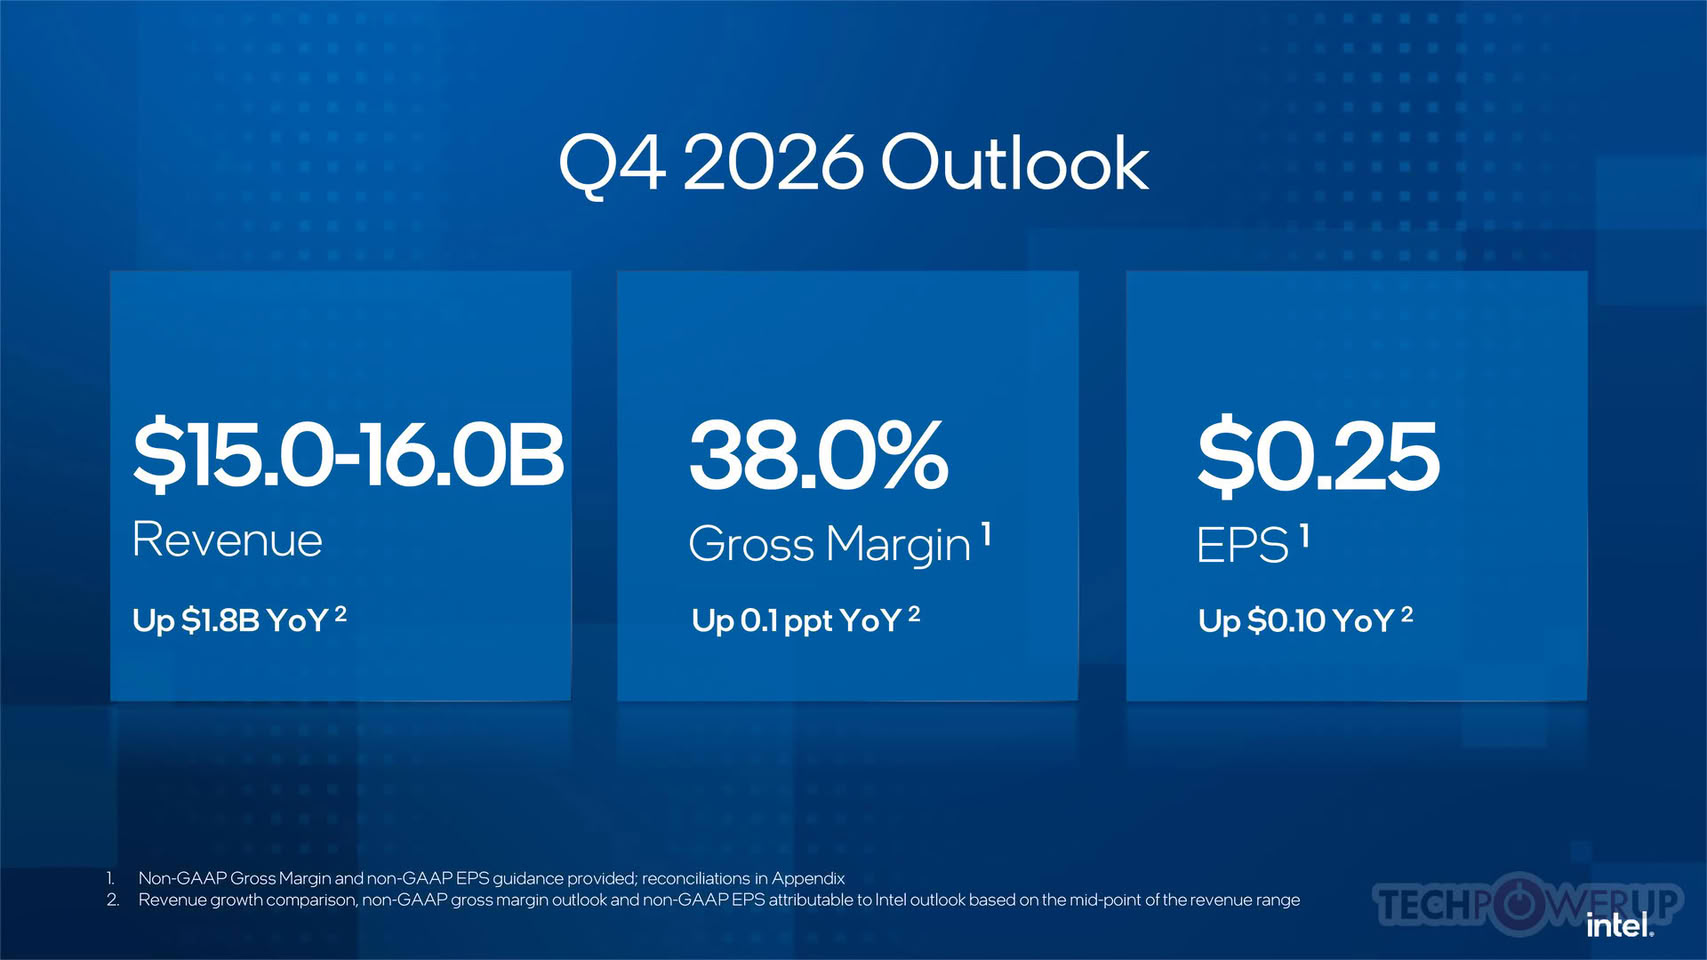
AMD looks set to bring in more quarterly revenue than Intel for what appears to be the first time ever. Alongside its record Q3 2026 results, AMD guided Q4 revenue to approximately $17 billion, plus or minus 3%, or roughly $16.5 billion to $17.5 billion. Intel, on the other hand, expects Q4 revenue between $15 billion and $16 billion. Even the bottom of AMD's range sits above the top of Intel's, so unless either company misses its guidance badly, the flip is pretty much locked in.

Most of AMD's growth comes from the data center. AMD's Data Center segment hit a record $8.5 billion in Q3, up 97% year over year, on strong EPYC demand and the launch of the Instinct MI450 Series GPUs inside its Helios racks. AMD expects the segment to grow about 50% sequentially in Q4, while Client and Gaming is expected to drop by more than 20%. Intel's Q4 outlook, meanwhile, came in well below expectations, partly due to a two-week shutdown at Fab 28 in Israel that Intel says will cost about $300 million in Q4 revenue.

NVIDIA Cuts HBM4 Speed and NVLink Bandwidth Targets for "Vera Rubin"

NVIDIA has officially implemented changes across its "Vera Rubin" product line, reducing target specifications for memory and interconnect fabric. According to the updated product specification sheet, the first change involves HBM4 memory. Previously, NVIDIA used HBM4 with a speed of 11.7 Gbps per pin, which has now been reduced to 9.6 Gbps per pin. In a "Vera Rubin" NVL72 rack-scale solution, NVIDIA now offers a total memory bandwidth of 1,400 TB/s, down from the previously advertised 1,580 TB/s. While this issue does not stem directly from NVIDIA's suppliers, it indicates that the company's implementation of memory bus width and overall electrical signaling is insufficient to support higher speeds.

However, the changes are not limited to memory. NVIDIA has also reduced the previously advertised NVLink bandwidth per GPU, decreasing it from 1.8 TB/s to 1.5 TB/s. This results in a reduction from 3.6 TB/s to 3 TB/s in bidirectional NVLink GPU bandwidth. The underlying issue is related to signal integrity, as NVIDIA reportedly lowered the NVLink Nyquist frequency target from 56 GHz to 47 GHz. Lowering the Nyquist frequency reduces the electrical demands on the SerDes, cables, and materials, which can improve manufacturing yields and overall feasibility, even though it requires accepting a small reduction in peak interconnect bandwidth. Thus, NVIDIA chose to sacrifice some bandwidth to enhance system stability. Below is the new system specification in light mode, and old system specification in dark mode.

AMD Unveils Helion Rack Designed for Agentic AI

AMD (NASDAQ: AMD) today introduced the AMD Helion agentic AI rack, an open blueprint for agentic AI infrastructure based on an Open Compute Project spec-design and powered by AMD compute.

Building on the open-platform approach of the AMD Helios rackscale solution, AMD Helion is designed to provide partners and customers with the flexibility they need for agentic AI infrastructure. With AMD Helion, customers can match CPU performance, core density and power with GPU acceleration for the work their AI agents perform.

AMD CEO Visits Samsung for HBM, Samsung Wants Foundry Orders in Return

AMD CEO Dr. Lisa Su reportedly visited Samsung on October 7th and spent about three hours with Samsung chip chief Jun Young-hyun in Seoul on Wednesday, and a Korean media report suggests the two sides want different things from each other. As relayed by @jukan05 on X, Samsung apparently wants AMD to place orders with Samsung Foundry in return for HBM and other memory, which AMD urgently needs. A senior semiconductor industry official quoted in the report said "AMD sees entrusting its foundry work to Samsung Electronics as too risky," and added that this gap is what brought about the talks. Neither company has confirmed any of it, so it is best treated as an industry report for now.

Su's public comments were far more diplomatic. Speaking to Reuters and other reporters in Seoul ahead of the meeting, she said AMD continues to explore opportunities with Samsung in both memory and foundry. Asked directly whether AMD would build chips at Samsung, she stopped short of confirming any plans. She was more direct about memory, urging suppliers to "build faster, as fast as possible" and noting that AMD is working with customers to trim their memory footprint.

AMD Introduces Threadripper Halo Station at IFA 2026

The opening keynote at IFA 2026 was held by AMD and our team on the ground was there to see it. During the event, AMD announced the Threadripper Halo Station, a liquid-cooled workstation built around the 96-core Threadripper PRO 9995WX CPU codenamed "Shimada Peak" and up to four AMD Instinct MI350P accelerators. The system is designed around one specific use case: run AI models with more than one trillion parameters locally, without a cloud connection. Jack Huynh, AMD's SVP and GM of Computing and Graphics, described it as a new class of workstation bringing supercomputer-class compute to individual users and developers. The Threadripper PRO 9995WX Zen 5 CPU has 96 cores and 192 threads, 5,4 GHz boost frequency and supports up to 2 TB of DDR5 system memory.

Going further down the specifications, each MI350P card features 144 GB of HBM3E running at 4 TB/s, offering a bandwidth 14 times higher than any LPDDR5X variant. At IFA 2026, AMD presented a configuration based on two MI350P PCIe cards for a total of 288 GB of HBM3E memory. Users can upgrade the system to four cards and 576 GB of HBM3E. This amount of accelerator memory is enough, says AMD, to hold a trillion-parameter model entirely on-device. Each Instinct MI350P card has a TBP of up to 600 W and is liquid-cooled independently, as is the CPU. Complete system specifications, availability and pricing have not been announced.

AMD Instinct GPUs and EPYC CPUs to Power Europe's Next-Generation LUMI-AI Supercomputer

The EuroHPC Joint Undertaking (EuroHPC JU) has signed a procurement contract with Bull to deliver LUMI-AI, a next-generation supercomputer at the CSC - IT Center for Science Ltd. data center in Kajaani, Finland. Powered by AMD Instinct MI430X GPUs and 6th Gen AMD EPYC 256-core processors, the system is expected to provide 10 times the AI capacity and nearly twice the high-performance computing (HPC) capability of the current LUMI supercomputer. Deployment is scheduled for the second half of 2027.

LUMI-AI will serve as the computing backbone of the LUMI AI Factory, supporting industrial AI innovation, academic research, AI training and inference, and large-scale scientific simulation. Its combination of AI and high-precision HPC capabilities is designed to strengthen Europe's capacity for data-driven research and innovation while expanding access to advanced computing for researchers, startups and industry.

HPE Showcases Cray Supercomputing GX5000 Featuring 6th Gen AMD EPYC Processors

Today, at AMD Advancing AI 2026 in San Francisco, HPE showcased its latest engineering innovation in supercomputing with the HPE Cray Supercomputing GX5000 featuring 6th Gen AMD EPYC processors. The GX5000 builds on the success of previous HPE supercomputing architecture that broke the exascale speed barrier, and dominates the world's top 10 list of fastest supercomputers, to support the most complex scientific and engineering problems involving AI and quantum.

The GX5000 delivers the industry's highest density performance with 40% more AMD EPYC 9996 cores per rack than the market's next densest offering. The GX5000 also maximizes capacity for growing HPC and AI workloads and improves operational efficiency by reducing carbon footprint with 25% less floor space compared to the previous generation and an increase of warm facility water by 25%, with up to 40C heating capacity, through next-generation direct-liquid cooling capabilities from HPE.

AMD Instinct MI400 Series and Helios Rack Debut: CDNA 5 Goes 2 nm, Plus ROCm.ai and "Gorgon Halo"

AMD used its Advancing AI 2026 keynote today to launch the Instinct MI400 Series, its next-generation data-center GPU family, alongside the Helios rack-scale solution and the CDNA 5 architecture that underpins both. CDNA 5 is AMD's first GPU architecture to reach the 2 nm node, with the flagship Instinct MI455X carrying 320 billion transistors across a multi-chiplet package and 432 GB of HBM4. This is a data-center compute architecture, not a Radeon gaming architecture, though some of the design choices in CDNA 5 point to where AMD's future unified gaming/compute architecture could be headed.

The MI400 Series splits into two parts: the Instinct MI455X for frontier AI and AI-factory deployments, and the Instinct MI430X for sovereign AI and HPC. Together with the Helios rack, 6th Gen EPYC "Venice" CPUs and AMD Pensando networking, they form AMD's open answer to NVIDIA's Vera Rubin NVL72. This post also covers the new ROCm.ai software stack and AMD's "Gorgon Halo" client teaser.

ASRock Rack Unveils Next-Generation Server Portfolio Powered by 6th Gen AMD EPYC Processors

ASRock Rack Inc., a leading innovative server company, today announced support for the newly-launched 6th Gen AMD EPYC 9006 Series processors, unveiled this week at AMD Advancing AI 2026 in San Francisco. ASRock Rack will showcase its upcoming server platforms optimized for the new processor generation at the event, demonstrating its commitment to delivering advanced infrastructure for enterprise AI, cloud, and HPC workloads.

Delivering Leadership Performance for the Agentic AI Era
As agentic AI enters enterprise-scale deployment, the 6th Gen AMD EPYC 9006 Series processors deliver the performance, efficiency, and scalability required to support increasingly complex AI services and applications. Featuring up to 256 cores, industry-leading 5 GHz frequencies, and PCIe Gen 6 connectivity, 6th Gen EPYC Server CPUs enable organizations to scale AI agents, maximize AI host-node throughput and GPU utilization, and power the general-purpose workloads essential to modern data centers.

Supermicro Introduces New Server Portfolio with 6th Gen AMD EPYC 9006 Series CPUs, Delivering 1.7x Generational Performance Improvements

Super Micro Computer, Inc., an AI, Enterprise, Storage, and 5G/Edge Total IT Solution Provider featuring Data Center Building Block Solutions (DCBBS), today announced its next-generation H15 server portfolio powered by 6th Gen AMD EPYC 9006 Series CPUs, optimized for next generation GPUs including AMD Instinct, and connected by AMD Pensando networking. With up to 256 cores and 512 threads, H15 systems meet the growing compute demands of cloud, enterprise, storage, high-performance computing (HPC), and agentic AI workloads. With breakthrough 1.7x generational CPU performance improvement1, expanded memory and I/O bandwidth, and industry-leading compute density, customers are now able to run more concurrent AI agents, accelerate enterprise applications, and maximize host-node performance while operating within existing power envelopes.

"The latest AMD powered additions to our DCBBS family deliver the next generation of AI infrastructure, optimized for high performance, rapid scalability, and peak efficiency," said Vik Malyala, Chief Business Officer at Supermicro. "Backed by our global services team, resilient U.S. supply chain, and consistent investment in US AI innovation, we continue to help customers deploy and scale AI with confidence."

MiTAC Shows Liquid and Air Cooled Servers, Debuts 96-GPU AMD Instinct MI355X Rack at Computex 2026

MiTAC showcased an extended portfolio of HPC, servers and enterprise components at Computex 2026, among them being AMD Instinct MI350X air-cooled servers, MI355X liquid-cooled systems and enterprise MI350P PCIe accelerator cards. On display was an impressive 52U liquid-cooled AI rack built around 12x G4826Z5 servers and 96 AMD Instinct MI355X GPUs. In the server area MiTAC presented a 4U liquid-cooled G4826Z5 server powered by AMD Instinct MI355X accelerators and the 8U air-cooled G8825Z5 featuring Instinct MI350X GPUs.

NVIDIA MGX architecture AI servers powered by 6th Gen AMD EPYC processors and NVIDIA Blackwell B200 GPUs were also presented.

AMD Announces More Than $10 Billion in Taiwan Ecosystem Investments to Accelerate AI Infrastructure

To meet the growing demand for AI infrastructure, AMD (NASDAQ: AMD) today announced more than $10 billion in investments across the Taiwan ecosystem to expand strategic partnerships and scale advanced packaging manufacturing for next-generation AI infrastructure. Working with strategic partners in Taiwan and globally, AMD is advancing leading-edge silicon, packaging and manufacturing technologies that enable higher performance, greater efficiency and faster deployment of AI systems. These efforts build on AMD's deep ecosystem partnerships and long-standing leadership in chiplet architectures, high-bandwidth memory integration, 3D hybrid bonding and rack-scale system design for next-generation AI infrastructure.

"As AI adoption accelerates, our global customers are rapidly scaling AI infrastructure to meet growing compute demand," said Dr. Lisa Su, Chair and CEO, AMD. "By combining AMD leadership in high-performance computing with the Taiwan ecosystem and our strategic global partners, we are enabling integrated, rack-scale AI infrastructure that helps customers accelerate deployment of next-generation AI systems."

AMD Launches Instinct MI350P PCIe GPUs

As organizations adopt AI, many discover that their infrastructure struggles to keep up. Running AI in the cloud is an option, but the cloud can introduce privacy concerns and unpredictable costs. Upgrading on-prem infrastructure is another option, but supporting large GPU-accelerator platforms can require expensive redesigns in data center power and cooling. Our new AMD Instinct MI350 PCIe cards give your enterprise a third option: Leadership AI performance designed to fit the data center infrastructure you already own.

Performance That Drops into Your Existing Racks
Designed to help you prepare for the agentic AI era, AMD Instinct MI350P PCIe cards are dual-slot drop-in cards for standard air-cooled servers. They are built to deploy inference on premises within your current data center's power, cooling and rack infrastructure. AMD Instinct GPUs in cost-effective PCIe cards round out the AMD AI compute portfolio, providing a range of options for your enterprise as it navigates its unique AI adoption curve.

AMD Stock Hits Record High Above $300 as AI Optimism Fuels Rally

AMD's stock has been experiencing a significant rise over the past few months, with the company's share price reaching a record $303.46 at the time of writing and a market capitalization of nearly half a trillion USD, precisely $494.74 billion. Historically, AMD's stock has struggled to match the levels of NVIDIA and, to some extent, Intel. However, the company has seen a massive turnaround with the expansion of AI data centers. AMD has been performing well in the data center space with its EPYC processors and Instinct MI accelerators, and the stock price has followed this upward trajectory. This is AMD's best stock performance yet, supported by a strong current and upcoming product portfolio that has major investors confident in the company's operations, financials, and execution of plans.

AMD is on track to ship its EPYC "Venice" server CPUs with "Zen 6" architecture, the Instinct MI400 series of accelerators for AI training, inference, and HPC workloads, and Pensando "Vulcano" AI NICs, all housed within a rack-scale system called "Helios." Expected to match and exceed NVIDIA's "Vera Rubin" in some areas, AMD will be competitive in the world's largest industry today—AI data centers. However, the company is not resting on its laurels and has already prepared a 2027 update of this product portfolio for the next-generation AI rack. This execution has instilled confidence in AMD's investors, driving the stock price significantly higher.

AMD and Meta Announce Expanded Strategic Partnership to Deploy 6 Gigawatts of AMD GPUs

AMD and Meta today announced a 6-gigawatt agreement to power Meta's next generation of AI infrastructure across multiple generations of AMD Instinct GPUs. This agreement expands on the companies' existing strategic partnership and aligns roadmaps across silicon, systems and software to deliver AI platforms purpose-built for Meta's workloads. The first deployment will use a custom AMD Instinct GPU based on the MI450 architecture to deliver AI platforms that are optimized for Meta's workloads at gigawatt-scale. Shipments supporting the first gigawatt deployment are scheduled to begin in the second half of 2026 powered by the custom AMD Instinct MI450-based GPU and 6th Gen AMD EPYC CPUs, codenamed "Venice," running ROCm software and built on the AMD Helios rack-scale architecture. AMD Helios was developed jointly by AMD and Meta through the Open Compute Project to enable scalable, rack-level AI infrastructure.

"We are proud to expand our strategic partnership with Meta as they push the boundaries of AI at unprecedented scale," said Dr. Lisa Su, chair and CEO, AMD. "This multi-year, multi-generation collaboration across Instinct GPUs, EPYC CPUs and rack-scale AI systems aligns our roadmaps to deliver high-performance, energy-efficient infrastructure optimized for Meta's workloads, accelerating one of the industry's largest AI deployments and placing AMD at the center of the global AI buildout."

AMD Shoots Down Report of Delayed Instinct MI455X Accelerator Launch

Yesterday, a Semi Analysis article predicted the postponement of a forthcoming AMD Instinct MI455X AI mass manufacturing phase. As covered by TechPowerUp this morning, this controversial forecast places Team Red's next-gen design in a precarious position, especially when compared to the apparent rapid progression of NVIDIA's competitive "Vera Rubin" server-grade hardware. This evening, Anush Elangovan has responded to the latest claims—the Corporate Vice President of AMD AI software and solutions issued a curt reply to a tech industry analyst's quoting of Semi Analysis' hit piece: "B.S (bullshit). Right on target for H2 2026."

The high volume rollout of Team Red's first rack scale "Helios" MI455X UALoE72 system has—allegedly—been plagued with engineering sample problems and manufacturing hiccups. In a separate social media post, Elangovan insisted that the finalized MI455X model will not be postponed into the second quarter of 2027: "speed is the moat. MI455X is both fast, and is the fastest I have seen in execution for bring-up of a complex GPU platform. MI455X is right on target for shipments in 2H2026—irrespective of what Semi Analysis says—rev your engines because speed is coming." Technology-wise, AMD's Artificial Intelligence Group (AIG) seems ready to answer NVIDIA's incoming new-gen wave, but it is not clear whether the upcoming "Helios" rack system can compete in terms of sheer factory output numbers.

Comcast, Classiq and AMD Demonstrate Quantum Algorithm for More Resilient and Reliable Internet

Classiq, the leading quantum computing software company, Comcast and AMD today announced the completion of a groundbreaking trial aimed at improving Internet delivery by leveraging quantum algorithms to supercharge network routing resilience.

"What our customers want is simple: fast, secure and reliable connectivity, but when you operate a network as large and dynamic as ours, delivering on that promise is complex, especially in the face of growing network demand," said Elad Nafshi, Chief Network Officer, Comcast Connectivity and Platforms. "We launched these trials with Classiq last year with the goal of understanding how quantum software and technology could tackle real network challenges. Our results have shown that quantum computing for network optimization isn't theoretical - it's practical, scalable, and grounded in the needs of our customers."

SoftBank and AMD Validate GPU Partitioning for AI Workloads Using Instinct GPUs

SoftBank and AMD have started joint validation of AMD Instinct GPUs for next-generation AI infrastructure by focusing on a GPU partitioning mechanism that lets a single GPU handle multiple AI workloads simultaneously. SoftBank developed an Orchestrator system that divides AMD Instinct GPU resources based on workload requirements: model size, number of concurrent executions, and memory needs. The system splits compute workloads across multiple GPU instances running on individual Accelerator Complex Dies (XCDs). These can range from single instance mode (SPX mode) up to eight instances (CPX mode). The HBM memory pools are also divided into individual regions for each GPU instance to prevent latency spikes. The goal is to avoid the inefficiency of uniform GPU resource allocation, which can lead to GPU resource shortages or waste depending on workload demands.

SoftBank says the enhanced Orchestrator runs multiple AI applications on a single GPU with minimal resource strain. No performance figures have been shared yet, though SoftBank mentions improved resource allocation for small and mid-size language model workloads. The company also plans to explore similar orchestration for other AI accelerators beyond AMD. A live demonstration is planned at the AMD booth during MWC Barcelona 2026 in March 2-5. SoftBank also published technical details on architecture and Orchestrator management methods on its Research Institute of Advanced Technology blog. In a recent report, we noted that AMD's next-gen Instinct MI455X accelerators, set to compete with NVIDIA's Vera Rubin, are running into serious manufacturing problems that are pushing back AMD's roadmap. Only limited production is expected this year, with mass production pushed to Q2 2027.

AMD Announces Day 0 Support for Qwen 3.5 LLM on Instinct GPUs

AMD is excited to announce Day 0 support for Alibaba's latest generation of Large Language Models, Qwen 3.5, on AMD Instinct MI300X, MI325X, and MI355X GPU accelerators, in close collaboration with Alibaba Qwen team. Leveraging the optimized ROCm software stack, SGLang and vLLM inference serving framework, developers can immediately deploy these state-of-the-art models.

The Strategic Value of Qwen 3.5 on AMD Instinct
Empowering Next-Generation AI Agents—This Day 0 enablement is designed for AI developers, system architects, and DevOps professionals building the next wave of AI agents and enterprise platforms. While previous models required trade-offs between parameter depth and reasoning speed, the Qwen 3.5 family on AMD Instinct GPUs allows teams to deploy massive 256K context windows and complex multimodal workflows with unprecedented efficiency.

AMD's State-of-the-Art "Helios" Rack-scale AI Architecture Heading to India

AMD, a leader in high-performance and AI computing, and Tata Consultancy Services, a global leader in IT services, consulting, and business solutions, have expanded their strategic collaboration. TCS, through its subsidiary HyperVault AI Data Center Limited (HyperVault), and AMD will codevelop a rack-scale AI infrastructure design based on the AMD "Helios" platform in support of India's national AI initiatives.

Powered by GPUs, next-generation AMD EPYC "Venice" CPUs, AMD Pensando Vulcano NICs and the open ROCm software ecosystem, "Helios" is purpose-built to deliver a rack-scale AI platform supporting sovereign AI factories. "Helios," combined with TCS' enterprise expertise and scale, will accelerate deployment and enhance operational efficiencies for enterprises. As part of this strategic collaboration, both companies will offer an AI-ready data center blueprint supporting up to 200 MW of capacity and will work with hyperscalers and AI companies to accelerate data center build-outs in India.

AMD Reports Record Q4 $10.3 Billion Revenue, FY 2025 Reaches $34.6 Billion

AMD (NASDAQ:AMD) today announced financial results for the fourth quarter and full year of 2025. Fourth quarter revenue was a record $10.3 billion, gross margin was 54%, operating income was $1.8 billion, net income was $1.5 billion and diluted earnings per share was $0.92. On a non-GAAP basis, gross margin was 57%, operating income was a record $2.9 billion, net income was a record $2.5 billion and diluted earnings per share was a record $1.53.

For the full year 2025, AMD reported record revenue of $34.6 billion, gross margin of 50%, operating income of $3.7 billion, net income of $4.3 billion, and diluted earnings per share of $2.65. On a non-GAAP basis, gross margin was 52%, operating income was a record $7.8 billion, net income was a record $6.8 billion and diluted earnings per share was a record $4.17.

AMD Intros ROCm v7.2 - Smarter, Faster, & More Scalable for Modern AI Workloads

Modern AI workloads demand more than raw compute—they require a tightly integrated software stack that can extract maximum performance, scale efficiently across systems, and operate reliably in production environments. With the latest ROCm 7.2 release, we're delivering a broad set of optimizations and software enhancements designed to improve developer productivity, runtime performance, and enterprise readiness.

In this blog, we highlight the latest ROCm 7.2 enhancements for AMD Instinct GPUs, designed to boost AI and HPC performance. Learn how hipBLASLt and GEMM optimizations, FP8/FP4 support in rocMLIR and MIGraphX, and topology-aware communication with GDA and RCCL deliver higher throughput and lower latency. We also cover AI model tuning for AMD Instinct MI300X and MI350 GPUs and Node Power Management (NPM) for efficient multi-GPU operation—together enabling faster, more scalable, and reliable AI workloads.
Return to Keyword Browsing
Nov 18th, 2026 12:48 PST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts