Wednesday, March 4th 2026

NVIDIA Reportedly Preparing 9 GB GeForce RTX 5050 Variant with GDDR7
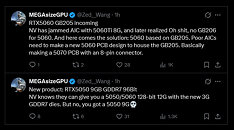
NVIDIA is reportedly planning a second RTX 5050 variant with 9 GB of memory instead of the standard 8 GB, according to leaker MEGAsizeGPU who has a decent track record on NVIDIA leaks. Unlike the existing RTX 5050, which uses 8 GB of 20 Gbps GDDR6 memory on a 128-bit bus for 320 GB/s of bandwidth, the new model is said to adopt 3 GB GDDR7 modules. The updated configuration would total 9 GB across a 96-bit memory bus. While the narrower bus reduces interface width, the move to 28 Gbps GDDR7 would raise total memory bandwidth to 336 GB/s, a roughly 5% increase, alongside a 12.5% boost in VRAM capacity. Core specifications are expected to remain unchanged. The card would continue to use the GB207 GPU, based on the Blackwell architecture, with 2560 CUDA cores and a 130 W TDP. No changes to clock speeds or core counts have been mentioned.
The report also claims NVIDIA is preparing adjustments higher up the stack. A revised GeForce RTX 5060 may transition to the larger GB205 die, currently used in the RTX 5070, in a cut-down configuration. That would reportedly reduce the GPU from 6144 CUDA cores and a 192-bit bus to 3840 cores and a 128-bit interface. Such a move would require board partners to adopt new PCBs compatible with GB205 and standard 8-pin power connectors. According to the leak, these changes are tied to supply constraints affecting lower-tier RTX 50-series GPUs, including the RTX 5050 and RTX 5060. The GeForce RTX 5060 12 GB, which appeared in earlier roadmaps, is now reportedly canceled.
Sources:
Videocardz, MEGAsizeGPU
The report also claims NVIDIA is preparing adjustments higher up the stack. A revised GeForce RTX 5060 may transition to the larger GB205 die, currently used in the RTX 5070, in a cut-down configuration. That would reportedly reduce the GPU from 6144 CUDA cores and a 192-bit bus to 3840 cores and a 128-bit interface. Such a move would require board partners to adopt new PCBs compatible with GB205 and standard 8-pin power connectors. According to the leak, these changes are tied to supply constraints affecting lower-tier RTX 50-series GPUs, including the RTX 5050 and RTX 5060. The GeForce RTX 5060 12 GB, which appeared in earlier roadmaps, is now reportedly canceled.


126 Comments on NVIDIA Reportedly Preparing 9 GB GeForce RTX 5050 Variant with GDDR7
Usual 5050 even when undervolted to limits (0.73V), still uses too much power for single slot/no additional power requirement :
Same goes for 3050 8GB :
9GB 5050, just might have enough wiggle room on power side to enable single slot/no ext. power designs.
Maybe...
The die is designed as 128 bit. This doesn't change.. outside disabling 1 32 bit controller.
I've done those tests and a laptop 4060 (same silicon, core count, bus width, slightly lower GDDR6 speed as desktop 4060) performs quite well at 70W and is ~70% faster than the current best 70W consumer GPU, the RTX 3050 6GB. The 8 or 9GB 5050 would be a great option at 70W and perform similarly to the 4060.
Put another way: gaming laptops have been shipping with the 4060 for over 3 years now and many are 70W and lower designs. This GPU has already existed for over half of the 2020s and works well, it just needs to be released with these specs for 70W slot-powered desktops. Either 5050 is a functionally identical design.
that if we call "office PC" - "i5-i7 8+ gen" - it's STILL good PCs, not for HARDCORE gaming of course.
But for GENERIC John Doe Excel powwwa machine - i5+ starting from already 7 gen. was stupidly unneeded power, same stuff as driving pickup trucks in city-only conditions.I also don't consider "china underground mobile-to-desktop converted hardware" anything viable due to unknown lifespan, but that's besides the point:D
have seen RTX 3050 6 Gb just a little cheaper than normal 8 Gb version...:D what the sellers smoke, "smoke weed every day ftw!":D
Nvidia would have done better with just uncrippling the PCIe interface or a combo of that and more VRAM.
While the 1 extra gigabyte of VRAM will help in some games even with the crippling of the memory bus, the benefit is extremely marginal since most of the games that end up struggling with 8GB, e.g., Hogwarts Legacy, Monster Hunter Wilds, and various others, ended up needing to allocate VRAM in the 10+GB range.
As slow as the 5050 is, the GPU is still quite capable and there are games where the primary limiting factor in the user experience assuming you just want a 60FPS experience, is the VRAM.
A truly good improvement would be the 9GB of VRAM in addition to increasing the interface to PCIe 5.0 X16. For most games with minimal impact, you could effectively treat it like an 11GB card.
One of the biggest benefits of PCIe 5.0 has been the increase in throughput headroom before the interface saturated and caused manor frame time and performance issues.
ALL desktop GPUs made today are TDP "locked" from factory, and there is exactly 0 of them that don't throttle while running at 75W TDP.
The only difference between cards is amount of frame drops/"micro stutter" caused by clock/voltage throttling while running a variable workloads.
PS.
I tested one game too BTW, 5050 :
RTX 3050 :
And RTX 4060 ;)
No it's not going to run at 3000 MHz but it's going to deliver very good performance and what you show is exactly how the current 3050 6GB works compared to the regular 3050: at lower but still good clock speeds while delivering the vast majority of the performance, all while being much faster than the product it replaced, the 1650.
Remember when AMD rapidly repurposed a mobile GPU into a desktop card while axing expected desktop features, with a completely gimped bus, performing significantly lower than expected based on the line-up above it relative to the previous generation, with only 4GB VRAM after publicly saying that's not enough, at an insultingly high MSRP, during a GPU shortage, to fleece as many desperate buyers as they could?
Pepperidge Farm remembers.
The RTX 5050 9GB is highly unlikely to end up with anywhere near as much egg on it's face the 6500 XT has, if any really.So many seem to miss the bandwidth comparison... By specs alone I don't see it being any slower than the current 5050, it would perform at least about the same if not better with more VRAM. Honestly seems like the opposite of enshitification.
With modern games, not all assets need the full throughput of the VRAM, and video cards have been pretty good at managing VRAM for a long time. e.g., with the GTX 970, the 512MB pool of VRAM ran at around 25GB/s, while the 3.5GB would run at around 256GB/s depending on how it is clocked. While the 512MB pool was slow, the performance impact was very minimal for most games, as the card was at least smart enough to not push anything that is extremely throughput sensitive in the slow pool. Furthermore, when the GTX 970 experienced spillover to system RAM, it would gradually unload that 512MB chunk of VRAM and just use 3.5GB on the card, and shared memory making up the rest (apparently there was a latency penalty from trying to juggle 3 different memory pools, with 2 being slow poold of memory).
With that in mind, a faster PCIe interface has a truly massive performance difference when it comes to shared memory use cases.
For example, the RX 9060 is about 15% slower than the RTX 5060, but once you need to use a few GB of shared memory, the performance differences change drastically.
Overall, the biggest crippling that Nvidia has done is refusing to offer PCIe 5.0 X16 on their lower end cards. The extra throughput capability effectively allows you to use 2+GB of shared memory, with some games allowing well above that, especially ones where game world assets are swapped periodically, for example Ratchet & Clank: Rift Apart, with PCIe 3.0 X16, that that game can allocate 3+GB of shared memory without much of a performance hit beyond a larger frame time spike when going through a rift, which really just teleports you under the map to an area that it preloads but leaves all NPCs inactive and all physics and animations stopped. When you use a card with low VRAM, it has a lot of low priority assets that it can shift over the system RAM, and swap as needed depending on which rift you enter.
Outside of edge cases like Ratchet & Clank: Rift Apart, usually with PCIe 4.0 X16, you can use around 1-1.5GB or so of shared memory before performance takes a massive hit
PCIe 3.0 X16 can often do 400-700MB of shared memory before performance takes a major hit.
At least when I saw a 5070 (12 GB) dip it was way nastier than when a 4070 Ti (same 12 GB) dipped at the same games.
But I will bite :
Ad. 1. One of oldest ways to do marketing is to create "buzz" - "it doesn't matter what they talk about you - the most important thing is everyone talks about it". As for source : Just read a book on marketing 101 LOL
Ad. 2. I think it was self explanatory ?
Not sure why you think this is trash talk when it's plain fact (as in - no other desktop GPUs are released with 24Gbit G7 memory at this point in time). They want to launch it on 5050, because it has lowest chip/card ratio (ie. lowest cost with highest possible availability).
Ad. 3. History of this kind of products launches.
Recent two : RTX 3050 (6GB), GT 1030 (DDR4) - changing bottom line product usually meant making it as cheap as possible to produce with performance being "second class citizen".
Sure, we did get +12% on memory capacity (1 whole GB), with single digit bandwidth uplift.
However, do you REALLY think this is going to make a bad product (which current 5050 definitely is), into a good one in current market reality (with all RTX 5060s and RX 9060s 8GB options being available for not much more than 5050) ?
Sure, you can claim we don't know exact prices yet, but I tend to be a pessimist when it comes to this kind of thing.
It's not trash talk though, just a pessimistic view on situation.
There are however outliers, a handful games where you see "comparable" GPUs get a noticeable performance drop (like ~10-30% or more), while still being playable. If this was due to actual swapping frame by frame, the performance would tank completely and create a unplayable stuttering mess. But if you look closer, you'll see the GPU load is completely different. This is actually due to malfunctioning LoD scaling, if not a driver issue. In the example you provided, e.g. RTX 2060 6GB performs better than RTX 5060 8GB, so there's clearly something funky going on in the game engine.
If you want to pay extra for "double" VRAM, that's fine by me, but it only really matters in edge-cases for gaming. Game engines these days are increasingly crap, so some might argue this justifies it, but by the time you're considering e.g. RX 9060 XT 16B or RTX 5060 Ti 16GB, RTX 5070 12GB is very close and much more powerful.Significant swapping frame-by-frame would ruin performance regardless of PCIe bandwidth. The bigger issue with lower bandwidth is that it might be too slow for asset streaming to keep up so you avoid delays, as asset streaming needs to stay "ahead". With only 8 lanes at disposal, running on PCIe 4.0 or 3.0 platforms becomes an issue because you're getting twice the bottleneck vs. 16 lanes. This is largely a software issue though, as if games were made well enough, this would scale perfectly fine.
Modern DRAM implementations no longer mean a slide show, instead it means that your PCIe videocard begins to perform a lot more like low end integrated graphics but with some more variation in the frame time. I have done the testing with a number of different cards, including a GTX 970, RTX 2060, RTX 3060 (when repasting a used one for a friend), though with the Radeon 7800XT is it harder to test because it is harder to find games where I can push VRAM usage past 16GB, in a way where I don't run into a completely unusable GPU bottleneck. Though for lower VRAM, especially 6GB and below, it is easier to cause spillover and vary it more accurately. PS, for extreme out of memory situations, sometimes a card can act strange with the way it boosts clock speeds, if clock speeds become very inconsistent, then you need to go into the driver settings and change the power management to "Prefer maximum performance", otherwise you will lose even more performance compared to a card that is keeping a more consistent clock speed even though it is waiting on system RAM much of the time.
For the screenshots below, those were older tests, though the behavior was consistent, performance would gradually slow until the GPUz showed a bus usage of 50%, then the power usage will effectively be cut in half and performance would be drastically slower. Then as you allocate more and more shared memory, if it is assets that are not too throughput sensitive, then additional performance degradation becomes more gradual. Simply put, not every bit of data written to VRAM has the same read speed demands, and those items with lower throughput demands can be safely moved to system RAM at least until their combined needs lead to saturation.
There are outliers, e.g., the initial unpatched version of hogwarts legacy from before they patched it to stop loading textures when you ran out of dedicated VRAM, it could easily become a slideshow with just a few hundred MB of spillover as a lot of what loaded into memory was pretty demanding on VRAM throughput, thus not much to move to shared system memory without experiencing a massive penalty.
Other outliers are games like Marvel's Guardians of the Galaxy, would have a more condensed version of the performance drop where at a certain point something VRAM throughput intensive would spillover and you would go from a 20% PCIe bus utilization, to complete saturation suddenly and become a slideshow.
The game and game engine have a lot of influence over the performance hit, but so far I have not seen any games where even the tiniest amount of spillover would completely ruin the performance.
RX 9060 XT with 320 GB/s of bandwidth achieving an average of 112 FPS, which means the theoretical limit of how much VRAM which can be used within a single frame to be 2.86 GB, assuming 100% saturation (which is never the case) and that nothing is accessed multiple times. In reality though, most games are using multiple render passes (which in turn means most of the data is used several times during a frame) and some assets are also reused within the frame, and some buffers are written to and reused several times. So essentially, the average unique data read per frame will in this case be ~1-1.5 GB (including temporary buffers and several mip levels for textures). This also shows that even 8 GB is plenty for a buffer zone close to the camera, and in the few games it works poorly, it's due to bad resource management.
At 112 FPS, a x16 PCIe 5.0 bus would allow for a theoretical ~576 MB to be received during the frame, assuming no overhead, and no latency on either end. In reality though, if it happens through page faults, the resulting bandwidth will be a tiny fraction of that. Rendering is a pipelined queue of operations, and it doesn't take a large amount of page faults for a massive performance impact. The only good way to stream a significant amount of data would be through preemptive streaming of resources by the game engine. (There have been other approaches like with id tech, resulting in texture popping.)
Back to RX 9060 XT, if we for fun wanted to read the entire 8 GB during a frame, the memory bus would limit the max FPS to 40 FPS, now imagine trying to use 16 GB and you'll hopefully see how it becomes pointless. :)
Beyond that, your analogy assumes 100% no GPU bottleneck, which is extremely rare outside synthetic workloads, e.g., a VRAM benchmark.
Furthermore, the work needed to completely render a frame will not have uniform throughout demands on the VRAM and system RAM. When spillover happens you will see using a tool such as GPUz that the bus usage will gradually increase as more shared memory is allocated by the game. The reason why shared memory even works for modern cards, is because a cache miss that leads all the way to shared system RAM is statistically extremely rare in that it makes up an extremely small portion of overall IO/s taking place, but when that data is needed, it needs to be made available.
Video cards and applications implement methods of ensuring that the most useful and most reused data is prioritized for the fastest tiers of memory and cache. The moment highly reused data for the video card ends up needing to be stored on shared system RAM, is the moment a game becomes completely unplayable, and depending on how it handles a sideshow, even crashing, e.g., think The Callisto Protocol, where with playtime as you move to more complex areas, the VRAM needs increase and it gradually spills over to system RAM. After a small initial slowdown, it all of a sudden becomes completely unplayable.