News Posts matching #hyperscaler

Return to Keyword Browsing

SK hynix Expects Memory Demand to Outpace Supply Through 2030

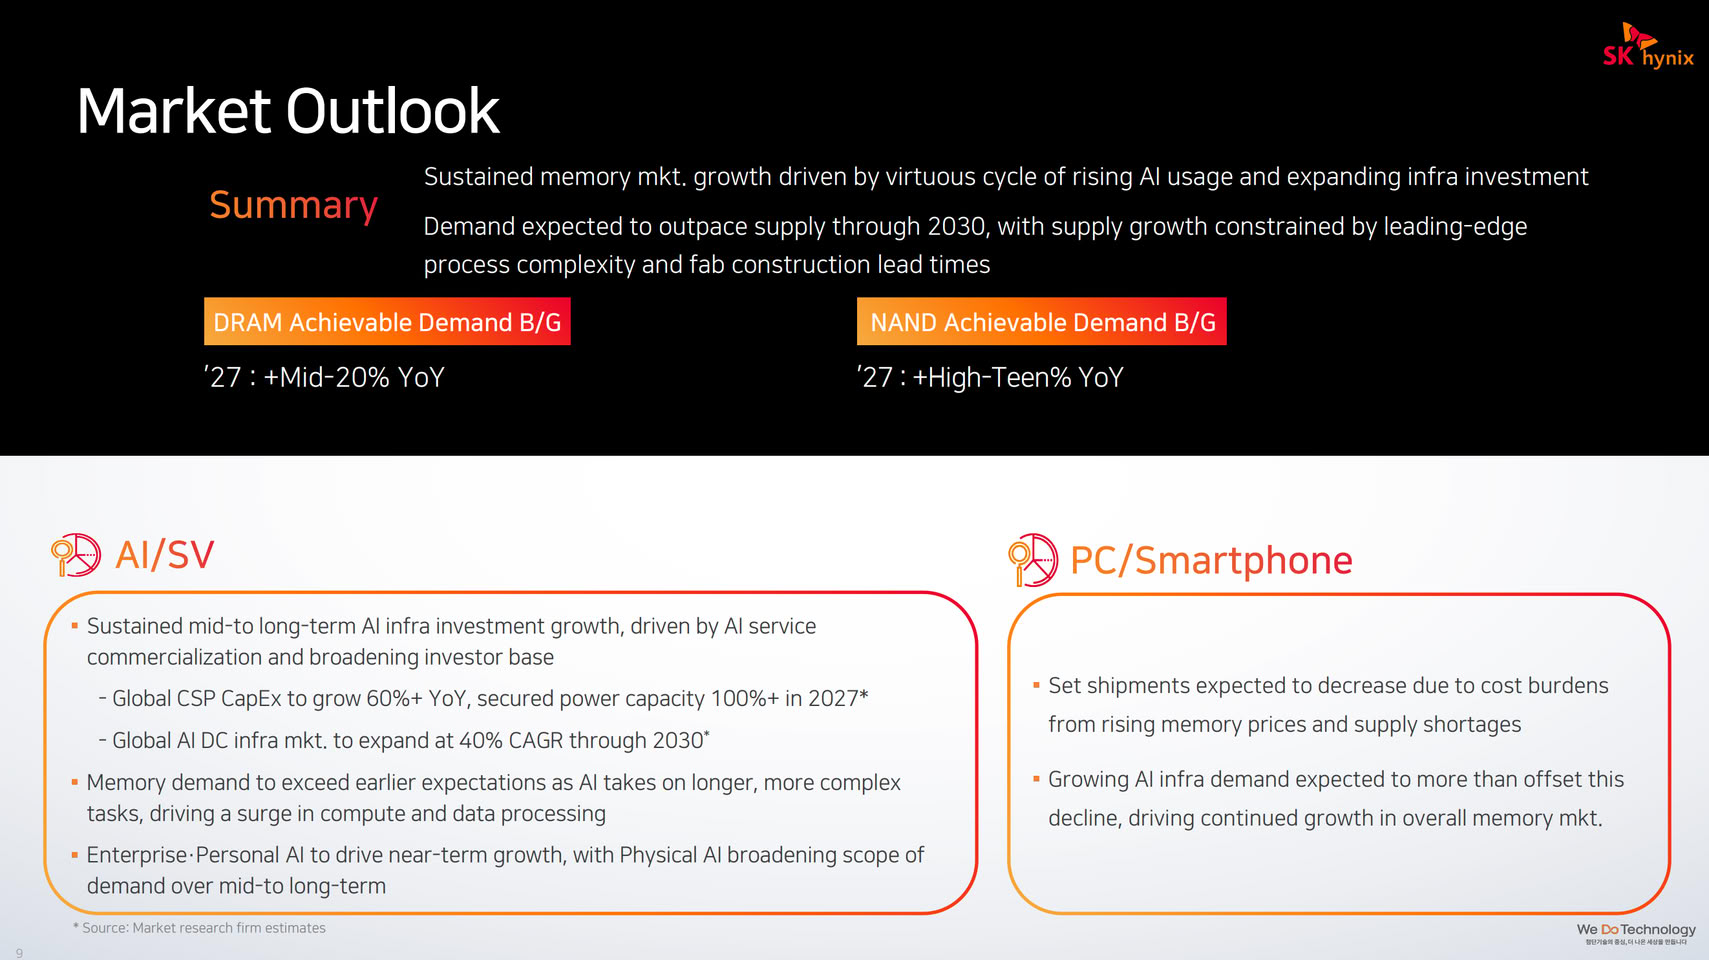
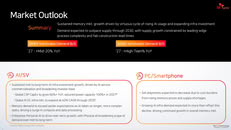
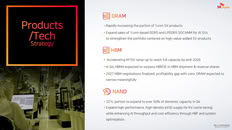
SK hynix reported its latest Q3 2026 quarterly results with a record $78.129 billion in net revenue. However, the company also shared a market outlook, highlighting its long-term supply agreements and plans for expansion with new fab capacity and facilities under construction. For the consumer market, the outlook is grim as SK hynix expects memory demand to continue outpacing supply through 2030. The main supply constraint is the complexity of leading-edge semiconductor nodes and the lengthy lead times for fab construction, which take years to translate into regular mass production volumes.

Despite sustained demand, pricing is also on an upward trajectory, with the average selling price of memory modules in Q3 increasing by over 20% compared to Q2. This is concerning, as it suggests that the prices of consumer electronics devices might jump by more than 20% once memory inventory is depleted. Although SK hynix expects a decrease in PC and smartphone shipments, this will be offset by a strong rollout of AI data centers. About 14 major customers, including most hyperscalers, have signed 5-year long-term agreements, which will account for over 50% of total capacity sold for 2027 and 2028.
Memory Makers Seal 2027 Deals: No Room for New Buyers

According to DigiTimes, industry insiders are now claiming that the entire memory production capacity for 2027 has been fully booked, well ahead of the schedule the industry expected. All of the big three memory makers—Samsung, SK hynix, and Micron—have sold out their memory capacity for the upcoming year, leaving no room for additional supply for third parties to purchase more DRAM wafers. Interestingly, the report notes that everyone from OEM server makers and PC makers to AI labs knows that July and August are crucial months for securing allocations for the following year. However, some businesses have been kept in the dark because nobody has been public about this out of fear of losing their allocation.

Memory makers have been pushing customers into long-term agreements with contracts ranging from three to five years, using an advance payment deposit model where customers essentially pre-pay for some of the memory capacity. These deals are made on an individual customer level. All of this combined signals that 2027 will be the worst year in recent history regarding memory shortages, meaning that only those who managed to sign agreements for supply will benefit, while the rest are left without as there simply isn't enough available DRAM. Only about 60-70% of the estimated demand can be met in 2027, leaving a significant amount of demand unmet and waiting for the 2028 supply.

NVIDIA's CPU Sales Could Make It One of the Biggest CPU Makers This Year

Earlier this year, we learned that NVIDIA began selling its "Vera" CPU generation as a standalone solution, offering hyperscalers and cloud providers a CPU ready for the agentic AI era. It appears that the "Vera" CPU generation could propel NVIDIA to become one of the largest CPU makers, just behind AMD and Intel in their own game. According to the company's own estimates, NVIDIA is projected to sell about $20 billion worth of "Vera" and "Grace" CPUs, unlocking a $200 billion Total Addressable Market (TAM) with its standalone offerings. As NVIDIA partners with every major hyperscaler to supply "Vera" CPU racks, we are starting to see many deployments across infrastructure providers for their own use cases and offering it to third-party customers. This approach allows NVIDIA to tap into a massive market, potentially propelling it to become one of the largest CPU makers.

For comparison, Intel's data center group DCAI generated about $5.1 billion in revenue in the first quarter of 2026, while AMD reported $5.8 billion in its Data Center Segment. These figures include a mix of accompanying products, such as AMD's Instinct MI GPU sales and networking solutions. With rough estimates and assumptions that both companies will report four times the revenue (assuming no growth, just for general comparison), this would yield $20 billion in sales in their respective data center divisions for the year. NVIDIA's "Grace" and "Vera" CPU are now projected to reach $20 billion on their own, positioning NVIDIA as one of the largest CPU makers this year and potentially on a path to become the largest CPU maker in the world.

SK Group Chairman Warns That Customers Will Use Less Memory Unless DRAM Supply Grows

Memory makers like Samsung, SK hynix, and Micron are currently striving to find the delicate balance between supplying the world with enough DRAM and expanding their production capacity by placing large new orders for the semiconductor fabs used to produce the memory. According to SK Group chairman Chey Tae-won, who also oversees SK hynix, if companies like SK hynix do not increase their memory supply, customers will find ways to use less memory by optimizing their infrastructure and software for much lower utilization. At present, hyperscalers and AI accelerator makers such as AMD, NVIDIA, and others are securing as much memory as possible. This is part of AI data center expansion, which requires more GPU and CPU DRAM to support large training runs and maintain massive model inference, now reaching tens of trillions of parameters and needing hundreds of gigabytes of system memory to host a single model for just a few users.

This demand has created a supply chain issue where memory makers are selling all of their available DRAM months in advance but are hesitant to significantly expand manufacturing capacity, despite recognizing the increase in demand years ago. Memory makers are the first to notice rising demand, and their reluctance to increase manufacturing capacity is contributing to the current memory shortage. However, they are also wary of expanding production capacity as it takes years to build new memory fabs, just as projected demand is expected to stabilize. SK hynix has ordered about 20 Low-NA EUV machines from ASML for their expansion plans, which will also support future storage production once the tools are operational. However, all of this added capacity is still years away, and we will remain in a tight situation for a little while longer.

Arm Reports Results for the Fourth Quarter and Fiscal Year Ended 2026

Today (May 6, 2026) Arm (NASDAQ: ARM) published a letter to its shareholders containing the company's results for its fourth quarter and fiscal year 2026 ended March 31, 2026. The infographic below provides the key highlights for the quarter:
  • Arm delivered record-breaking quarterly and full-year results, with Q4 FYE26 revenue reaching $1.49 billion and full-year revenue at $4.92 billion. FYE26 was Arm's third consecutive financial year since going public of more than 20% revenue growth.
  • Arm delivered record full-year royalty revenue of $2.61 billion alongside Q4 FYE26 revenue at $671 million, with this driven by growth across smartphones, Edge AI, Physical AI and Cloud AI, where data center royalties more than doubled year-over-year. Meanwhile, Arm's Q4 FYE26 revenue for licensing reached a record $819 million, with yearly revenue at $2.31 billion.

AMD to Expand EPYC Lineup With Specialized CPUs for AI, HPC, and Cloud

AMD's CPU offerings will soon expand into more categories, specializing in different tasks and use cases. During the latest Q1 earnings call, AMD CEO Dr. Lisa Su confirmed that customers are increasingly interested in specialized EPYC solutions and that future CPU generations will cater to different customer needs. This means that agentic AI will receive a dedicated EPYC CPU SKU, HPC workloads will have their own EPYC CPU SKU, AI training and inference will get a separate EPYC SKU, and cloud workloads will have a distinct SKU. This expansion of task-specialized CPU designs will go beyond the "Venice" CPU platform, which is expected to be released this year. At CES 2026, AMD confirmed that EPYC "Venice" will be a highly dense CPU package with up to 256 cores and 512 threads of "Zen 6c" cores, while the regular "Zen 6" configuration will have a maximum of 96 cores and 192 threads.

With this generation of EPYC CPUs based on the "Zen 6" core IP, AMD will promote "Venice" CPUs broadly, while the "Venice" CPU generation will be complemented by the "Verano" CPUs. These appear to use the same "Zen 6" microarchitecture but have optimizations specifically designed for AI infrastructure. Contrary to previous assumptions that "Verano" would be a "Zen 7" IP, it is now confirmed to be part of the 6th-generation EPYC CPU family. This indicates that AMD is starting its CPU customization for different workloads as early as this year. As the server CPU market is projected to reach $120 billion by the end of this decade, less than 3.5 years away in 2030, it makes sense to have different CPU SKUs for each task and capture a significant portion of that revenue. Server CPUs are also expected to grow at a 35% compound annual growth rate, which is impressive for a relatively mature market.

Qualcomm Reports Second Quarter Fiscal 2026 Results

Qualcomm Incorporated (NASDAQ: QCOM) today announced results for its fiscal second quarter ended March 29, 2026.

"We are pleased to deliver results in line with our guidance, reflecting solid execution as we navigate a challenging memory environment," said Cristiano Amon, President and CEO of Qualcomm Incorporated. "We are in a period of profound industry transformation—the rise of AI agents is reshaping our roadmap across every platform we develop. We are equally excited by our entry into the data center, where a leading hyperscaler custom silicon engagement is on track for initial shipments later this calendar year. We look forward to providing an update on our growth initiatives, including opportunities in Data Center and Physical AI, at our Investor Day on June 24."

Intel Turns Scrap Dies Into Usable CPUs as Demand Keeps Rising

We have been reporting on the intense demand in the CPU sector currently sweeping the industry. AMD and Intel have sold out their inventories, and lead times are now weeks long. However, Intel, which manufactures a large part of its CPU portfolio, has been handling the situation differently. According to Intel and confirmed by industry analyst Ben Bajarin, the company is repurposing some of the dies found on the very edge of the silicon wafer, which would have otherwise become silicon scrap, into products that customers are eager to buy. This approach allows even some SKUs, which may have been flawed due to various effects like silicon node yield, to find new life through repurposing. Intel's customers are so eager for CPUs that higher-end parts, which would typically be discarded, are now being sold as independent SKUs. No silicon is left behind.

For example, when Intel produces a Xeon 6 "Granite Rapids" CPU on the Intel 3 node, the CPU compute die can accommodate up to 44 cores per die, but some are disabled for yield and power reasons. When the yield fails, these compute dies are repurposed into SKUs with lower core counts, as it costs Intel money to manufacture the die, and wasting it would be a significant loss of resources. However, when the die doesn't achieve satisfactory yield on the Intel 3 production line, the company would usually discard it if it can't extract a reasonable number of working cores. Amidst one of the highest-ever recorded CPU shortages, Intel is doing the opposite. The company is using these defective or scrap dies and packaging them into lower-class SKUs to sell to its customers, as any CPU availability is crucial, and customers are eagerly purchasing them. Imagine a wafer edge, which is round, having only a few working P-Cores, and that being packaged into a CPU that a hyperscaler would integrate into their offering.

AMD Stock Hits Record High Above $300 as AI Optimism Fuels Rally

AMD's stock has been experiencing a significant rise over the past few months, with the company's share price reaching a record $303.46 at the time of writing and a market capitalization of nearly half a trillion USD, precisely $494.74 billion. Historically, AMD's stock has struggled to match the levels of NVIDIA and, to some extent, Intel. However, the company has seen a massive turnaround with the expansion of AI data centers. AMD has been performing well in the data center space with its EPYC processors and Instinct MI accelerators, and the stock price has followed this upward trajectory. This is AMD's best stock performance yet, supported by a strong current and upcoming product portfolio that has major investors confident in the company's operations, financials, and execution of plans.

AMD is on track to ship its EPYC "Venice" server CPUs with "Zen 6" architecture, the Instinct MI400 series of accelerators for AI training, inference, and HPC workloads, and Pensando "Vulcano" AI NICs, all housed within a rack-scale system called "Helios." Expected to match and exceed NVIDIA's "Vera Rubin" in some areas, AMD will be competitive in the world's largest industry today—AI data centers. However, the company is not resting on its laurels and has already prepared a 2027 update of this product portfolio for the next-generation AI rack. This execution has instilled confidence in AMD's investors, driving the stock price significantly higher.

NVIDIA Launches Vera CPU, Purpose-Built for Agentic AI

NVIDIA today launched the NVIDIA Vera CPU, the world's first processor purpose-built for the age of agentic AI and reinforcement learning—delivering results with twice the efficiency and 50% faster than traditional rack-scale CPUs. As reasoning and agentic AI advances, scale, performance and cost are increasingly driven by the infrastructure supporting the models that plan tasks, run tools, interact with data, run code and validate results.

The NVIDIA Vera CPU builds on the success of the NVIDIA Grace CPU, enabling organizations of all sizes and across industries to build AI factories that unlock agentic AI at scale. With the highest single-thread performance and bandwidth per core, Vera is a new class of CPU that delivers higher AI throughput, responsiveness and efficiency for large-scale AI services such as coding assistants, as well as consumer and enterprise agents.

Optical Scale-up Consortium Established to Create an Open Specification for AI Infrastructure

The Optical Compute Interconnect (OCI) Multi-Source Agreement (MSA) group today announced its formation, led by founding members AMD, Broadcom, Meta, Microsoft, NVIDIA and OpenAI. This industry consortium marks a pivotal shift toward a hyperscaler-driven open ecosystem to enable the development of a multi-vendor supply chain for optical scale-up interconnects. By aligning on an open specification, the OCI MSA members are promoting a robust optical ecosystem which will ensure that the future of AI interconnects is built with a flexible, multi-vendor foundation to meet the optical interconnect needs of modern AI infrastructure.

The Physics and Power Mandate
As large language models (LLMs) advance toward super intelligence, traditional copper-based connectivity is reaching limitations in physical reach which are impacting AI cluster scale-up domain architectures. OCI will enable migration from copper-based to optical-based scale-up architectures, alleviating copper interconnect bottlenecks.

Meta Unveils Four MTIA Chips Focused on High-Perfomance Inference

Meta has laid out an aggressive, inference-first roadmap for its in-house accelerators, announcing four Meta Training and Inference Accelerator (MTIA) generations developed with Broadcom and due to be integrated into its data centers over the next two years. The family spans MTIA 300, 400, 450, and 500, with early units already running ranking and recommendation workloads and later designs optimized for real-time model serving. Since Meta runs some of the largest social platforms on the web, developing a fast inference accelerator is required to make social media browsing and recommendation algorithms instant. Rather than pursuing raw peak arithmetic alone, Meta emphasizes memory throughput and inference efficiency. According to the specification table, HBM bandwidth and capacity rises substantially across the series while compute grows more linearly. This means that Meta's point is increasing on-package bandwidth and capacity which can cut latency and power costs for production inference.

The MTIA chips also include hardware support for attention primitives and mixture-of-experts layers, along with low-precision formats tailored to inference to reduce conversion overhead. Software compatibility was a stated priority. Meta says the stack runs natively on common frameworks, so existing production models can be deployed on both GPUs and MTIA without major rewrites, which should ease adoption. Multiple MTIA generations are built to share the same chassis, rack, and networking, allowing upgrades by swapping modules rather than refitting data center infrastructure. That modularity helps explain Meta's fast release cadence compared with the industry norm, considering that Meta's data centers span millions of chips. MTIA chips are already running at kilowatt power budgets and PetaFLOPS of compute, so MTIA accelerators are also competing with industry-leading solutions from NVIDIA, AMD, and other hyperscalers.

AMD CEO Lisa Su Says Server CPU Demand "Far Exceeded" Expectations, Supply Now Tightening

AMD is seeing server CPU demand it didn't fully anticipate, with CEO Lisa Su describing it as having "far exceeded" her expectations. Speaking at the Morgan Stanley Technology, Media & Telecom Conference earlier today, Su outlined how the landscape has shifted as agentic AI applications have taken off, pushing CPUs back into the spotlight alongside accelerators. The CPU-to-GPU ratio in AI compute workloads has evolved dramatically over the past few months, and top customers reportedly told Su that CPU demand sitting alongside AI was "under-forecasted." Supply is tightening as a result. The sudden spike in customer commitments left little time for the supply chain to adjust, though AMD says it's working closely with partners to ease existing bottlenecks and expects capacity to expand over the coming year. Su expressed confidence that AMD's product lineup is well positioned to address training, inference, and agentic workloads going forward. We've also seen this play out at the customer level, with hyperscalers like Meta signing CPU agreements with AMD and NVIDIA, a sign that compute is diversifying away from a pure GPU focus.

Back in late January, Intel disclosed it had to reallocate wafer capacity from its PC division to Xeon production after hyperscalers started ordering larger quantities than anticipated, triggering a temporary shortage. Then, in early February, both Intel and AMD warned customers in China about tightening supplies, with Intel Xeon delivery times stretching to as long as six months and prices up more than 10%. AMD's situation is somewhat less difficult, but lead times have still pushed out to eight to ten weeks for some orders. On the consumer side, AMD's next-gen Ryzen 'Olympic Ridge' desktop processors based on Zen 6 are rumored to have slipped to 2027, possibly another sign that AMD is prioritizing Zen 6 chiplets for EPYC server processors.

Linux Kernel 7.0 Speeds Up File Cache Memory Reclaim by Up to 75%

In the latest Linux kernel v7.0, freeing up system memory used for caching large files has received a noticeable performance boost. According to notes on the kernel mailing list, a new set of patches queued for the Linux 7.0 merge window showed reclaim speed improvements of up to 75% in testing. In one benchmark, developers allocated 10 GB of file-backed data in memory and then reclaimed 8 GB of it. On a 32-core Arm64 server, the reclaim process completed about 75% faster compared to the older Linux implementation, while on an x86 machine, the improvement was reported at over 50%.

Imagine your system running a large database or another memory-intensive workload. Instead of constantly reading from storage, the kernel can keep tens or even hundreds of gigabytes of frequently accessed file data in RAM for much faster access. When memory pressure builds and part of that cached data must be freed, the cleanup process now completes significantly faster. This is not going to be noticeable to consumers, but hyperscalers, HPC simulations, AI runs, and other workloads that involve heavy data processing will now see a significant performance boost. The improvement comes from work authored by Baolin Wang of Alibaba, who optimized how the kernel handles large blocks of cached file memory.

Report: AMD Breaks 40% Server Revenue Share for the First Time

It is official: AMD is now capturing 40% of the entire server CPU market revenue share, according to data from Mercury Research. In the final quarter of 2025, AMD EPYC server CPUs managed to capture 41.3% of the revenue in the server/data center market that hyperscalers are spending on. This is a 1.8% increase from Q3 2025 and an impressive 4.9% year-over-year growth in a multi-billion USD data center market. For unit share shipment, AMD now stands at 28.8%, meaning the company is actually selling more SKUs at a higher average selling price. Intel, on the other hand, now holds 71.2% of the unit share while capturing 58.7% of the revenue share, indicating that Intel Xeon processors are now selling for a lower ASP with more units needed to reach this revenue.

The situation in the desktop segment looks interesting as well, with AMD's revenue share in the desktop CPU market now at 42.6%, while the unit share is at 36.4%. Again, this means that AMD's Ryzen processors sell at a higher ASP, nearly capturing half of the desktop CPU revenue with a bit more than a third of the unit sales. This sector also grew 1.6% sequentially, while Ryzen CPUs won the hearts of 14.6% more gamers for a yearly revenue share increase.

Samsung Ships Industry-First Commercial HBM4 With Ultimate Performance for AI Computing

Samsung Electronics Co., Ltd., a global leader in advanced memory technology, today announced that it has begun mass production of its industry-leading HBM4 and has shipped commercial products to customers. This achievement marks a first in the industry, securing an early leadership position in the HBM4 market. By proactively leveraging its most advanced 6th-generation 10 nanometer (nm)-class DRAM process (1c), the company achieved stable yields and industry-leading performance from the outset of mass production—all accomplished seamlessly and without any additional redesigns.

"Instead of taking the conventional path of utilizing existing proven designs, Samsung took the leap and adopted the most advanced nodes like the 1c DRAM and 4 nm logic process for HBM4," said Sang Joon Hwang, Executive Vice President and Head of Memory Development at Samsung Electronics. "By leveraging our process competitiveness and design optimization, we are able to secure substantial performance headroom, enabling us to satisfy our customers' escalating demands for higher performance, when they need them."

Cisco Unveils Silicon One G300 102.4 Tbps Switching ASIC

Cisco (NASDAQ: CSCO) continues to transform the network into an AI innovation platform, today unveiling the Silicon One G300, a 102.4 Tbps switching silicon designed for massive AI cluster buildouts. The Cisco Silicon One G300 will power new Cisco N9000 and Cisco 8000 systems that push the frontier of AI networking in the data center. The systems feature innovative liquid cooling and support high-density optics to achieve new efficiency benchmarks and ensure customers get the most out of their GPU investments. In addition, the company enhanced Nexus One to make it easier for enterprises to operate their AI networks—on-premises or in the cloud—removing the complexity that can hold organizations back from scaling AI data centers.

"We are spearheading performance, manageability, and security in AI networking by innovating across the full stack - from silicon to systems and software," said Jeetu Patel, President and Chief Product Officer, Cisco. "We're building the foundation for the future of infrastructure, supporting every type of customer—from hyperscalers to enterprises—as they shift to AI-powered workloads."

Intel Kills Pay-to-Use "Software Defined Silicon" Initiative

Intel has quietly deprecated its Software Defined Silicon initiative (SDSi), known as "Intel On Demand," according to a report from Phoronix. The company has archived the official GitHub repository for SDSi for Xeon, an effort intended to enable optional features on Intel's server processors that could be unlocked for an extra fee. Intel had hoped enterprises would pay to enable these features, but the initiative never gained mass traction and was only sporadically maintained. Because hyperscalers operate at massive scale, paying an additional fee to enable a feature on silicon they had already purchased made little sense, contributing to Intel's decision to abandon the project. Subscription services are similar in concept, but they generally apply to software on a monthly basis rather than one-time hardware activations.

Originally, Intel planned to make Quick Assist, Dynamic Load Balancer, and Data Streaming Accelerator available as On Demand features, alongside Software Guard Extensions and the In-Memory Analytics Accelerator. These were described on the Intel On Demand website as a "one-time activation of select CPU accelerators and security features." The Intel On Demand site has since been reworked to remove most information, leaving only a few documents and paragraphs. Thankfully, the idea of putting hardware features behind a paywall has not gained traction for now, leaving the paywall model to traditional software. At one point enthusiasts wondered whether Intel On Demand would trickle down to consumer CPUs, but with the project apparently dead, that possibility seems unlikely in the near term. Intel Upgrade Service existed in a similar format back in early 2010s, but was also short-lived.

Arm Delivers Fourth Consecutive Billion-Dollar Revenue Quarter

Today (Feb. 4, 2026) Arm (NASDAQ: ARM) published a letter to its shareholders containing the company's results for the third quarter of fiscal year 2026 ended December 31, 2025. The infographic below provides the key highlights:

Here are what the results mean and how they were achieved:
  • Revenue grew 26% year-on-year to $1.24 billion, representing Arm's fourth consecutive billion-dollar revenue quarter.
  • Royalty revenue grew 27% year-over-year to a record $737 million, driven by growth across Arm's target end markets, including AI and general-purpose data center, smartphones, physical AI and edge AI.
  • License and other revenue of $505 million increased 25% year-over-year, as more leading companies sign high-value licenses for next-generation Arm technologies.
  • Demand for Arm Compute Subsystems (CSS) continues to exceed expectations as adoption grows in light of increasingly complex chip designs. This represents a significant tailwind to royalty growth, as Arm expands both the value delivered and economics captured per chip.
    • During the quarter, Arm signed two CSS licenses for use in both edge AI tablets and smartphones, bringing the total number of CSS licenses to 21 across 12 companies.
    • Additionally, five customers are now shipping Arm CSS-based chips, including two shipping its second-generation platform, while the top four Android smartphone vendors are all shipping Arm CSS-powered devices.

Microsoft Introduces Its Newest AI Accelerator: Maia 200

Today, we're proud to introduce Maia 200, a breakthrough inference accelerator engineered to dramatically improve the economics of AI token generation. Maia 200 is an AI inference powerhouse: an accelerator built on TSMC's 3 nm process with native FP8/FP4 tensor cores, a redesigned memory system with 216 GB HBM3e at 7 TB/s and 272 MB of on-chip SRAM, plus data movement engines that keep massive models fed, fast and highly utilized. This makes Maia 200 the most performant, first-party silicon from any hyperscaler, with three times the FP4 performance of the third generation Amazon Trainium, and FP8 performance above Google's seventh generation TPU. Maia 200 is also the most efficient inference system Microsoft has ever deployed, with 30% better performance per dollar than the latest generation hardware in our fleet today.

Maia 200 is part of our heterogenous AI infrastructure and will serve multiple models, including the latest GPT-5.2 models from OpenAI, bringing performance per dollar advantage to Microsoft Foundry and Microsoft 365 Copilot. The Microsoft Superintelligence team will use Maia 200 for synthetic data generation and reinforcement learning to improve next-generation in-house models. For synthetic data pipeline use cases, Maia 200's unique design helps accelerate the rate at which high-quality, domain-specific data can be generated and filtered, feeding downstream training with fresher, more targeted signals.

Intel Reallocates PC Production Capacity to Server CPUs Amid Tight Wafer Supply

Yesterday, after the equity market closed, Intel announced its Q4 and full-year 2025 earnings, along with weaker-than-expected guidance for Q1 2026. As a result, Intel's stock is anticipated to open 11% lower today. During the Q4 earnings call, Intel's CFO, David Zinsner, explained the reasons behind the reduced outlook, despite the increasing demand for Intel products. The situation arose due to hyperscalers demanding more units. Intel's discussions with these customers indicated a preference for high core count solutions rather than increased unit shipments. Consequently, Intel adjusted its inventory and internal wafer supply to maintain reasonable stock levels while consistently shipping new units. However, hyperscalers have since been ordering larger quantities, leading to a temporary shortage of Xeon processors for the Data Center and AI (DCAI) group. To address this, Intel plans to redirect some resources from the Client Computing Group (CCG) to support Xeon CPU production.
Intel CFO David ZinsnerBoth (DCAI and CCG) will be down as a function of supply. Obviously, we're shifting as much as we can over to data center to meet the high demand, but we can't completely vacate the client market. So we're trying to support both as best we can and obviously work our way out of this supply issue. I do believe that the first quarter is the trough. We will improve supply in the second quarter. Part of the challenge is that in the third and fourth quarter of 2025, we lived off of supply, but we also had a reasonable chunk of finished goods inventory to also work through. Unfortunately, that is now down to kind of 40% of what it was at peak levels.

Corvex Secures Long-Term NVIDIA H200 GPU Deployment

Corvex, Inc., an AI cloud computing company specializing in GPU-accelerated infrastructure for AI workloads, today announced a long-term GPU lease agreement with an established AI-driven provider of high-performance battery technologies. The deployment, a dedicated cluster of NVIDIA H200 GPUs, will underpin the customer's core AI development and research initiatives, including proprietary algorithms. The customer selected Corvex for its superior overall value, confidential AI enablement to unlock market expansion, and hyperscaler-class operations as compared to alternative AI cloud infrastructure providers.

Corvex's architecture of GPU clusters will provide the customer with high price-performance by maximizing compute density while maintaining elasticity and allowing flexibility for burst capacity during peak demand periods. Corvex is also enabling the customer to extend its enterprise AI offerings into the most security-conscious environments through a secure, managed on-premise solution. By architecting next-generation on-premise GPU clusters with hardware-enforced encryption, remote attestation, and payload-free telemetry, Corvex's technology allows the customer to run sensitive model training and production inference workloads while meeting strict data-sovereignty, compliance, and IP-protection requirements, and to expand its market to enterprise customers that cannot be served by public cloud infrastructure.

First Shipments of NVIDIA "Vera Rubin" AI Servers Expected Around Late Summer

Last week, Quanta Computer's Mike Yang let slip details about the eventual arrival of NVIDIA "Vera Rubin" AI server hardware. The executive vice president/general manager mentioned potential first shipments—heading in the direction of hyperscalers—occurring by August of this year. According to Taiwan's Commercial Times, this prediction was disclosed during an official celebratory company event (on January 15). Additionally, the Quanta boss does not expect a widespread deployment at that point in time, and (consequently) significant revenue generated by sales of new "Vera Rubin" equipment. According to the exec's statements, "most" customers are already running operations based on current-gen "Grace Blackwell" GB200 and GB300, but Yang believes that common architectural traits will make transitions—onto the next-gen platform—much easier than before.

Industry observers have highlighted possible issues of moving from the "Grace Blackwell" chiplet-based design to the advanced packaging of "Vera Rubin." During CES, NVIDIA announced that full production of server-grade "Vera" CPUs and "Rubin" GPUs had kicked off. This Q1 2026 initiation has happened well ahead of a previous "by H2 2026" mass manufacturing goal. Team Green's forthcoming "Vera Rubin" NVL72 SuperCluster is classed as a premier rack-scale system. A larger "NVL144" variant was previewed last year, but this CPX platform seems to be further out from release. According to a mid-October report, an involved manufacturing partner was weighing up a loose "2026 volume production" window.

4 TB RDIMM DDR5 Memory Kit Arrives at Eye-Watering $70,000+ Price Tag

If you're in the market for a high-capacity DDR5 memory kit featuring ECC RDIMMs, this might be your lucky opportunity. NEMIX, a U.S.-based memory and storage supplier that collaborates with major tech firms and the government, has listed a 4 TB DDR5 memory kit. This kit consists of 16x 256 GB ECC RDIMMs operating at 6400 MT with a CAS latency of 52. Notably, the listing comes with a hefty price tag of $70,800, making it accessible only to high-budget hyperscalers or workstation enthusiasts. The 4 TB kit's substantial cost is striking, especially during a time of significant DRAM shortages. This translates to approximately $17.3 per GB, significantly higher than the average $10 per GB for consumer DRAM.

The nearly doubled price of these modules is justified by the advanced technology incorporated into these RDIMMs. They feature off-die error correction chips for ECC, which are not standard in regular DDR5 DIMMs. While DDR5 includes on-die ECC, it does not provide complete error correction on its own. Therefore, additional silicon is necessary for hyperscalers and workstations to achieve full error correction, which is reflected in the price premium. The 4Rx4 rank setup helps maintain smooth performance, and it operates at just 1.1 V, making it quite efficient. With registered buffering and built-in ECC, these modules show why their price point is much higher than traditional DIMMs.

NVIDIA Powers Nearly 72% of Cloud Accelerator Locations, AMD at 5.8%

The cloud accelerator market share study was conducted at UBS bank, one of the leading research hubs and close followers of market trends. According to UBS, NVIDIA commands 71.2% of the cloud accelerator location share, which includes GPUs and other types of ASICs. The study also included AMD, and other ASICs. For the AMD front, the situation is entirely different as the data shows AMD only captures 5.8% of the cloud accelerator location share. The remaining portion is split between ASICs designed by the likes of AWS, Meta, Broadcom, MediaTek, and many others, which command 22.3%.

For NVIDIA, the company has managed to penetrate its GPUs in 258 datacenter locations, serving as cloud GPU providers. This is a significant number considering that some of these customers are ordering tens and even hundreds of thousands of GPUs at once, especially as the demand expands. NVIDIA is still the backbone of the entire AI infrastructure, and even its older GPUs, which include A100 and H100, are capturing a significant part of the GPU cloud market share. As "Blackwell" SKUs, designed for a million GPU scale systems, are scaled, and we enter the "Rubin" era, NVIDIA's lead may only expand.
Return to Keyword Browsing
Nov 11th, 2026 03:59 CST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts