Monday, January 26th 2026

Microsoft Introduces Its Newest AI Accelerator: Maia 200
Today, we're proud to introduce Maia 200, a breakthrough inference accelerator engineered to dramatically improve the economics of AI token generation. Maia 200 is an AI inference powerhouse: an accelerator built on TSMC's 3 nm process with native FP8/FP4 tensor cores, a redesigned memory system with 216 GB HBM3e at 7 TB/s and 272 MB of on-chip SRAM, plus data movement engines that keep massive models fed, fast and highly utilized. This makes Maia 200 the most performant, first-party silicon from any hyperscaler, with three times the FP4 performance of the third generation Amazon Trainium, and FP8 performance above Google's seventh generation TPU. Maia 200 is also the most efficient inference system Microsoft has ever deployed, with 30% better performance per dollar than the latest generation hardware in our fleet today.
Maia 200 is part of our heterogenous AI infrastructure and will serve multiple models, including the latest GPT-5.2 models from OpenAI, bringing performance per dollar advantage to Microsoft Foundry and Microsoft 365 Copilot. The Microsoft Superintelligence team will use Maia 200 for synthetic data generation and reinforcement learning to improve next-generation in-house models. For synthetic data pipeline use cases, Maia 200's unique design helps accelerate the rate at which high-quality, domain-specific data can be generated and filtered, feeding downstream training with fresher, more targeted signals.
 Maia 200 is deployed in our US Central datacenter region near Des Moines, Iowa, with the US West 3 datacenter region near Phoenix, Arizona, coming next and future regions to follow. Maia 200 integrates seamlessly with Azure, and we are previewing the Maia SDK with a complete set of tools to build and optimize models for Maia 200. It includes a full set of capabilities, including PyTorch integration, a Triton compiler and optimized kernel library, and access to Maia's low-level programming language. This gives developers fine-grained control when needed while enabling easy model porting across heterogeneous hardware accelerators.
Engineered for AI inference
Fabricated on TSMC's cutting-edge 3-nanometer process, each Maia 200 chip contains over 140 billion transistors and is tailored for large-scale AI workloads while also delivering efficient performance per dollar. On both fronts, Maia 200 is built to excel. It is designed for the latest models using low-precision compute, with each Maia 200 chip delivering over 10 petaFLOPS in 4-bit precision (FP4) and over 5 petaFLOPS of 8-bit (FP8) performance, all within a 750 W SoC TDP envelope. In practical terms, Maia 200 can effortlessly run today's largest models, with plenty of headroom for even bigger models in the future.
Crucially, FLOPS aren't the only ingredient for faster AI. Feeding data is equally important. Maia 200 attacks this bottleneck with a redesigned memory subsystem. The Maia 200 memory subsystem is centered on narrow-precision data-types, a specialized DMA engine, on-die SRAM and a specialized NoC fabric for high-bandwidth data movement, increasing token throughput.
Optimized AI systems
At the systems level, Maia 200 introduces a novel, two-tier scale-up network design built on standard Ethernet. A custom transport layer and tightly integrated NIC unlocks performance, strong reliability and significant cost advantages without relying on proprietary fabrics.
Each accelerator exposes:
Within each tray, four Maia accelerators are fully connected with direct, non-switched links, keeping high-bandwidth communication local for optimal inference efficiency. The same communication protocols are used for intra-rack and inter-rack networking using the Maia AI transport protocol, enabling seamless scaling across nodes, racks and clusters of accelerators with minimal network hops. This unified fabric simplifies programming, improves workload flexibility and reduces stranded capacity while maintaining consistent performance and cost efficiency at cloud scale.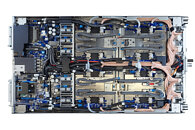
 A cloud-native development approach
A core principle of Microsoft's silicon development programs is to validate as much of the end-to-end system as possible ahead of final silicon availability.
A sophisticated pre-silicon environment guided the Maia 200 architecture from its earliest stages, modeling the computation and communication patterns of LLMs with high fidelity. This early co-development environment enabled us to optimize silicon, networking and system software as a unified whole, long before first silicon.
We also designed Maia 200 for fast, seamless availability in the datacenter from the beginning, building out early validation of some of the most complex system elements, including the backend network and our second-generation, closed loop, liquid cooling Heat Exchanger Unit. Native integration with the Azure control plane delivers security, telemetry, diagnostics and management capabilities at both the chip and rack levels, maximizing reliability and uptime for production-critical AI workloads.
As a result of these investments, AI models were running on Maia 200 silicon within days of first packaged part arrival. Time from first silicon to first datacenter rack deployment was reduced to less than half that of comparable AI infrastructure programs. And this end-to-end approach, from chip to software to datacenter, translates directly into higher utilization, faster time to production and sustained improvements in performance per dollar and per watt at cloud scale.
Source:
Microsoft Blog
Maia 200 is part of our heterogenous AI infrastructure and will serve multiple models, including the latest GPT-5.2 models from OpenAI, bringing performance per dollar advantage to Microsoft Foundry and Microsoft 365 Copilot. The Microsoft Superintelligence team will use Maia 200 for synthetic data generation and reinforcement learning to improve next-generation in-house models. For synthetic data pipeline use cases, Maia 200's unique design helps accelerate the rate at which high-quality, domain-specific data can be generated and filtered, feeding downstream training with fresher, more targeted signals.


Engineered for AI inference
Fabricated on TSMC's cutting-edge 3-nanometer process, each Maia 200 chip contains over 140 billion transistors and is tailored for large-scale AI workloads while also delivering efficient performance per dollar. On both fronts, Maia 200 is built to excel. It is designed for the latest models using low-precision compute, with each Maia 200 chip delivering over 10 petaFLOPS in 4-bit precision (FP4) and over 5 petaFLOPS of 8-bit (FP8) performance, all within a 750 W SoC TDP envelope. In practical terms, Maia 200 can effortlessly run today's largest models, with plenty of headroom for even bigger models in the future.
Crucially, FLOPS aren't the only ingredient for faster AI. Feeding data is equally important. Maia 200 attacks this bottleneck with a redesigned memory subsystem. The Maia 200 memory subsystem is centered on narrow-precision data-types, a specialized DMA engine, on-die SRAM and a specialized NoC fabric for high-bandwidth data movement, increasing token throughput.
Optimized AI systems
At the systems level, Maia 200 introduces a novel, two-tier scale-up network design built on standard Ethernet. A custom transport layer and tightly integrated NIC unlocks performance, strong reliability and significant cost advantages without relying on proprietary fabrics.
Each accelerator exposes:
- 2.8 TB/s of bidirectional, dedicated scale-up bandwidth
- Predictable, high-performance collective operations across clusters of up to 6,144 accelerators
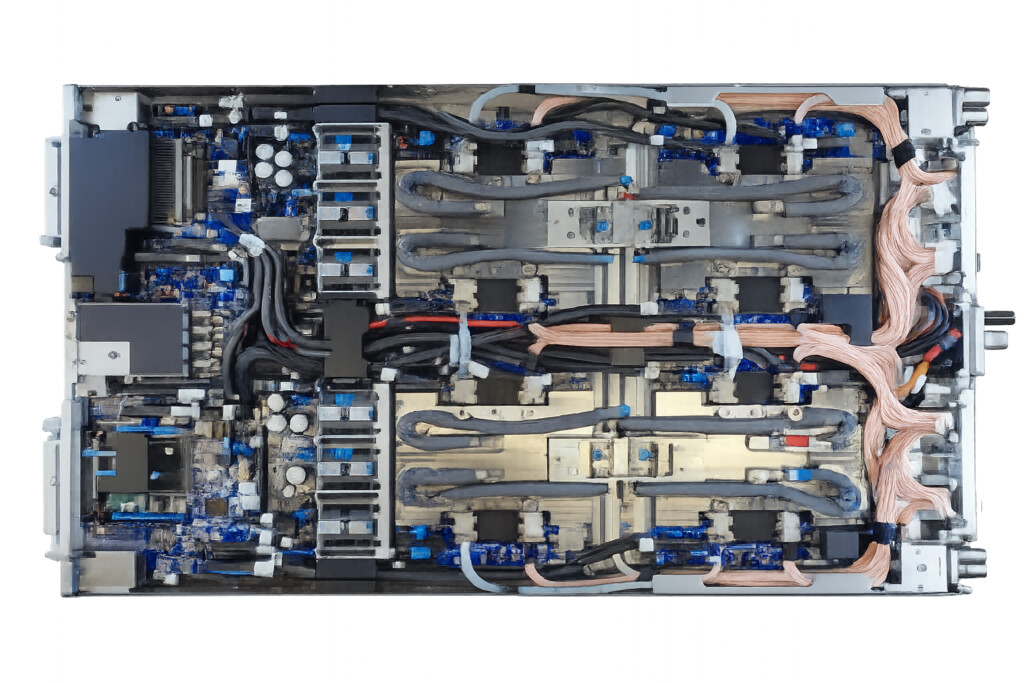
Within each tray, four Maia accelerators are fully connected with direct, non-switched links, keeping high-bandwidth communication local for optimal inference efficiency. The same communication protocols are used for intra-rack and inter-rack networking using the Maia AI transport protocol, enabling seamless scaling across nodes, racks and clusters of accelerators with minimal network hops. This unified fabric simplifies programming, improves workload flexibility and reduces stranded capacity while maintaining consistent performance and cost efficiency at cloud scale.

A core principle of Microsoft's silicon development programs is to validate as much of the end-to-end system as possible ahead of final silicon availability.
A sophisticated pre-silicon environment guided the Maia 200 architecture from its earliest stages, modeling the computation and communication patterns of LLMs with high fidelity. This early co-development environment enabled us to optimize silicon, networking and system software as a unified whole, long before first silicon.
We also designed Maia 200 for fast, seamless availability in the datacenter from the beginning, building out early validation of some of the most complex system elements, including the backend network and our second-generation, closed loop, liquid cooling Heat Exchanger Unit. Native integration with the Azure control plane delivers security, telemetry, diagnostics and management capabilities at both the chip and rack levels, maximizing reliability and uptime for production-critical AI workloads.
As a result of these investments, AI models were running on Maia 200 silicon within days of first packaged part arrival. Time from first silicon to first datacenter rack deployment was reduced to less than half that of comparable AI infrastructure programs. And this end-to-end approach, from chip to software to datacenter, translates directly into higher utilization, faster time to production and sustained improvements in performance per dollar and per watt at cloud scale.
12 Comments on Microsoft Introduces Its Newest AI Accelerator: Maia 200
I'm sure there will be no problem incorporating hallucinatory outputs into the training for new AI. It's not like the Studio Ghibli piss filter irrevocably destroyed ChatGPT's image generation after just a few days.
It doesn't matter if both come from the same company as fewer total chips will be needed to get the job done.
Maybe focus on increasing FP64 once again, which can be used for a wider range of workloads.