News Posts matching #RISC-V

Return to Keyword Browsing

Espressif Debuts ESP-Mosaico Modular Development Platform

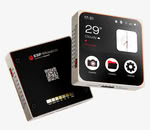
Espressif Systems (688018.SH) today announced ESP-Mosaico, a modular development platform designed for AI-assisted hardware creation. ESP-Mosaico allows creators to combine functional modules and multiple devices while enabling Coding Agents to understand the current hardware configuration and participate directly in application development.

ESP-Mosaico supports two complementary development approaches. Chat Coding lets creators start from a natural-language request and quickly build working hardware prototypes without setting up a local development environment. Vibe Coding brings AI Agents deeper into the engineering workflow, including implementation, deployment, testing on physical hardware, and continuous iteration.
Axelera Launches Europa AI Processing Unit (AIPU) With Up to 629 TOPS

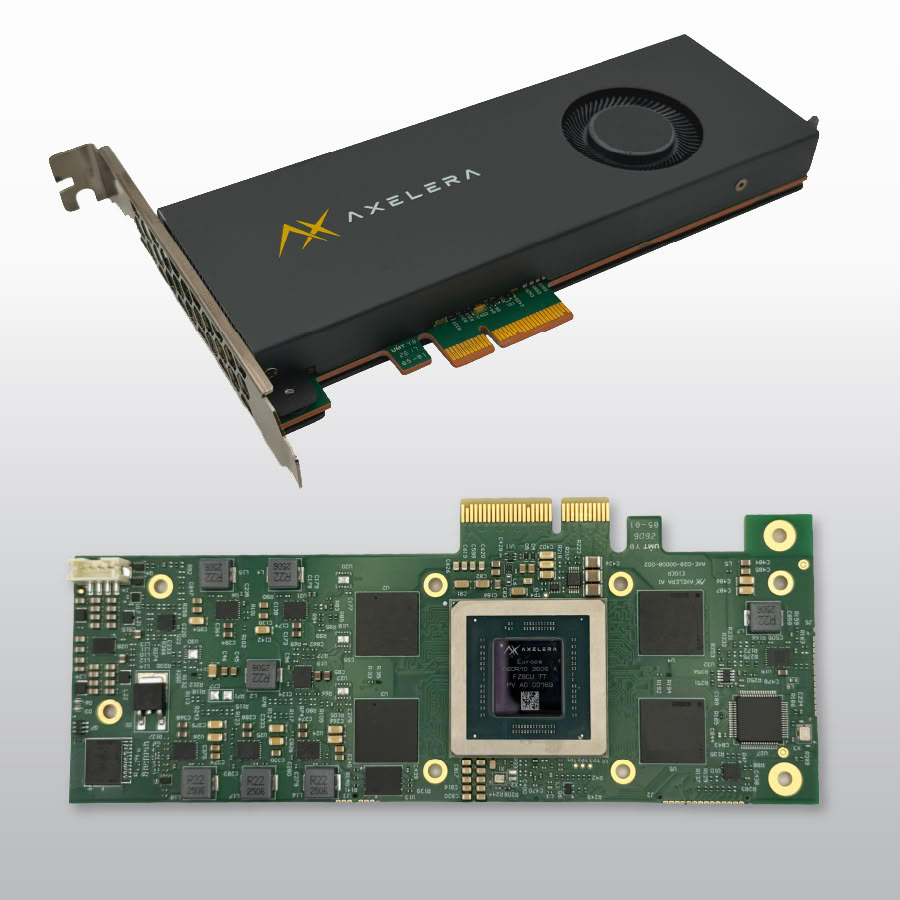
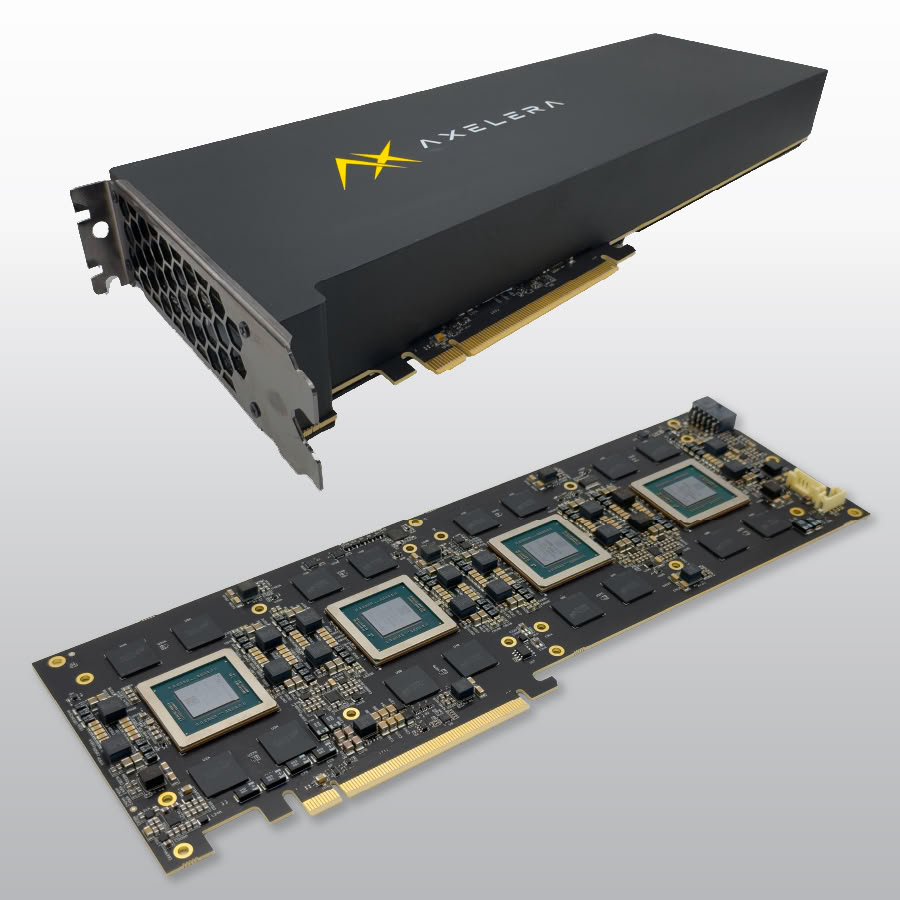
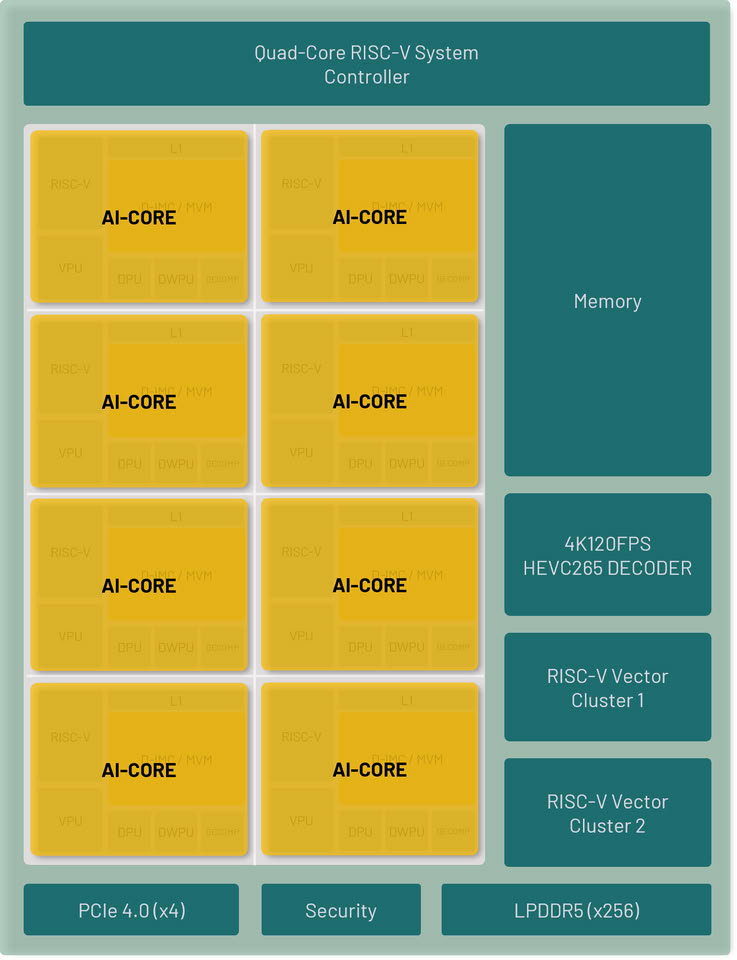
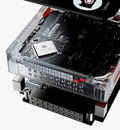
Axelera AI has formally launched Europa, its new AI Processing Unit architecture first announced back in October last year. The chip is now available in three form factors: as a chip for custom board designs, a half-height, half-length PCIe card (Edge 232p), and a full-height full-length PCIe card (Server 250p). The Europa AIPU has eight second-generation AI processing cores, 16 RISC-V vector processing cores, 128 MB of L2 SRAM, 200 GB/s DRAM bandwidth, PCIe 4.0 x4 interface and an onboard video decoder. The chip can reach 629 TOPS at a 45 W TDP, with INT4, INT8, and INT16 precision support. The Europa architecture targets inference workloads including agentic systems, vision-language models, generative AI, and computer vision and is the direct successor of Axelera Metis.

The Edge 232p is a single-chip HHHL card with up to 629 TOPS, reaching 83.4 tokens per second on Qwen 30B. It's available in validated configurations inside a Dell XE5 and a Supermicro 111AD. The Server 250p steps up to four Europa AIPUs for over 2,500 TOPS combined, delivering up to 4,205 tokens per second on Qwen3 8B at up to 32.1 tokens per second per watt. In a press release, Axelera says it has a sales pipeline that exceeds $1.5 billion and more than 600 customers across the globe. The company is now working on its first chiplet, the Titania, targeting rack-mount servers and supercomputers.

Qualcomm Introduces Dragonwing Q-2390 and IQ-2390 Processors for Consumer IoT and Industrial Edge

Ahead of IFA, Qualcomm Technologies, Inc. today announced the Qualcomm Dragonwing Q-2390 and IQ-2390 processors, expanding the Dragonwing portfolio with highly integrated platforms designed to make intelligent edge computing more accessible to consumer, commercial and industrial segments. As demand grows for devices that can perceive, analyze and act on data locally, the Dragonwing Q-2390 and IQ-2390 processors are designed to bring AI, vision, connectivity and security to a broader range of connected devices, helping power the next wave of intelligence across homes, businesses, cities and factories.

"AI is creating a fundamental shift in how connected devices are designed and deployed, but many product categories still face barriers around cost, complexity and integration," said Jeff Arnold, VP & GM, Auto Telematics & Industrial & Embedded IoT Consumer and Connectivity, Qualcomm Technologies, Inc. "With the Dragonwing Q-2390 and IQ-2390 processors, we're enabling intelligence to scale across a much broader range of devices, from retail systems, smart appliances and consumer robots to industrial controllers, machine vision systems and critical infrastructure. Together, these platforms help bring advanced edge AI within reach of more customers and more industries than ever before."

XCENA Details MX1 Architecture Integrating Memory Expansion and Near-Memory Computing at Hot Chips 2026

XCENA, a semiconductor company developing memory-centric computing solutions for AI infrastructure, today presented the architecture and measured performance of MX1, its computational CXL memory architecture, during the Hot Chips 2026 Memory session. Presented by Harry Kim, Chief Product Officer of XCENA, the session examined how MX1 combines large-scale memory expansion, SSD-backed capacity and programmable near-memory computing in a single CXL Type 3 device to address the growing memory constraints of AI infrastructure. The MX1 presentation was selected through the Hot Chips program committee's technical review process.

As AI models continue to grow, system performance is increasingly constrained by memory capacity, data movement and the economics of high-bandwidth memory scaling rather than compute alone. MX1 is designed to complement CPUs, GPUs and AI accelerators by expanding memory capacity and offloading selected memory-bound operations—including vector search, KV-cache retrieval and data preprocessing—so host processors can focus on compute-intensive inference.

XCENA Unveils MX1 Production Lineup to Accelerate Push Into Hyperscale AI Infrastructure

XCENA, providing memory-centric computing solutions for AI infrastructure, today introduced MX1, its production memory lineup built to break through the capacity, utilization and data-movement now limiting AI inference at scale. The company is showcasing MX1 at FMS 2026: The Future of Memory and Storage, being held Aug. 4-6 at the Santa Clara Convention Center.

As generative AI drives larger models, longer context windows and rapidly growing KV cache footprints, memory is emerging as the defining constraint on AI infrastructure. High-bandwidth memory remains costly and capacity-limited, and scaling out with additional servers creates stranded DRAM and rising total cost of ownership. XCENA developed the CXL-based MX1 lineup to give operators a different path - scaling memory as efficiently as they scale compute. Together with Intel Xeon 6 platforms, MX1 solutions showcase how CXL-based memory can help address memory-intensive AI workloads.

Intel's "Atom" CPU Technology Finds New Home at RosaicLabs

According to Reuters, Intel has shared access to its renowned "Atom" CPUs with a startup called RosaicLabs Inc. This means Intel will be transferring some of its in-house intellectual property to a third party, a rare occurrence in the semiconductor industry. Specifically, the register-transfer level (RTL) code that defines each CPU part, which is later turned into the actual silicon, will be licensed to Rosaic. Intel's Atom CPU line runs on the x86-64 instruction set. Historically, Intel has used these Atom CPUs for entry-level and low-power tasks, including networking equipment. However, the Atom CPU portfolio is now much smaller than it used to be as Intel transitions to other areas. Before developing E-Cores, Intel designed one last "Tremont" microarchitecture, which ended up in "Elkhart Lake" and "Jasper Lake" silicon for embedded, low-power laptops, and Chromebooks.

Intel has since transitioned to E-Cores, which are effectively successors to Atom cores, and these cores are also built on a separate microarchitecture like "Gracemont." While it's not exactly clear which Atom CPU core IP will be shared with Rosaic, the company could be receiving the "Tremont" CPU generation or something newer to start its x86 silicon manufacturing. Additionally, Rosaic is currently looking to raise about $10 million, which would support its unknown chip ambitions, potentially based on low-power x86 design. We have yet to see any teasers or detailed product announcements.

NextSilicon to Productize Arbel RISC-V Core Into 64-Core Enterprise Processor for AI and HPC

NextSilicon, a leader in next-generation computing solutions for AI and high-performance computing (HPC), today announced plans to productize its Arbel RISC-V core into a 64-core and a 128-core, enterprise-grade processor suited to deliver ultra-speed performance for agentic tools, expected to be available in early 2028. Following an October preview, the company is now sharing expanded technical detail and a roadmap shaped by early customer and partner feedback. This announcement coincides with NextSilicon's presentation at the RISC-V Summit.

NextSilicon designed Arbel from the ground up for the performance demands of AI infrastructure and HPC. The move from test chip to production roadmap follows customer and partner silicon evaluations, including HPC program leads, AI infrastructure architects, and data center operators. Their input has validated Arbel's key performance attributes and is shaping the requirements and architecture decisions for the 64-core production processor.

DeepComputing Launches DC-ROMA RISC-V Mainboard III for Framework Laptop 13

DeepComputing today announced the official launch of the DC-ROMA RISC-V Mainboard III for the Framework Laptop 13, marking a major milestone in bringing practical, high-performance RISC-V computing into a modular laptop form factor. Starting at $699, the new mainboard represents a significant step toward making RISC-V a developer-ready, everyday computing platform—combining open architecture, modern performance, and seamless integration with the Framework ecosystem.

Built on the RISC-V architecture and designed for full compatibility with the Framework Laptop 13, the DC-ROMA RISC-V Mainboard III is powered by the SpacemiT K3 RISC-V AI SoC—the world's first RISC-V SoC to support the RVA23 profile. This standardization milestone helps provide a more consistent software target for developers, accelerating ecosystem maturity.

SiFive Launches RISC-V Performance P550 and P570 Gen 3 IP

SiFive, Inc., the gold standard for RISC-V computing, today announced the launch of the SiFive Performance P570 Gen 3, the most powerful and efficient out-of-order processor core in its class. Purpose-built for demanding edge AI, high-end consumer, and commercial IoT applications, the P570 Gen 3 delivers a large leap in performance compared to the popular P550 Gen 1, and also provides the most modern RVA23 ISA profile support.

This versatile IP can be used as the control processor in embedded IoT devices, running a full networking stack, or can be used as the main applications processor in consumer devices, running rich OSs, such as Android or enterprise-grade Linux. The high-performance vector unit supports running AI models and inference on edge devices.

Samsung Readies PCIe 5.0 QLC SSD with a Custom RISC-V Controller

Samsung has developed a new SSD controller based on the open-source RISC-V instruction set, moving away from the Arm ISA in some of its SSD controllers. With the introduction of the BM9K1 PCIe 5.0 QLC NAND SSD, Samsung has officially created a proprietary RISC-V IP that will serve as a foundation for many SSDs the company plans to release. Announced at the China Flash Market Summit 2026, the BM9K1 SSD has been showcased with just one metric: sequential read speed. Achieving a maximum sequential read speed of 11.4 GB/s, Samsung has reached impressive speeds for QLC NAND Flash. While the sequential write speed is unknown, it is expected to be around 10 GB/s, varying slightly depending on Samsung's design. Typically, high-performance SSDs use TLC NAND, as seen in Samsung's own 9100 Pro SSD, which we reviewed. It features 3D TLC V-NAND V8 with 236 layers. While this SSD uses TLC NAND and has a proprietary Samsung Presto 5 nm controller running on Arm-based cores, Samsung might transition a significant portion of its SSD lineup to a RISC-V based design with the BM9K1, offering satisfactory performance with QLC NAND.

Interestingly, Samsung has designed this SSD with considerations for size, power, and AI. For instance, the BM9K1 PCIe 5.0 SSD replaces the previous BM9C1 PCIe 4.0 SSD controller. Although both use QLC NAND, the newer BM9K1 features a new RISC-V controller and a fresh PCIe 5.0 interface, doubling the performance in sequential reads on average. The power efficiency of the new RISC-V design is also improved. Samsung claims a 23% increase in power efficiency, thanks to the flexibility of RISC-V, which allows for greater customization and optimization of the controller firmware to match I/O patterns with the QLC NAND, resulting in nearly a quarter less power consumption. This improvement is expected to have a significant impact on small form factor PCs and client laptops. The main drawback of the design is the use of QLC NAND, but Samsung may introduce TLC NAND SSDs with RISC-V controllers in the future. For now, these remain on the 5 nm Presto Arm-powered controllers.

Espressif Unveils ESP32-S31 Dual-Core RISC-V SoC with Wi-Fi 6 and Bluetooth 5.4 Capabilities

Espressif Systems (688018.SH) proudly announces the upcoming release of ESP32-S31, a high-performance dual-core Wi-Fi 6 + Bluetooth 5.4 + IEEE 802.15.4 + Ethernet System-on-Chip (SoC). Building on Espressif's proven track record, this versatile SoC addresses the growing demand for advanced IoT applications including consumer and industrial appliances, smart speakers, voice-controlled devices, and automation systems requiring comprehensive wireless connectivity, edge AI capabilities, rich HMI, and robust security features.

ESP32-S31 delivers comprehensive wireless connectivity by combining Wi-Fi 6 (802.11ax) in 2.4 GHz band, Bluetooth 5.4 with both Bluetooth LE (Low Energy) and Classic (BR/EDR) support, plus an IEEE 802.15.4 radio enabling Thread and Zigbee protocols for diverse IoT applications. ESP32-S31 will provide a seamless support for Matter protocol over Wi-Fi as well as Thread radio.

NVIDIA Sells Remaining $140 Million Stake in Arm, Keeps Licensing Ties

Once a target of the largest industry acquisition that was halted by market regulators, NVIDIA has officially divested all its holdings in Arm Holdings PLC by selling 1.1 million shares, valued at about $140 million at the time of writing. Importantly, this does not end the NVIDIA-Arm relationship, as NVIDIA continues to be a customer and partner, licensing Arm IP and its instruction set for its older "Grace" and newer "Vera" CPUs. If readers recall, NVIDIA announced in late 2020 that it was acquiring Arm Ltd. in a deal valued at $40 billion. However, regulators from the UK and EU blocked the deal to preserve fair market competition, citing concerns that the NVIDIA-Arm deal would harm competition and stifle innovation. NVIDIA even paid a break-up fee of $1.25 billion as the deal collapsed under regulatory pressure.

As mentioned, NVIDIA's partnership with Arm is not limited to investment or stock ownership, as the company utilizes its IP and instruction set across a range of products. For example, NVIDIA has Arm-based SoCs in various forms in its embedded computing unit with Jetson modules and mini-computers that power everything from robotics to automated driving development in modern vehicles. Additionally, NVIDIA recently began offering its "Vera" CPUs as standalone server CPUs designed to compete with the industry's latest and greatest x86-based designs from AMD and Intel, demonstrating that NVIDIA is serious about being an Arm ISA licensee for the foreseeable future, not just viewing the company as an investment target.

Espressif Introduces ESP32-E22, Its First Wi-Fi 6E Connectivity Co-Processor

Espressif Systems (SSE: 688018.SH) is pleased to introduce the ESP32-E22, the company's first Wi-Fi 6E SoC and the foundation of a new product line aimed at high-performance wireless connectivity. As a Radio Co-Processor (RCP), ESP32-E22 integrates tri-band Wi-Fi 6E and dual-mode Bluetooth into a single subsystem, offloading the entire networking stack and enabling host processors to focus exclusively on application logic.

Built on Espressif's self-developed RISC-V processor architecture and Wi-Fi 6E protocol stack, ESP32-E22 offers long-term support, improved flexibility, and a resilient supply chain for demanding wireless products.

SiFive to Power Next-Gen RISC-V AI Data Centers with NVIDIA NVLink Fusion

SiFive, the industry leader in high-performance RISC-V processor IP and compute subsystems, today announced it is adopting and integrating NVIDIA NVLink Fusion in its high-performance data center-class solutions, expanding options for building tightly integrated AI systems based on the RISC-V open instruction set architecture. As artificial intelligence workloads continue to redefine the requirements of modern data centers, system architects are increasingly seeking open, customizable compute platforms that can scale efficiently alongside advanced acceleration.

AI-driven computing is entering a phase where architectural flexibility and power efficiency are as critical as peak throughput. Training and inference workloads are growing faster than power budgets, forcing data center operators to rethink how CPUs, GPUs, and domain-specific accelerators are connected and orchestrated. In this environment, performance per watt and data movement efficiency have become first-order design constraints.

Synopsys Enters Definitive Agreement with GlobalFoundries For Sale of Processor IP Solutions Business

Synopsys, Inc. today announced it has entered into a definitive agreement for the sale of its Processor IP Solutions business to GlobalFoundries (GF). Synopsys' extensive investment in IP quality, comprehensive technical support and robust IP development methodology enables designers to reduce integration risk and accelerate time-to-market. This transaction enhances the focus of Synopsys' IP business on strengthening its leadership position in interface and foundation IP while pursuing the highest-value, AI-driven opportunities from the cloud to the edge for customers spanning HPC, mobile, automotive and consumer.
"We are focusing our IP resources and roadmap to further our leadership in essential interface and foundation IP while winning new, high-value opportunities that advance our position as the leading provider of engineering solutions from silicon to systems," said Sassine Ghazi, president and CEO of Synopsys. "GF will be an excellent future steward for the processor IP solutions business, and we are committed to a smooth transition for the team, customers and partners."

India Launches DHRUV64, Its First 1 GHz, 64-bit Dual-Core RISC-V CPU

India has achieved a significant milestone in its semiconductor journey with the launch of DHRUV64. It is a fully indigenous microprocessor developed by the Centre for Development of Advanced Computing (C-DAC) under the Microprocessor Development Program (MDP). DHRUV64 provides the nation a reliable, homegrown processor technology. It is capable of supporting strategic and commercial applications. It marks a major advancement in India's pursuit of self-reliance in advanced chip design.

DHRUV64 is built with modern architectural features. It delivers higher efficiency, enhanced multitasking capability and improved reliability. Its advanced design enables seamless integration with a wide range of external hardware systems. The processor's modern fabrication leverages technologies used for high-performance chips. This makes DHRUV64 suitable for sectors such as 5G infrastructure, automotive systems, consumer electronics, industrial automation and the Internet of Things (IoT).

Qualcomm Acquires Ventana Micro Systems, Deepening RISC-V CPU Expertise

Qualcomm Technologies, Inc. today announced the acquisition of Ventana Micro Systems Inc., underscoring its commitment to advancing the RISC-V standard and ecosystem. This strategic move strengthens Qualcomm's CPU capabilities by integrating Ventana's expertise in RISC-V ISA development. The Ventana team will complement Qualcomm's ongoing RISC-V and custom Oryon CPU development, further advancing technology leadership in the AI era across all businesses.

"At Qualcomm, we are committed to shaping the future of intelligent computing. We believe the RISC-V instruction set architecture has the potential to advance the frontier on CPU technology, enabling innovation across products. The acquisition of Ventana Micro Systems marks a pivotal step in our journey to deliver industry-leading RISC-V based CPU technology across products," said Durga Malladi, executive vice president and general manager, technology planning, edge solutions and datacenter, Qualcomm Technologies.

NextSilicon Claims Its Maverick-2 Outperforms NVIDIA GPUs, Unveils New RISC-V Chip

NextSilicon, a startup company founded in 2017 has detailed its Maverick-2 Intelligent Compute Accelerator (ICA), claiming it outperforms NVIDIA's HGX B200 GPU and Intel's Sapphire Rapids CPUs in high-performance computing and AI workloads. Built on TSMC's 5 nm node, Maverick-2 is available as a single-die PCIe card with 96 GB of HBM3e (300 W) or a dual-die OAM version with 192 GB of HBM3e (600 W). According to internal benchmarks, Maverick-2 delivers up to 4× higher FP64 performance-per-watt than the HGX B200 and over 20× higher efficiency than Intel's Xeon Sapphire Rapids. In GUPS benchmarks, it reached 32.6 GUPS at 460 W, reportedly 22× faster than CPUs and 6× faster than GPUs. In HPCG workloads it achieved 600 GFLOPS at 750 W, while consuming roughly half the power of competing solutions. The company attributes these gains to a data-flow based architecture that shifts overhead management from hardware to adaptive software, allowing most silicon area to be used for computation rather than control logic.

Alongside Maverick-2, NextSilicon announced Arbel, a RISC-V-based enterprise-grade chip also built on TSMC's 5 nm process. The company claims Arbel already surpasses current RISC-V designs as well as Intel Lion Cove and AMD Zen 5 cores. Arbel features a 10-wide instruction pipeline with a 480-entry reorder buffer for high core utilization, running at 2.5 GHz. The chip can execute up to 16 scalar instructions in parallel and includes four 128-bit vector units for data-parallel workloads. A 64 KB L1 cache and large shared L3 cache ensure high memory throughput and low latency to reduce bottlenecks in compute-intensive applications. No release date or full benchmarks were disclosed, but NextSilicon says Arbel represents a move toward a fully open, software-adaptive silicon platform for future HPC and AI systems.

Axelera Announces Europa AI Processor Unit with 629 TOPs

Axelera AI, the leading provider of purpose-built AI hardware acceleration technology, today announced Europa, an AI processor unit (AIPU) that sets a new performance/price standard for multi-user generative AI and computer vision applications. Europa's combination of processing power, energy and thermal efficiency, compact packaging, and multiple form factor options make it ideal for compute-intensive, multi-modal AI inference applications from the edge to enterprise servers. Designed to be cost-effective and accessible, Europa enables any organization to unlock the power of cutting-edge AI applications.

Next Gen Architecture For Real World AI Processing Power
The Europa AIPU features eight second-generation AI cores, each incorporating Axelera's advanced Digital In-Memory Compute (D-IMC) technology and large vector engines, delivering up to 629 TOPS at INT8 precision. Complementing the AI cores are two clusters of eight dedicated RISC-V vector processing cores for non-AI pre- and post-processing, achieving a peak performance of 4915 GOPS. An integrated H.264/H.265 decoder further offloads media tasks, enabling customers to reserve the host CPU entirely for business logic and application-level workloads. These cores, programmable through the Voyager SDK, will provide better total cost of ownership than having to offload to other hardware.

Synaptics Launches the Next Generation of Astra Multimodal GenAI Edge Processors

Synaptics Incorporated (Nasdaq: SYNA), announces the new Astra SL2600 Series of multimodal Edge AI processors designed to deliver exceptional power and performance. The Astra SL2600 series enables a new generation of cost-effective intelligent devices that make the cognitive Internet of Things (IoT) possible.

The SL2600 Series will launch with the SL2610 product line, featuring five processor families tailored for diverse Edge AI applications. These processors are purpose-built for the next wave of smart appliances, home and factory automation equipment, charging infrastructure, healthcare devices, retail point of sale terminals and scanners, autonomous robotic systems, UAVs, casual gaming devices, and more.

Intel and AMD Detail New x86 Improvements to Keep the Instruction Set Relevant

Late last year, Intel and AMD founded x86 ecosystem advisory group (EAG) to keep the x86 ISA growing and thriving in the era where Arm and RISC-V are expanding their presence. A year later, the hard work of Intel and AMD engineers is coming to a fruition. According to new blog posts by both x86 ecosystem advisory group founders, new instructions are being added as of now to harder the security layer and increase the vector and matrix performance. First in line is the new FRED (Flexible Return and Event Delivery) instruction, designed as a new modernized and standardized interrupt model to reduce latency in software and improve reliability in software. In addition to FRED, instructions such as AVX10 and ACE (Advanced Matrix Extensions for Matrix Multiplication) are now standardized and implemented across the stack, meaning that we now have a standardized way to accelerate matrix multiplication, as well as 512-bit vector extensions.

Perhaps the most interesting and the most important part of this update is the ChkTag for x86 memory safety. ChkTag is a new x86 memory-tagging instruction set that helps catch common memory-safety bugs such as buffer overflows and use-after-free by attaching small tags to memory and checking them in hardware. It gives developers and compilers fine-grained control over which accesses are checked, so tools can enable protections where they matter most without the heavy overhead of software-only approaches. That makes it practical for hardening applications, kernels, hypervisors and even firmware, while ChkTag-enabled binaries can still run on older processors that lack the hardware features, which eases deployment. The designers intend ChkTag to complement existing defenses like shadow stacks and confidential computing, and the full specification is expected later this year.

InnoSilicon's Fenghua No.3 GPU Launches with 112GB+ HBM Memory and Claims to Support CUDA

InnoSilicon has unveiled the Fenghua No.3 GPU marking a significant shift in how the Chinese company develops GPUs. While for previous versions, they used Imagination Technologies' PowerVR IP, now the Fenghua No.3 uses an open-source RISC-V design based on OpenCore Institute's Nanhu V3 project. The Fenghua No.3 comes with over 112 GB of HBM memory putting it right in the AI accelerator market. InnoSilicon says one card can run 32B and 72B parameter language models. They also claim that if you use eight cards together, you can handle huge 671B and 685B parameter models.

The GPU support DirectX 12 Vulkan 1.2, and OpenGL 4.6 APIs for games, and it can handle even ray tracing. InnoSilicon showed the card running Tomb Raider, Delta Force, and Valorant, however it didn't share exact performance numbers or the settings in use. The card can power up to six 8 K screens at 30 Hz and supports YUV444 format to improve color accuracy. This aims at medical, CAD, and scientific computing markets. What's even more interesting is that InnoSilicon says that Fenghua No.3 it's CUDA compatible—a bold claim that, if true, could expand the GPU's software options. However, since CUDA is proprietary, this claim requires verification.

SiFive's New RISC-V IP Combines Scalar, Vector and Matrix Compute to Accelerate AI from the Far Edge IoT to the Data Center

Further expanding SiFive's lead in RISC-V AI IP, the company today launched its 2nd Generation Intelligence family, featuring five new RISC-V-based products designed to accelerate AI workloads across thousands of potential applications. The lineup includes two entirely new products—the X160 Gen 2 and X180 Gen 2—alongside upgraded X280 Gen 2, X390 Gen 2 and XM Gen 2. These new products all feature enhanced scalar, vector and, specifically with XM, matrix processing capabilities designed for modern AI workloads.

The X160 Gen 2 and X180 Gen 2 target far edge compute and IoT applications, achieving high efficiency in a compact footprint and delivering advanced AI functionality to the deeply embedded edge, which is heavily constrained by power and area. Target industries include automotive, autonomous robotics, industrial automation, and smart IoT.

Oxmiq Labs: Re-Architecting the GPU Stack: From Atoms to Agents

Oxmiq Labs Inc., the all-new GPU software and IP startup founded by one of the world's top GPU architects and visionaries, Raja Koduri, emerges from stealth after two years of intensive IP development. Raja has assembled a world-class team of GPU and AI architects with over 500 years of combined experience, hundreds of patents, and a collective track record of generating more than $100B in revenue at prior companies.

The Opportunity:
Modern computing has fundamentally shifted toward multimodal experiences where text, audio, video, images, and 3D environments seamlessly interact, establishing GPU architecture as the cornerstone of this transformation. Unlike fixed-function AI accelerators that handle specific tasks, GPUs provide the general-purpose computational flexibility required for these diverse modalities while maintaining deep integration with mainstream operating systems through standardized APIs and unified memory models. This architectural advantage positions GPUs as the essential compute engine for both current applications and the emerging landscape of multimodal AI, where heterogeneous workloads must be processed in harmony.

NVIDIA Ports CUDA to RISC-V, Betting Big on Open-Source ISA

During the RISC-V Summit in China, NVIDIA's Frans Sijstermans, vice president of hardware engineering, officially announced that NVIDIA has ported its massive CUDA software library to RISC-V ISA, signaling that the company sees RISC-V adoption accelerating in every aspect of the hardware stack, and that it could be a perfect match for NVIDIA GPUs. Historically, NVIDIA ported its CUDA platform to every major instruction set, including x86, Arm, PowerPC, and even Sun's SPARC. This is done to ensure that if any platform takes off in the enterprise or any segment, NVIDIA is there from the start to support it and allow its GPUs to run at full speed. Now, the $4 trillion company is making a bet that RISC-V will be the next desirable ISA to bring full support for.

NVIDIA envisions systems where its GPUs are the center of any acceleration, and supplementary RISC-V CPUs oversee CUDA drivers, application logic, and the operating system, orchestrating parallel workloads entirely within the CUDA ecosystem. The diagram shown at the summit highlights a DPU handling networking tasks, creating a cohesive trio of compute, control, and data-movement elements. If you recall, NVIDIA already uses NV-RISC-V CPU inside its GPUs for handling control logic on the GPU itself. That demonstrates NVIDIA's strategy to build heterogeneous platforms that combine RISC-V controllers with its GPUs, DPUs, and networking silicon. Now that CUDA is fully supported on RISC-V, NVIDIA could look into alternatives for its Grace CPU to be built on the RISC-V ISA. As the open-source ISA slowly breaks into the server space with the RVA23 specification, which NVIDIA mandates for CUDA support, we could see some interesting heterogeneous designs.
Return to Keyword Browsing
Nov 11th, 2026 03:16 CST change timezone

New Forum Posts

Popular Reviews

TPU on YouTube

Controversial News Posts