Intel Details "Crescent Island" Graphics: 32 Xe3P Cores, up to 480 GB LPDDR5X Memory
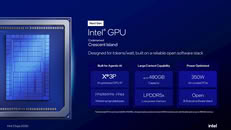
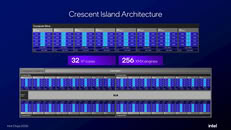
Intel's long-awaited graphics card update is arriving for data centers and workstations with the introduction of "Crescent Island," now detailed. At Hot Chips 2026, the company revealed more about the upcoming graphics card. Based on the Xe3P GPU IP, the graphics card is designed as a 350 W, air-cooled, PCIe format compatible with any configuration. The GPU itself features 32 Xe3P cores, 256 XMX engines, 32 MB of unified L2 cache, and 160 GB of LPDDR5X memory. This memory configuration is exclusive to Intel-branded "Crescent Island" graphics cards, while the company allows its ODMs to equip the card with up to 480 GB of LPDDR5X memory for maximum VRAM capacity. Just a few of these in their maximum configuration could power frontier open-source models locally.
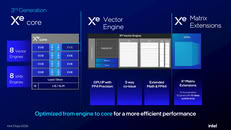
What is particularly interesting about Xe3P is the pipeline, as XMX engines have been redesigned from the four-deep systolic design on the regular Xe3 to 16-deep processing on Xe3P. Additional details include FP4 data format support alongside FP8, as well as massive register files of 1 MB per core and L1 cache of 512 KB per core. In total, there are 256 Vector engines and 256 of the new XMX engines, each split into groups of eight per Xe3P core. Additionally, in Xe3P, there are no graphics processing elements that would output any imagery, as the silicon is designed purely for AI inference workloads that include long context, agentic tasks.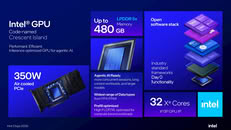
What is particularly interesting about Xe3P is the pipeline, as XMX engines have been redesigned from the four-deep systolic design on the regular Xe3 to 16-deep processing on Xe3P. Additional details include FP4 data format support alongside FP8, as well as massive register files of 1 MB per core and L1 cache of 512 KB per core. In total, there are 256 Vector engines and 256 of the new XMX engines, each split into groups of eight per Xe3P core. Additionally, in Xe3P, there are no graphics processing elements that would output any imagery, as the silicon is designed purely for AI inference workloads that include long context, agentic tasks.